Qwen3.6-35B-A3B-Uncensored-Heretic-IQ2_M (GGUF)
This repository contains an IQ2_M GGUF quantization of:
The quantization was produced using the official llama.cpp quantizer together with the published Unsloth importance matrix for the matching Qwen3.6-35B-A3B-MTP architecture.
The goal is simple:
- Keep the storage footprint small enough for local inference.
- Preserve as much of the original model quality as possible.
- Retain the refusal-reduced behavior introduced by the Heretic model.
What is this model?
This is not a conventional supervised fine-tune.
The Heretic release applies an abliteration technique designed to reduce unnecessary refusals while remaining close to the original Qwen3.6-35B-A3B model.
According to the original release, only a relatively small subset of the network is modified, with the intention of preserving the underlying reasoning, coding, and language capabilities of the base model.
For details about the modification itself, please refer to the original repository.
Quantization
This GGUF was produced with:
- Official llama.cpp quantizer
- IQ2_M quantization
- Matching Unsloth MTP importance matrix
--leave-output-tensor
No custom tensor overrides or experimental quantization recipes were used.
The resulting file is fully compatible with current llama.cpp releases.
Dynamic Quantization
IQ2_M is a dynamic (mixed) quantization format.
Although the model is referred to as "IQ2_M", not every tensor is stored using the same quantization type.
During quantization, llama.cpp automatically chooses different quantization formats for different tensors based on their characteristics and the supplied importance matrix.
As a result, some tensors may be stored using higher precision formats (such as IQ3 variants), while others remain IQ2, providing a better quality-to-size trade-off than uniformly quantizing every tensor.
Importance Matrix
An importance matrix (imatrix) is not a fine-tune.
Instead, it is a calibration artifact used only during quantization.
Its purpose is to estimate which weights are most important so that the quantizer allocates the available bits more effectively.
For this GGUF, the published Unsloth importance matrix for Qwen3.6-35B-A3B-MTP was used.
This should generally produce a higher-quality quantization than quantizing without an importance matrix or with a mismatched calibration.
Since the Heretic model preserves the original architecture and modifies only a subset of weights, the matching base-model importance matrix is expected to remain a reasonable calibration choice.
Why combine Heretic + Unsloth imatrix?
These two components serve different purposes.
Heretic
- Modifies model weights.
- Reduces unnecessary refusals.
- Attempts to preserve the original model's capabilities.
Unsloth Importance Matrix
- Does not modify model weights.
- Does not change the BF16 model.
- Helps preserve more of the original model quality during aggressive low-bit quantization.
In other words:
- Heretic affects what the model has learned.
- The importance matrix affects how faithfully those learned weights are compressed.
These approaches are complementary rather than overlapping.
Credits
Original model:
- llmfan46/Qwen3.6-35B-A3B-uncensored-heretic
Quantization:
- ggml-org/llama.cpp
Importance Matrix:
- unsloth/Qwen3.6-35B-A3B-MTP-GGUF
License
This GGUF follows the licensing of the original model.
Please refer to the upstream repository for the complete license terms.
📚 Reference Material
This repository contains only the IQ2_M GGUF quantization of the original model. For completeness and to preserve attribution, the model cards from the upstream repositories are included below.
88% fewer refusals (10/100 Uncensored vs 83/100 Original) while preserving model quality (0.0015 KL divergence).
❤️ Support My Work
Creating these models takes significant time, work and compute. If you find them useful consider supporting me:
| Platform | Link | What you get |
|---|---|---|
| 🎉 Patreon | Monthly support | Priority model requests |
| ☕ Ko-fi | One-time tip | My eternal gratitude |
Your help will motivate me and would go into further improving my workflow and coverings fees for storage, compute and may even help uncensoring bigger model with rental Cloud GPUs.
This is a decensored version of Qwen/Qwen3.6-35B-A3B, made using Heretic v1.2.0 with a variant of the Magnitude-Preserving Orthogonal Ablation (MPOA) method
Abliteration parameters
| Parameter | Value |
|---|---|
| direction_index | 19.93 |
| attn.out_proj.max_weight | 1.49 |
| attn.out_proj.max_weight_position | 23.45 |
| attn.out_proj.min_weight | 1.08 |
| attn.out_proj.min_weight_distance | 16.54 |
| mlp.down_proj.max_weight | 1.46 |
| mlp.down_proj.max_weight_position | 28.05 |
| mlp.down_proj.min_weight | 1.27 |
| mlp.down_proj.min_weight_distance | 18.79 |
| attn.o_proj.max_weight | 1.47 |
| attn.o_proj.max_weight_position | 24.35 |
| attn.o_proj.min_weight | 0.07 |
| attn.o_proj.min_weight_distance | 22.58 |
Targeted components
- attn.o_proj
- attn.out_proj
- mlp.down_proj
Performance
| Metric | This model | Original model (Qwen3.6-35B-A3B) |
|---|---|---|
| KL divergence | 0.0015 | 0 (by definition) |
| Refusals | ✅ 10/100 | ❌ 83/100 |
Lower refusals indicate fewer content restrictions, while lower KL divergence indicates more closeness to the original model's baseline. Higher refusals cause more rejections, objections, pushbacks, lecturing, censorship, softening and deflections.
MMLU test results:
Original:
============================================================
-
Total questions: 7021
-
Correct: 5877
-
Accuracy: 0.8371 (83.71%)
-
Parse failures: 0
============================================================
Tested subject scores:
- professional_law: 0.7121 (559/785)
- moral_scenarios: 0.6765 (299/442)
- miscellaneous: 0.9426 (361/383)
- professional_psychology: 0.8924 (282/316)
- high_school_psychology: 0.9704 (262/270)
- high_school_macroeconomics: 0.8985 (177/197)
- elementary_mathematics: 0.7826 (144/184)
- moral_disputes: 0.8448 (147/174)
- prehistory: 0.9070 (156/172)
- philosophy: 0.8994 (143/159)
- high_school_biology: 0.9605 (146/152)
- professional_accounting: 0.7622 (109/143)
- clinical_knowledge: 0.8929 (125/140)
- high_school_microeconomics: 0.9559 (130/136)
- nutrition: 0.8889 (120/135)
- professional_medicine: 0.9328 (125/134)
- conceptual_physics: 0.9219 (118/128)
- high_school_mathematics: 0.6142 (78/127)
- human_aging: 0.7931 (92/116)
- security_studies: 0.8661 (97/112)
- high_school_statistics: 0.8378 (93/111)
- marketing: 0.8991 (98/109)
- high_school_world_history: 0.8962 (95/106)
- sociology: 0.9320 (96/103)
- high_school_government_and_politics: 0.9901 (100/101)
- high_school_geography: 0.9495 (94/99)
- high_school_chemistry: 0.7732 (75/97)
- high_school_us_history: 0.9263 (88/95)
- virology: 0.5169 (46/89)
- college_medicine: 0.8636 (76/88)
- world_religions: 0.8977 (79/88)
- high_school_physics: 0.7857 (66/84)
- electrical_engineering: 0.8519 (69/81)
- astronomy: 0.9620 (76/79)
- logical_fallacies: 0.9211 (70/76)
- high_school_european_history: 0.8630 (63/73)
- anatomy: 0.9014 (64/71)
- college_biology: 0.9219 (59/64)
- human_sexuality: 0.8750 (56/64)
- formal_logic: 0.7500 (48/64)
- public_relations: 0.7377 (45/61)
- international_law: 0.9167 (55/60)
- college_physics: 0.7544 (43/57)
- college_mathematics: 0.6182 (34/55)
- econometrics: 0.7963 (43/54)
- jurisprudence: 0.9057 (48/53)
- high_school_computer_science: 0.9423 (49/52)
- machine_learning: 0.7692 (40/52)
- medical_genetics: 0.9608 (49/51)
- global_facts: 0.4706 (24/51)
- management: 0.9000 (45/50)
- us_foreign_policy: 0.9600 (48/50)
- college_chemistry: 0.6383 (30/47)
- abstract_algebra: 0.6383 (30/47)
- business_ethics: 0.8696 (40/46)
- college_computer_science: 0.7778 (35/45)
- computer_security: 0.8837 (38/43)
Heretic:
============================================================
-
Total questions: 7021
-
Correct: 5843
-
Accuracy: 0.8322 (83.22%)
-
Parse failures: 0
============================================================
Tested subject scores:
- professional_law: 0.7032 (552/785)
- moral_scenarios: 0.6267 (277/442)
- miscellaneous: 0.9373 (359/383)
- professional_psychology: 0.8956 (283/316)
- high_school_psychology: 0.9704 (262/270)
- high_school_macroeconomics: 0.9036 (178/197)
- elementary_mathematics: 0.8152 (150/184)
- moral_disputes: 0.8563 (149/174)
- prehistory: 0.8779 (151/172)
- philosophy: 0.9057 (144/159)
- high_school_biology: 0.9605 (146/152)
- professional_accounting: 0.7483 (107/143)
- clinical_knowledge: 0.9000 (126/140)
- high_school_microeconomics: 0.9632 (131/136)
- nutrition: 0.8741 (118/135)
- professional_medicine: 0.9254 (124/134)
- conceptual_physics: 0.9297 (119/128)
- high_school_mathematics: 0.5827 (74/127)
- human_aging: 0.7931 (92/116)
- security_studies: 0.8661 (97/112)
- high_school_statistics: 0.8559 (95/111)
- marketing: 0.9083 (99/109)
- high_school_world_history: 0.8868 (94/106)
- sociology: 0.9320 (96/103)
- high_school_government_and_politics: 0.9901 (100/101)
- high_school_geography: 0.9495 (94/99)
- high_school_chemistry: 0.7732 (75/97)
- high_school_us_history: 0.9263 (88/95)
- virology: 0.5169 (46/89)
- college_medicine: 0.8636 (76/88)
- world_religions: 0.9091 (80/88)
- high_school_physics: 0.7738 (65/84)
- electrical_engineering: 0.8642 (70/81)
- astronomy: 0.9494 (75/79)
- logical_fallacies: 0.9474 (72/76)
- high_school_european_history: 0.8630 (63/73)
- anatomy: 0.9296 (66/71)
- college_biology: 0.9375 (60/64)
- human_sexuality: 0.9062 (58/64)
- formal_logic: 0.7188 (46/64)
- public_relations: 0.7213 (44/61)
- international_law: 0.9167 (55/60)
- college_physics: 0.7544 (43/57)
- college_mathematics: 0.6182 (34/55)
- econometrics: 0.7593 (41/54)
- jurisprudence: 0.8868 (47/53)
- high_school_computer_science: 0.9231 (48/52)
- machine_learning: 0.7115 (37/52)
- medical_genetics: 0.9216 (47/51)
- global_facts: 0.5294 (27/51)
- management: 0.9000 (45/50)
- us_foreign_policy: 0.9400 (47/50)
- college_chemistry: 0.5745 (27/47)
- abstract_algebra: 0.6809 (32/47)
- business_ethics: 0.8478 (39/46)
- college_computer_science: 0.7778 (35/45)
- computer_security: 0.8837 (38/43)
MMLU - Massive Multitask Language Understanding, multiple-choice questions across 57 subjects (math, history, law, medicine, etc.).
GGUF Version
GGUF quantizations available here llmfan46/Qwen3.6-35B-A3B-uncensored-heretic-GGUF.
Qwen3.6-35B-A3B

[!Note] This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
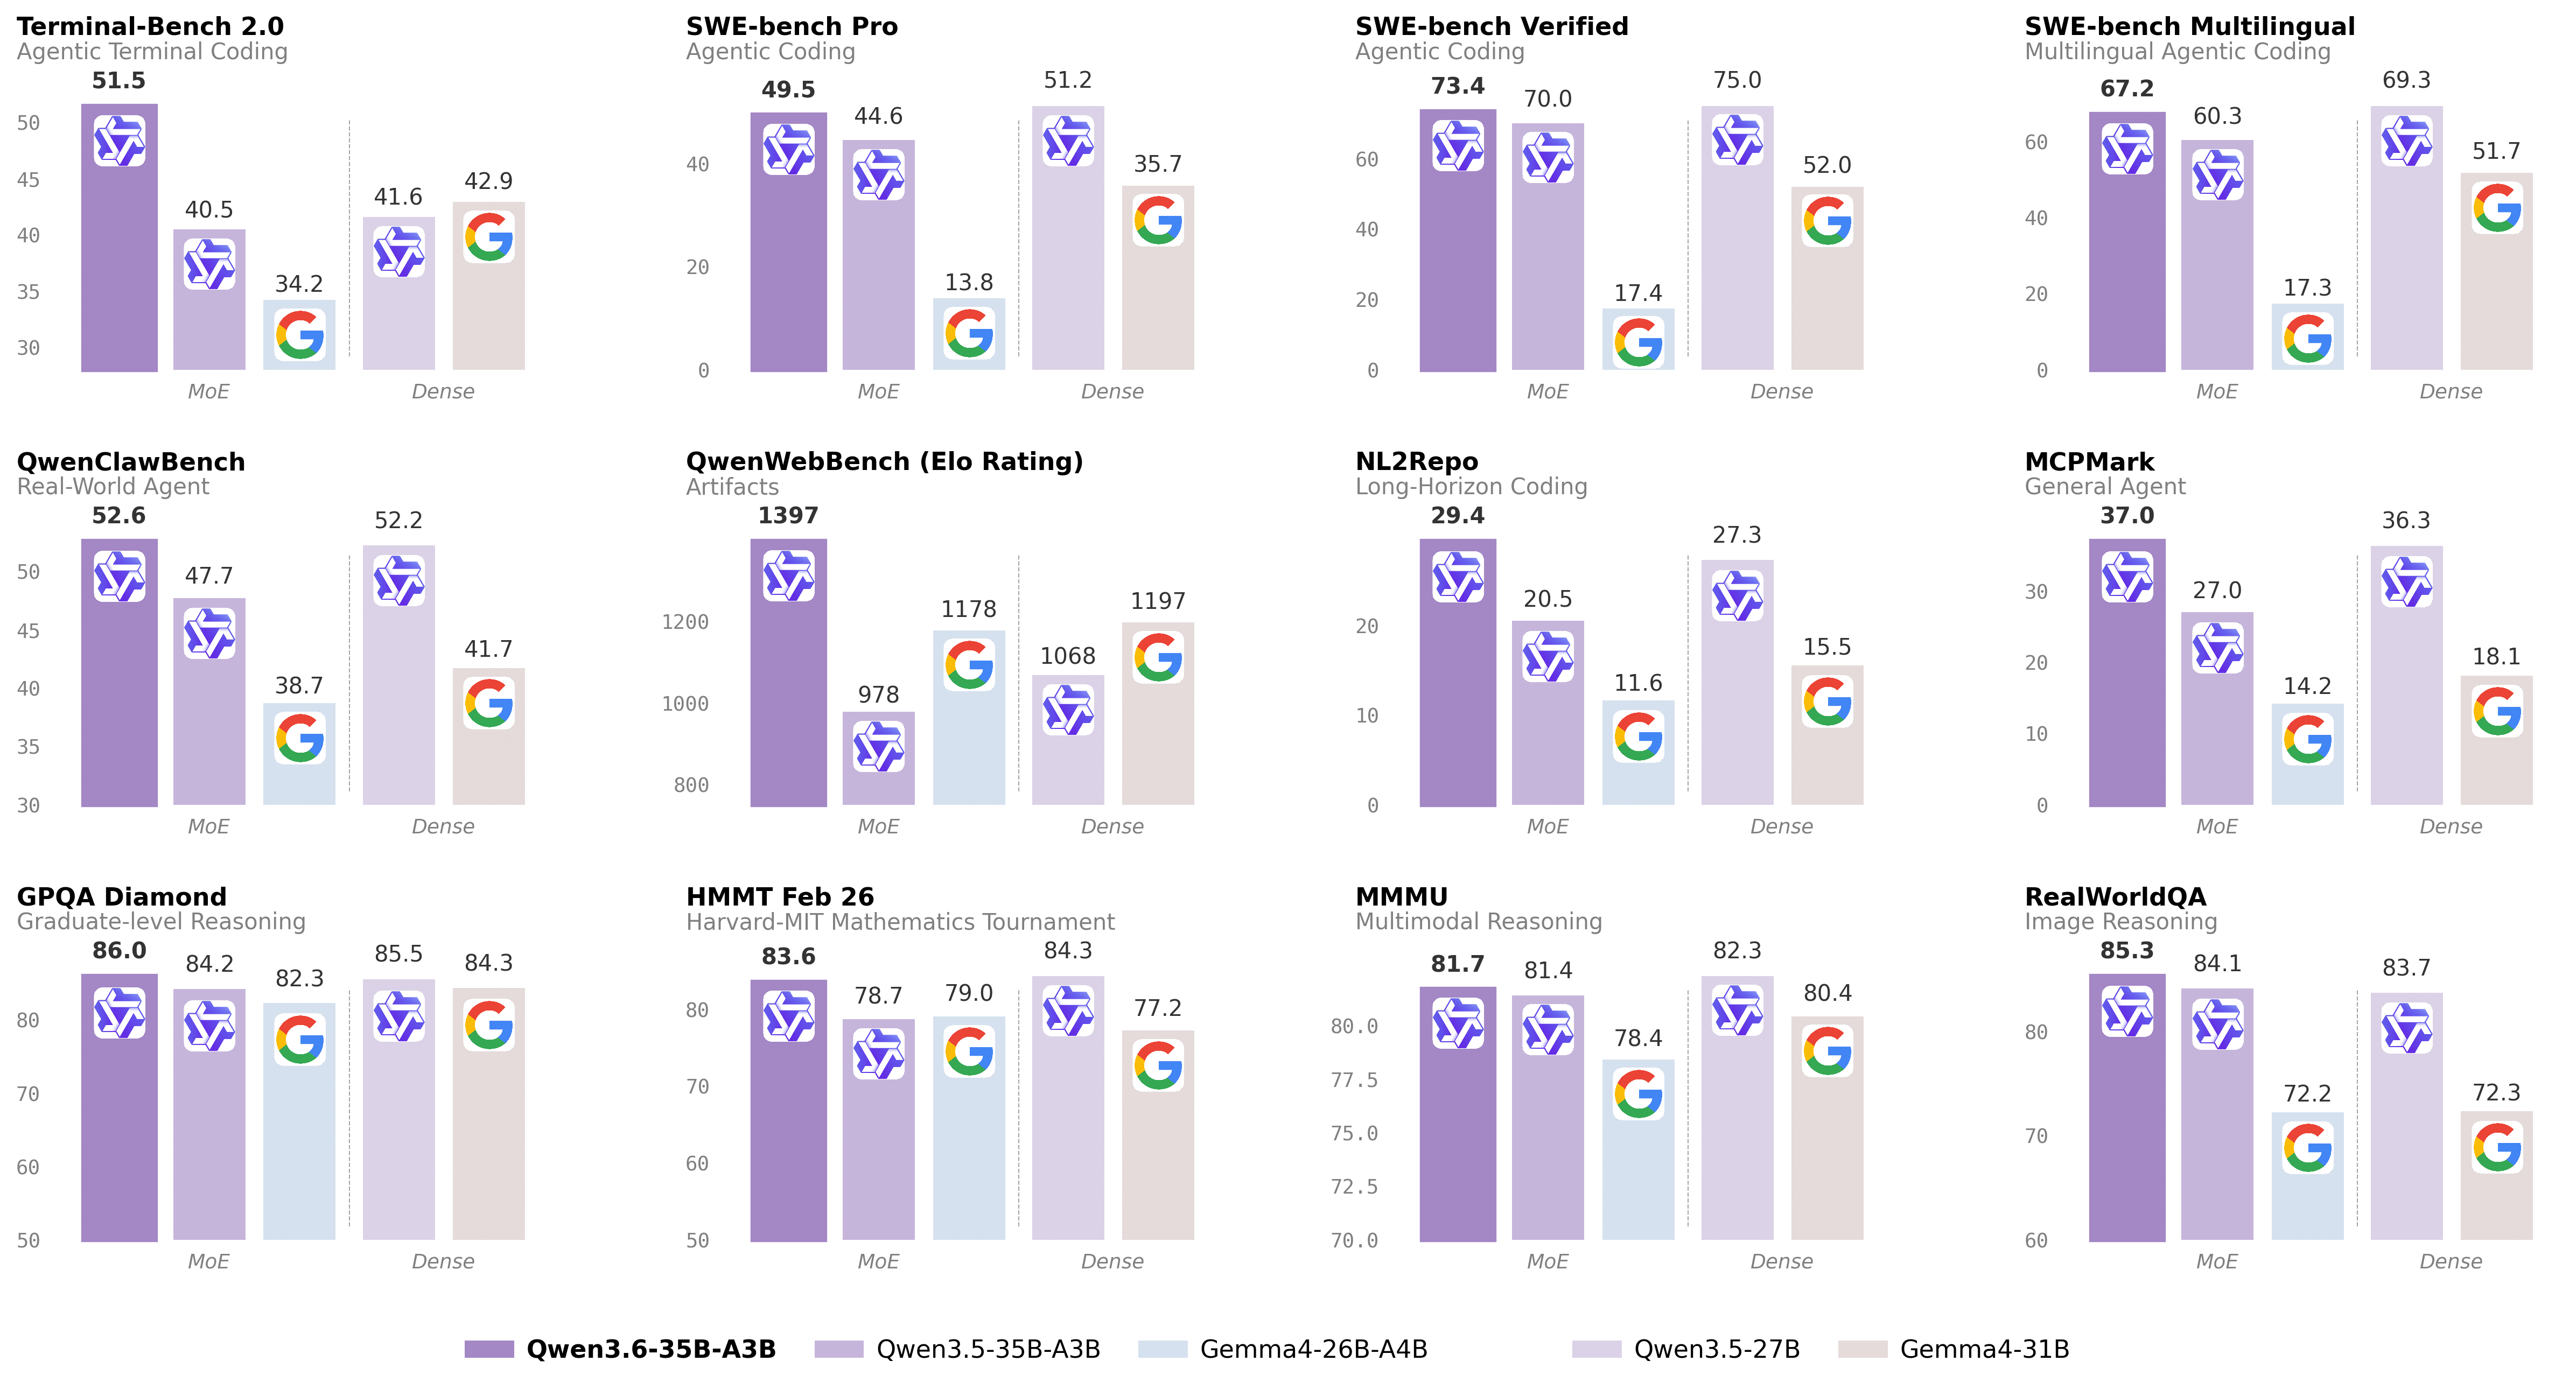
For more details, please refer to our blog post Qwen3.6-35B-A3B.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 35B in total and 3B activated
- Hidden Dimension: 2048
- Token Embedding: 248320 (Padded)
- Number of Layers: 40
- Hidden Layout: 10 × (3 × (Gated DeltaNet → MoE) → 1 × (Gated Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 32 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 16 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Mixture Of Experts
- Number of Experts: 256
- Number of Activated Experts: 8 Routed + 1 Shared
- Expert Intermediate Dimension: 512
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
Benchmark Results
Language
Vision Language
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks. In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important] Inference efficiency and throughput vary significantly across frameworks. We recommend using the latest framework versions to ensure optimal performance and compatibility. For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important] The model has a default context length of 262,144 tokens. If you encounter out-of-memory (OOM) errors, consider reducing the context window. However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models.
sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install sglang[all]
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-35B-A3B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 -
Tool Use: To support tool use, you can use the following command.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-35B-A3B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coder -
Multi-Token Prediction (MTP): The following command is recommended for MTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.6-35B-A3B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --speculative-algo NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.
vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install vllm --torch-backend=auto
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 -
Tool Call: To support tool use, you can use the following command.
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder -
Multi-Token Prediction (MTP): The following command is recommended for MTP:
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --speculative-config '{"method":"qwen3_next_mtp","num_speculative_tokens":2}' -
Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
vllm serve Qwen/Qwen3.6-35B-A3B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --language-model-only
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing. For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
transformers serve Qwen/Qwen3.6-35B-A3B --port 8000 --continuous-batching
Using Qwen3.6 via the Chat Completions API
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs. Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
pip install -U openai

# Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
[!Tip] We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Instruct (or non-thinking) mode for general tasks:
temperature=0.7, top_p=0.8, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0- Instruct (or non-thinking) mode for reasoning tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0Please note that the support for sampling parameters varies according to inference frameworks.
[!Important] Qwen3.6 models operate in thinking mode by default, generating thinking content signified by
<think>\n...</think>\n\nbefore producing the final responses. To disable thinking content and obtain direct response, refer to the examples here.
Text-Only Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Type \"I love Qwen3.6\" backwards"},
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-35B-A3B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Image Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"
                }
            },
            {
                "type": "text",
                "text": "The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$"
            }
        ]
    }
]

response = client.chat.completions.create(
    model="Qwen/Qwen3.6-35B-A3B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
Video Input
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "video_url",
                "video_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4"
                }
            },
            {
                "type": "text",
                "text": "How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?"
            }
        ]
    }
]

# When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,
# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).
# This feature is currently supported only in vLLM.
#
# By default, `fps=2` and `do_sample_frames=True`.
# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.
response = client.chat.completions.create(
    model="Qwen/Qwen3.6-35B-A3B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "mm_processor_kwargs": {"fps": 2, "do_sample_frames": True},
    },
)

print("Chat response:", chat_response)
Instruct (or Non-Thinking) Mode
[!Important] Qwen3.6 does not officially support the soft switch of Qwen3, i.e.,
/thinkand/nothink.
Qwen3.6 will think by default before response. You can obtain direct response from the model without thinking by configuring the API parameters. For example,
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.6/demo/RealWorld/RealWorld-04.png"
                }
            },
            {
                "type": "text",
                "text": "Where is this?"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-35B-A3B",
    messages=messages,
    max_tokens=32768,
    temperature=0.7,
    top_p=0.8,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"enable_thinking": False},
    },
)
print("Chat response:", chat_response)
[!Note] If you are using APIs from Alibaba Cloud Model Studio, in addition to changing
model, please use"enable_thinking": Falseinstead of"chat_template_kwargs": {"enable_thinking": False}.
Preserve Thinking
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [...]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-35B-A3B",
    messages=messages,
    max_tokens=32768,
    temperature=0.7,
    top_p=0.8,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"preserve_thinking": True},
    },
)
print("Chat response:", chat_response)
[!Note] If you are using APIs from Alibaba Cloud Model Studio, in addition to changing
model, please use"preserve_thinking": Trueinstead of"chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
import os
from qwen_agent.agents import Assistant

# Define LLM
# Using Alibaba Cloud Model Studio
llm_cfg = {
    # Use the OpenAI-compatible model service provided by DashScope:
    'model': 'Qwen3.6-35B-A3B',
    'model_type': 'qwenvl_oai',
    'model_server': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
    'api_key': os.getenv('DASHSCOPE_API_KEY'),

    'generate_cfg': {
        'use_raw_api': True,
        # When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way
        'extra_body': {
            'enable_thinking': True,
            'preserve_thinking': True,
        },
    },
}

# Using OpenAI-compatible API endpoint.
# functionality of the deployment frameworks and let Qwen-Agent automate the related operations.
#
# llm_cfg = {
#     # Use your own model service compatible with OpenAI API by vLLM/SGLang:
#     'model': 'Qwen/Qwen3.6-35B-A3B',
#     'model_type': 'qwenvl_oai',
#     'model_server': 'http://localhost:8000/v1',  # api_base
#     'api_key': 'EMPTY',
#
#     'generate_cfg': {
#         'use_raw_api': True,
#         # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way
#         'extra_body': {
#             'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}
#         },
#     },
# }

# Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            "filesystem": {
                "command": "npx",
                "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/xxxx/Desktop"]
            }
        }
    }
]

# Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

# Streaming generation
messages = [{'role': 'user', 'content': 'Help me organize my desktop.'}]
for responses in bot.run(messages=messages):
    pass
print(responses)

# Streaming generation
messages = [{'role': 'user', 'content': 'Develop a dog website and save it on the desktop'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Processing Ultra-Long Texts
Qwen3.6 natively supports context lengths of up to 262,144 tokens. For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
-
Modifying the model configuration file: In the
config.jsonfile, change therope_parametersfields intext_configto:{ "mrope_interleaved": true, "mrope_section": [ 11, 11, 10 ], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144, } -
Passing command line arguments:
For
vllm, you can useVLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1010000For
sglangandktransformers, you can useSGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1010000
[!NOTE] All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts. We advise modifying the
rope_parametersconfiguration only when processing long contexts is required. It is also recommended to modify thefactoras needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to setfactoras 2.0.
Best Practices
To achieve optimal performance, we recommend the following settings:
-
Sampling Parameters:
- We suggest using the following sets of sampling parameters depending on the mode and task type:
- Thinking mode for general tasks:
temperature=1.0,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=1.5,repetition_penalty=1.0 - Thinking mode for precise coding tasks (e.g., WebDev):
temperature=0.6,top_p=0.95,top_k=20,min_p=0.0,presence_penalty=0.0,repetition_penalty=1.0 - Instruct (or non-thinking) mode for general tasks:
temperature=0.7,top_p=0.8,top_k=20,min_p=0.0,presence_penalty=1.5,repetition_penalty=1.0 - Instruct (or non-thinking) mode for reasoning tasks:
temperature=1.0,top_p=1.0,top_k=40,min_p=0.0,presence_penalty=2.0,repetition_penalty=1.0
- Thinking mode for general tasks:
- For supported frameworks, you can adjust the
presence_penaltyparameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
- We suggest using the following sets of sampling parameters depending on the mode and task type:
-
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
-
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
- Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the
answerfield with only the choice letter, e.g.,"answer": "C"."
-
Long Video Understanding: To optimize inference efficiency for plain text and images, the
sizeparameter in the releasedvideo_preprocessor_config.jsonis conservatively configured. It is recommended to set thelongest_edgeparameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,{"longest_edge": 469762048, "shortest_edge": 4096}Alternatively, override the default values via engine startup parameters. For implementation details, refer to: vLLM / SGLang.
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen36_35b_a3b,
    title = {{Qwen3.6-35B-A3B}: Agentic Coding Power, Now Open to All},
    url = {https://qwen.ai/blog?id=qwen3.6-35b-a3b},
    author = {{Qwen Team}},
    month = {April},
    year = {2026}
}