bge-small-en-v1.5-gguf
Model creator: BAAI
Original model: bge-small-en-v1.5
Original Description
More details please refer to our Github: FlagEmbedding.
If you are looking for a model that supports more languages, longer texts, and other retrieval methods, you can try using bge-m3.
Description
This repo contains GGUF format files for the bge-small-en-v1.5 embedding model.
These files were converted and quantized with llama.cpp PR 5500, commit 34aa045de, on a consumer RTX 4090.
This model supports up to 512 tokens of context.
Compatibility
These files are compatible with llama.cpp as of commit 4524290e8, as well as LM Studio as of version 0.2.19.
Meta-information
Explanation of quantisation methods
Provided Files
| Name | Quant method | Bits | Size | Max RAM required | Use case |
|---|---|---|---|---|---|
| Name | Quant method | Bits | Size | Use case | |
| bge-small-en-v1.5.Q2_K.gguf | Q2_K | 2 | 25.3 MB | smallest, significant quality loss - not recommended for most purposes | |
| bge-small-en-v1.5.Q3_K_S.gguf | Q3_K_S | 3 | 25.3 MB | very small, high quality loss | |
| bge-small-en-v1.5.Q3_K_M.gguf | Q3_K_M | 3 | 26.7 MB | very small, high quality loss | |
| bge-small-en-v1.5.Q3_K_L.gguf | Q3_K_L | 3 | 27.7 MB | small, substantial quality loss | |
| bge-small-en-v1.5.Q4_0.gguf | Q4_0 | 4 | 26.2 MB | legacy; small, very high quality loss - prefer using Q3_K_M | |
| bge-small-en-v1.5.Q4_K_S.gguf | Q4_K_S | 4 | 28.2 MB | small, greater quality loss | |
| bge-small-en-v1.5.Q4_K_M.gguf | Q4_K_M | 4 | 29.2 MB | medium, balanced quality - recommended | |
| bge-small-en-v1.5.Q5_0.gguf | Q5_0 | 5 | 28.8 MB | legacy; medium, balanced quality - prefer using Q4_K_M | |
| bge-small-en-v1.5.Q5_K_S.gguf | Q5_K_S | 5 | 29.7 MB | large, low quality loss - recommended | |
| bge-small-en-v1.5.Q5_K_M.gguf | Q5_K_M | 5 | 30.5 MB | large, very low quality loss - recommended | |
| bge-small-en-v1.5.Q6_K.gguf | Q6_K | 6 | 35.1 MB | very large, extremely low quality loss | |
| bge-small-en-v1.5.Q8_0.gguf | Q8_0 | 8 | 36.8 MB | very large, extremely low quality loss - recommended | |
| bge-small-en-v1.5.Q8_0.gguf | FP16 | 16 | 67.3 MB | enormous, pretty much the original model - not recommended | |
| bge-small-en-v1.5.Q8_0.gguf | FP32 | 32 | 134 MB | enormous, pretty much the original model - not recommended |
Examples
Example Usage with llama.cpp
To compute a single embedding, build llama.cpp and run:
./embedding -ngl 99 -m [filepath-to-gguf].gguf -p 'search_query: What is TSNE?'
You can also submit a batch of texts to embed, as long as the total number of tokens does not exceed the context length. Only the first three embeddings are shown by the embedding example.
texts.txt:
search_query: What is TSNE?
search_query: Who is Laurens Van der Maaten?
Compute multiple embeddings:
./embedding -ngl 99 -m [filepath-to-gguf].gguf -f texts.txt
Example Usage with LM Studio
Download the 0.2.19 beta build from here: Windows MacOS Linux
Once installed, open the app. The home should look like this:

Search for either "ChristianAzinn" in the main search bar or go to the "Search" tab on the left menu and search the name there.

Select your model from those that appear (this example uses bge-small-en-v1.5-gguf) and select which quantization you want to download. Since this model is pretty small, I recommend Q8_0, if not f16/32. Generally, the lower you go in the list (or the bigger the number gets), the larger the file and the better the performance.
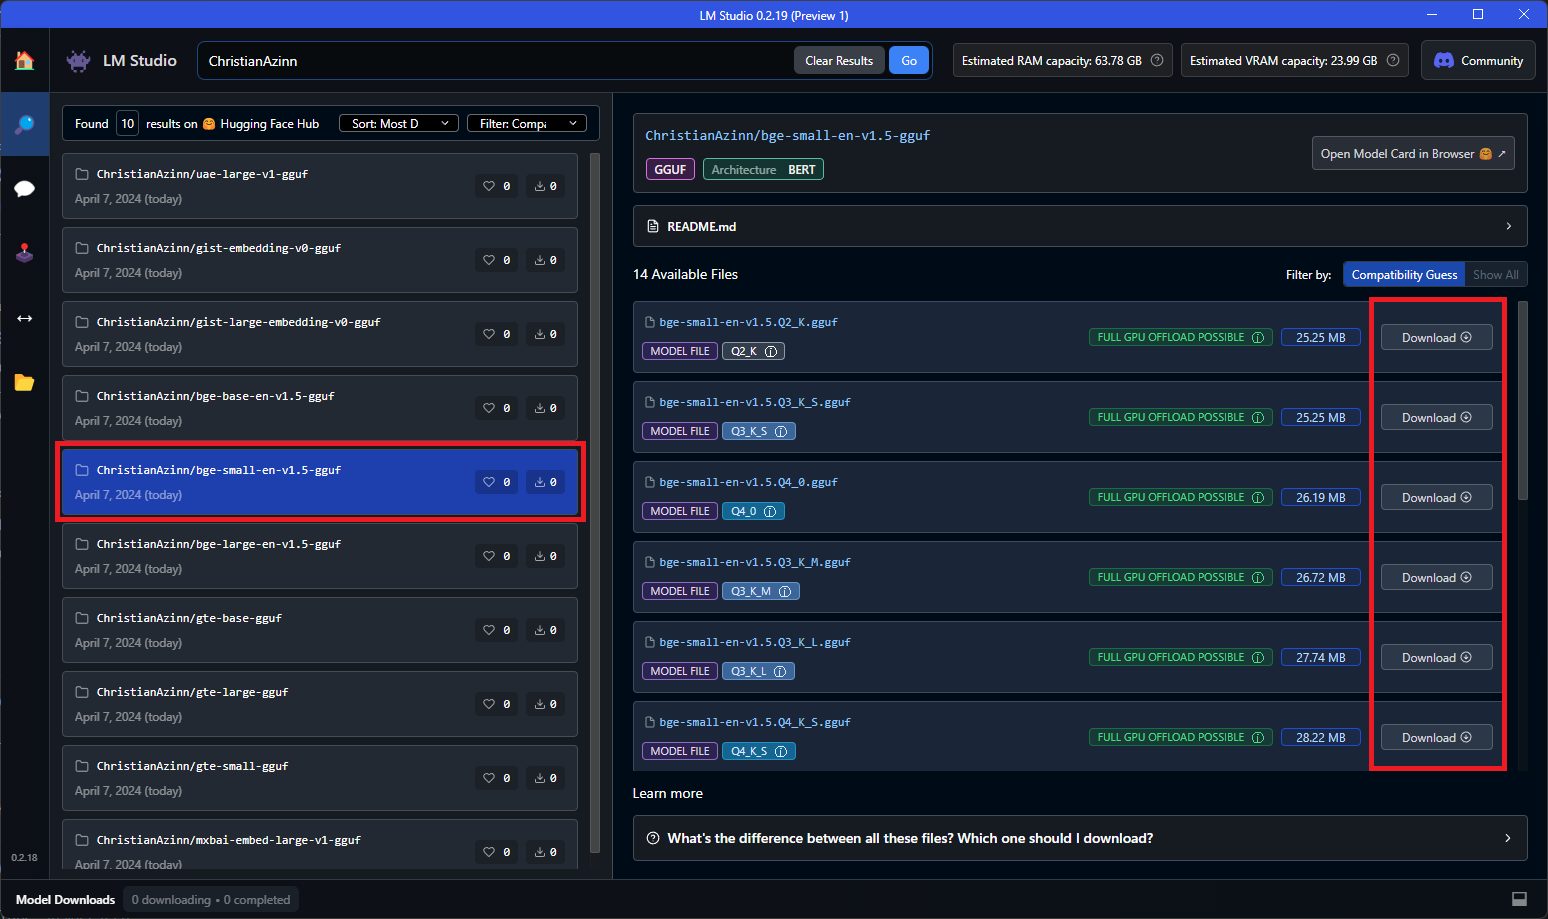
You will see a green checkmark and the word "Downloaded" once the model has successfully downloaded, which can take some time depending on your network speeds.

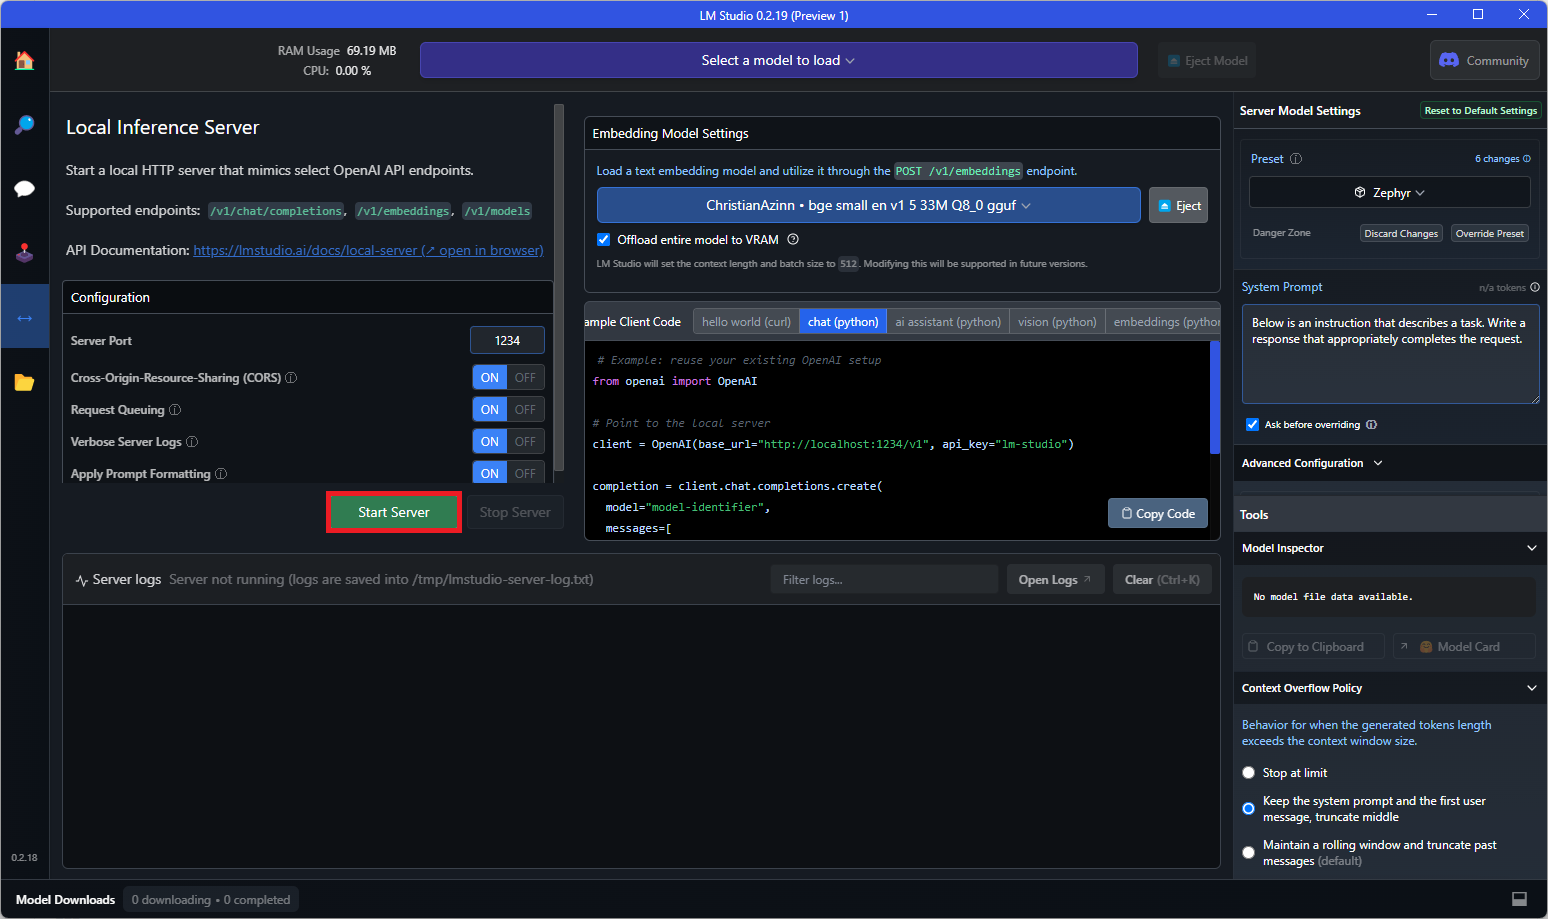
Once this model is finished downloading, navigate to the "Local Server" tab on the left menu and open the loader for text embedding models. This loader does not appear before version 0.2.19, so ensure you downloaded the correct version.

Select the model you just downloaded from the dropdown that appears to load it. You may need to play with configuratios in the right-side menu, such as GPU offload if it doesn't fit entirely into VRAM.

All that's left to do is to hit the "Start Server" button:
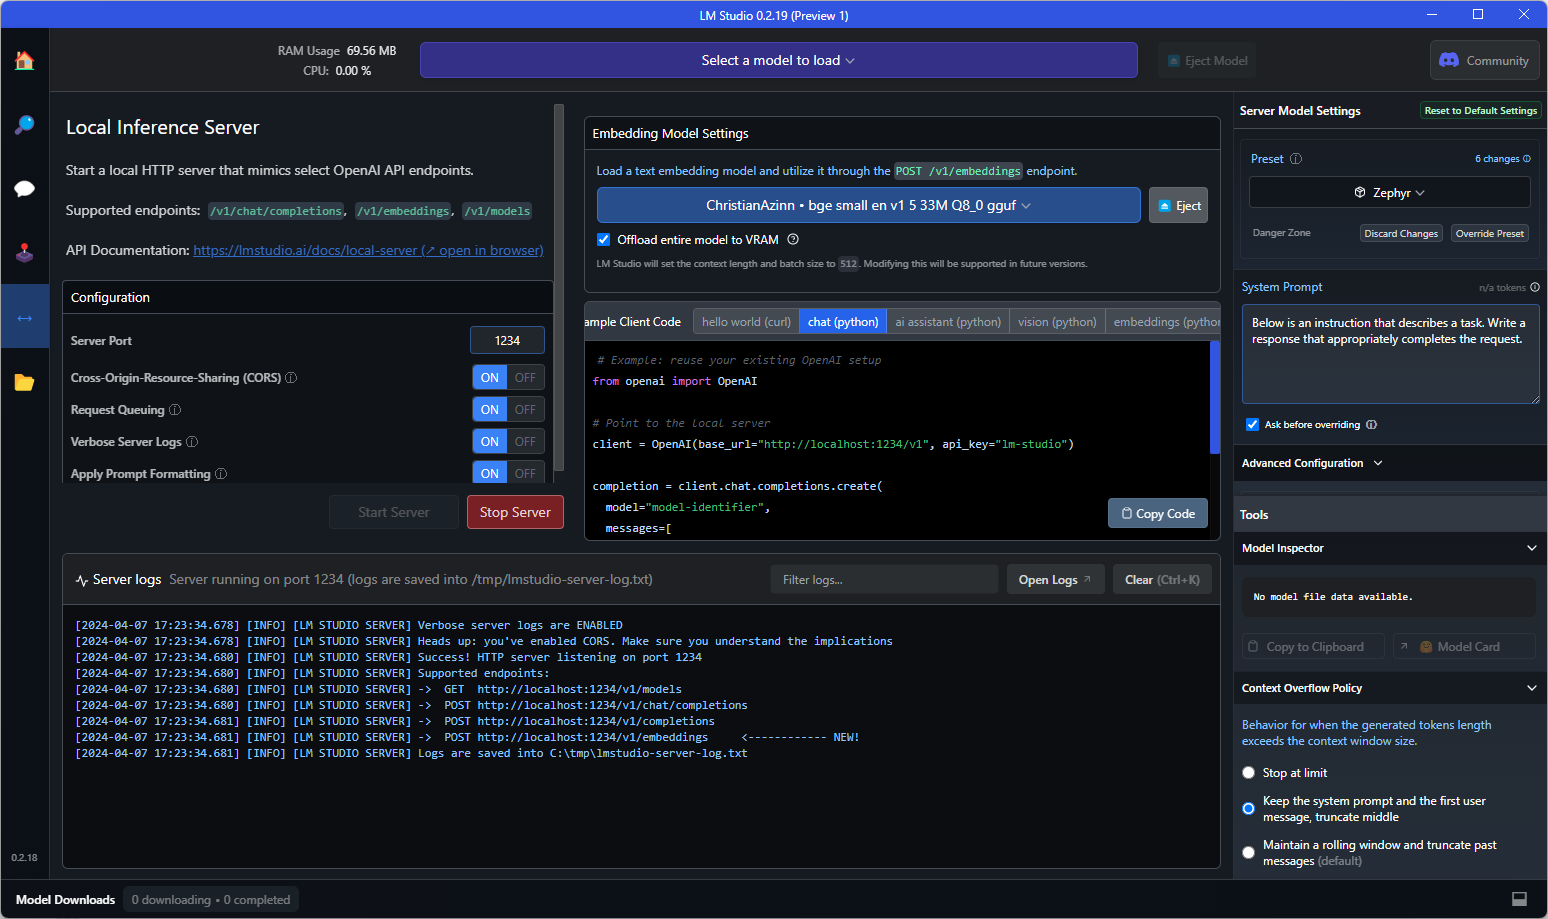
And if you see text like that shown below in the console, you're good to go! You can use this as a drop-in replacement for the OpenAI embeddings API in any application that requires it, or you can query the endpoint directly to test it out.
Example curl request to the API endpoint:
curl http://localhost:1234/v1/embeddings \
  -H "Content-Type: application/json" \
  -d '{
    "input": "Your text string goes here",
    "model": "model-identifier-here"
  }'
For more information, see the LM Studio text embedding documentation.
Acknowledgements
Thanks to the LM Studio team and everyone else working on open-source AI.
This README is inspired by that of nomic-ai-embed-text-v1.5-gguf, another excellent embedding model, and those of the legendary TheBloke.