Kalibrated Vision Exp — DeepSeek-V4-Flash-Vision-Exp (abliterated), EXL3, one DGX Spark
Kalibrated Vision Exp is vcruz305's MixedK pack of DeepSeek-V4-Flash-Vision-Exp with 22 more expert layers re-quantized at a calibrated 3-bit. The K in the name is MixedK's; the "calibrated" is what was added. It is ready to serve on one NVIDIA DGX Spark (GB10, 128 GB) with the recipe in GaelicThunder/DeepSeek-V4-Flash-Vision-One-DGX-Spark: text + images, 245,760 tokens of context, speculative decoding, CUDA graphs.
git clone https://github.com/GaelicThunder/DeepSeek-V4-Flash-Vision-One-DGX-Spark
cd DeepSeek-V4-Flash-Vision-One-DGX-Spark
./start.sh        # downloads this repo (106 GB), serves it, waits for /v1/models, prints a test request
What is in the pack
| vcruz305's MixedK | Kalibrated Vision Exp | |
|---|---|---|
| base model | DeepSeek-V4-Flash-Vision-Exp, abliterated by drowzeys (wo_b of layers 10–35, λ 3.5) | same weights, same abliteration |
| routed experts per layer | 256 | 256 (none pruned) |
| expert bits | 2-bit trellis, 6 layers at 3-bit | 3-bit on 28 layers (his 6 + 22 calibrated), 2-bit on 15 |
| everything else | BF16 non-expert tensors | his tensors, requantized to the FP8 block format the sparkinfer image loads (the same conversion the MixedK route of the recipe applies) |
| layout | 48 exllamav3 shards | rank-sliced tp1 (tp1/) + the DSpark K64 draft (dspark-draft-k64/), i.e. exactly what scripts/serve.sh mounts |
| size | 95 GB | 106 GB; 100.08 GiB resident |
The 22 added layers are 27 23 31 35 32 34 37 40 1 39 25 29 8 30 19 26 24 11 12 9 0 42 (ranked by the measured
quantization error of their expert tensors); MixedK's own 3-bit layers 3 13 21 22 28 41 are kept as they are. The
other 15 expert layers, attention, indexer, shared experts, router rows, hash tables, head, vision tower and the draft's
expert plan are vcruz305's files, unchanged. Same EXL3 trellis format, same mcg codebook.
Quality
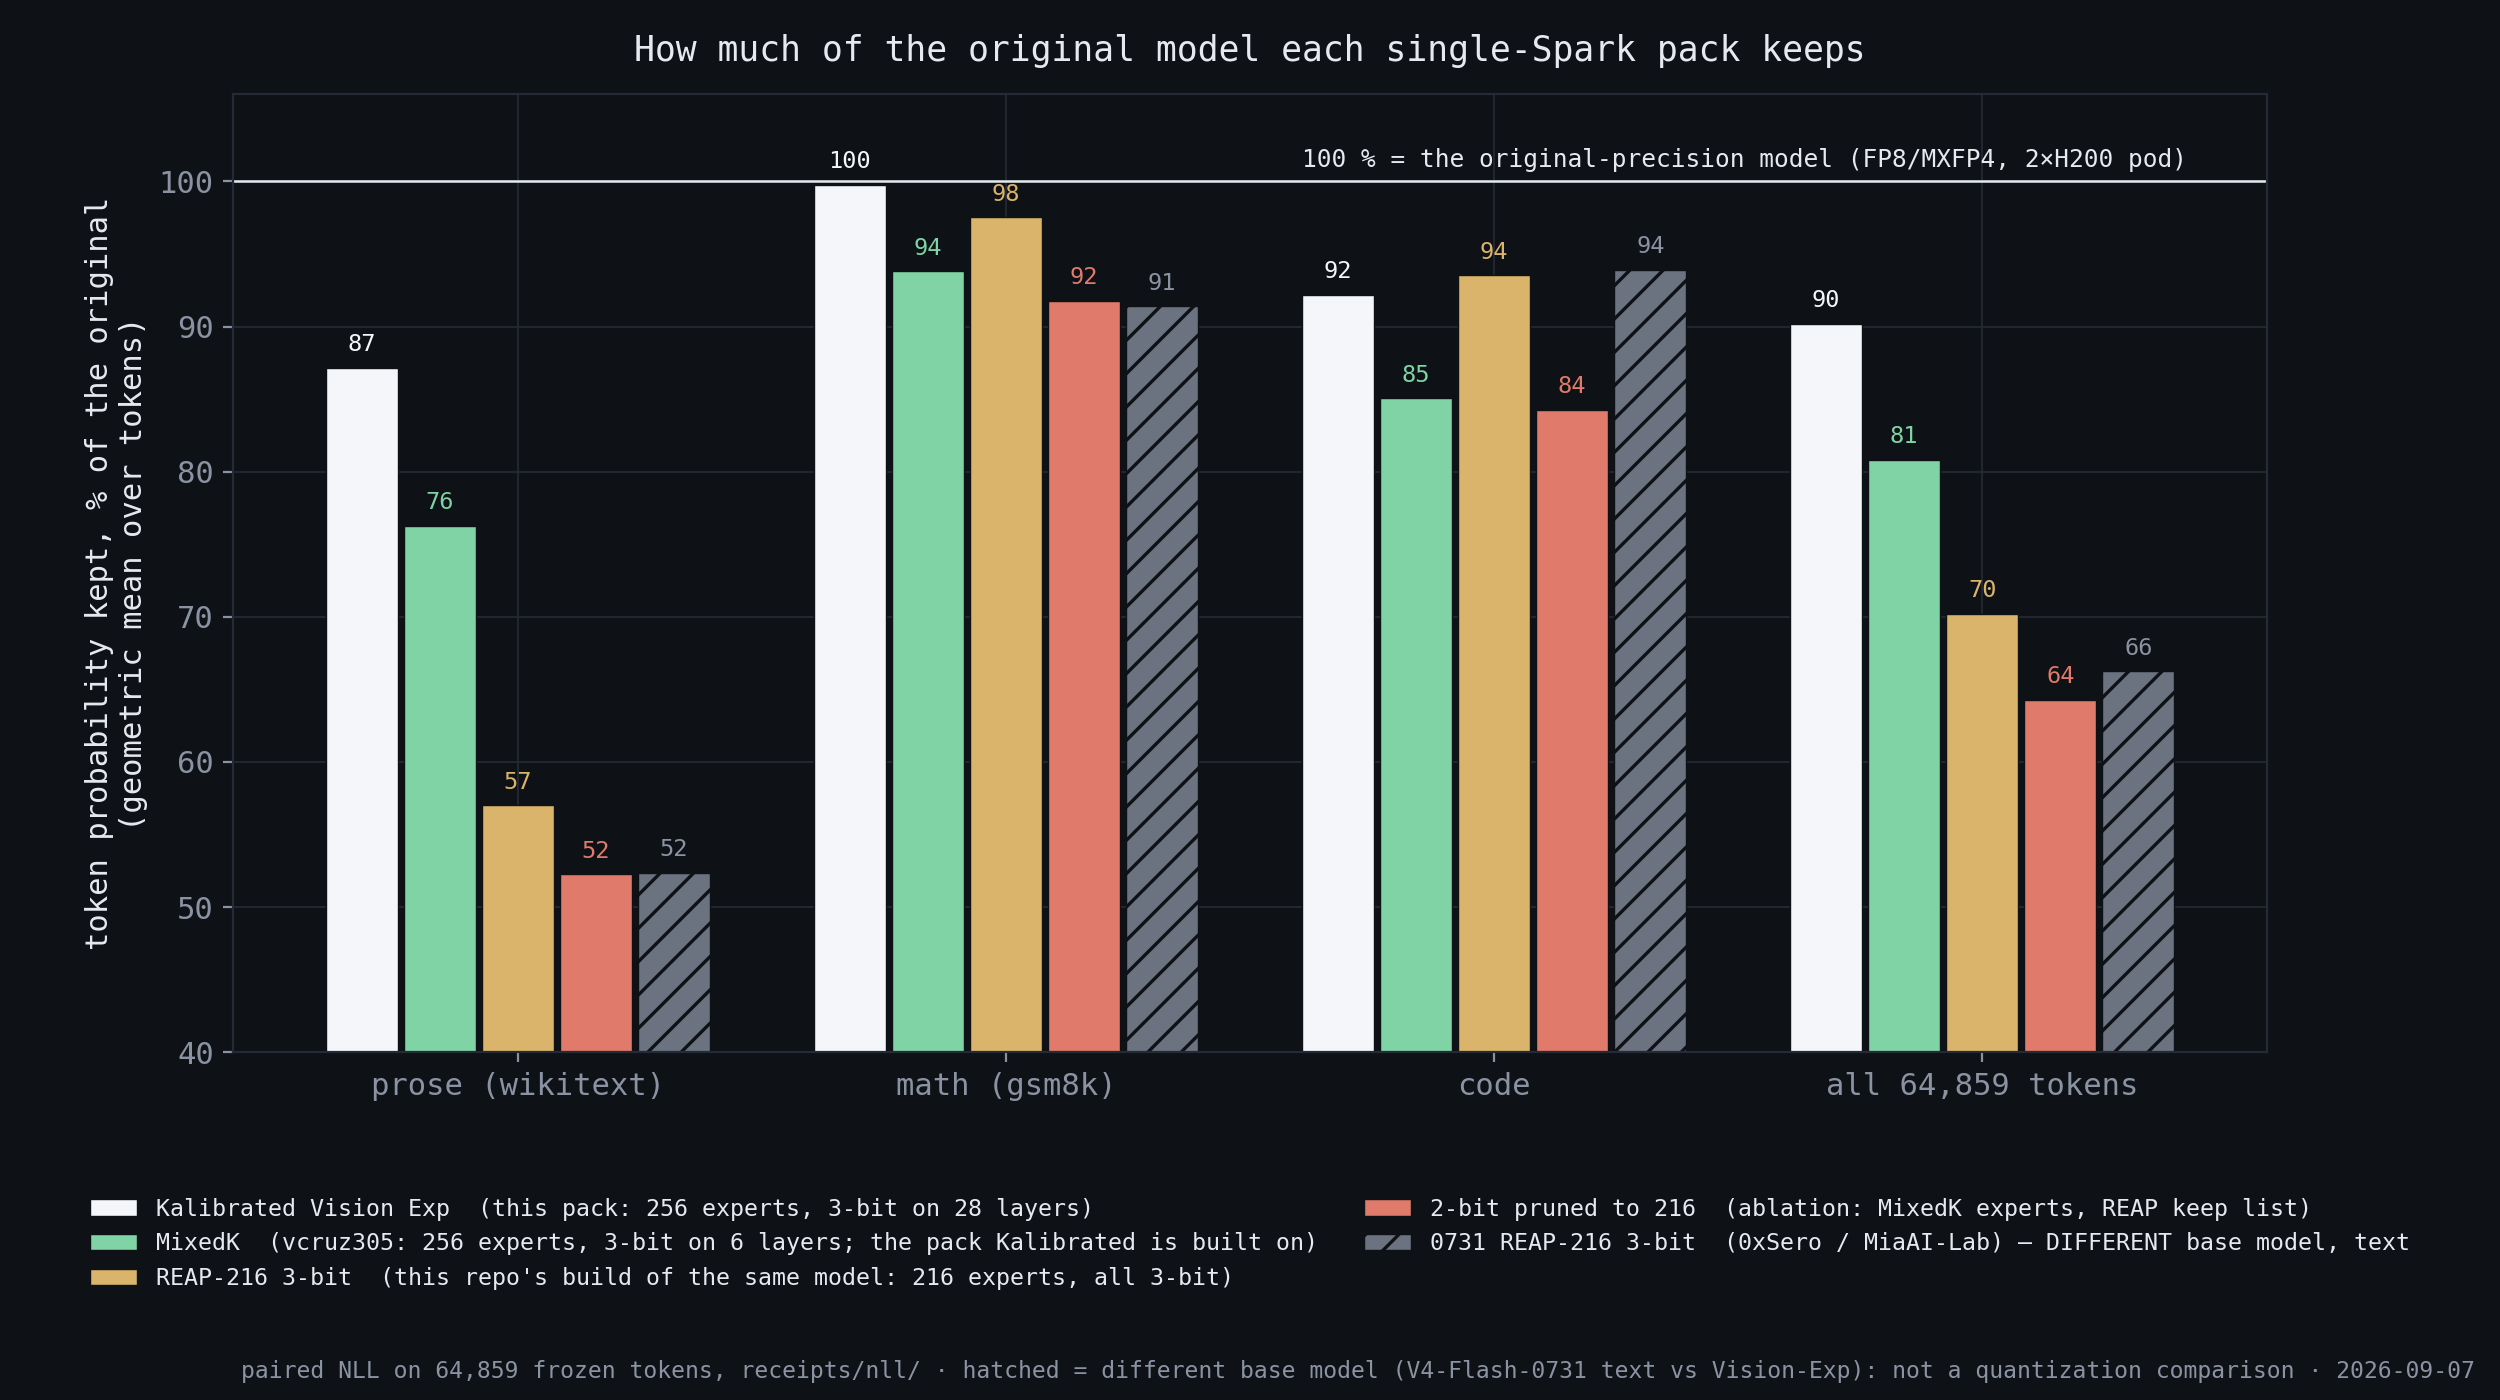
Paired per-token NLL on 64,859 frozen tokens (wikitext · gsm8k · code), greedy, the same items for every pack, against the original-precision release of the same abliterated model (FP8 attention, MXFP4 experts, served with vLLM on a 2×H200 pod). "% kept" is exp(−Δ mean NLL): the geometric mean over tokens of p_pack / p_original. 100 % is the original.
| % of the original's token probability kept | prose | math | code | all |
|---|---|---|---|---|
| Kalibrated Vision Exp | 87 % | 99.8 % | 92 % | 90 % |
| MixedK (vcruz305) | 76 % | 94 % | 85 % | 81 % |
| REAP-216 3-bit of the same model (216 experts, all 3-bit) | 57 % | 98 % | 94 % | 70 % |
Kalibrated − MixedK, paired on the same tokens: −0.133 ± 0.005 nats on prose, −0.062 ± 0.008 on math, −0.081 ± 0.005
on code. MMLU-Pro (251 items, two option orders): 63.2 % vs 64.3 %, a tie within the harness noise of ±1 item.
Perplexity on 8 fixed passages 4.487 vs 4.545. The 0731 text packs (0xSero / MiaAI-Lab) are a different base model
(V4-Flash-0731) and are not in this table; the cross-model comparison with its caveat, the experts-versus-bits study
with byte-identical weights, the layer choice and every receipt are in
docs/KALIBRATED.md.
Serving on one GB10
| measured | |
|---|---|
| context | 245,760 tokens per request; KV pool 269,471 tokens at gpu_memory_utilization 0.925 |
| decode, DSpark K5 draft | 37.6 tok/s code · 34.1 counting · 19.7 free prose with thinking (medians of 3) |
| load | 28 s with a warm page cache; the first boot compiles ~10 min of kernels |
| images | 1 to 3 per prompt verified, same endpoint (image_url) |
The memory budget: with the non-expert tensors in FP8 and CUDA graphs (the sparkinfer image) about 16 GiB more are free than on the PyPI vLLM + plugin stack, and this pack spends them on expert bits rather than on a bigger KV pool (MixedK on the same image holds 986k tokens). 26 promoted layers load but leave no room for one 245k request, so the pack stops at 22. Never set the utilization above 0.93 on a 128 GB Spark.
Known issue, mitigated: the serving stack occasionally emits the token )Skip at clause ends (a decode-path
logits fault, documented in the recipe). start.sh puts a small proxy in front of the engine that adds
"bad_words": [")Skip", ",Skip", ".Skip"] to every request; if you serve the pack another way, add it yourself.
How it was built
exllamav3 (0531096 + the recipe's conversion patch) on a 2×H200 pod, a per-tensor recipe with 3-bit on the chosen
layers, -cb mcg -cr 250 -cpi 600, the non-promoted layers stored at 16 bit during the run so the calibration
activations stay exact; each finished layer spliced into a 256-expert file in MixedK's exact 3-bit layer layout.
Scripts: scripts/kalibrated/.
Credits
- vcruz305 — this is his MixedK pack with 22 layers added, nothing less: the 2-bit experts, the non-expert tensors,
the vision tower, the six original 3-bit layers and the draft plan are his files, and his recipe found the same
load_weightsbug on the same day. If he wants the 22 layer files folded into the MixedK pack itself, they are his to take: same format, same layout, same license. - DeepSeek for DeepSeek-V4-Flash-Vision-Exp; drowzeys for the abliteration the weights carry.
- 0xSero for the sparkinfer image and the rank-sliced tp1 layout; MiaAI-Lab for the single-Spark recipe; turboderp for EXL3 and a converter that takes a per-tensor recipe.
License and terms
DeepSeek-V4-Flash-Vision-Exp is released under the MIT license; this pack carries the same license. The weights have had their refusals removed upstream (see the source's terms): they are published for red-teaming, security research and evaluation, and you are responsible for your deployment and jurisdiction.