Code-Qwen3-1.7B-Qwen3-4B-Non-Thinking-RL-Code-Step300
Paper · GitHub · Project · Collection
This repository contains an on-policy distillation (OPD) student checkpoint released with Towards Understanding On-Policy Distillation through the Lens of Test-Time Scaling. Its base model, teacher, and training data are listed below.
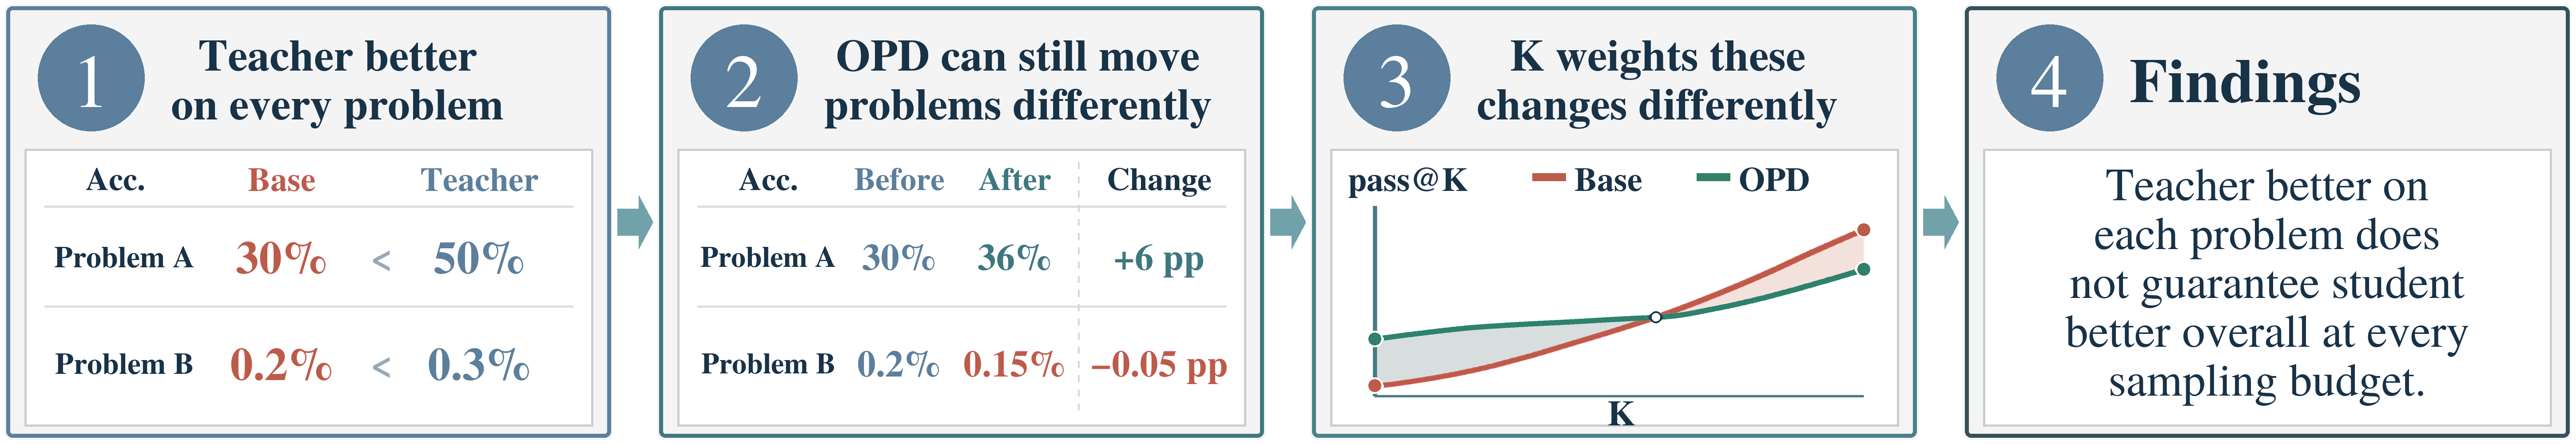
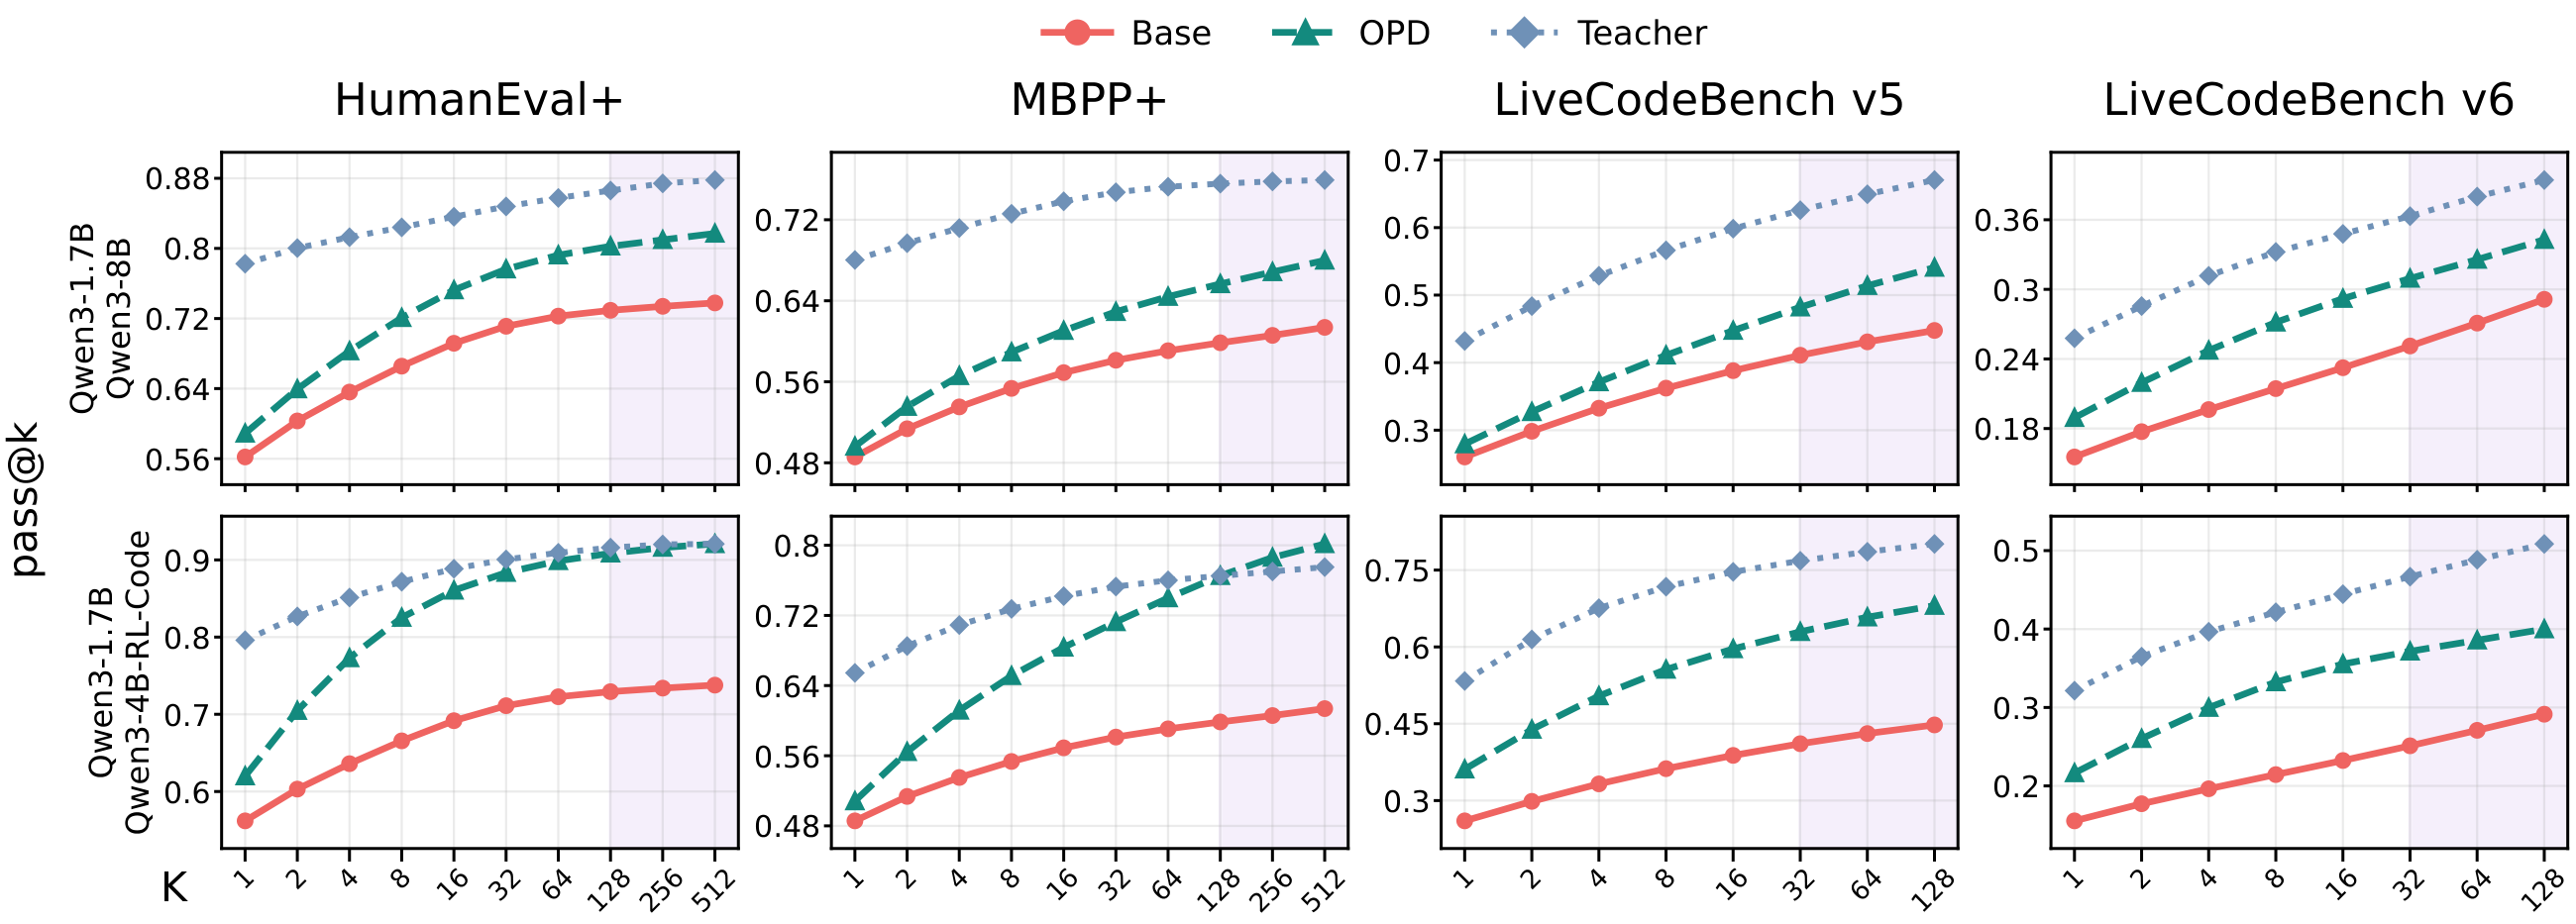
The figure reports paper results across code settings; it is not a scorecard for this checkpoint alone.
Checkpoint details
- Base model: Qwen/Qwen3-1.7B
- Teacher model: Keven16/Qwen3-4B-Non-Thinking-RL-Code-Step300
- Training data: CodeR1-12K coding problems sourced from LeetCode and TACO.
Step300 belongs to the teacher model name; it does not identify a student training step.
More information
See the paper and GitHub repository for training settings, evaluation protocols, and analysis. Upstream model and data terms remain applicable; see third-party notices.
Citation
@misc{ge2026understandingonpolicydistillationlens,
  title={Towards Understanding On-Policy Distillation through the Lens of Test-Time Scaling},
  author={Xinmu Ge and Zizhuo Zhang and Yu Huang and Jianing Zhu and Lin Yuan and Wanli Gu and Weichang Wu and Weiran Huang and Bo Han and Xiaolu Zhang and Jiangchao Yao},
  year={2026},
  eprint={2608.11829},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  doi={10.48550/arXiv.2608.11829},
  url={https://arxiv.org/abs/2608.11829}
}