ACertainModel
Try full functions with Google Colab free T4 
Check Twitter #ACertainModel for community artworks
Welcome to ACertainModel - a latent diffusion model for weebs. This model is intended to produce high-quality, highly detailed anime style pictures with just a few prompts. Like other anime-style Stable Diffusion models, it also supports danbooru tags, including artists, to generate images.
Since I noticed that the laion-aesthetics introduced in the Stable-Diffusion-v-1-4 checkpoint hindered finetuning anime style illustration generation model, Dreambooth was used to finetune some tags separately to make it closer to what it was in SD1.2. To avoid overfitting and possible language drift, I added a huge amount of auto-generated pictures from a single word prompt to the training set, using models that are popular in the community such as Anything-3.0, together with partially manual selected full-danbooru images within a year, for further native training. I am also aware of a method of LoRA, with a similar idea, finetuning attention layer solely, to have better performance on eyes, hands, and other details.
For copyright compliance and technical experiment, it was trained from few artist images directly. It was trained on Dreambooth with pictures generated from several popular diffusion models in the community. The checkpoint was initialized with the weights of a Stable Diffusion Model and subsequently fine-tuned for 2K GPU hours on V100 32GB and 600 GPU hours on A100 40GB at 512P dynamic aspect ratio resolution with a certain ratio of unsupervised auto-generated images from several popular diffusion models in the community with some Textual Inversions and Hypernetworks. We do know some tricks on xformers and 8-bit optimization, but we didn't use any of them for better quality and stability. Up to 15 branches are trained simultaneously, cherry-picking about every 20,000 steps.
e.g. masterpiece, best quality, 1girl, brown hair, green eyes, colorful, autumn, cumulonimbus clouds, lighting, blue sky, falling leaves, garden
About online preview with Hosted inference API, also generation with this model
Parameters are not allowed to be modified, as it seems that it is generated with Clip skip: 1, for better performance, it is strongly recommended to use Clip skip: 2 instead.
Here is an example of inference settings, if it is applicable with you on your own server: Steps: 28, Sampler: Euler a, CFG scale: 11, Clip skip: 2.
🧨 Diffusers
This model can be used just like any other Stable Diffusion model. For more information, please have a look at the Stable Diffusion.
You can also export the model to ONNX, MPS and/or FLAX/JAX.
from diffusers import StableDiffusionPipeline
import torch

model_id = "JosephusCheung/ACertainModel"
branch_name= "main"

pipe = StableDiffusionPipeline.from_pretrained(model_id, revision=branch_name, torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "pikachu"
image = pipe(prompt).images[0]

image.save("./pikachu.png")
Examples
Below are some examples of images generated using this model, with better performance on framing and hand gestures, as well as moving objects, comparing to other analogues:
Anime Girl:

1girl, brown hair, green eyes, colorful, autumn, cumulonimbus clouds, lighting, blue sky, falling leaves, garden
Steps: 28, Sampler: Euler a, CFG scale: 11, Seed: 114514, Clip skip: 2
Anime Boy:
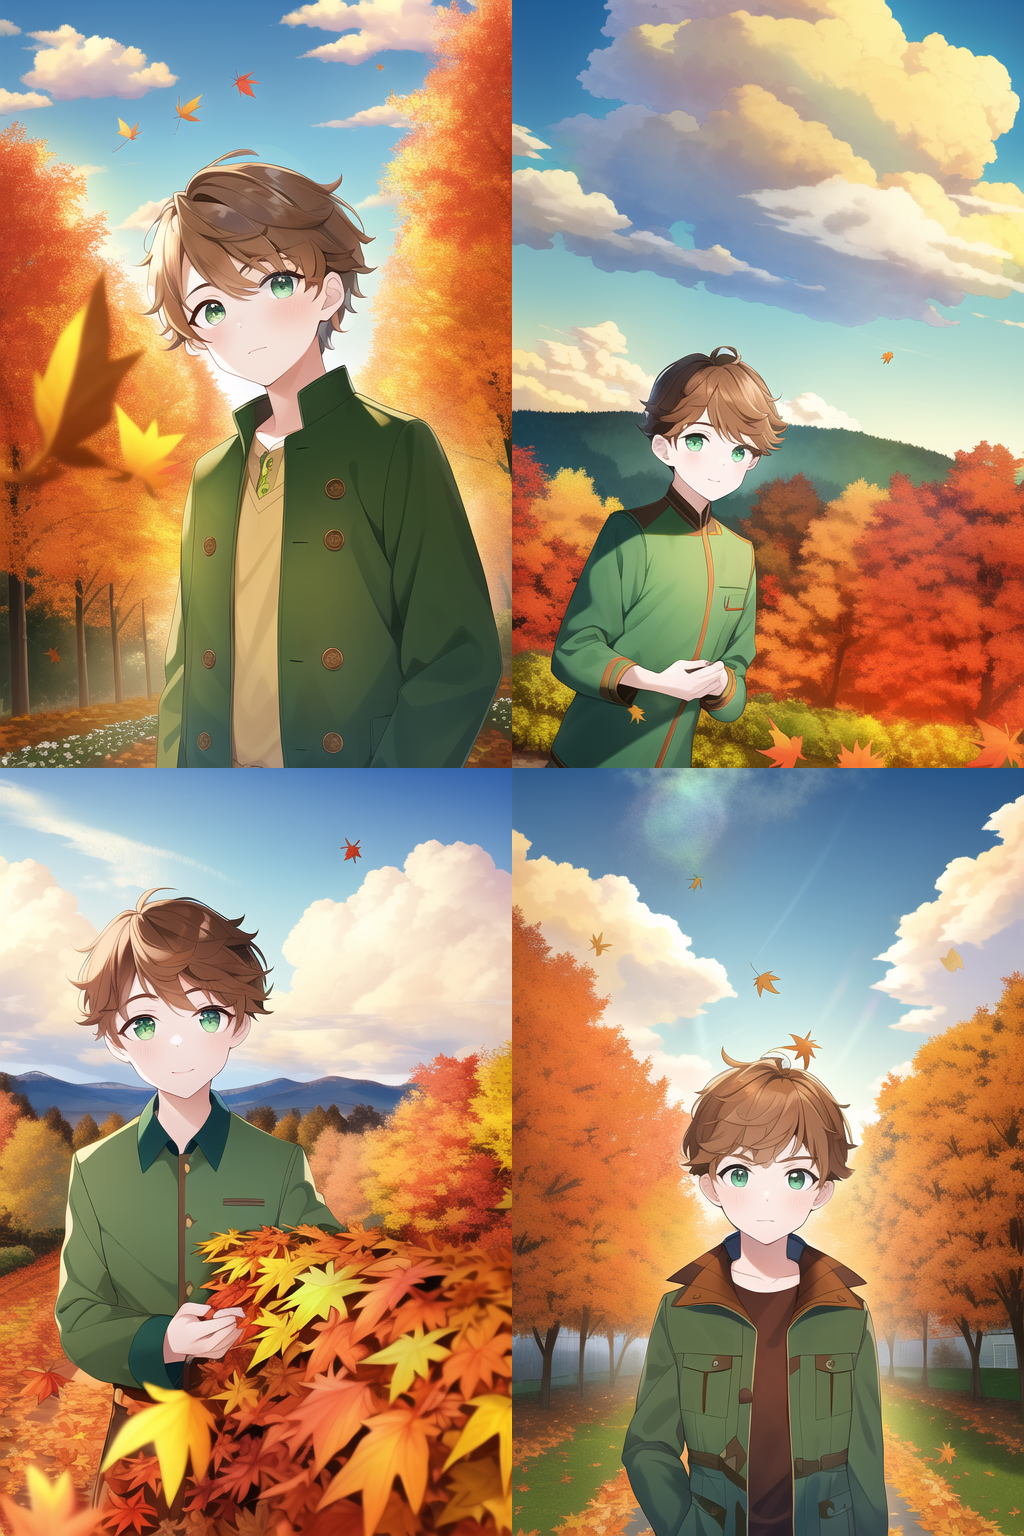
1boy, brown hair, green eyes, colorful, autumn, cumulonimbus clouds, lighting, blue sky, falling leaves, garden
Steps: 28, Sampler: Euler a, CFG scale: 11, Seed: 114514, Clip skip: 2
License
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies:
- You can't use the model to deliberately produce nor share illegal or harmful outputs or content
- The authors claims no rights on the outputs you generate, you are free to use them and are accountable for their use which must not go against the provisions set in the license
- You may re-distribute the weights and use the model commercially and/or as a service. If you do, please be aware you have to include the same use restrictions as the ones in the license and share a copy of the CreativeML OpenRAIL-M to all your users (please read the license entirely and carefully) Please read the full license here