ACertainThing
Try full functions with Google Colab free T4 
Anything3.0 is an overfitted model that takes liberties when it shouldn't be generating human images and certain details. However, the community has given it a high rating, and I believe that is because many lazy people who don't know how to write a prompt can use this overfitted model to generate high-quality images even if their prompts are poorly written.
Here is a ACertain version of Anything3.0, made with Dreambooth (idea of LoRA integrated), initialized with ACertainModel.
Although this model may produce better results for image generation, it is built on two major problems. Firstly, it does not always stay true to your prompts; it adds irrelevant details, and sometimes these details are highly homogenized. Secondly, it is an unstable, overfitted model, similar to Anything3.0, and is not suitable for any form of further training. As far as I know, Anything3.0 is obtained by merging several models in just the right way, but it is itself an overfitted model with defects in both its saturation and configuration. However, as I mentioned earlier, it can make even poorly written prompts produce good output images, which leads many lazy people who are incapable of writing good prompts to quickly surpass those who study the writing of prompts carefully. Despite these problems, I still want to release an extended version of the model that caters to the preferences of many people in the community. I hope would you like it.
In my personal view, I oppose all forms of model merging as it has no scientific principle and is nothing but a waste of time. It is a desire to get results without putting in the effort. That is why I do not like Anything3.0, or this model that is being released. But I respect the choices and preferences of the community, and I hope that you can also respect and understand my thoughts.
If you want your prompts to be accurately output and want to learn the correct skills for using prompts, it is recommended that you use the more balanced model ACertainModel.
e.g. masterpiece, best quality, 1girl, brown hair, green eyes, colorful, autumn, cumulonimbus clouds, lighting, blue sky, falling leaves, garden
About online preview with Hosted inference API, also generation with this model
Parameters are not allowed to be modified, as it seems that it is generated with Clip skip: 1, for better performance, it is strongly recommended to use Clip skip: 2 instead.
Here is an example of inference settings, if it is applicable with you on your own server: Steps: 28, Sampler: Euler a, CFG scale: 11, Clip skip: 2.
🧨 Diffusers
This model can be used just like any other Stable Diffusion model. For more information, please have a look at the Stable Diffusion.
You can also export the model to ONNX, MPS and/or FLAX/JAX.
from diffusers import StableDiffusionPipeline
import torch

model_id = "JosephusCheung/ACertainThing"
branch_name= "main"

pipe = StableDiffusionPipeline.from_pretrained(model_id, revision=branch_name, torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "pikachu"
image = pipe(prompt).images[0]

image.save("./pikachu.png")
Examples
Below are some examples of images generated using this model, with better performance on framing and hand gestures, as well as moving objects, comparing to other analogues:
Anime Girl:
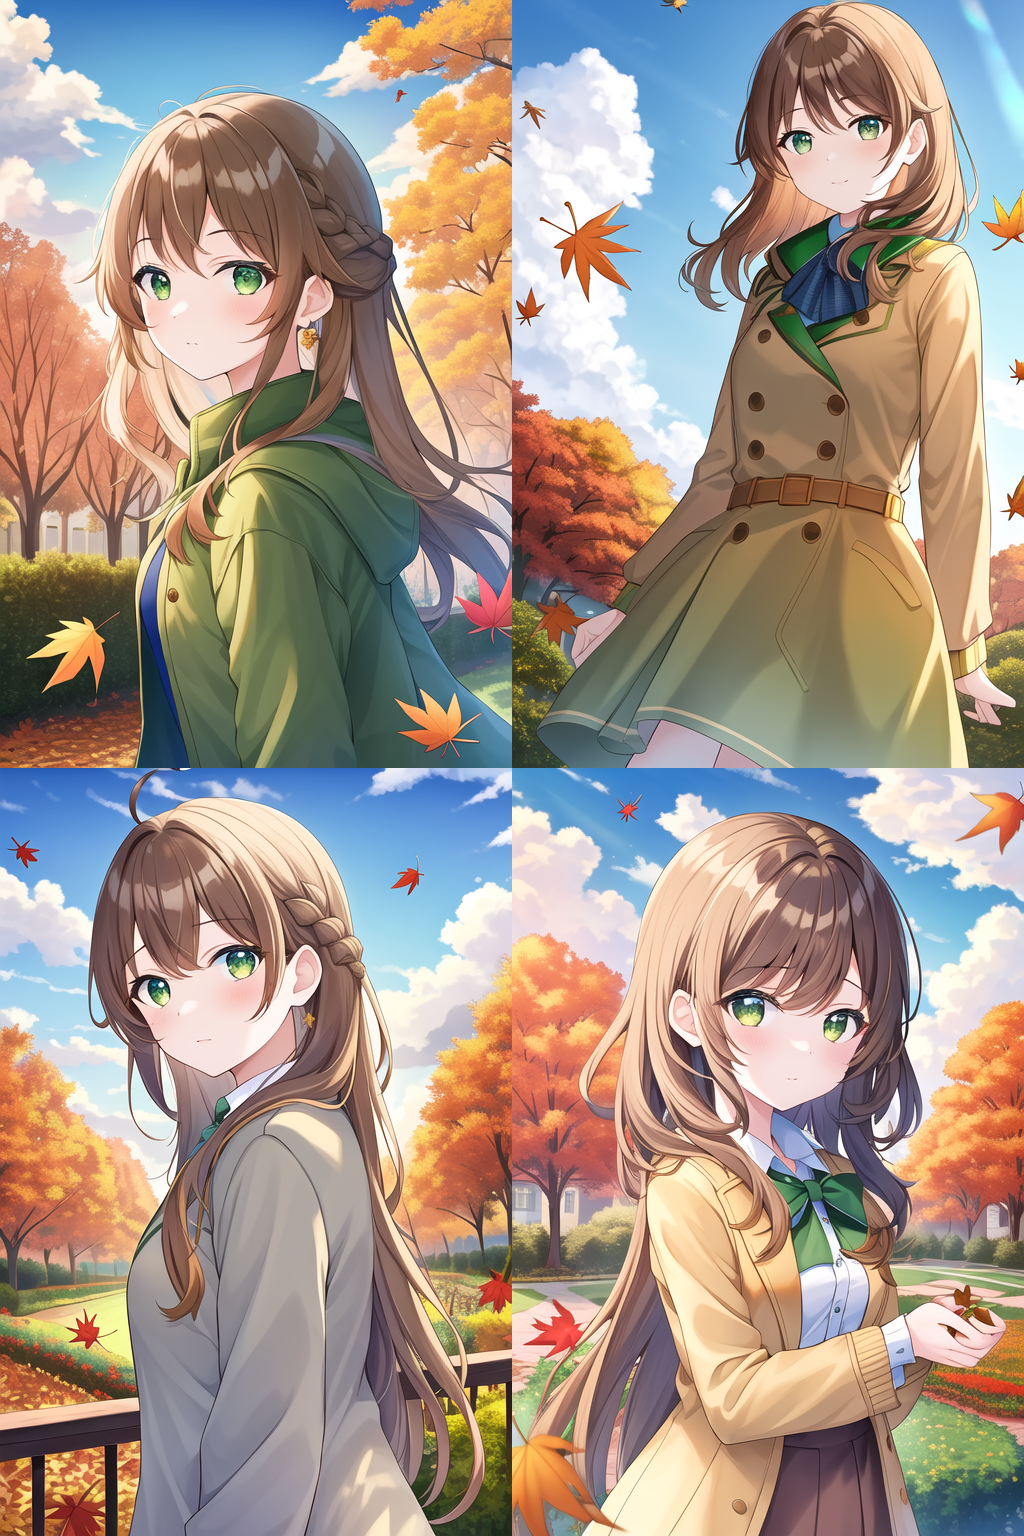
1girl, brown hair, green eyes, colorful, autumn, cumulonimbus clouds, lighting, blue sky, falling leaves, garden
Steps: 28, Sampler: Euler a, CFG scale: 11, Seed: 114514, Clip skip: 2
Anime Boy:
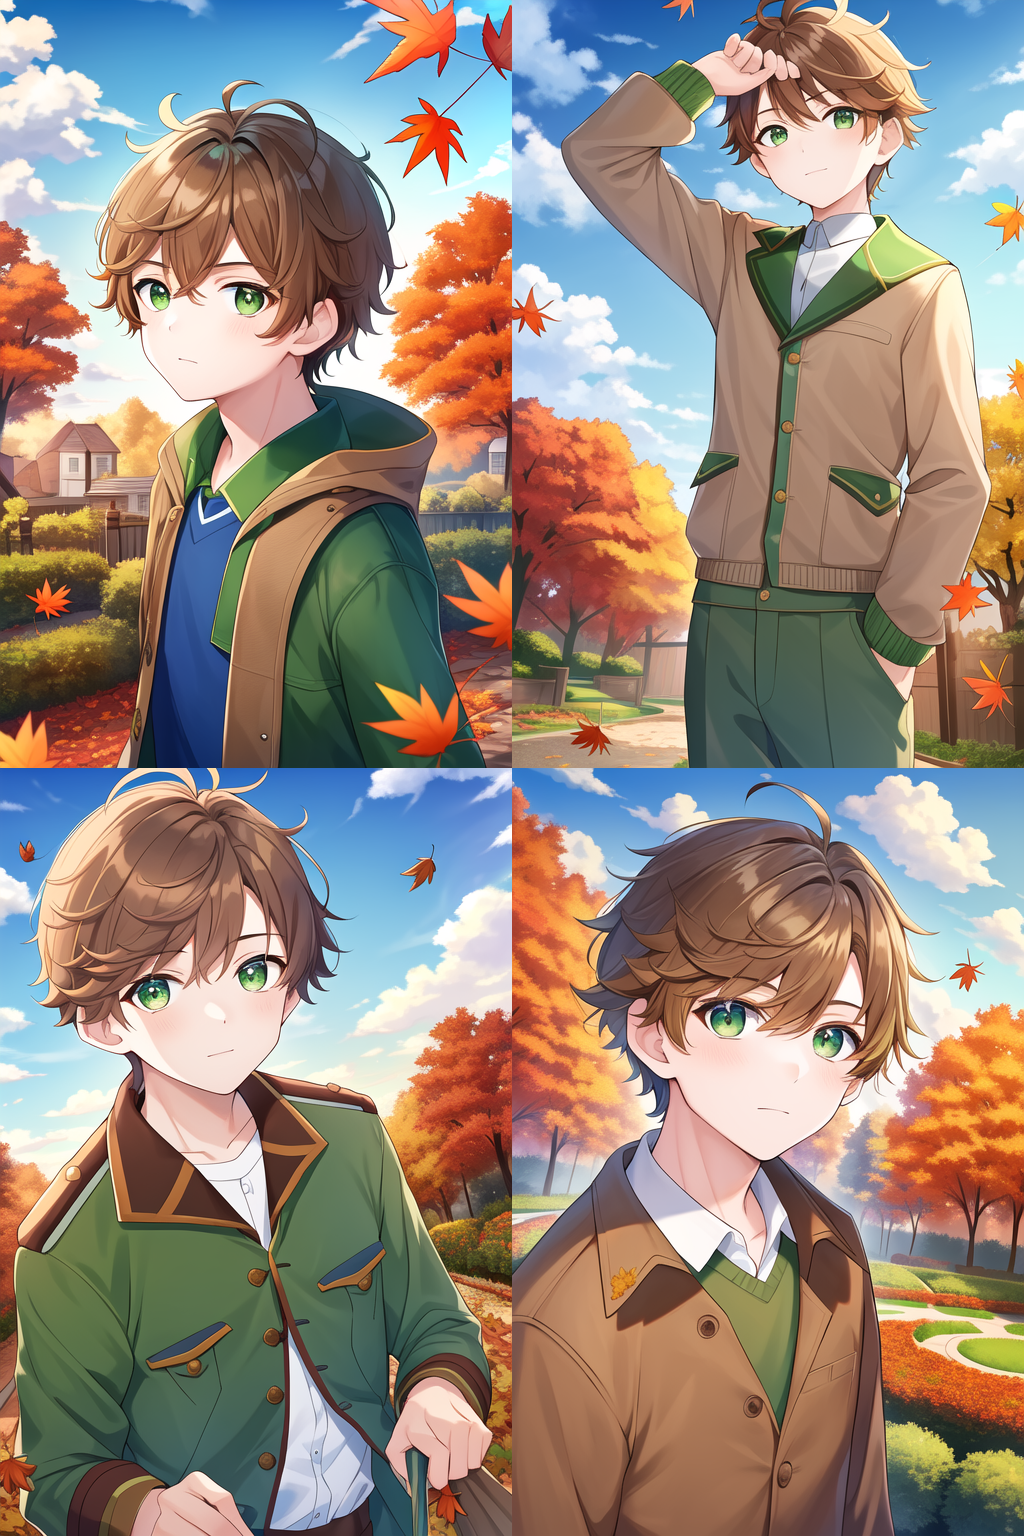
1boy, brown hair, green eyes, colorful, autumn, cumulonimbus clouds, lighting, blue sky, falling leaves, garden
Steps: 28, Sampler: Euler a, CFG scale: 11, Seed: 114514, Clip skip: 2
License
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies:
- You can't use the model to deliberately produce nor share illegal or harmful outputs or content
- The authors claims no rights on the outputs you generate, you are free to use them and are accountable for their use which must not go against the provisions set in the license
- You may re-distribute the weights and use the model commercially and/or as a service. If you do, please be aware you have to include the same use restrictions as the ones in the license and share a copy of the CreativeML OpenRAIL-M to all your users (please read the license entirely and carefully) Please read the full license here