German BERT
Overview
Language model: bert-base-cased
Language: German
Training data: Wiki, OpenLegalData, News (~ 12GB)
Eval data: Conll03 (NER), GermEval14 (NER), GermEval18 (Classification), GNAD (Classification)
Infrastructure: 1x TPU v2
Published: Jun 14th, 2019
Update April 3rd, 2020: we updated the vocabulary file on deepset's s3 to conform with the default tokenization of punctuation tokens. For details see the related FARM issue. If you want to use the old vocab we have also uploaded a "deepset/bert-base-german-cased-oldvocab" model.
Details
- We trained using Google's Tensorflow code on a single cloud TPU v2 with standard settings.
- We trained 810k steps with a batch size of 1024 for sequence length 128 and 30k steps with sequence length 512. Training took about 9 days.
- As training data we used the latest German Wikipedia dump (6GB of raw txt files), the OpenLegalData dump (2.4 GB) and news articles (3.6 GB).
- We cleaned the data dumps with tailored scripts and segmented sentences with spacy v2.1. To create tensorflow records we used the recommended sentencepiece library for creating the word piece vocabulary and tensorflow scripts to convert the text to data usable by BERT.
See https://deepset.ai/german-bert for more details
Hyperparameters
batch_size = 1024
n_steps = 810_000
max_seq_len = 128 (and 512 later)
learning_rate = 1e-4
lr_schedule = LinearWarmup
num_warmup_steps = 10_000
Performance
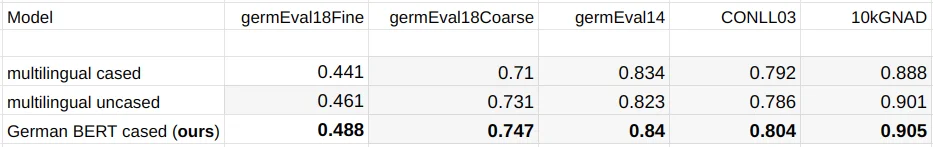
During training we monitored the loss and evaluated different model checkpoints on the following German datasets:
- germEval18Fine: Macro f1 score for multiclass sentiment classification
- germEval18coarse: Macro f1 score for binary sentiment classification
- germEval14: Seq f1 score for NER (file names deuutf.*)
- CONLL03: Seq f1 score for NER
- 10kGNAD: Accuracy for document classification
Even without thorough hyperparameter tuning, we observed quite stable learning especially for our German model. Multiple restarts with different seeds produced quite similar results.
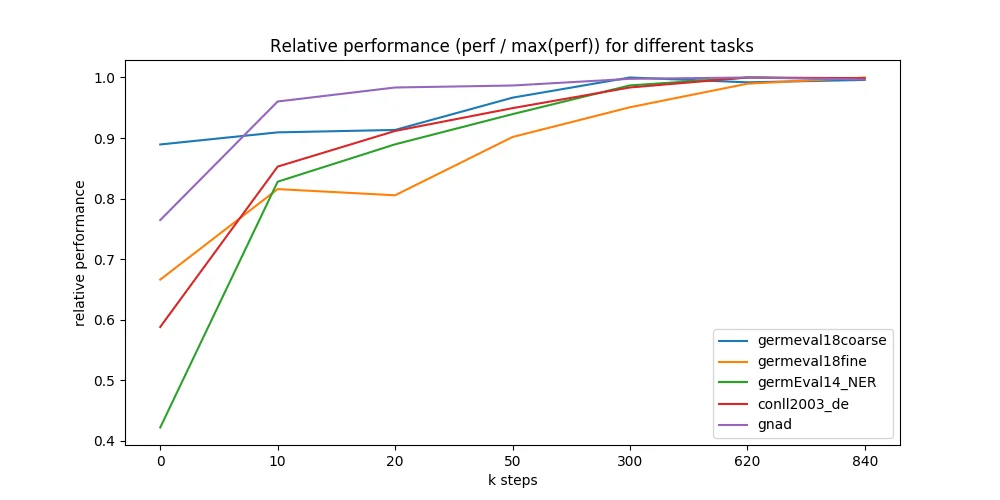
We further evaluated different points during the 9 days of pre-training and were astonished how fast the model converges to the maximally reachable performance. We ran all 5 downstream tasks on 7 different model checkpoints - taken at 0 up to 840k training steps (x-axis in figure below). Most checkpoints are taken from early training where we expected most performance changes. Surprisingly, even a randomly initialized BERT can be trained only on labeled downstream datasets and reach good performance (blue line, GermEval 2018 Coarse task, 795 kB trainset size).
Authors
- Branden Chan:
branden.chan [at] deepset.ai - Timo Möller:
timo.moeller [at] deepset.ai - Malte Pietsch:
malte.pietsch [at] deepset.ai - Tanay Soni:
tanay.soni [at] deepset.ai
About us
We bring NLP to the industry via open source!
Our focus: Industry specific language models & large scale QA systems.
Some of our work: