OpenOrca-Platypus2-13B
OpenOrca-Platypus2-13B is a merge of garage-bAInd/Platypus2-13B and Open-Orca/OpenOrcaxOpenChat-Preview2-13B.
This model is more than the sum of its parts! We are happy to be teaming up with the Platypus team to bring you a new model which once again tops the leaderboards!
Want to visualize our full (pre-filtering) dataset? Check out our Nomic Atlas Map.
We are in-process with training more models, so keep a look out on our org for releases coming soon with exciting partners.
We will also give sneak-peak announcements on our Discord, which you can find here:
Evaluation
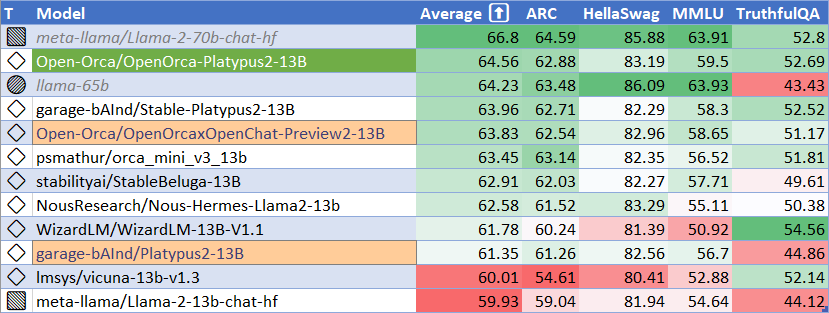
HuggingFace Leaderboard Performance
| Metric | Value |
|---|---|
| MMLU (5-shot) | 59.5 |
| ARC (25-shot) | 62.88 |
| HellaSwag (10-shot) | 83.19 |
| TruthfulQA (0-shot) | 52.69 |
| Avg. | 64.56 |
We use Language Model Evaluation Harness to run the benchmark tests above, using the same version as the HuggingFace LLM Leaderboard.
Please see below for detailed instructions on reproducing benchmark results.
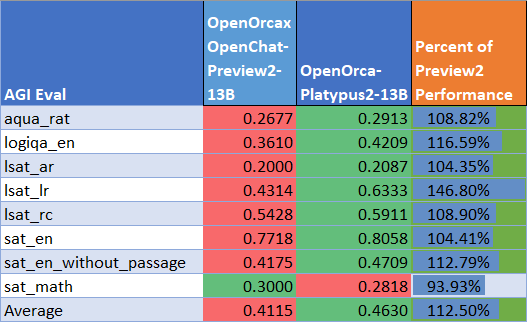
AGIEval Performance
We compare our results to our base Preview2 model (using LM Evaluation Harness).
We find 112% of the base model's performance on AGI Eval, averaging 0.463. A large part of this boost is the substantial improvement to LSAT Logical Reasoning performance.
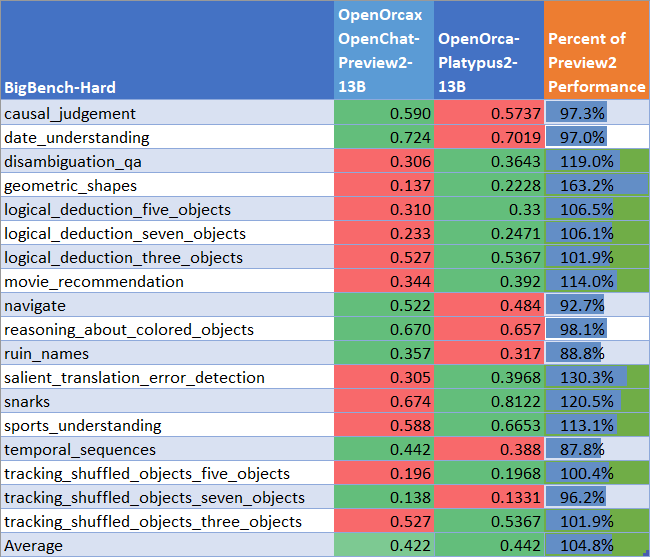
BigBench-Hard Performance
We compare our results to our base Preview2 model (using LM Evaluation Harness).
We find 105% of the base model's performance on BigBench-Hard, averaging 0.442.
Model Details
- Trained by: Platypus2-13B trained by Cole Hunter & Ariel Lee; OpenOrcaxOpenChat-Preview2-13B trained by Open-Orca
- Model type: OpenOrca-Platypus2-13B is an auto-regressive language model based on the Lllama 2 transformer architecture.
- Language(s): English
- License for Platypus2-13B base weights: Non-Commercial Creative Commons license (CC BY-NC-4.0)
- License for OpenOrcaxOpenChat-Preview2-13B base weights: Llama 2 Commercial
Prompting
Prompt Template for base Platypus2-13B
### Instruction:

<prompt> (without the <>)

### Response:
Prompt Template for base OpenOrcaxOpenChat-Preview2-13B
OpenChat Llama2 V1: see OpenOrcaxOpenChat-Preview2-13B for additional information.
Training
Training Datasets
garage-bAInd/Platypus2-13B trained using STEM and logic based dataset garage-bAInd/Open-Platypus.
Please see our paper and project webpage for additional information.
Open-Orca/OpenOrcaxOpenChat-Preview2-13B trained using a refined subset of most of the GPT-4 data from the OpenOrca dataset.
Training Procedure
Open-Orca/Platypus2-13B was instruction fine-tuned using LoRA on 1x A100-80GB.
For training details and inference instructions please see the Platypus GitHub repo.
Supplemental
Reproducing Evaluation Results (for HuggingFace Leaderboard Eval)
Install LM Evaluation Harness:
# clone repository
git clone https://github.com/EleutherAI/lm-evaluation-harness.git
# change to repo directory
cd lm-evaluation-harness
# check out the correct commit
git checkout b281b0921b636bc36ad05c0b0b0763bd6dd43463
# install
pip install -e .
Each task was evaluated on a single A100-80GB GPU.
ARC:
python main.py --model hf-causal-experimental --model_args pretrained=Open-Orca/OpenOrca-Platypus2-13B --tasks arc_challenge --batch_size 1 --no_cache --write_out --output_path results/OpenOrca-Platypus2-13B/arc_challenge_25shot.json --device cuda --num_fewshot 25
HellaSwag:
python main.py --model hf-causal-experimental --model_args pretrained=Open-Orca/OpenOrca-Platypus2-13B --tasks hellaswag --batch_size 1 --no_cache --write_out --output_path results/OpenOrca-Platypus2-13B/hellaswag_10shot.json --device cuda --num_fewshot 10
MMLU:
python main.py --model hf-causal-experimental --model_args pretrained=Open-Orca/OpenOrca-Platypus2-13B --tasks hendrycksTest-* --batch_size 1 --no_cache --write_out --output_path results/OpenOrca-Platypus2-13B/mmlu_5shot.json --device cuda --num_fewshot 5
TruthfulQA:
python main.py --model hf-causal-experimental --model_args pretrained=Open-Orca/OpenOrca-Platypus2-13B --tasks truthfulqa_mc --batch_size 1 --no_cache --write_out --output_path results/OpenOrca-Platypus2-13B/truthfulqa_0shot.json --device cuda
Limitations and bias
Llama 2 and fine-tuned variants are a new technology that carries risks with use. Testing conducted to date has been in English, and has not covered, nor could it cover all scenarios. For these reasons, as with all LLMs, Llama 2 and any fine-tuned varient's potential outputs cannot be predicted in advance, and the model may in some instances produce inaccurate, biased or other objectionable responses to user prompts. Therefore, before deploying any applications of Llama 2 variants, developers should perform safety testing and tuning tailored to their specific applications of the model.
Please see the Responsible Use Guide available at https://ai.meta.com/llama/responsible-use-guide/
Citations
@software{hunterlee2023orcaplaty1
  title = {OpenOrcaPlatypus: Llama2-13B Model Instruct-tuned on Filtered OpenOrcaV1 GPT-4 Dataset and Merged with divergent STEM and Logic Dataset Model},
  author = {Ariel N. Lee and Cole J. Hunter and Nataniel Ruiz and Bleys Goodson and Wing Lian and Guan Wang and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://huggingface.co/Open-Orca/OpenOrca-Platypus2-13B},
}
@article{platypus2023,
    title={Platypus: Quick, Cheap, and Powerful Refinement of LLMs},
    author={Ariel N. Lee and Cole J. Hunter and Nataniel Ruiz},
    booktitle={arXiv preprint arxiv:2308.07317},
    year={2023}
}
@software{OpenOrcaxOpenChatPreview2,
  title = {OpenOrcaxOpenChatPreview2: Llama2-13B Model Instruct-tuned on Filtered OpenOrcaV1 GPT-4 Dataset},
  author = {Guan Wang and Bleys Goodson and Wing Lian and Eugene Pentland and Austin Cook and Chanvichet Vong and "Teknium"},
  year = {2023},
  publisher = {HuggingFace},
  journal = {HuggingFace repository},
  howpublished = {\url{https://https://huggingface.co/Open-Orca/OpenOrcaxOpenChat-Preview2-13B},
}
@software{openchat,
  title = {{OpenChat: Advancing Open-source Language Models with Imperfect Data}},
  author = {Wang, Guan and Cheng, Sijie and Yu, Qiying and Liu, Changling},
  doi = {10.5281/zenodo.8105775},
  url = {https://github.com/imoneoi/openchat},
  version = {pre-release},
  year = {2023},
  month = {7},
}
@misc{mukherjee2023orca,
      title={Orca: Progressive Learning from Complex Explanation Traces of GPT-4},
      author={Subhabrata Mukherjee and Arindam Mitra and Ganesh Jawahar and Sahaj Agarwal and Hamid Palangi and Ahmed Awadallah},
      year={2023},
      eprint={2306.02707},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
@misc{touvron2023llama,
    title={Llama 2: Open Foundation and Fine-Tuned Chat Models},
    author={Hugo Touvron and Louis Martin and Kevin Stone and Peter Albert and Amjad Almahairi and Yasmine Babaei and Nikolay Bashlykov and Soumya Batra and Prajjwal Bhargava and Shruti Bhosale and Dan Bikel and Lukas Blecher and Cristian Canton Ferrer and Moya Chen and Guillem Cucurull and David Esiobu and Jude Fernandes and Jeremy Fu and Wenyin Fu and Brian Fuller and Cynthia Gao and Vedanuj Goswami and Naman Goyal and Anthony Hartshorn and Saghar Hosseini and Rui Hou and Hakan Inan and Marcin Kardas and Viktor Kerkez and Madian Khabsa and Isabel Kloumann and Artem Korenev and Punit Singh Koura and Marie-Anne Lachaux and Thibaut Lavril and Jenya Lee and Diana Liskovich and Yinghai Lu and Yuning Mao and Xavier Martinet and Todor Mihaylov and Pushkar Mishra and Igor Molybog and Yixin Nie and Andrew Poulton and Jeremy Reizenstein and Rashi Rungta and Kalyan Saladi and Alan Schelten and Ruan Silva and Eric Michael Smith and Ranjan Subramanian and Xiaoqing Ellen Tan and Binh Tang and Ross Taylor and Adina Williams and Jian Xiang Kuan and Puxin Xu and Zheng Yan and Iliyan Zarov and Yuchen Zhang and Angela Fan and Melanie Kambadur and Sharan Narang and Aurelien Rodriguez and Robert Stojnic and Sergey Edunov and Thomas Scialom},
    year={2023},
    eprint= arXiv 2307.09288
}
@misc{longpre2023flan,
      title={The Flan Collection: Designing Data and Methods for Effective Instruction Tuning},
      author={Shayne Longpre and Le Hou and Tu Vu and Albert Webson and Hyung Won Chung and Yi Tay and Denny Zhou and Quoc V. Le and Barret Zoph and Jason Wei and Adam Roberts},
      year={2023},
      eprint={2301.13688},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
@article{hu2021lora,
  title={LoRA: Low-Rank Adaptation of Large Language Models},
  author={Hu, Edward J. and Shen, Yelong and Wallis, Phillip and Allen-Zhu, Zeyuan and Li, Yuanzhi and Wang, Shean and Chen, Weizhu},
  journal={CoRR},
  year={2021}
}