Base model for paper "AnyGPT: Unified Multimodal LLM with Discrete Sequence Modeling"
Introduction
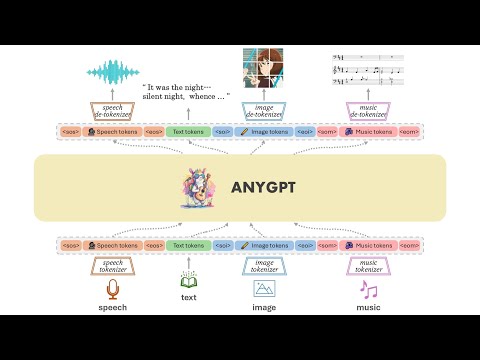
We introduce AnyGPT, an any-to-any multimodal language model that utilizes discrete representations for the unified processing of various modalities, including speech, text, images, and music. The base model aligns the four modalities, allowing for intermodal conversions between different modalities and text. Furthermore, we constructed the AnyInstruct dataset based on various generative models, which contains instructions for arbitrary modal interconversion. Trained on this dataset, our chat model can engage in free multimodal conversations, where multimodal data can be inserted at will.
AnyGPT proposes a generative training scheme that converts all modal data into a unified discrete representation, using the Next Token Prediction task for unified training on a Large Language Model (LLM). From the perspective of 'compression is intelligence': when the quality of the Tokenizer is high enough, and the perplexity (PPL) of the LLM is low enough, it is possible to compress the vast amount of multimodal data on the internet into the same model, thereby emerging capabilities not present in a pure text-based LLM. Demos are shown in project page.
Example Demonstrations
Inference
Installation
git clone https://github.com/OpenMOSS/AnyGPT.git
cd AnyGPT
conda create --name AnyGPT python=3.9
conda activate AnyGPT
pip install -r requirements.txt
Model Weights
- Check the AnyGPT-base weights in fnlp/AnyGPT-base
- Check the AnyGPT-chat weights in fnlp/AnyGPT-chat
- Check the SpeechTokenizer and Soundstorm weights in fnlp/AnyGPT-speech-modules
- Check the SEED tokenizer weights in AILab-CVC/seed-tokenizer-2
The SpeechTokenizer is used for tokenizing and reconstructing speech, Soundstorm is responsible for completing paralinguistic information, and SEED-tokenizer is used for tokenizing images.
The model weights of unCLIP SD-UNet which are used to reconstruct the image, and Encodec-32k which are used to tokenize and reconstruct music will be downloaded automatically.
Base model CLI Inference
python anygpt/src/infer/cli_infer_base_model.py \
--model-name-or-path "path/to/AnyGPT-7B-base" \
--image-tokenizer-path models/seed-tokenizer-2/seed_quantizer.pt \
--speech-tokenizer-path "path/to/model" \
--speech-tokenizer-config "path/to/config" \
--soundstorm-path "path/to/model" \
--output-dir "infer_output/base"
for example
python anygpt/src/infer/cli_infer_base_model.py \
--model-name-or-path models/anygpt/base \
--image-tokenizer-path models/seed-tokenizer-2/seed_quantizer.pt \
--speech-tokenizer-path models/speechtokenizer/ckpt.dev \
--speech-tokenizer-config models/speechtokenizer/config.json \
--soundstorm-path models/soundstorm/speechtokenizer_soundstorm_mls.pt \
--output-dir "infer_output/base"
Interaction
The Base Model can perform various tasks, including text-to-image, image caption, Automatic Speech Recognition (ASR), Zero-shot Text-to-Speech (TTS), Text-to-Music, and Music Captioning.
We can perform inference following a specific instruction format.
- Text-to-Image
text|image|{caption}- example:
text|image|A bustling medieval market scene with vendors selling exotic goods under colorful tents
- Image Caption
image|text|{caption}- example:
image|text|static/infer/image/cat.jpg
- TTS(random voice)
text|speech|{speech content}- example:
text|speech|I could be bounded in a nutshell and count myself a king of infinite space.
- Zero-shot TTS
text|speech|{speech content}|{voice prompt}- example:
text|speech|I could be bounded in a nutshell and count myself a king of infinite space.|static/infer/speech/voice_prompt1.wav/voice_prompt3.wav
- ASR
speech|text|{speech file path}- example:
speech|text|AnyGPT/static/infer/speech/voice_prompt2.wav
- Text-to-Music
text|music|{caption}- example:
text|music|features an indie rock sound with distinct elements that evoke a dreamy, soothing atmosphere
- Music Caption
music|text|{music file path}- example:
music|text|static/infer/music/features an indie rock sound with distinct element.wav
Notes
For different tasks, we used different language model decoding strategies. The decoding configuration files for image, speech, and music generation are located in config/image_generate_config.json, config/speech_generate_config.json, and config/music_generate_config.json, respectively. The decoding configuration files for other modalities to text are in config/text_generate_config.json. You can directly modify or add parameters to change the decoding strategy.
Due to limitations in data and training resources, the model's generation may still be unstable. You can generate multiple times or try different decoding strategies.
The speech and music response will be saved to .wav files, and the image response will be saved to a jpg. The filename will be a concatenation of the prompt and the time. The paths to these files will be indicated in the response.
Training
Pretraining
- Install dependency
cd FastChat pip3 install -e ".[train]" - run
srun --partition=llm_h --job-name=pretrain --gres=gpu:8 --quotatype=spot --ntasks=1 --ntasks-per-node=1 --cpus-per-task 100 --kill-on-bad-exit=1 bash scripts/stage1_pretrain.sh
We have provided some sample data in the "data" folder. To download the complete dataset, please refer to the following:
- Image data: https://huggingface.co/datasets/zhanjun/AnyGPT-data-image
- The two datasets in the t2i folder are high-quality image datasets, used for fine-tuning text-to-image generation.
- Speech data: https://huggingface.co/datasets/zhanjun/AnyGPT-data-speech
- Music data: None
- Insruction data: https://huggingface.co/datasets/zhanjun/Anygpt_data_instruction
These data are preprocessed by multimodal tokeniziers.
Acknowledgements
- SpeechGPT, Vicuna: The codebase we built upon.
- We thank the great work from SpeechTokenizer,soundstorm-speechtokenizer, SEED-tokenizer,
Lincese
AnyGPT is released under the original License of LLaMA2.
Citation
If you find AnyGPT and AnyInstruct useful in your research or applications, please kindly cite:
@article{zhan2024anygpt,
  title={AnyGPT: Unified Multimodal LLM with Discrete Sequence Modeling},
  author={Zhan, Jun and Dai, Junqi and Ye, Jiasheng and Zhou, Yunhua and Zhang, Dong and Liu, Zhigeng and Zhang, Xin and Yuan, Ruibin and Zhang, Ge and Li, Linyang and others},
  journal={arXiv preprint arXiv:2402.12226},
  year={2024}
}