
QuantFactory/Qwen2.5-Math-7B-GGUF
This is quantized version of Qwen/Qwen2.5-Math-7B created using llama.cpp
Original Model Card
Qwen2.5-Math-7B
[!Warning]
Introduction
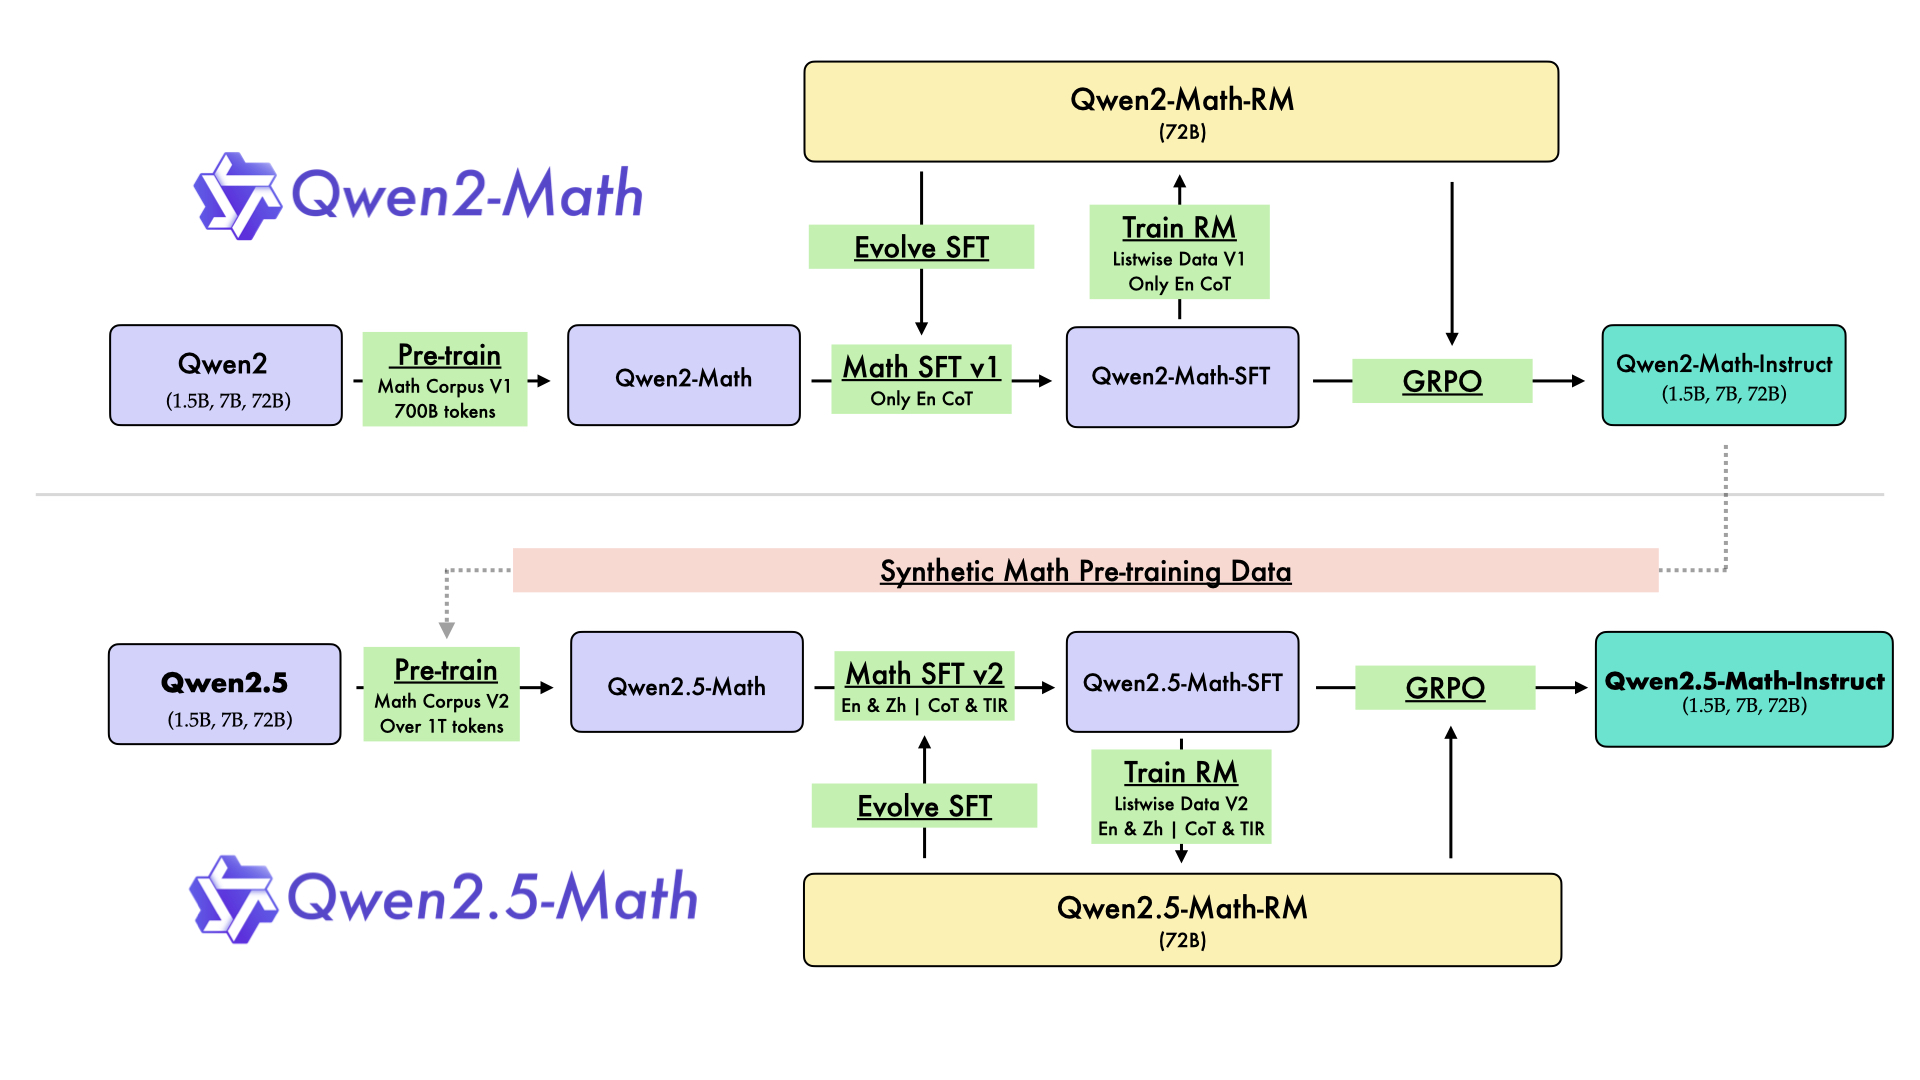
In August 2024, we released the first series of mathematical LLMs - Qwen2-Math - of our Qwen family. A month later, we have upgraded it and open-sourced Qwen2.5-Math series, including base models Qwen2.5-Math-1.5B/7B/72B, instruction-tuned models Qwen2.5-Math-1.5B/7B/72B-Instruct, and mathematical reward model Qwen2.5-Math-RM-72B.
Unlike Qwen2-Math series which only supports using Chain-of-Thught (CoT) to solve English math problems, Qwen2.5-Math series is expanded to support using both CoT and Tool-integrated Reasoning (TIR) to solve math problems in both Chinese and English. The Qwen2.5-Math series models have achieved significant performance improvements compared to the Qwen2-Math series models on the Chinese and English mathematics benchmarks with CoT.
While CoT plays a vital role in enhancing the reasoning capabilities of LLMs, it faces challenges in achieving computational accuracy and handling complex mathematical or algorithmic reasoning tasks, such as finding the roots of a quadratic equation or computing the eigenvalues of a matrix. TIR can further improve the model's proficiency in precise computation, symbolic manipulation, and algorithmic manipulation. Qwen2.5-Math-1.5B/7B/72B-Instruct achieve 79.7, 85.3, and 87.8 respectively on the MATH benchmark using TIR.
Model Details
For more details, please refer to our blog post and GitHub repo.
Requirements
transformers>=4.37.0for Qwen2.5-Math models. The latest version is recommended.
[!Warning]
For requirements on GPU memory and the respective throughput, see similar results of Qwen2 here.
Quick Start
[!Important]
Qwen2.5-Math-7B-Instruct is an instruction model for chatting;
Qwen2.5-Math-7B is a base model typically used for completion and few-shot inference, serving as a better starting point for fine-tuning.
Citation
If you find our work helpful, feel free to give us a citation.
@article{yang2024qwen2,
  title={Qwen2 technical report},
  author={Yang, An and Yang, Baosong and Hui, Binyuan and Zheng, Bo and Yu, Bowen and Zhou, Chang and Li, Chengpeng and Li, Chengyuan and Liu, Dayiheng and Huang, Fei and others},
  journal={arXiv preprint arXiv:2407.10671},
  year={2024}
}