📃Paper | 🌐Website | 💻Github | 🛢️Datasets | 🤗Model (VideoScore) | 🤗Demo
Introduction
-
🤯🤯Try on the new version VideoScore-v1.1, a variant from VideoScore with better performance in "text-to-video alignment" subscore and the support for 48 frames in inference now! It takes Mantis-8B-Idefics2 as base model, and is trained on trained on VideoFeedback dataset.
-
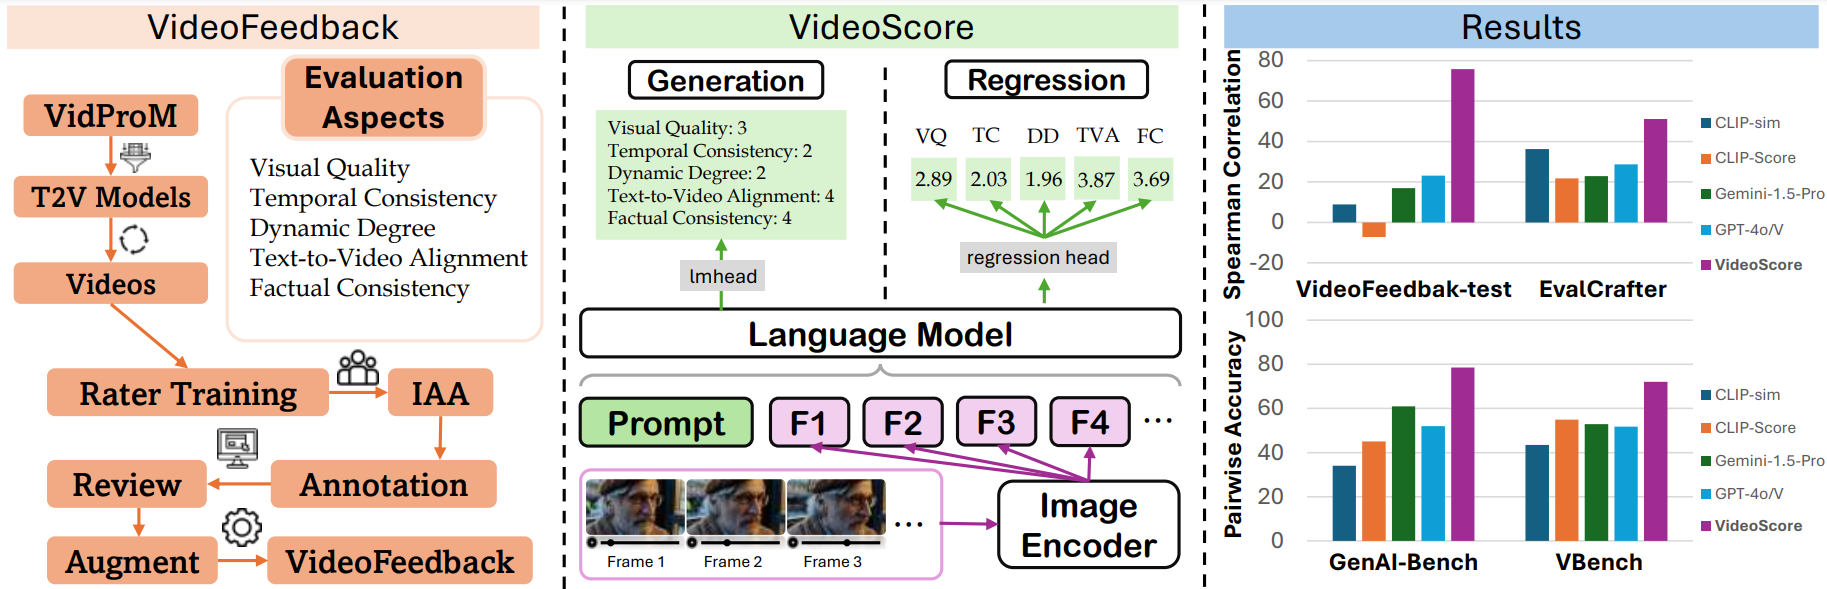
VideoScore series is a video quality evaluation model series, taking Mantis-8B-Idefics2 or Qwen/Qwen2-VL as base-model and trained on VideoFeedback, a large video evaluation dataset with multi-aspect human scores.
-
Following VideoScore, VideoScore-v1.1 can also reach about 75 Spearman correlation with humans on VideoFeedback-test, surpassing all the MLLM-prompting methods and feature-based metrics. VideoScore-v1.1 also beat the best baselines on other two benchmarks GenAI-Bench and VBench, showing high alignment with human evaluations. For the data details of these benchmarks, please refer to VideoScore-Bench.
-
VideoScore-v1.1 is a regression version model.
Evaluation Results
We test VideoScore-v1.1 on VideoFeedback-test and take Spearman corrleation between model's output and human ratings averaged among all the evaluation aspects as indicator.
The evaluation results are shown below:
| metric | VideoFeedback-test |
|---|---|
| VideoScore-v1.1 | 74.0 |
| Gemini-1.5-Pro | 22.1 |
| Gemini-1.5-Flash | 20.8 |
| GPT-4o | 23.1 |
| CLIP-sim | 8.9 |
| DINO-sim | 7.5 |
| SSIM-sim | 13.4 |
| CLIP-Score | -7.2 |
| LLaVA-1.5-7B | 8.5 |
| LLaVA-1.6-7B | -3.1 |
| X-CLIP-Score | -1.9 |
| PIQE | -10.1 |
| BRISQUE | -20.3 |
| Idefics2 | 6.5 |
| MSE-dyn | -5.5 |
| SSIM-dyn | -12.9 |
The best in VideoScore series is in bold and the best in baselines is underlined.
Usage
Installation
pip install git+https://github.com/TIGER-AI-Lab/VideoScore.git
# or
# pip install mantis-vl
Inference
cd VideoScore/examples
import av
import numpy as np
from typing import List
from PIL import Image
import torch
from transformers import AutoProcessor
from mantis.models.idefics2 import Idefics2ForSequenceClassification
def _read_video_pyav(
    frame_paths:List[str],
    max_frames:int,
):
    frames = []
    container.seek(0)
    start_index = indices[0]
    end_index = indices[-1]
    for i, frame in enumerate(container.decode(video=0)):
        if i > end_index:
            break
        if i >= start_index and i in indices:
            frames.append(frame)
    return np.stack([x.to_ndarray(format="rgb24") for x in frames])

ROUND_DIGIT=3
REGRESSION_QUERY_PROMPT = """
Suppose you are an expert in judging and evaluating the quality of AI-generated videos,
please watch the following frames of a given video and see the text prompt for generating the video,
then give scores from 5 different dimensions:
(1) visual quality: the quality of the video in terms of clearness, resolution, brightness, and color
(2) temporal consistency, both the consistency of objects or humans and the smoothness of motion or movements
(3) dynamic degree, the degree of dynamic changes
(4) text-to-video alignment, the alignment between the text prompt and the video content
(5) factual consistency, the consistency of the video content with the common-sense and factual knowledge
for each dimension, output a float number from 1.0 to 4.0,
the higher the number is, the better the video performs in that sub-score,
the lowest 1.0 means Bad, the highest 4.0 means Perfect/Real (the video is like a real video)
Here is an output example:
visual quality: 3.2
temporal consistency: 2.7
dynamic degree: 4.0
text-to-video alignment: 2.3
factual consistency: 1.8
For this video, the text prompt is "{text_prompt}",
all the frames of video are as follows:
"""

# MAX_NUM_FRAMES=16
# model_name="TIGER-Lab/VideoScore"

# =======================================
# we support 48 frames in VideoScore-v1.1
# =======================================
MAX_NUM_FRAMES=48
model_name="TIGER-Lab/VideoScore-v1.1"

video_path="video1.mp4"
video_prompt="Near the Elephant Gate village, they approach the haunted house at night. Rajiv feels anxious, but Bhavesh encourages him. As they reach the house, a mysterious sound in the air adds to the suspense."

processor = AutoProcessor.from_pretrained(model_name,torch_dtype=torch.bfloat16)
model = Idefics2ForSequenceClassification.from_pretrained(model_name,torch_dtype=torch.bfloat16).eval()
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
model.to(device)

# sample uniformly 8 frames from the video
container = av.open(video_path)
total_frames = container.streams.video[0].frames
if total_frames > MAX_NUM_FRAMES:
    indices = np.arange(0, total_frames, total_frames / MAX_NUM_FRAMES).astype(int)
else:
    indices = np.arange(total_frames)

frames = [Image.fromarray(x) for x in _read_video_pyav(container, indices)]
eval_prompt = REGRESSION_QUERY_PROMPT.format(text_prompt=video_prompt)
num_image_token = eval_prompt.count("<image>")
if num_image_token < len(frames):
    eval_prompt += "<image> " * (len(frames) - num_image_token)
flatten_images = []
for x in [frames]:
    if isinstance(x, list):
        flatten_images.extend(x)
    else:
        flatten_images.append(x)

flatten_images = [Image.open(x) if isinstance(x, str) else x for x in flatten_images]
inputs = processor(text=eval_prompt, images=flatten_images, return_tensors="pt")
inputs = {k: v.to(model.device) for k, v in inputs.items()}

with torch.no_grad():
    outputs = model(**inputs)
logits = outputs.logits
num_aspects = logits.shape[-1]
aspect_scores = []
for i in range(num_aspects):
    aspect_scores.append(round(logits[0, i].item(),ROUND_DIGIT))

print(aspect_scores)
"""
model output on visual quality, temporal consistency, dynamic degree,
text-to-video alignment, factual consistency, respectively
VideoScore:
[2.297, 2.469, 2.906, 2.766, 2.516]

VideoScore-v1.1:
[2.328, 2.484, 2.562, 1.969, 2.594]
"""
Training
see VideoScore/training for details
Evaluation
see VideoScore/benchmark for details
Citation
@article{he2024videoscore,
  title = {VideoScore: Building Automatic Metrics to Simulate Fine-grained Human Feedback for Video Generation},
  author = {He, Xuan and Jiang, Dongfu and Zhang, Ge and Ku, Max and Soni, Achint and Siu, Sherman and Chen, Haonan and Chandra, Abhranil and Jiang, Ziyan and Arulraj, Aaran and Wang, Kai and Do, Quy Duc and Ni, Yuansheng and Lyu, Bohan and Narsupalli, Yaswanth and Fan, Rongqi and Lyu, Zhiheng and Lin, Yuchen and Chen, Wenhu},
  journal = {ArXiv},
  year = {2024},
  volume={abs/2406.15252},
  url = {https://arxiv.org/abs/2406.15252},
}