This is a float16 HF format repo for junelee's wizard-vicuna 13B.
June Lee's repo was also HF format. The reason I've made this is that the original repo was in float32, meaning it required 52GB disk space, VRAM and RAM.
This model was converted to float16 to make it easier to load and manage.
Repositories available
- 4bit GPTQ models for GPU inference.
- 4bit and 5bit GGML models for CPU inference.
- float16 HF format model for GPU inference.
Discord
For further support, and discussions on these models and AI in general, join us at:
Thanks, and how to contribute.
Thanks to the chirper.ai team!
I've had a lot of people ask if they can contribute. I enjoy providing models and helping people, and would love to be able to spend even more time doing it, as well as expanding into new projects like fine tuning/training.
If you're able and willing to contribute it will be most gratefully received and will help me to keep providing more models, and to start work on new AI projects.
Donaters will get priority support on any and all AI/LLM/model questions and requests, access to a private Discord room, plus other benefits.
- Patreon: https://patreon.com/TheBlokeAI
- Ko-Fi: https://ko-fi.com/TheBlokeAI
Patreon special mentions: Aemon Algiz, Dmitriy Samsonov, Nathan LeClaire, Trenton Dambrowitz, Mano Prime, David Flickinger, vamX, Nikolai Manek, senxiiz, Khalefa Al-Ahmad, Illia Dulskyi, Jonathan Leane, Talal Aujan, V. Lukas, Joseph William Delisle, Pyrater, Oscar Rangel, Lone Striker, Luke Pendergrass, Eugene Pentland, Sebastain Graf, Johann-Peter Hartman.
Thank you to all my generous patrons and donaters!
Original WizardVicuna-13B model card
Github page: https://github.com/melodysdreamj/WizardVicunaLM
WizardVicunaLM
Wizard's dataset + ChatGPT's conversation extension + Vicuna's tuning method
I am a big fan of the ideas behind WizardLM and VicunaLM. I particularly like the idea of WizardLM handling the dataset itself more deeply and broadly, as well as VicunaLM overcoming the limitations of single-turn conversations by introducing multi-round conversations. As a result, I combined these two ideas to create WizardVicunaLM. This project is highly experimental and designed for proof of concept, not for actual usage.
Benchmark
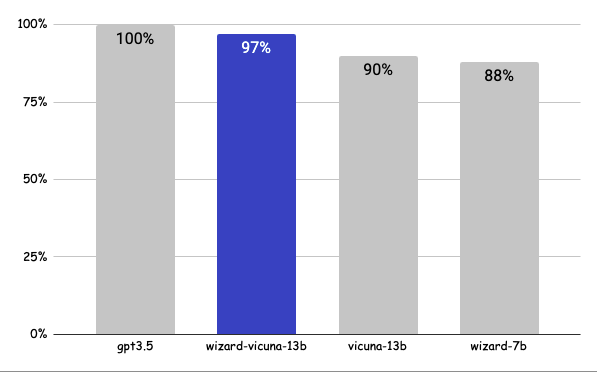
Approximately 7% performance improvement over VicunaLM
Detail
The questions presented here are not from rigorous tests, but rather, I asked a few questions and requested GPT-4 to score them. The models compared were ChatGPT 3.5, WizardVicunaLM, VicunaLM, and WizardLM, in that order.
| gpt3.5 | wizard-vicuna-13b | vicuna-13b | wizard-7b | link | |
|---|---|---|---|---|---|
| Q1 | 95 | 90 | 85 | 88 | link |
| Q2 | 95 | 97 | 90 | 89 | link |
| Q3 | 85 | 90 | 80 | 65 | link |
| Q4 | 90 | 85 | 80 | 75 | link |
| Q5 | 90 | 85 | 80 | 75 | link |
| Q6 | 92 | 85 | 87 | 88 | link |
| Q7 | 95 | 90 | 85 | 92 | link |
| Q8 | 90 | 85 | 75 | 70 | link |
| Q9 | 92 | 85 | 70 | 60 | link |
| Q10 | 90 | 80 | 75 | 85 | link |
| Q11 | 90 | 85 | 75 | 65 | link |
| Q12 | 85 | 90 | 80 | 88 | link |
| Q13 | 90 | 95 | 88 | 85 | link |
| Q14 | 94 | 89 | 90 | 91 | link |
| Q15 | 90 | 85 | 88 | 87 | link |
| 91 | 88 | 82 | 80 |
Principle
We adopted the approach of WizardLM, which is to extend a single problem more in-depth. However, instead of using individual instructions, we expanded it using Vicuna's conversation format and applied Vicuna's fine-tuning techniques.
Turning a single command into a rich conversation is what we've done here.
After creating the training data, I later trained it according to the Vicuna v1.1 training method.
Detailed Method
First, we explore and expand various areas in the same topic using the 7K conversations created by WizardLM. However, we made it in a continuous conversation format instead of the instruction format. That is, it starts with WizardLM's instruction, and then expands into various areas in one conversation using ChatGPT 3.5.
After that, we applied the following model using Vicuna's fine-tuning format.
Training Process
Trained with 8 A100 GPUs for 35 hours.
Weights
You can see the dataset we used for training and the 13b model in the huggingface.
Conclusion
If we extend the conversation to gpt4 32K, we can expect a dramatic improvement, as we can generate 8x more, more accurate and richer conversations.
License
The model is licensed under the LLaMA model, and the dataset is licensed under the terms of OpenAI because it uses ChatGPT. Everything else is free.
Author
JUNE LEE - He is active in Songdo Artificial Intelligence Study and GDG Songdo.