This is a 2-step turbo LoRA for Qwen Image 2512 trained by Wuli Team, representing an advancement over our 4-step turbo LoRA.
For users in Chinese mainland, you can try our website: https://wuli.art/generate, getting four images with 2k resolution generated by Qwen Image 2512 Turbo with only 5 seconds.
Result Visualization
| Prompt | Qwen Image 2512 40 Steps | Our 4 Steps Turbo LoRA (V3.0) | Our 2 Steps Turbo LoRA (V1.0) |
|---|---|---|---|
| A Chinese female college student, around 20 years old, with a very short haircut that conveys a gentle, artistic vibe. Her hair naturally falls to partially cover her cheeks, projecting a tomboyish yet charming demeanor. She has cool-toned fair skin and delicate features, with a slightly shy yet subtly confident expression—her mouth crooked in a playful, youthful smirk. She wears an off-shoulder top, revealing one shoulder, with a well-proportioned figure. The image is framed as a close-up selfie: she dominates the foreground, while the background clearly shows her dormitory—a neatly made bed with white linens on the top bunk, a tidy study desk with organized stationery, and wooden cabinets and drawers. The photo is captured on a smartphone under soft, even ambient lighting, with natural tones, high clarity, and a bright, lively atmosphere full of youthful, everyday energy. | 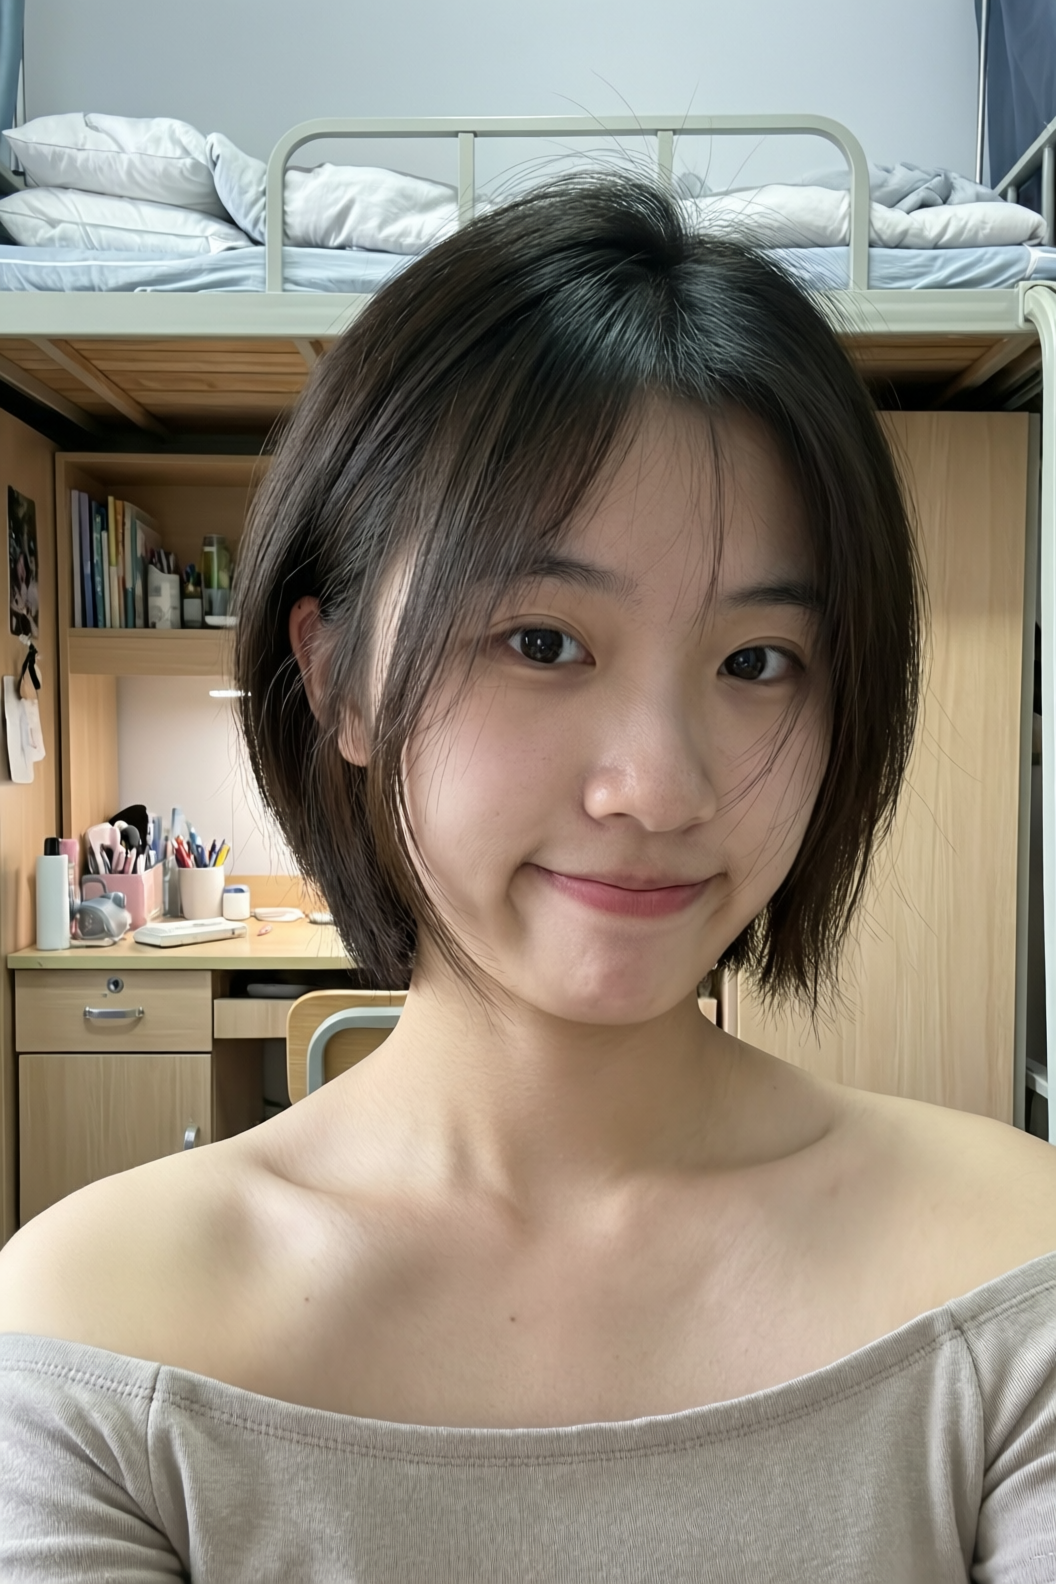 | 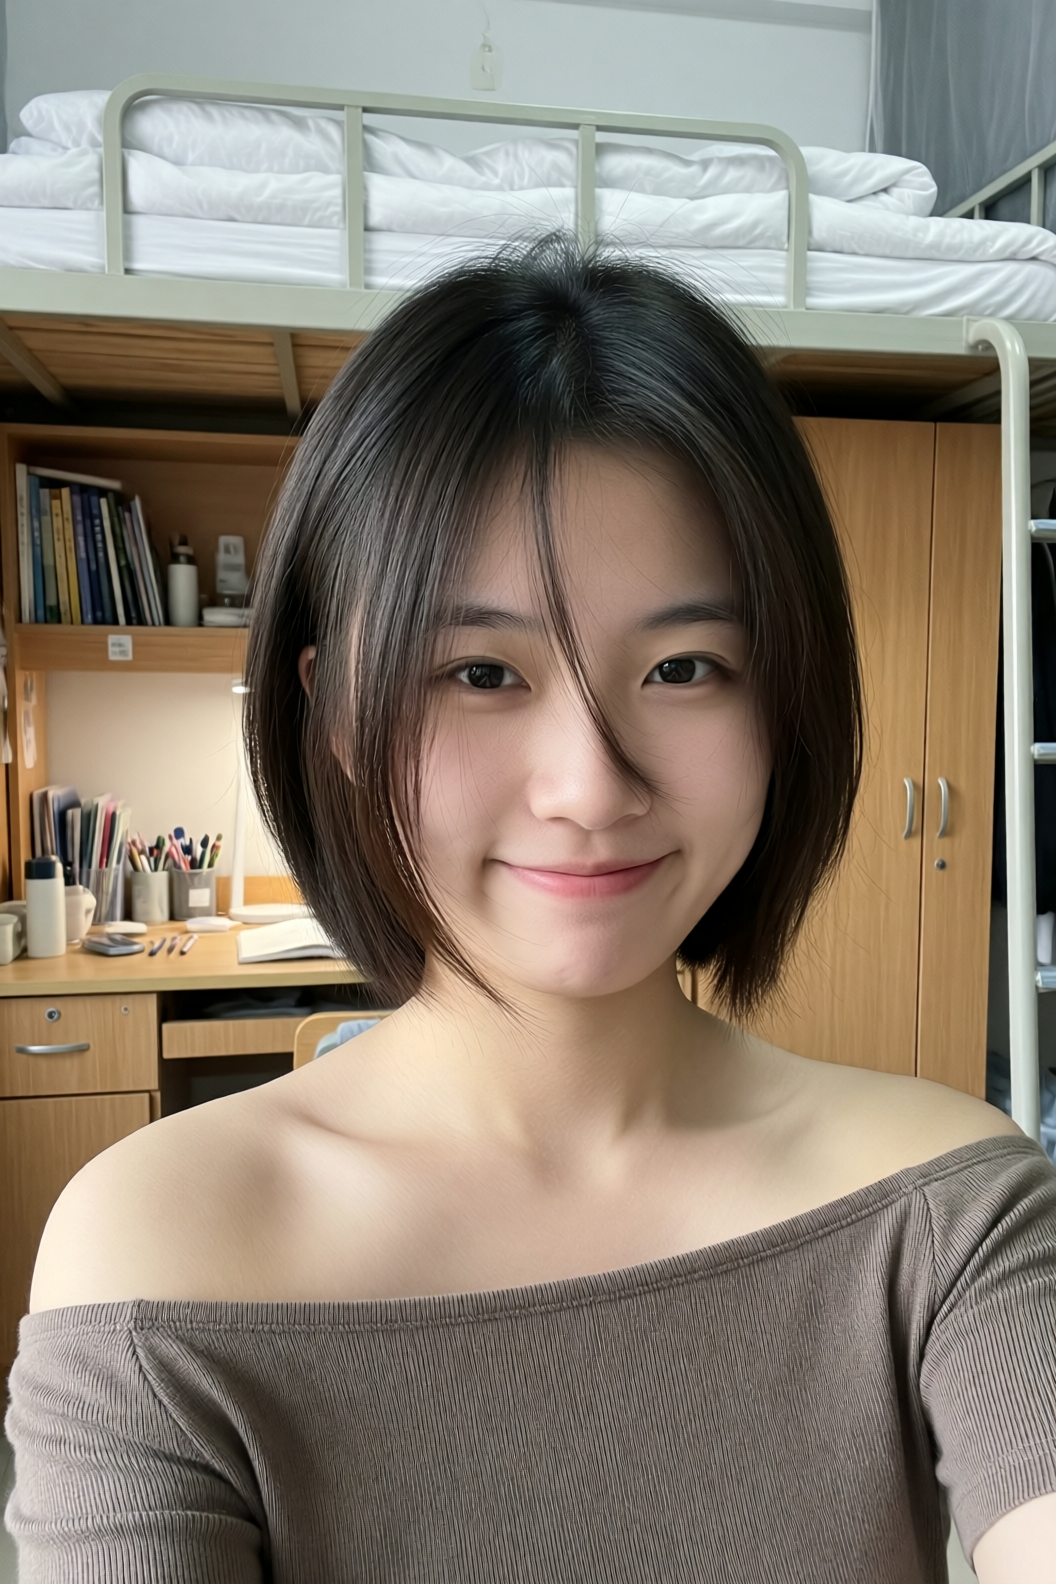 | 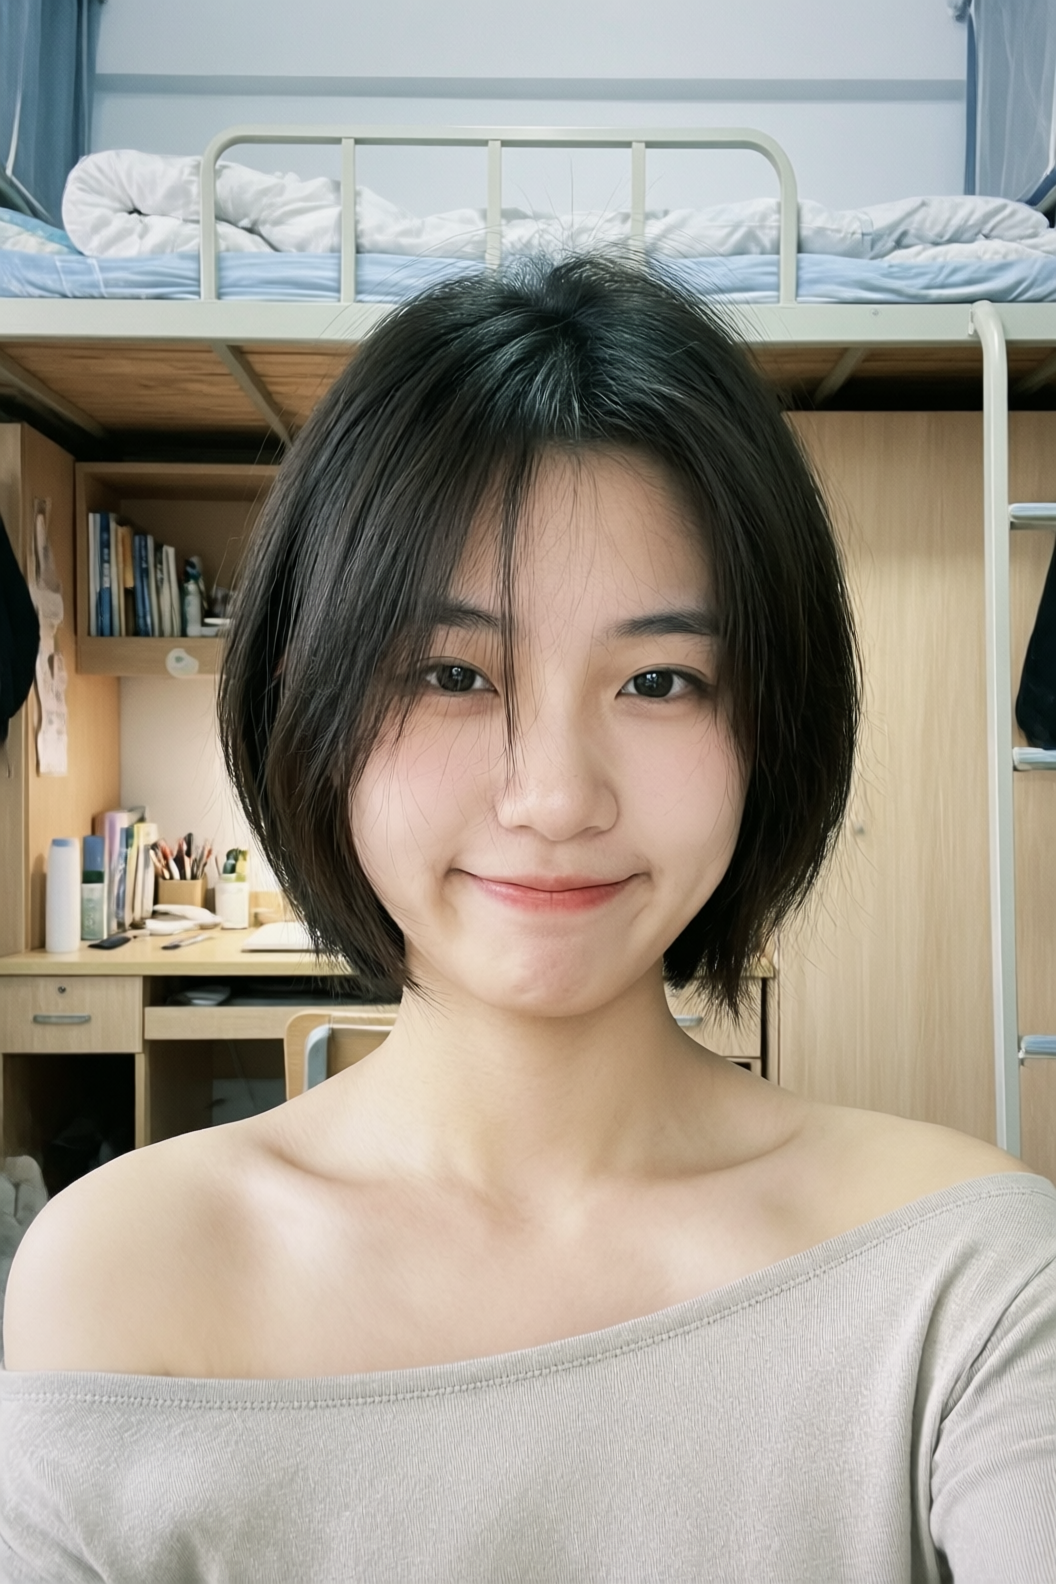 |
| A 20-year-old East Asian girl with delicate, charming features and large, bright brown eyes—expressive and lively, with a cheerful or subtly smiling expression. Her naturally wavy long hair is either loose or tied in twin ponytails. She has fair skin and light makeup accentuating her youthful freshness. She wears a modern, cute dress or relaxed outfit in bright, soft colors—lightweight fabric, minimalist cut. She stands indoors at an anime convention, surrounded by banners, posters, or stalls. Lighting is typical indoor illumination—no staged lighting—and the image resembles a casual iPhone snapshot: unpretentious composition, yet brimming with vivid, fresh, youthful charm. | 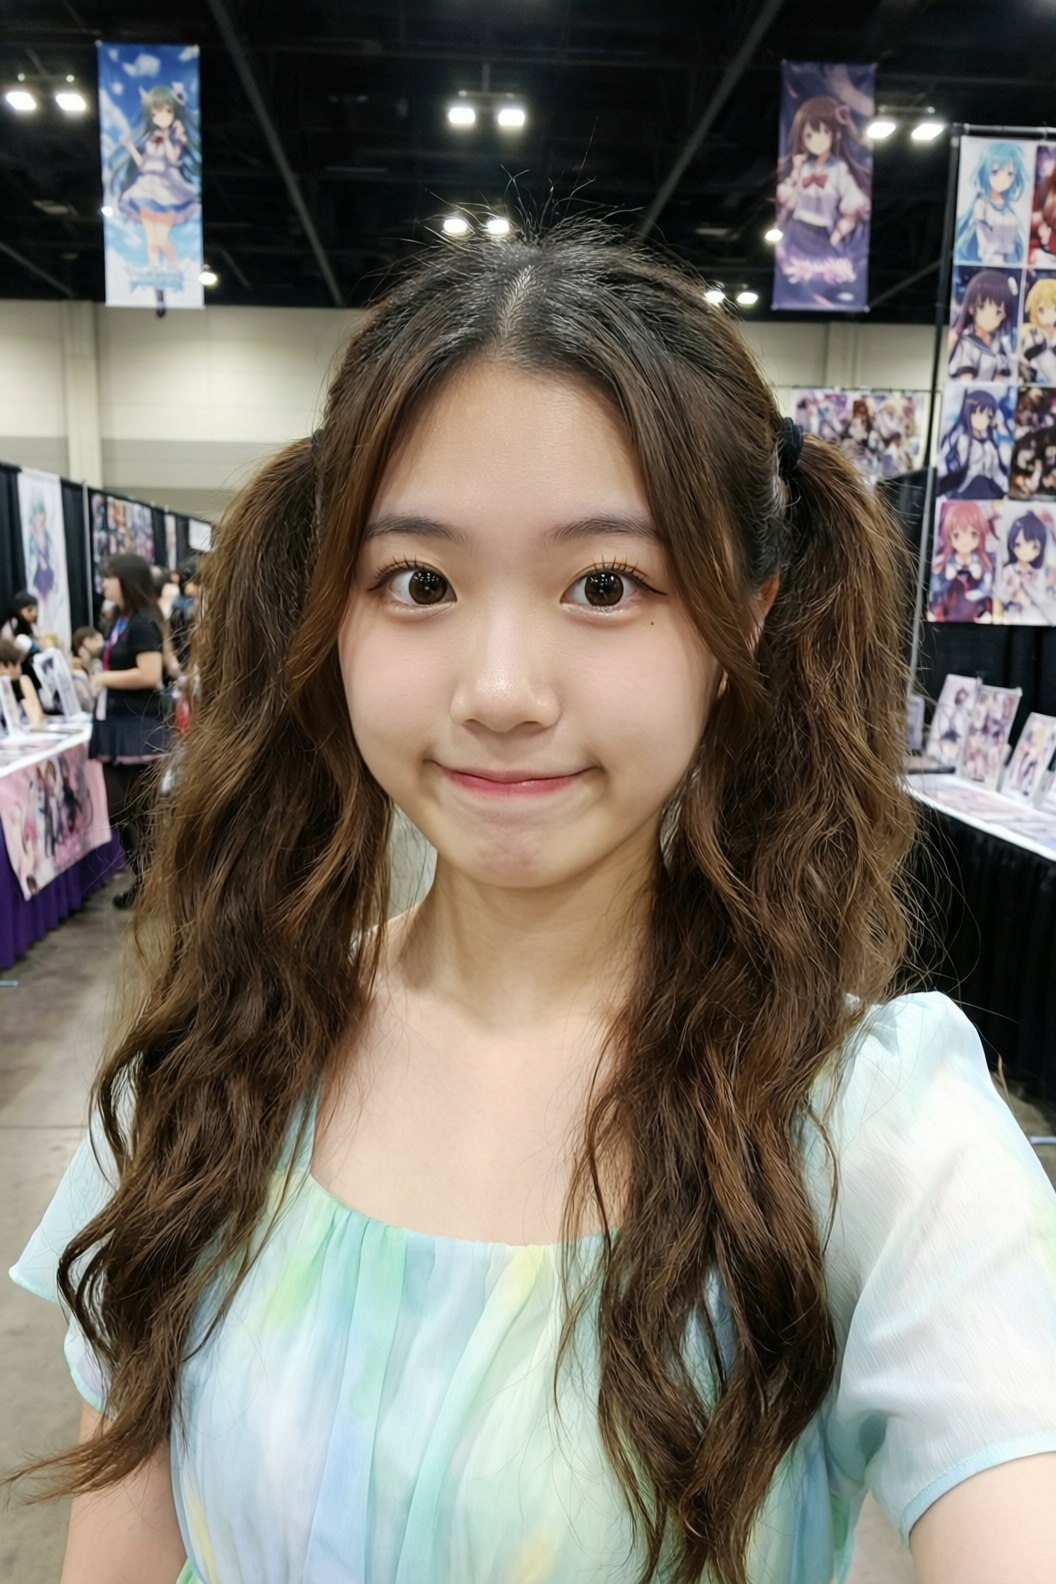 | 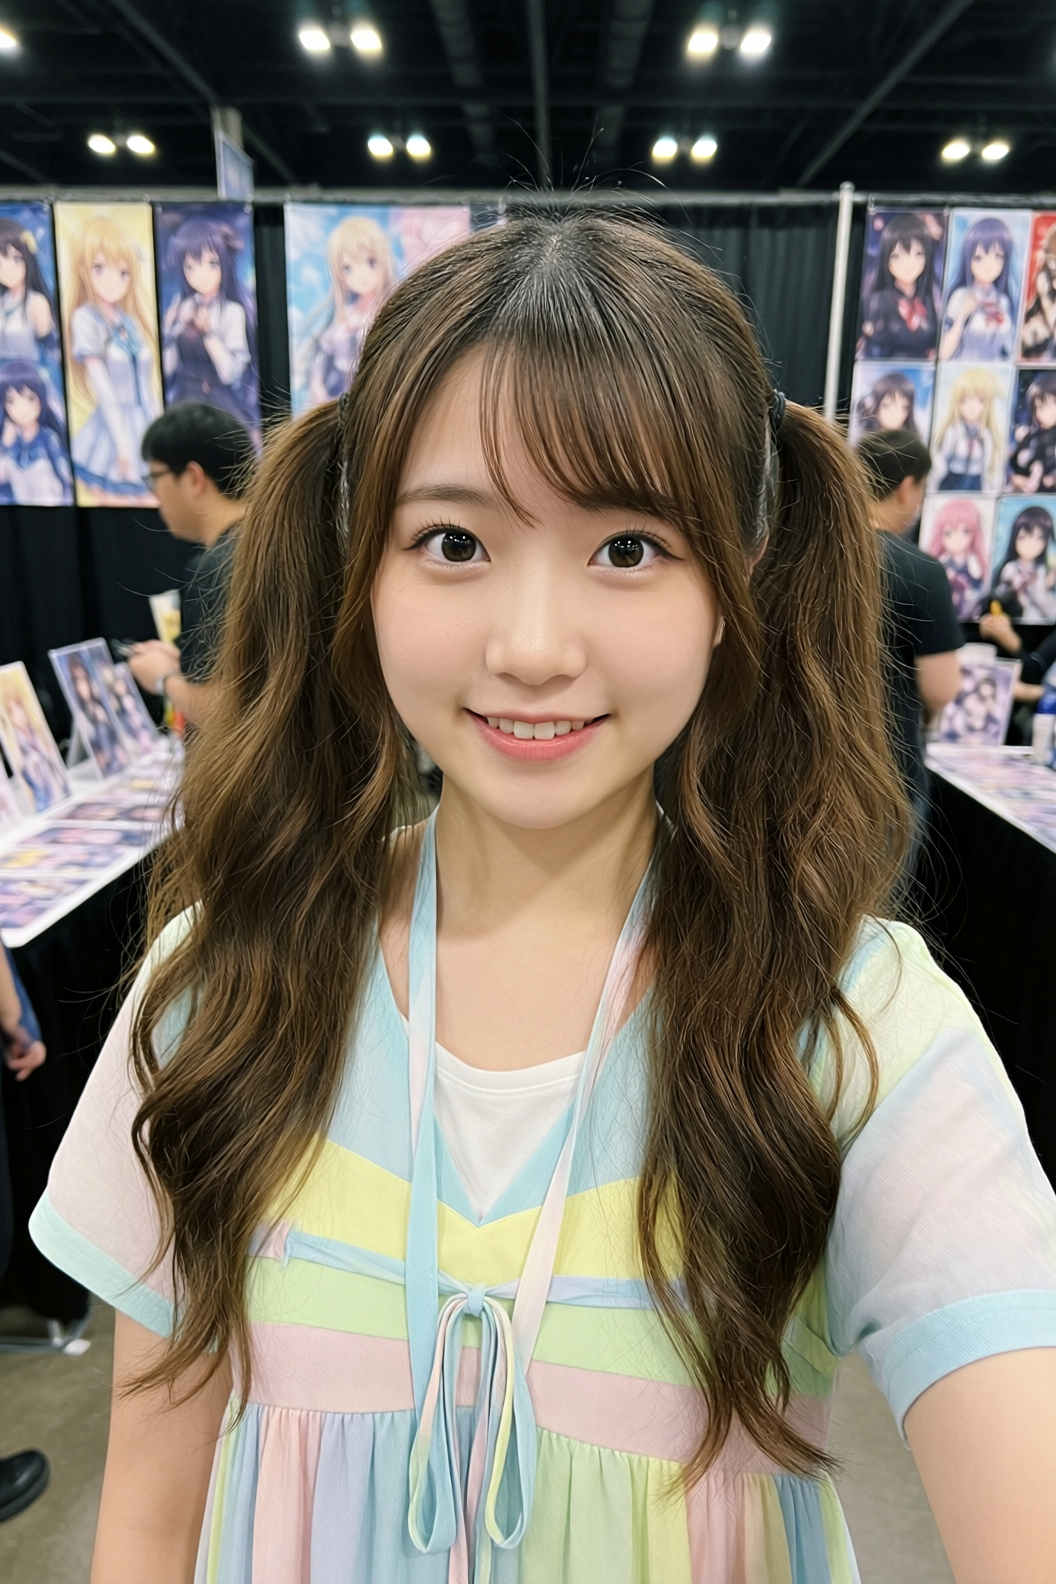 | 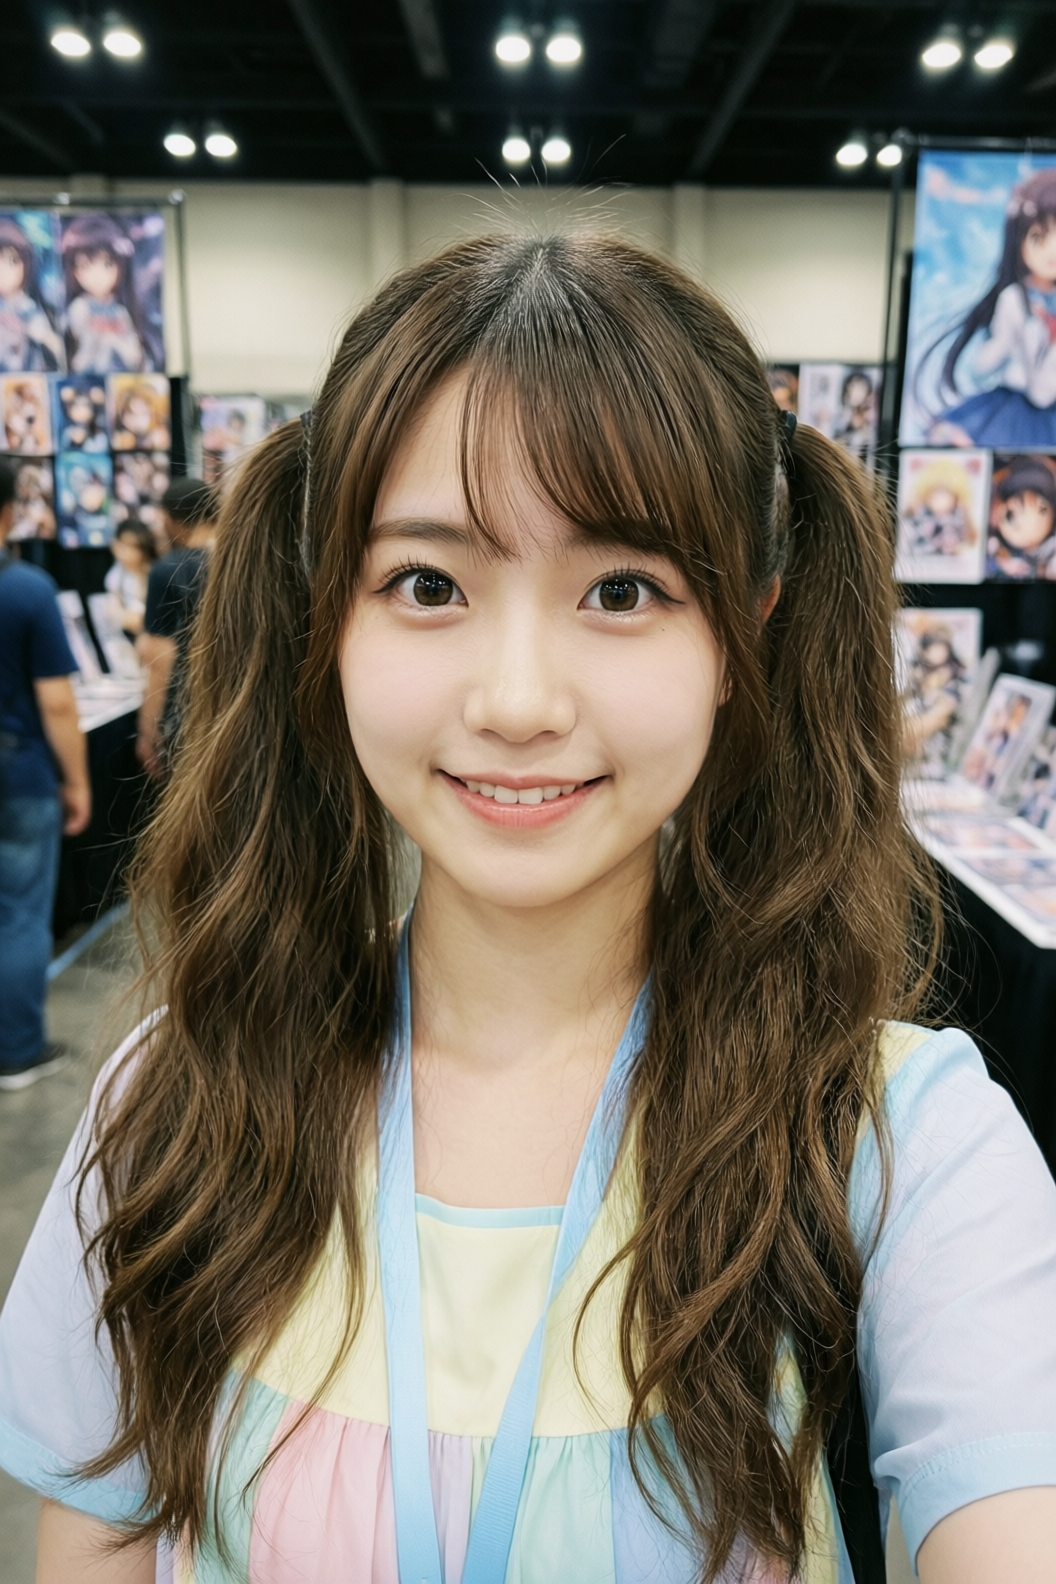 |
| A turquoise river winds through a lush canyon. Thick moss and dense ferns blanket the rocky walls; multiple waterfalls cascade from above, enveloped in mist. At noon, sunlight filters through the dense canopy, dappling the river surface with shimmering light. The atmosphere is humid and fresh, pulsing with primal jungle vitality. No humans, text, or artificial traces present. | 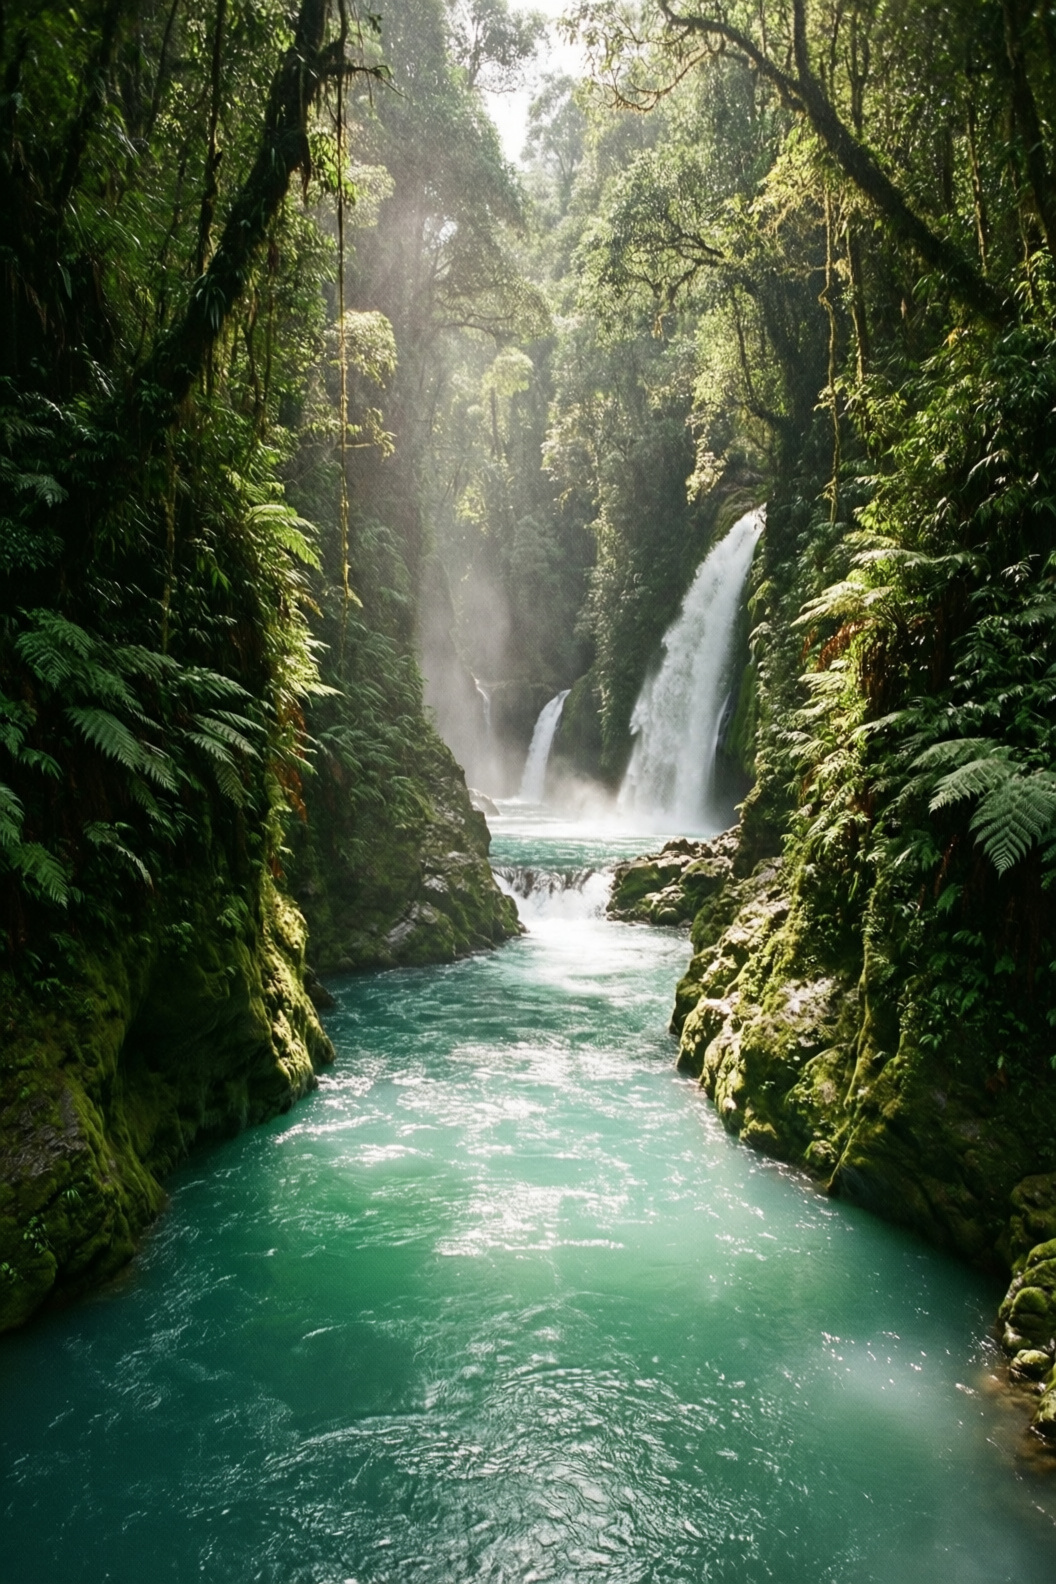 | 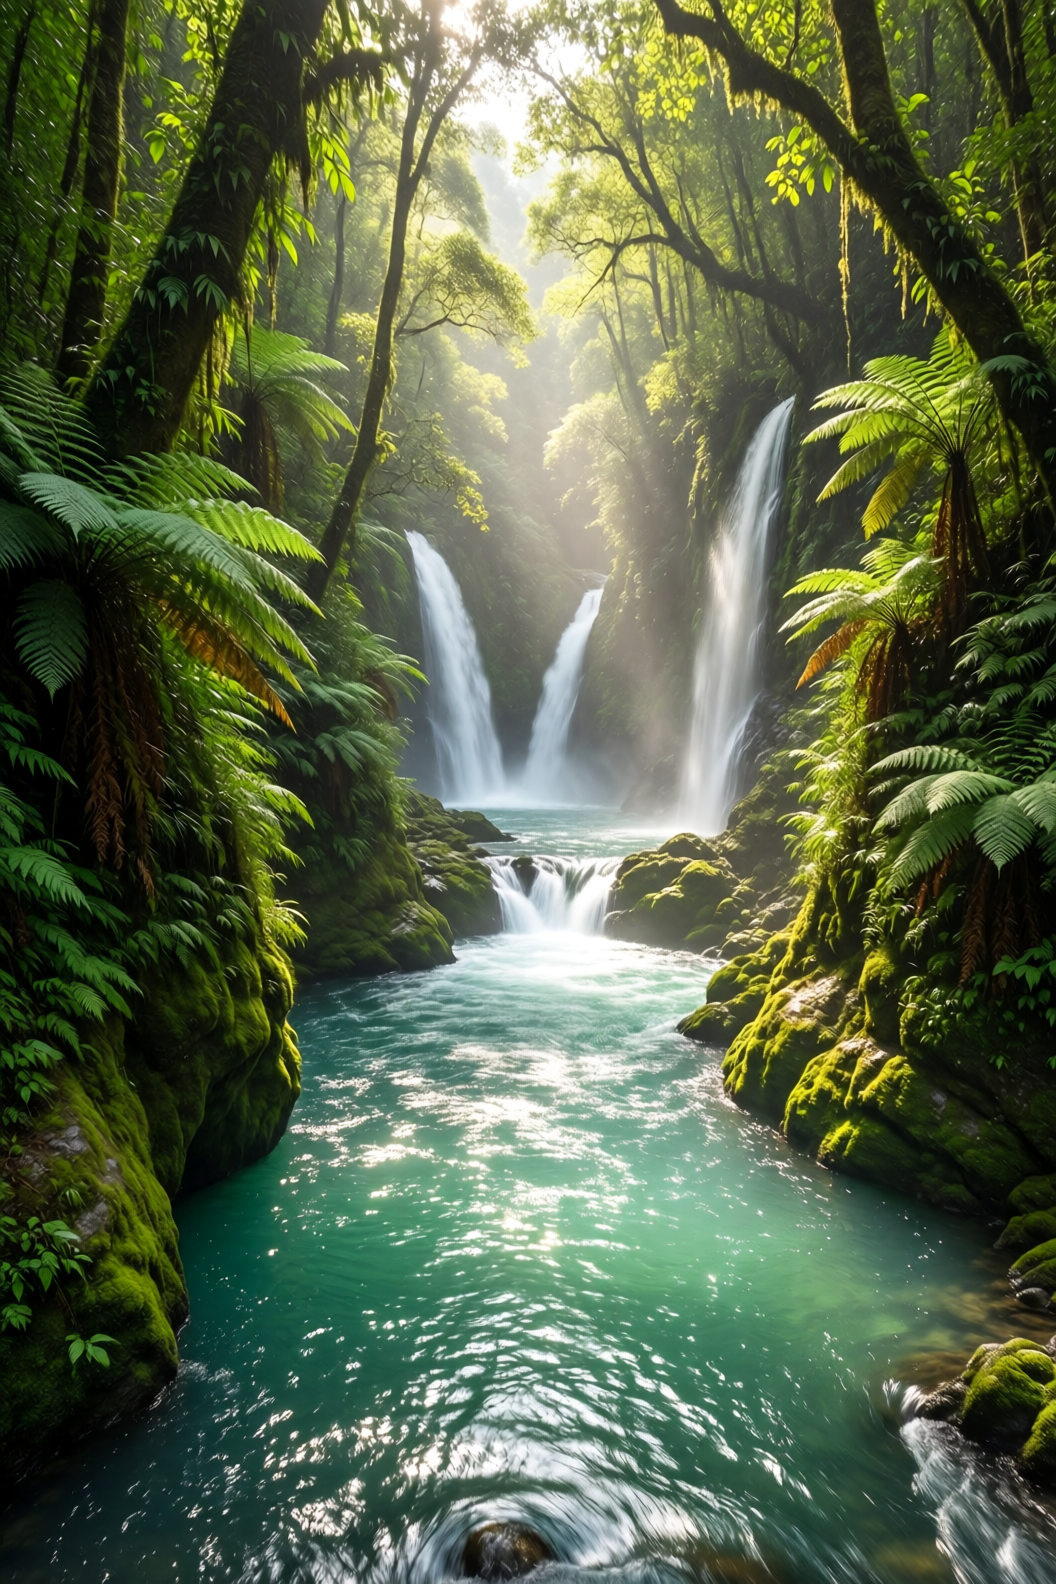 | 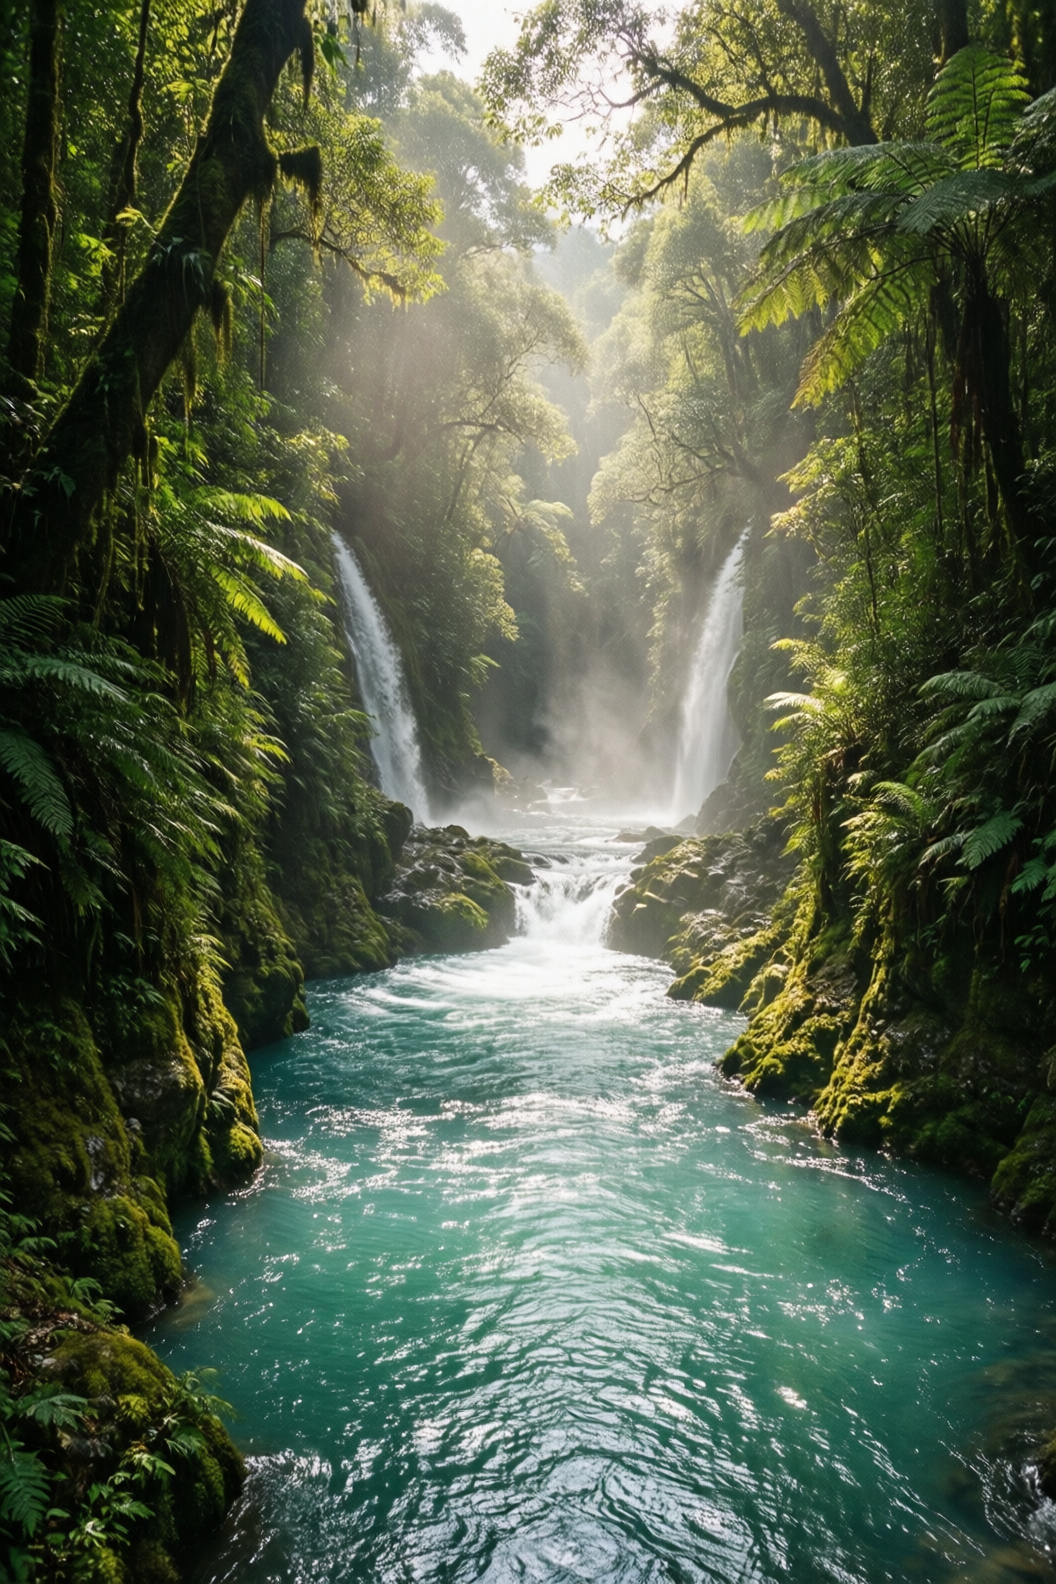 |
| At dawn, a thin mist veils the sea. An ancient stone lighthouse stands at the cliff’s edge, its beacon faintly visible through the fog. Black rocks are pounded by waves, sending up bursts of white spray. The sky glows in soft blue-purple hues under cool, hazy light—evoking solitude and solemn grandeur. | 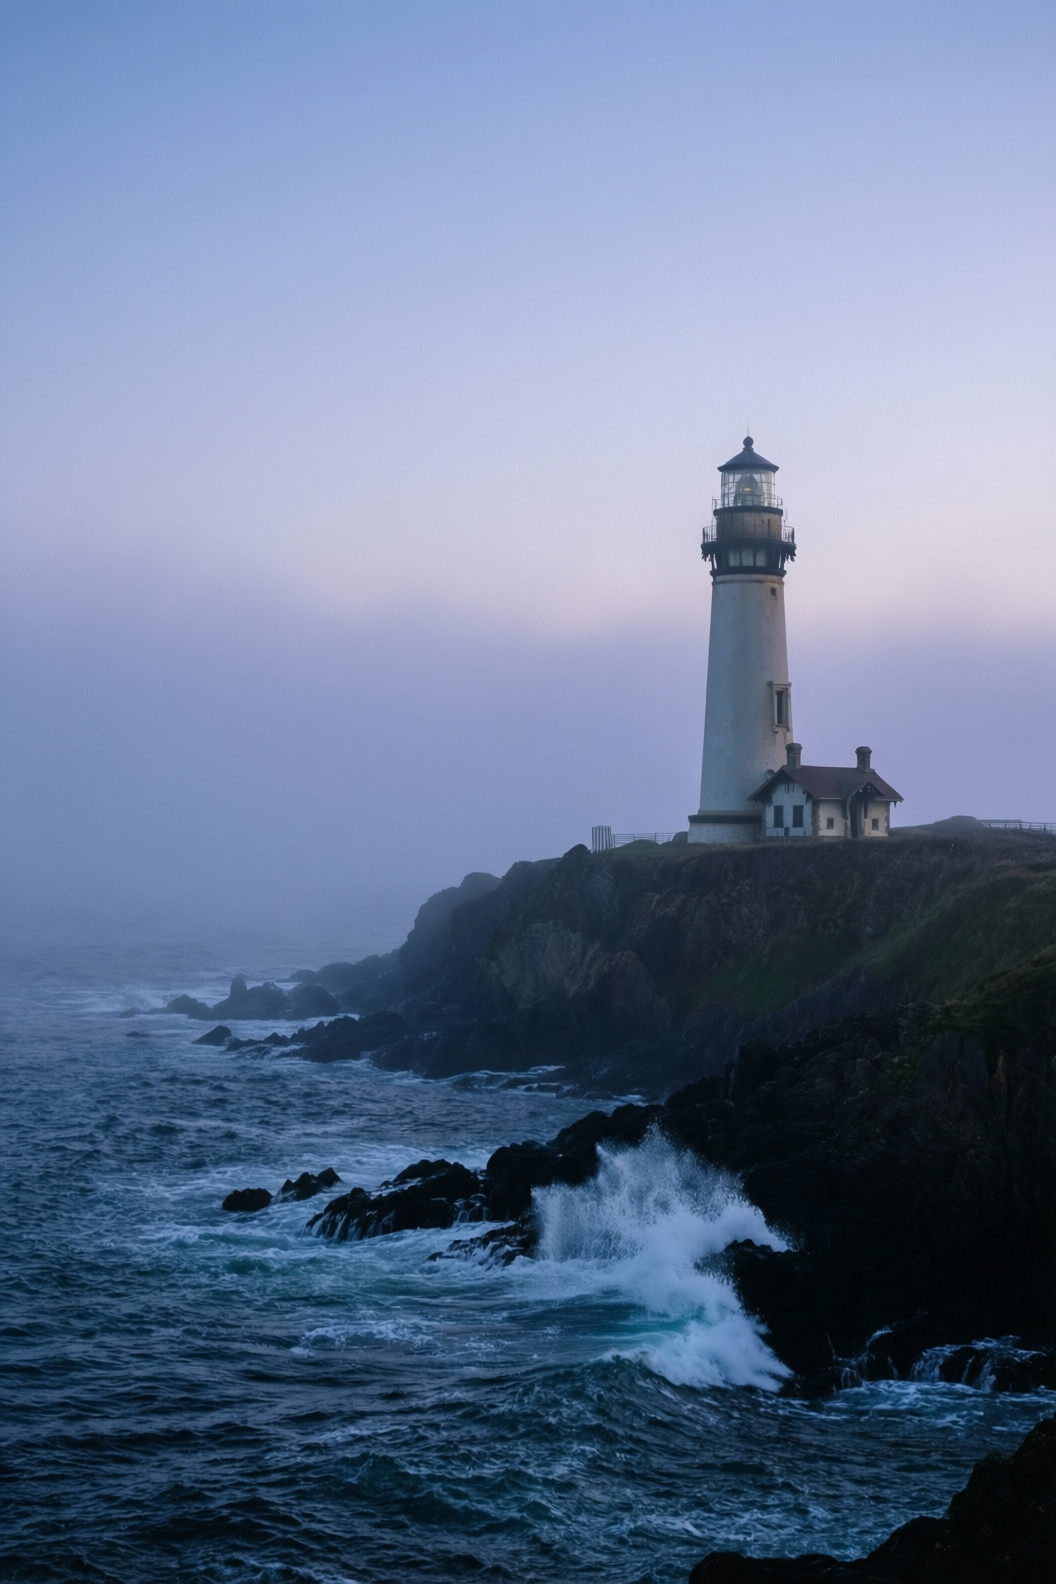 | 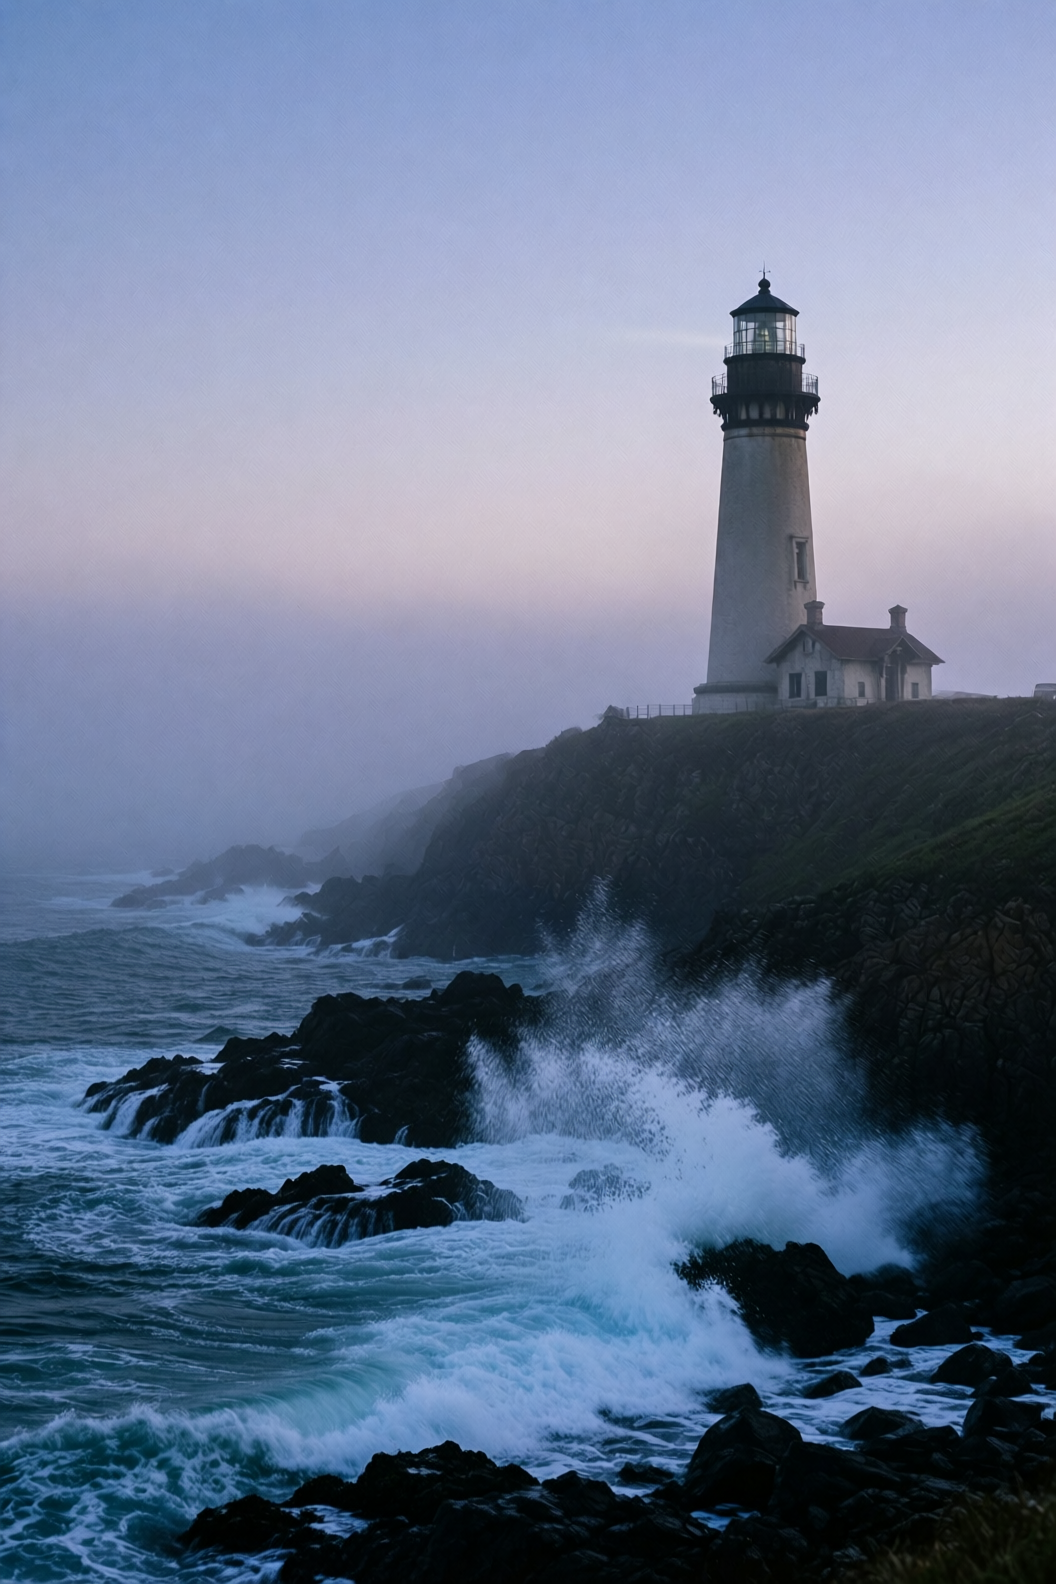 | 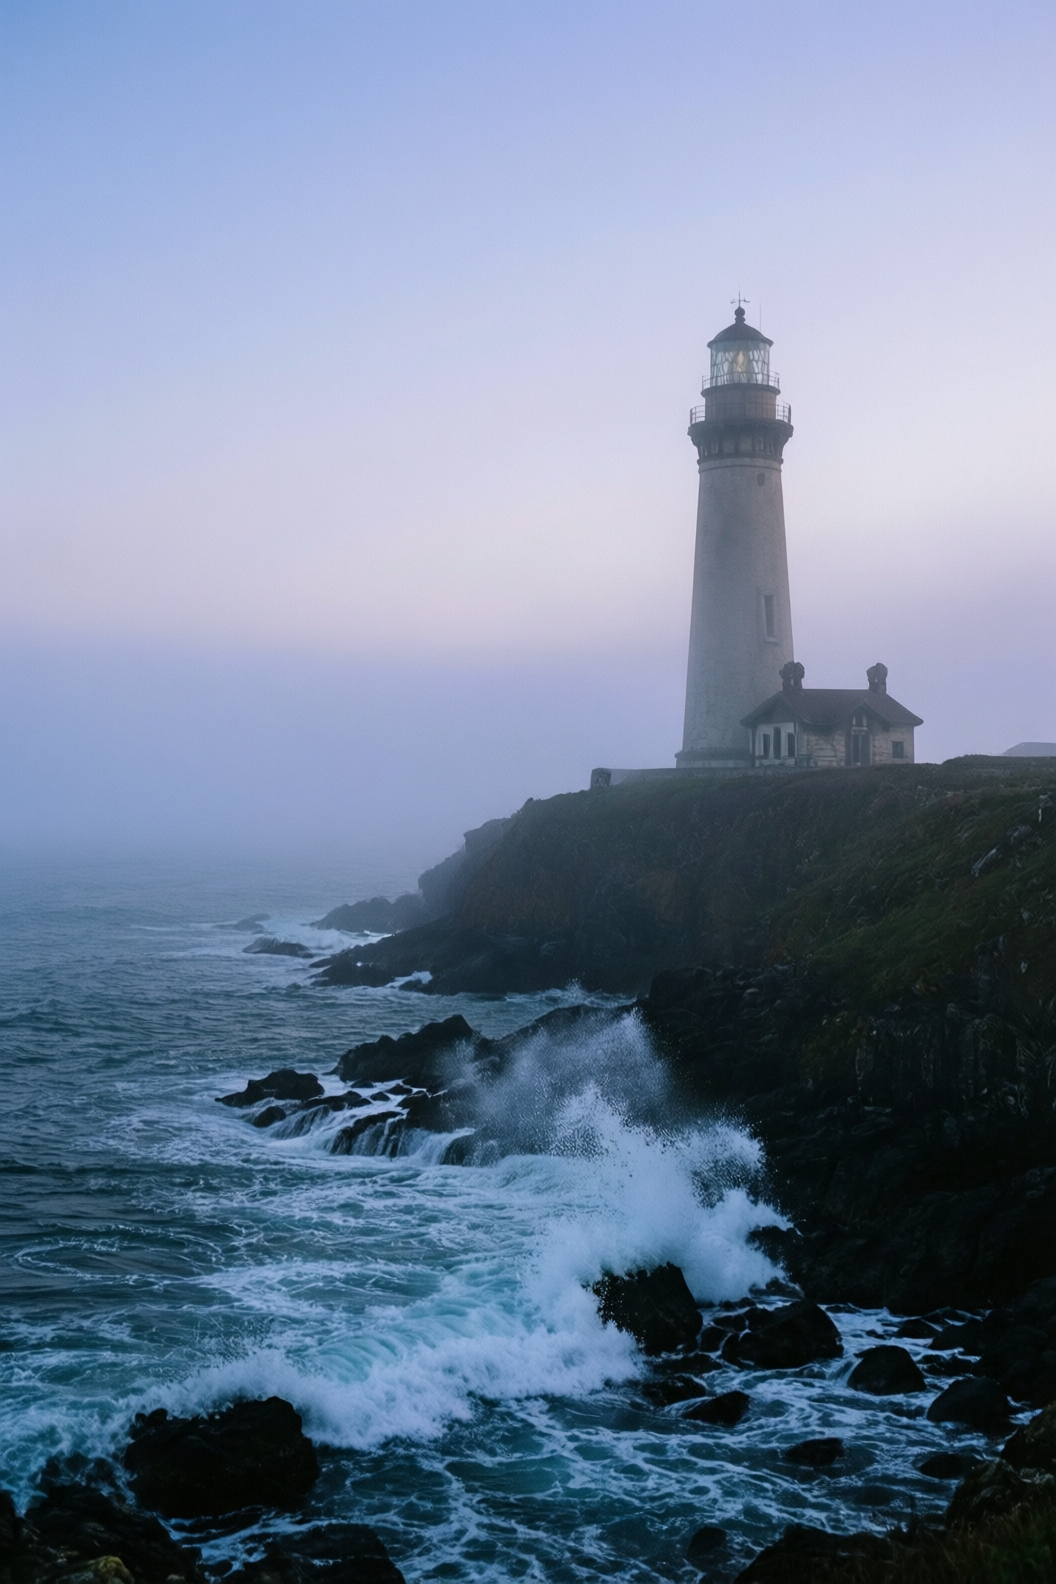 |
| An ultra-realistic close-up of a golden retriever outdoors under soft daylight. Hair is exquisitely detailed: strands distinct, color transitioning naturally from warm gold to light cream, light glinting delicately at the tips; a gentle breeze adds subtle volume. Undercoat is soft and dense; guard hairs are long and well-defined, with visible layering. Eyes are moist, expressive; nose is slightly damp with fine specular highlights. Background is softly blurred to emphasize the dog’s tangible texture and vivid expression. | 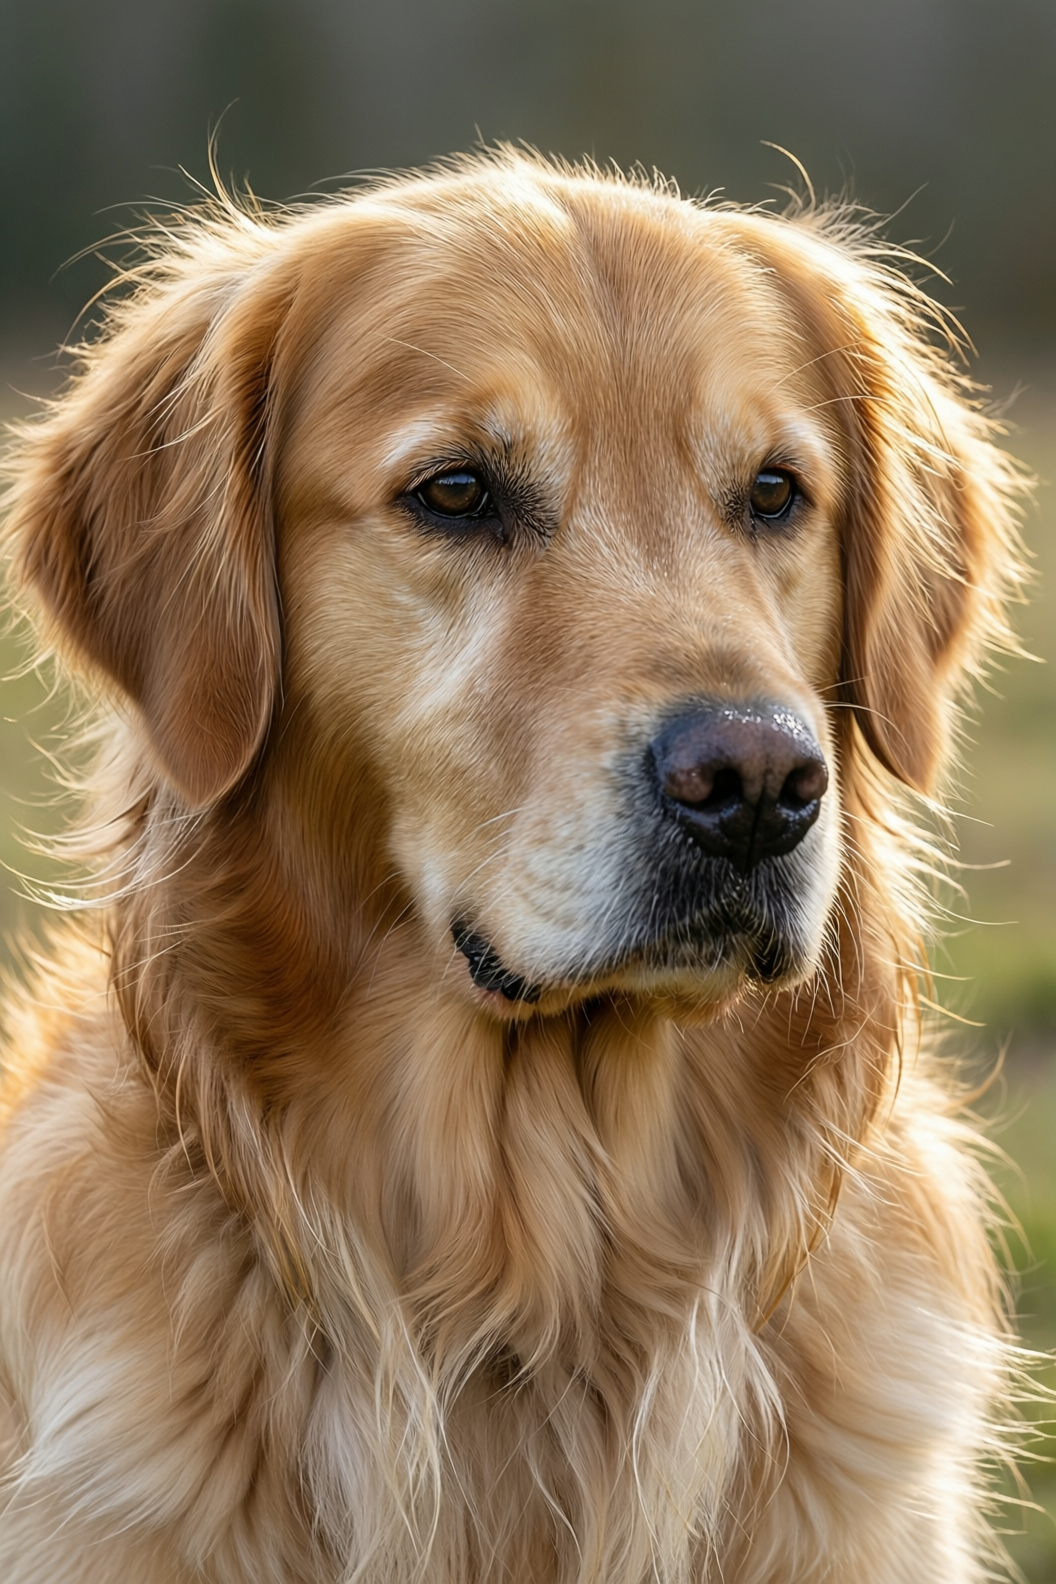 | 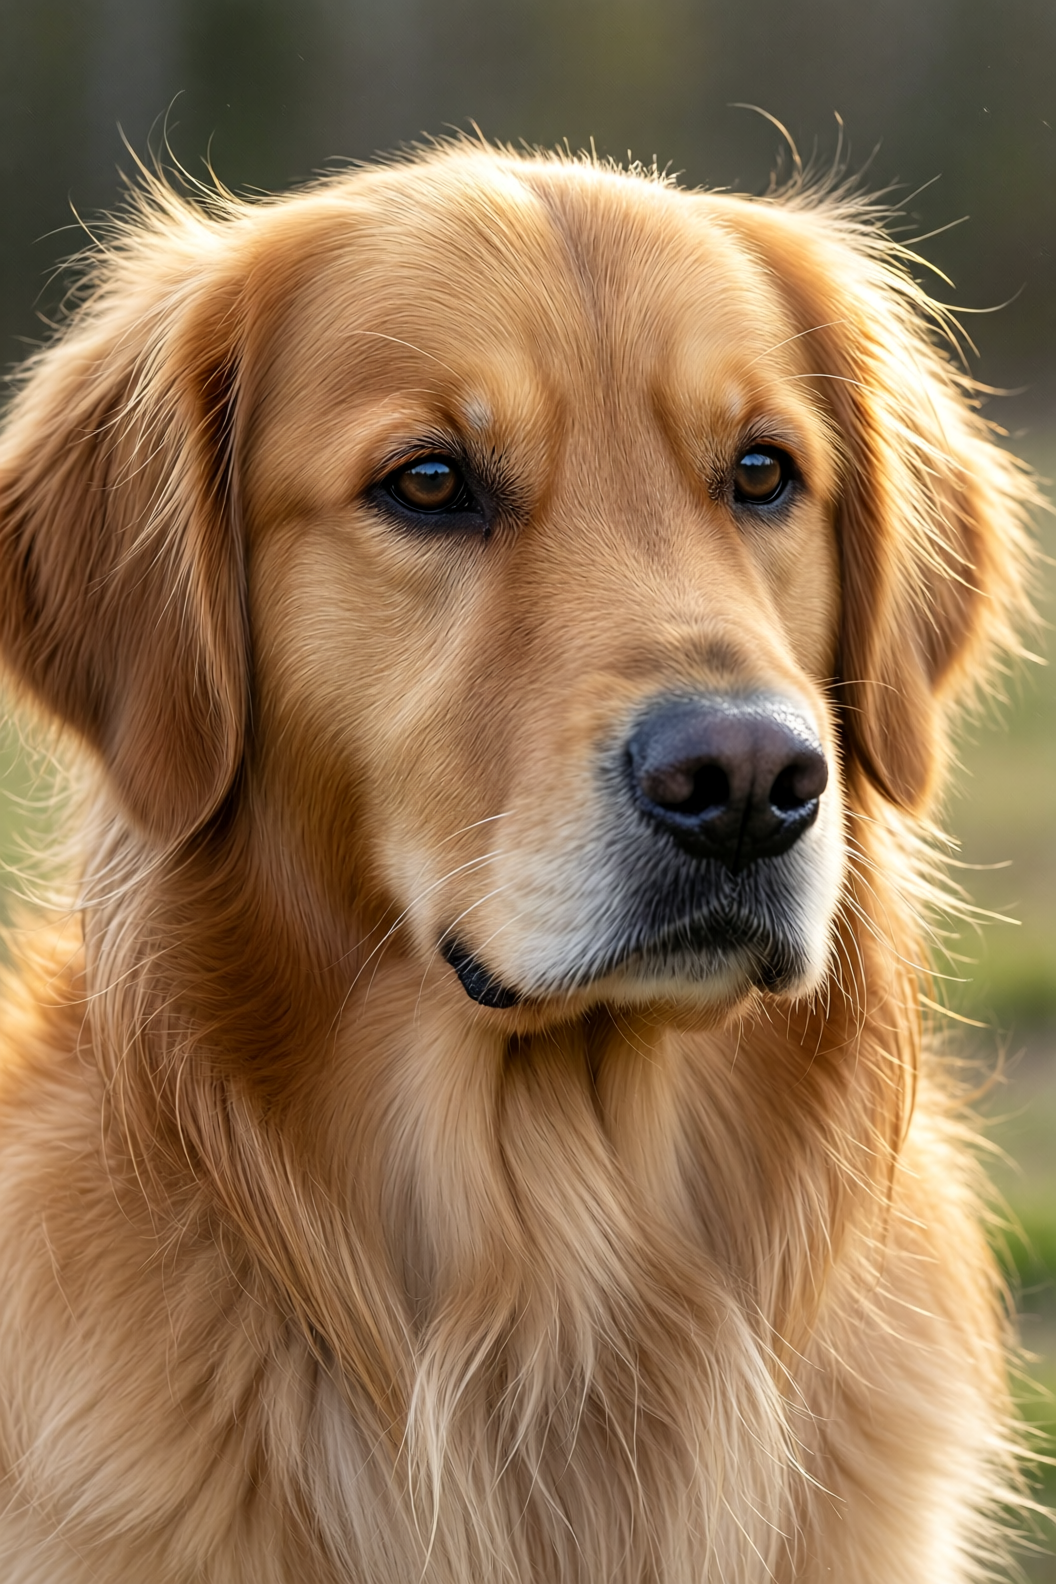 | 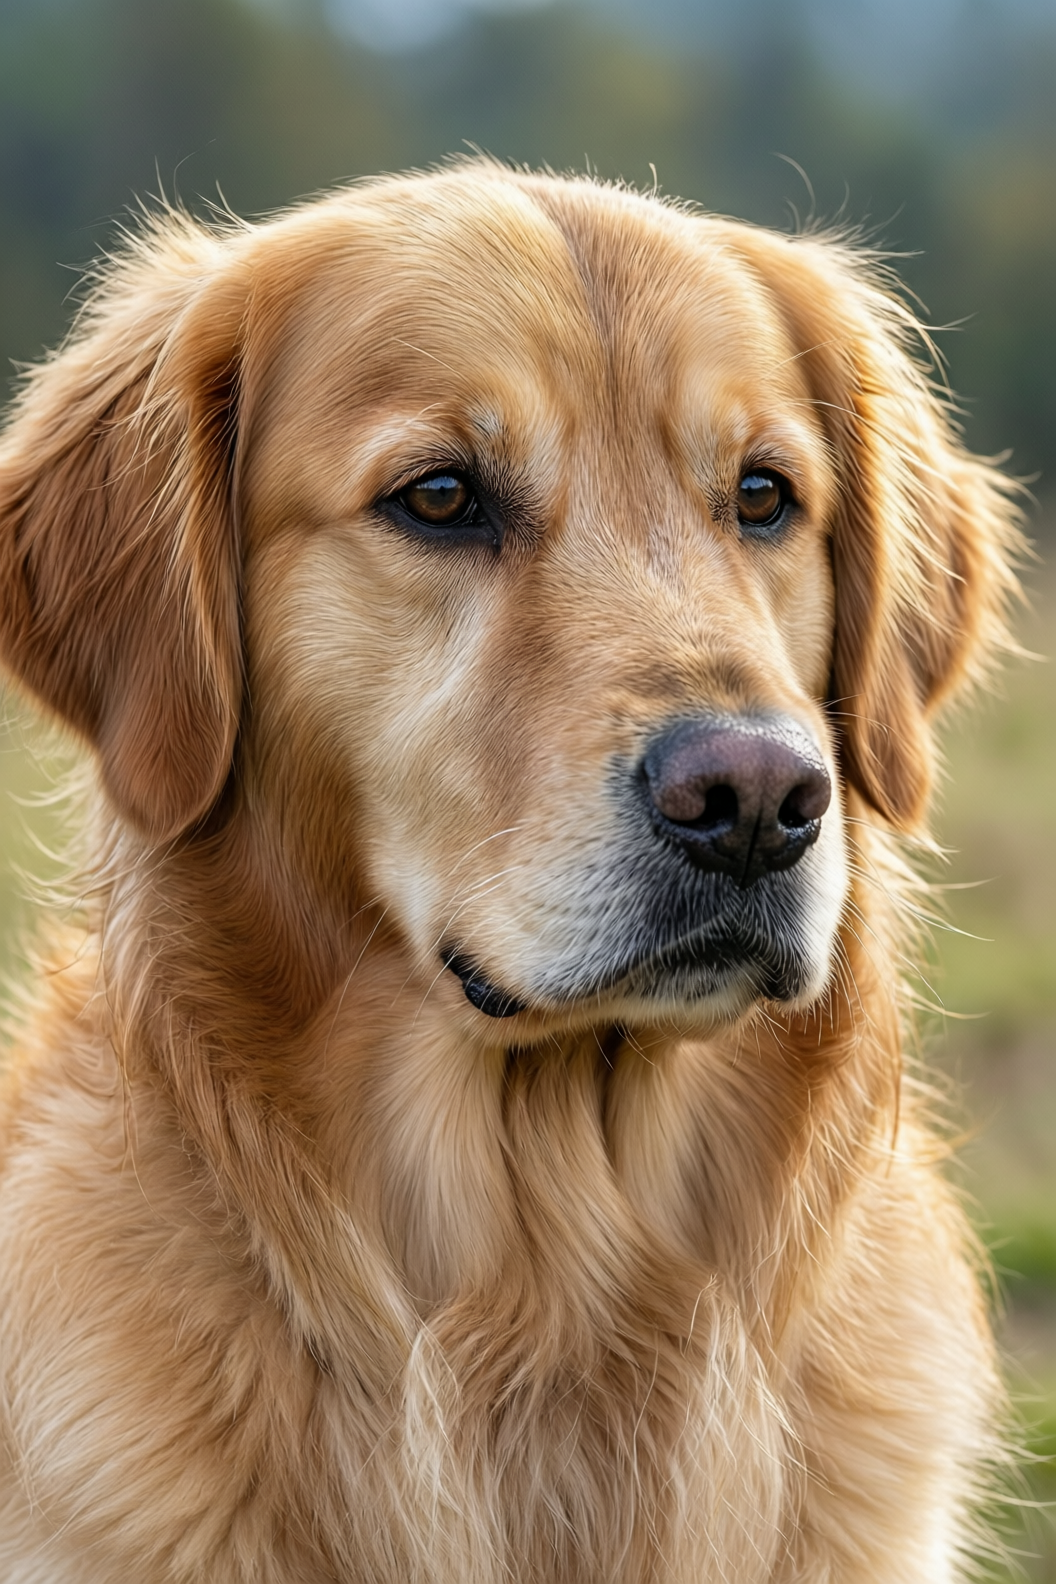 |
| Bookstore window display. A sign displays “New Arrivals This Week”. Below, a shelf tag with the text “Best-Selling Novels Here”. To the side, a colorful poster advertises “Author Meet And Greet on Saturday” with a central portrait of the author. There are four books on the bookshelf, namely “The light between worlds” “When stars are scattered” “The slient patient” “The night circus” | 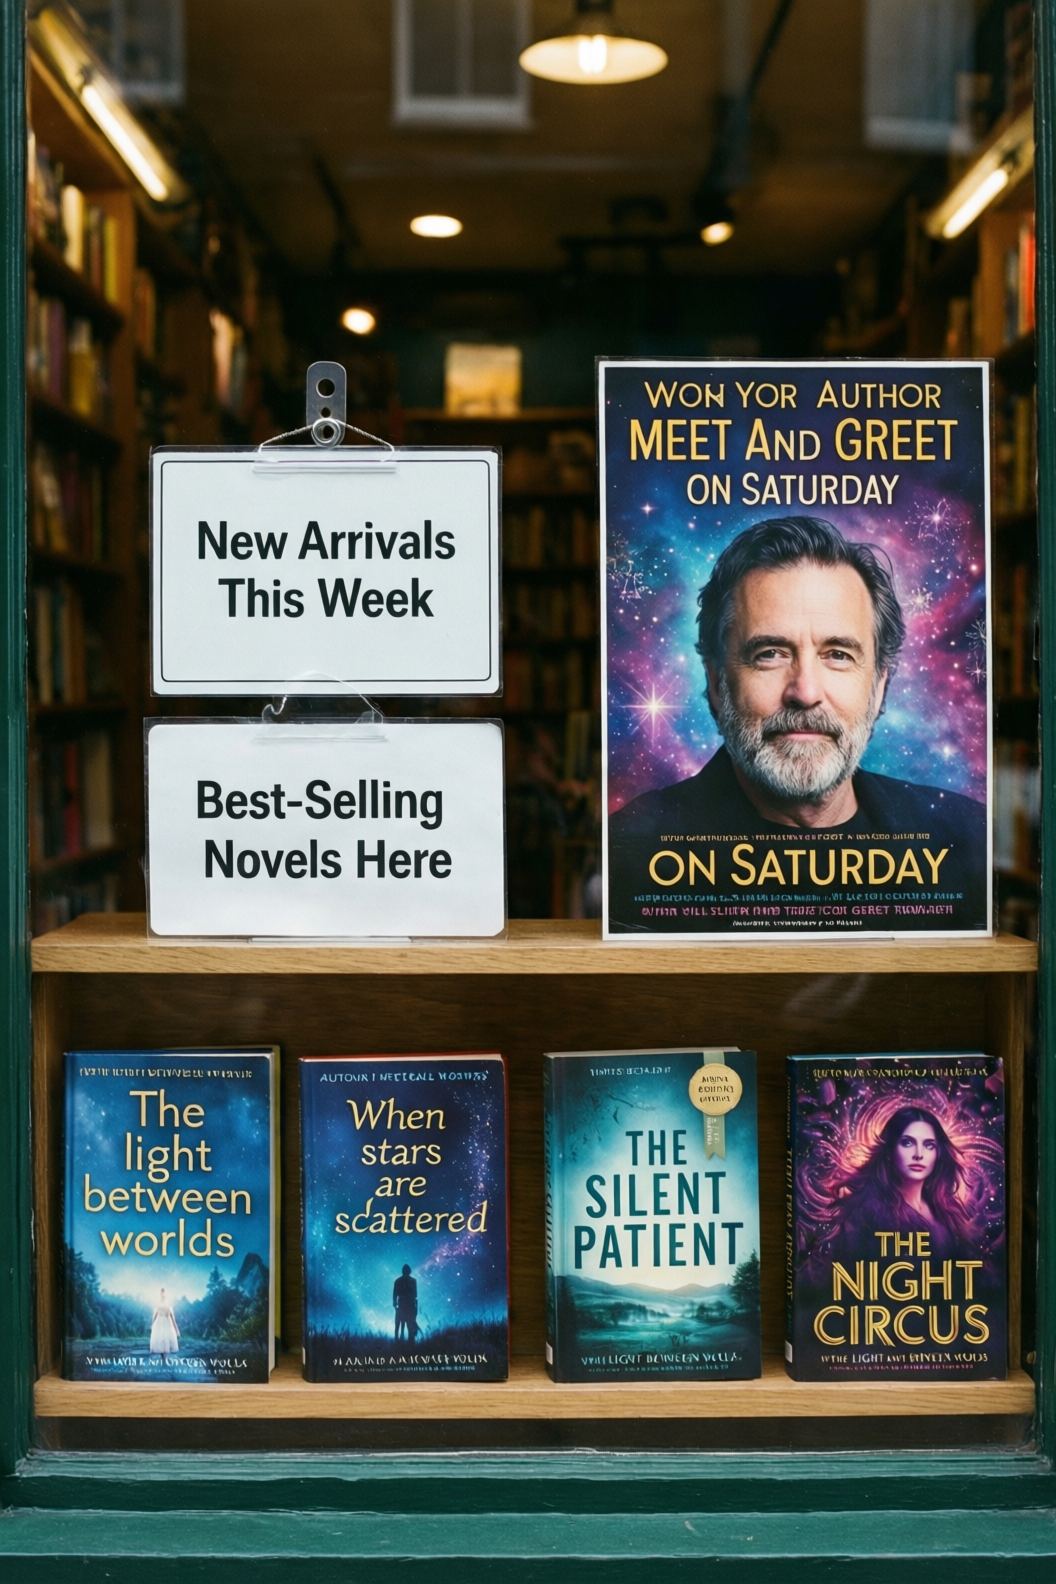 | 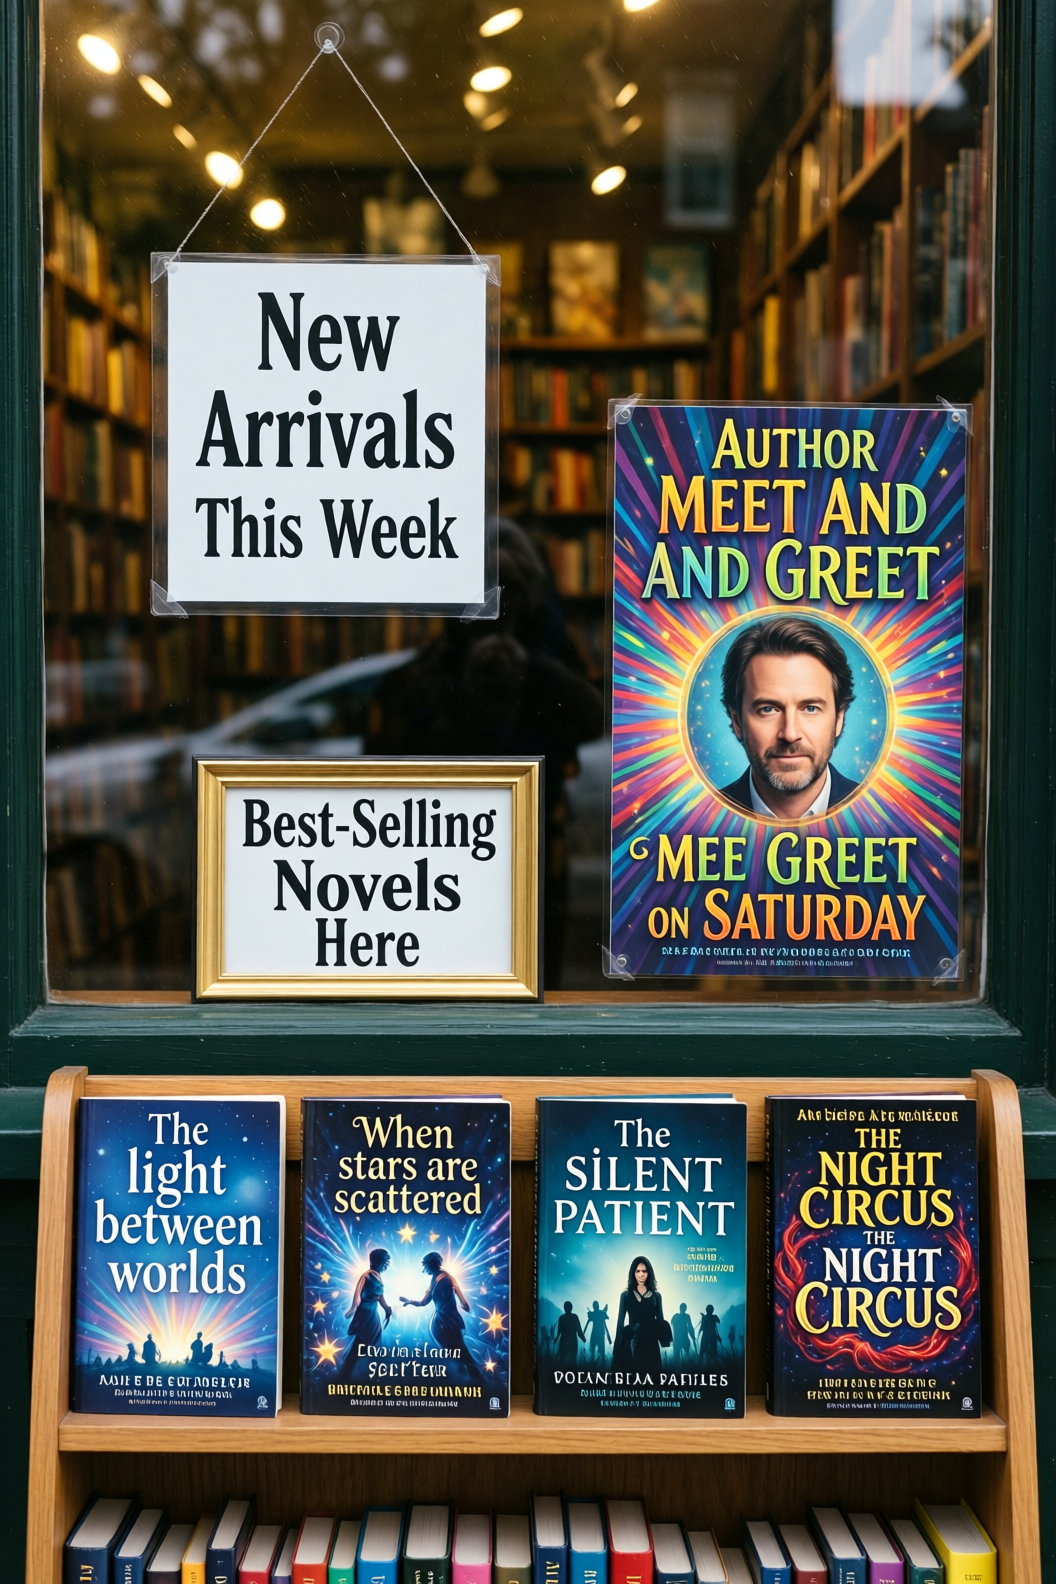 | 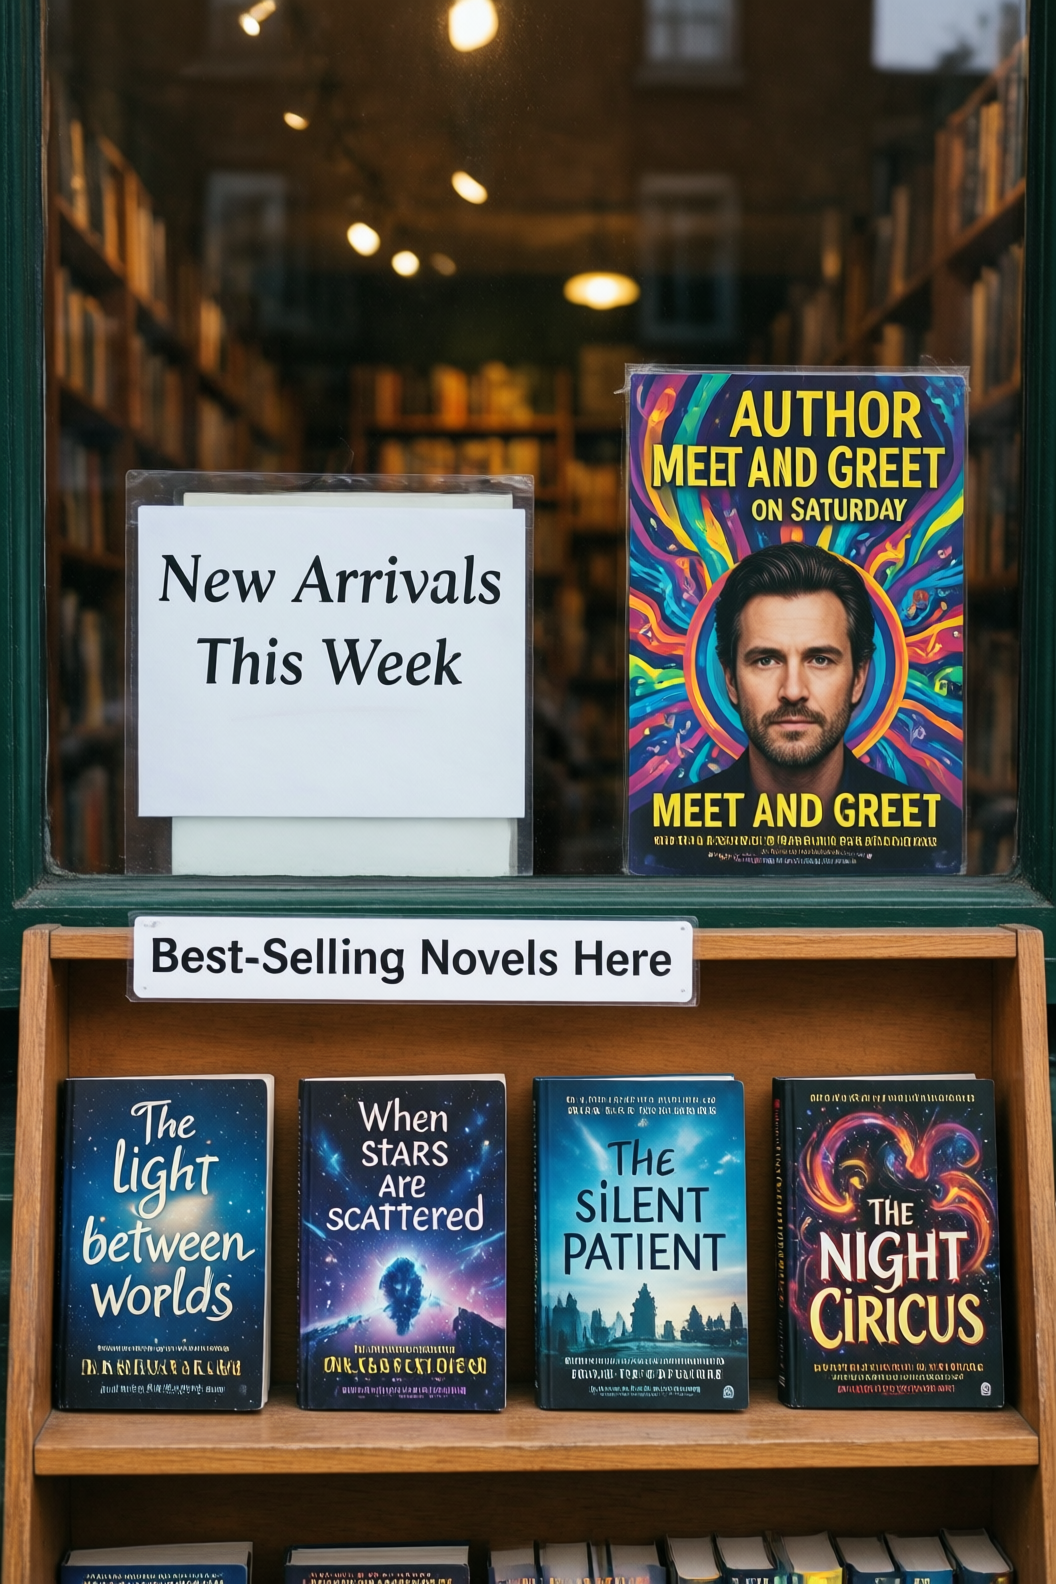 |
Quick start with Diffsynth-Engine
- Diffsynth-Engine:https://github.com/modelscope/DiffSynth-Engine
- Example Code:
import math
from diffsynth_engine import fetch_model, QwenImagePipeline, QwenImagePipelineConfig

# Create pipeline
config = QwenImagePipelineConfig.basic_config(
    model_path=fetch_model("Qwen/Qwen-Image-2512", path="transformer/*.safetensors"),
    encoder_path=fetch_model("Qwen/Qwen-Image-2512", path="text_encoder/*.safetensors"),
    vae_path=fetch_model("Qwen/Qwen-Image-2512", path="vae/*.safetensors"),
    offload_mode="cpu_offload",
)
pipe = QwenImagePipeline.from_pretrained(config)

# Load our turbo LoRA
pipe.load_lora(
    path=fetch_model("Wuli-art/Qwen-Image-2512-Turbo-LoRA-2-Steps", path="Wuli-Qwen-Image-2512-Turbo-LoRA-2steps-V1.0-bf16.safetensors"),
    scale=1.0,
    fused=True,
)

# Change scheduler config
scheduler_config = {
    "exponential_shift_mu": math.log(2.5),
    "use_dynamic_shifting": True,
    "shift_terminal": 0.7155
}
pipe.apply_scheduler_config(scheduler_config)

# Sample image
output = pipe(
    prompt="a young girl with flowing long hair, wearing a white halter dress and smiling sweetly. The background features a blue seaside where seagulls fly freely.",
    cfg_scale=1,
    num_inference_steps=2,
    seed=42,
    width=1328,
    height=1328
)
output.save("output.png")
Existing problem
- Generated image quality may degrade when handling extremely complex text rendering tasks, you can increase the value of
num_inference_steps.