AMD Nitro-T
Introduction
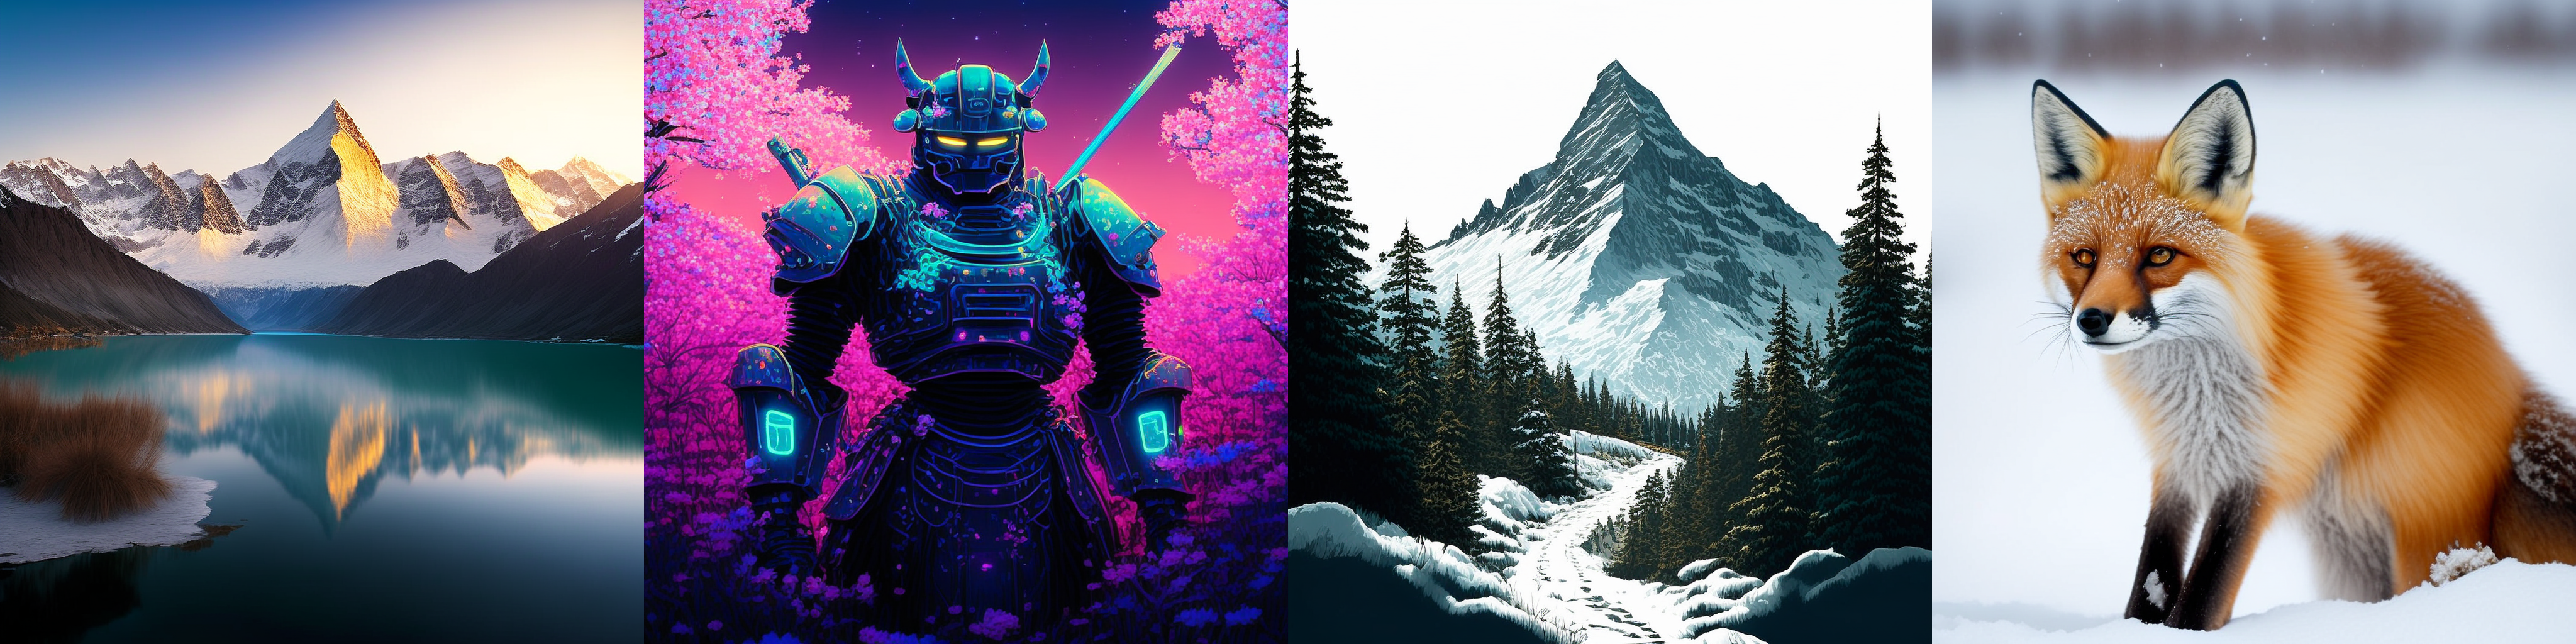
Nitro-T is a family of text-to-image diffusion models focused on highly efficient training. Our models achieve competitive scores on image generation benchmarks compared to previous models focused on efficient training while requiring less than 1 day of training from scratch on 32 AMD Instinct™ MI300X GPUs. The release consists of:
- Nitro-T-0.6B: a 512px DiT-based model
- Nitro-T-1.2B: a 1024px MMDiT-based model
⚡️ Open-source code! Our GitHub provides training and data preparation scripts to reproduce our results. We hope this codebase for efficient diffusion model training enables researchers to iterate faster on ideas and lowers the barrier for independent developers to build custom models.
📝 Read our technical blog post for more details on the techniques we used to achieve fast training and for results and evaluations.
Details
- Model architecture: Nitro-T-0.6B is a text-to-image Diffusion Transformer that resembles the architecture of PixArt-α. It uses the latent space of Deep Compression Autoencoder (DC-AE) and uses a Llama 3.2 1B model for text conditioning. Additionally, several techniques were used to reduce training time. See our technical blog post for more details.
- Dataset: The Nitro-T models were trained on a dataset of ~35M images consisting of both real and synthetic data sources that are openly available on the internet. See our GitHub repo for data processing scripts.
- Training cost: Nitro-T-0.6B requires less than 1 day of training from scratch on 32 AMD Instinct™ MI300X GPUs.
Quickstart
You must use diffusers>=0.34 in order to load the model from the Huggingface hub.
import torch
from diffusers import DiffusionPipeline
from transformers import AutoModelForCausalLM

torch.set_grad_enabled(False)

device = torch.device('cuda:0')
dtype = torch.bfloat16
resolution = 512
MODEL_NAME = "amd/Nitro-T-0.6B"

text_encoder = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-3.2-1B", torch_dtype=dtype)
pipe = DiffusionPipeline.from_pretrained(
    MODEL_NAME,
    text_encoder=text_encoder,
    torch_dtype=dtype,
    trust_remote_code=True,
)
pipe.to(device)

image = pipe(
    prompt="The image is a close-up portrait of a scientist in a modern laboratory. He has short, neatly styled black hair and wears thin, stylish eyeglasses. The lighting is soft and warm, highlighting his facial features against a backdrop of lab equipment and glowing screens.",
    height=resolution, width=resolution,
    num_inference_steps=20,
    guidance_scale=4.0,
).images[0]

image.save("output.png")
For more details on training and evaluation please visit the GitHub repo and read our technical blog post.
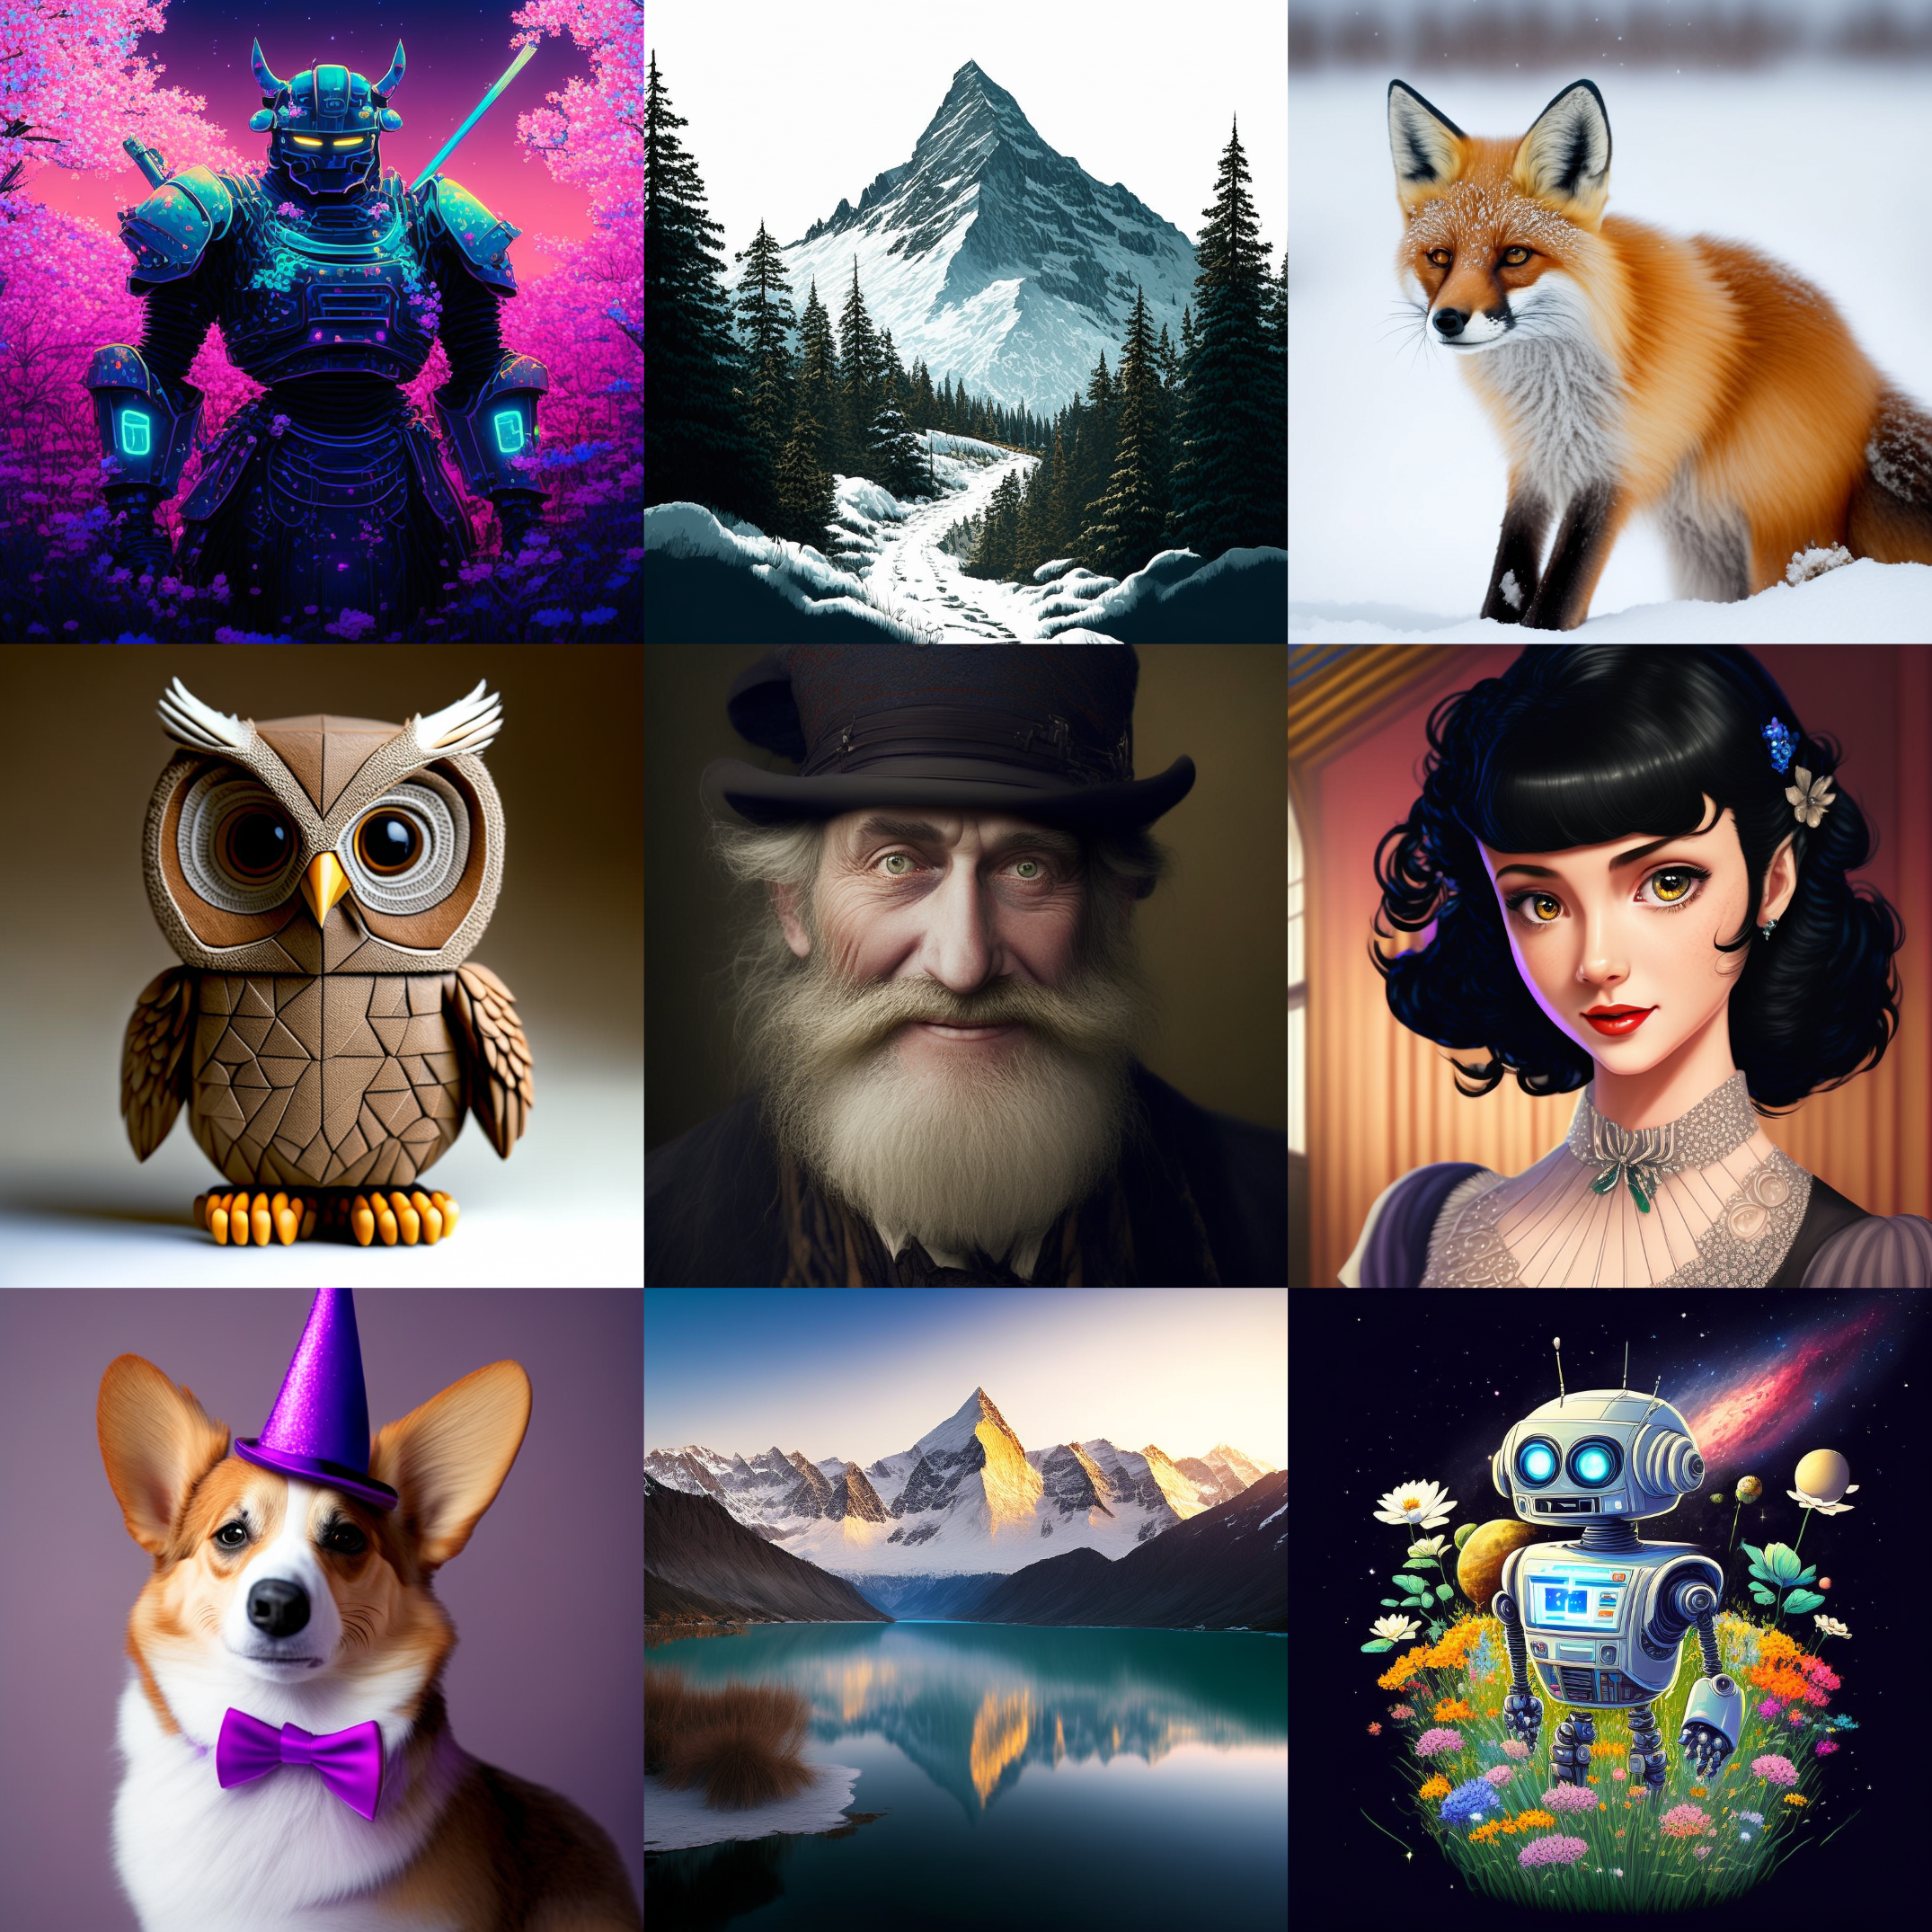
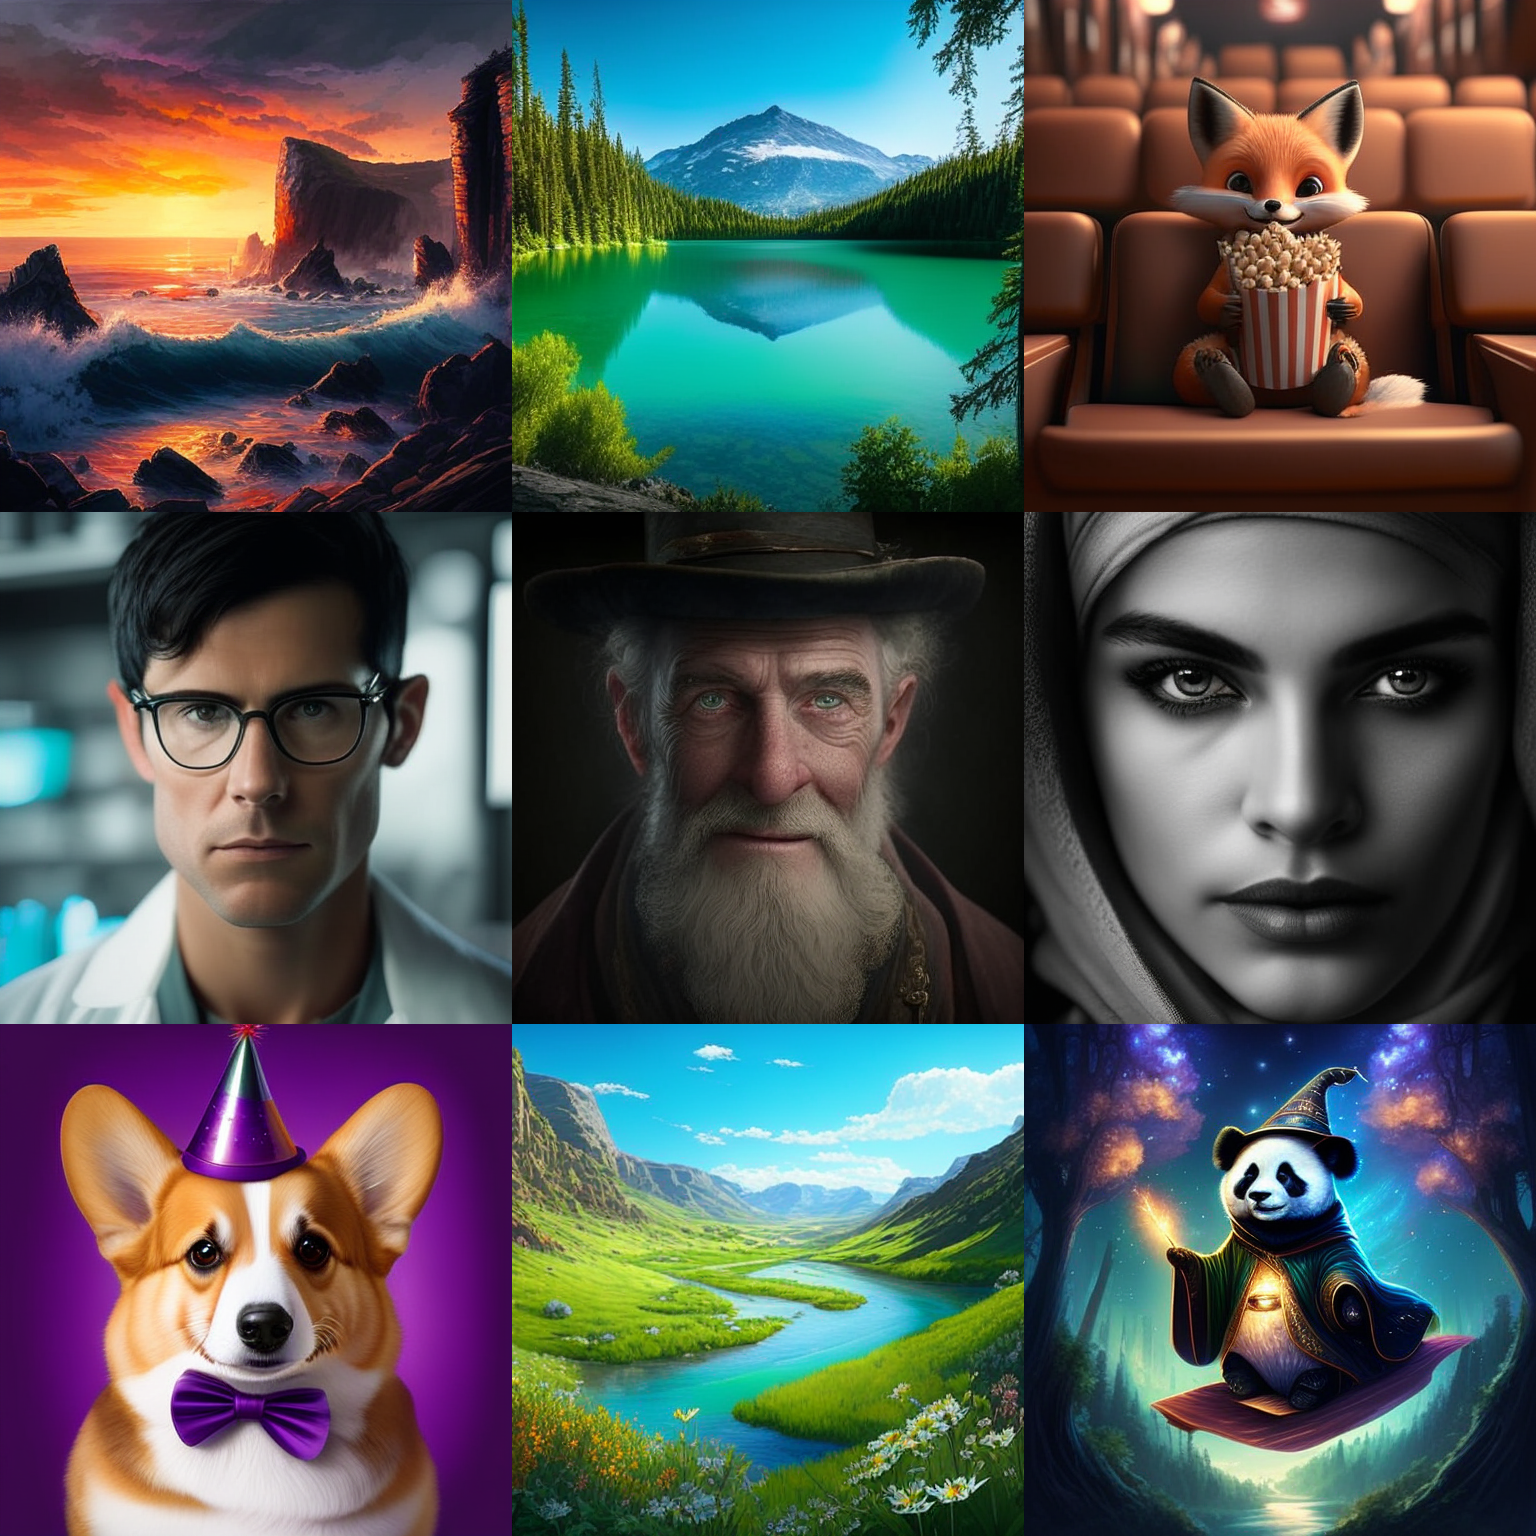
Examples of images generated by Nitro-T
 |
|---|
| Images generated by Nitro-T-1.2B at 1024px resolution |
 |
|---|
| Images generated by Nitro-T-0.6B at 512px resolution |
License
Copyright (c) 2018-2025 Advanced Micro Devices, Inc. All Rights Reserved. Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with the License. You may obtain a copy of the License at http://www.apache.org/licenses/LICENSE-2.0 Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the specific language governing permissions and limitations under the License.