Model
This model is hosted for Demodokos Foundry but it can be used for other purposes, enjoy a stable download location and custom quantizations not available elsewhere.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
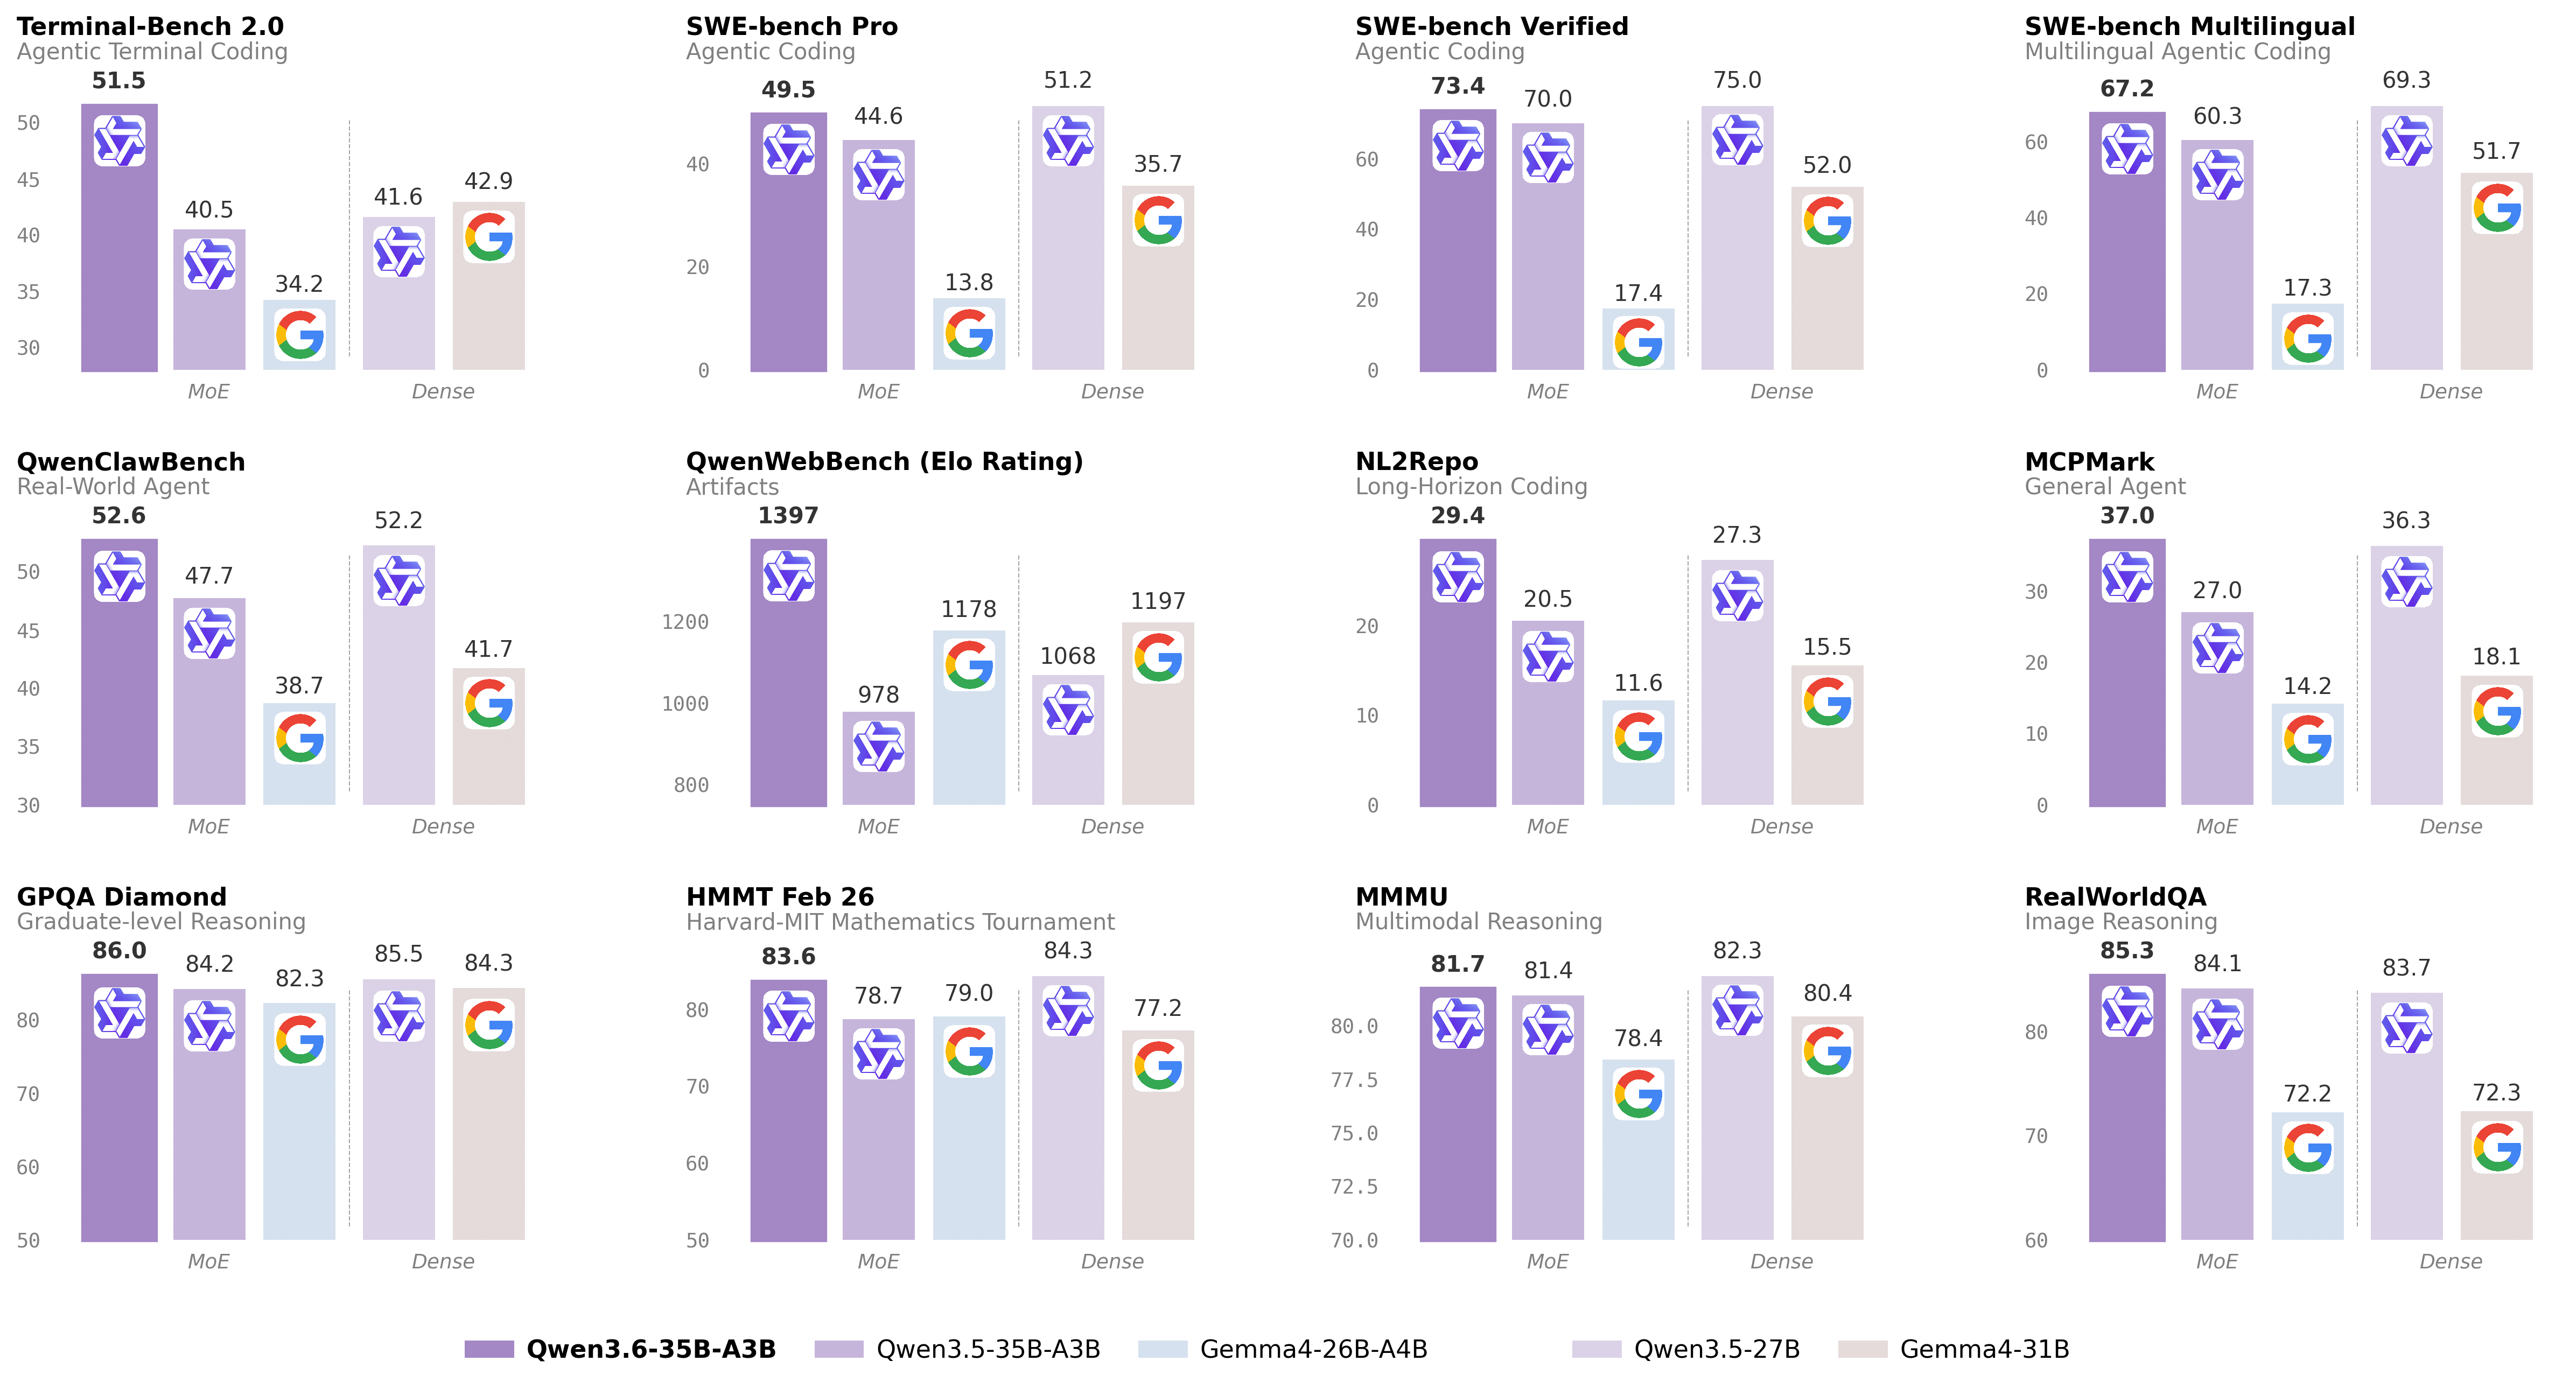
For more details, please refer to our blog post Qwen3.6-35B-A3B.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 35B in total and 3B activated
- Hidden Dimension: 2048
- Token Embedding: 248320 (Padded)
- Number of Layers: 40
- Hidden Layout: 10 × (3 × (Gated DeltaNet → MoE) → 1 × (Gated Attention → MoE))
- Gated DeltaNet:
- Number of Linear Attention Heads: 32 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 16 for Q and 2 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Mixture Of Experts
- Number of Experts: 256
- Number of Activated Experts: 8 Routed + 1 Shared
- Expert Intermediate Dimension: 512
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
Benchmark Results
Language
Vision Language
Citation
If you find our work helpful, feel free to give us a cite.
@misc{qwen36_35b_a3b,
    title = {{Qwen3.6-35B-A3B}: Agentic Coding Power, Now Open to All},
    url = {https://qwen.ai/blog?id=qwen3.6-35b-a3b},
    author = {{Qwen Team}},
    month = {April},
    year = {2026}
}