DETR (End-to-End Object Detection) model with ResNet-50 backbone
DEtection TRansformer (DETR) model trained end-to-end on COCO 2017 object detection (118k annotated images). It was introduced in the paper End-to-End Object Detection with Transformers by Carion et al. and first released in this repository.
Disclaimer: The team releasing DETR did not write a model card for this model so this model card has been written by the Hugging Face team.
Model description
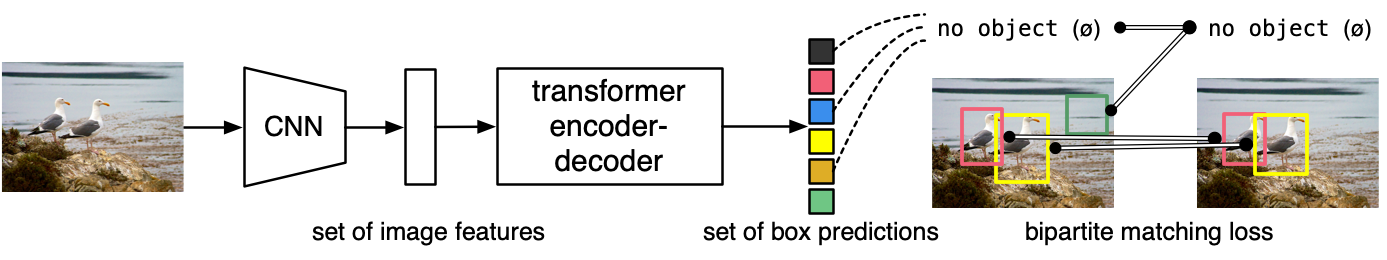
The DETR model is an encoder-decoder transformer with a convolutional backbone. Two heads are added on top of the decoder outputs in order to perform object detection: a linear layer for the class labels and a MLP (multi-layer perceptron) for the bounding boxes. The model uses so-called object queries to detect objects in an image. Each object query looks for a particular object in the image. For COCO, the number of object queries is set to 100.
The model is trained using a "bipartite matching loss": one compares the predicted classes + bounding boxes of each of the N = 100 object queries to the ground truth annotations, padded up to the same length N (so if an image only contains 4 objects, 96 annotations will just have a "no object" as class and "no bounding box" as bounding box). The Hungarian matching algorithm is used to create an optimal one-to-one mapping between each of the N queries and each of the N annotations. Next, standard cross-entropy (for the classes) and a linear combination of the L1 and generalized IoU loss (for the bounding boxes) are used to optimize the parameters of the model.
Intended uses & limitations
You can use the raw model for object detection. See the model hub to look for all available DETR models.
How to use
Here is how to use this model:
from transformers import DetrImageProcessor, DetrForObjectDetection
import torch
from PIL import Image
import requests

url = "http://images.cocodataset.org/val2017/000000039769.jpg"
image = Image.open(requests.get(url, stream=True).raw)

# you can specify the revision tag if you don't want the timm dependency
processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-50", revision="no_timm")
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50", revision="no_timm")

inputs = processor(images=image, return_tensors="pt")
outputs = model(**inputs)

# convert outputs (bounding boxes and class logits) to COCO API
# let's only keep detections with score > 0.9
target_sizes = torch.tensor([image.size[::-1]])
results = processor.post_process_object_detection(outputs, target_sizes=target_sizes, threshold=0.9)[0]

for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
    box = [round(i, 2) for i in box.tolist()]
    print(
            f"Detected {model.config.id2label[label.item()]} with confidence "
            f"{round(score.item(), 3)} at location {box}"
    )
This should output:
Detected remote with confidence 0.998 at location [40.16, 70.81, 175.55, 117.98]
Detected remote with confidence 0.996 at location [333.24, 72.55, 368.33, 187.66]
Detected couch with confidence 0.995 at location [-0.02, 1.15, 639.73, 473.76]
Detected cat with confidence 0.999 at location [13.24, 52.05, 314.02, 470.93]
Detected cat with confidence 0.999 at location [345.4, 23.85, 640.37, 368.72]
Currently, both the feature extractor and model support PyTorch.
Training data
The DETR model was trained on COCO 2017 object detection, a dataset consisting of 118k/5k annotated images for training/validation respectively.
Training procedure
Preprocessing
The exact details of preprocessing of images during training/validation can be found here.
Images are resized/rescaled such that the shortest side is at least 800 pixels and the largest side at most 1333 pixels, and normalized across the RGB channels with the ImageNet mean (0.485, 0.456, 0.406) and standard deviation (0.229, 0.224, 0.225).
Training
The model was trained for 300 epochs on 16 V100 GPUs. This takes 3 days, with 4 images per GPU (hence a total batch size of 64).
Evaluation results
This model achieves an AP (average precision) of 42.0 on COCO 2017 validation. For more details regarding evaluation results, we refer to table 1 of the original paper.
BibTeX entry and citation info
@article{DBLP:journals/corr/abs-2005-12872,
  author    = {Nicolas Carion and
               Francisco Massa and
               Gabriel Synnaeve and
               Nicolas Usunier and
               Alexander Kirillov and
               Sergey Zagoruyko},
  title     = {End-to-End Object Detection with Transformers},
  journal   = {CoRR},
  volume    = {abs/2005.12872},
  year      = {2020},
  url       = {https://arxiv.org/abs/2005.12872},
  archivePrefix = {arXiv},
  eprint    = {2005.12872},
  timestamp = {Thu, 28 May 2020 17:38:09 +0200},
  biburl    = {https://dblp.org/rec/journals/corr/abs-2005-12872.bib},
  bibsource = {dblp computer science bibliography, https://dblp.org}
}