Voxtral-Mini-4B-Realtime-2602: transcribe.cpp GGUF
GGUF conversions of mistralai/Voxtral-Mini-4B-Realtime-2602 for use with transcribe.cpp.
Ported from upstream commit 2769294, pinned 2026-06-06. Validated against the Transformers reference at transcribe.cpp commit 483c122 on 2026-06-06.
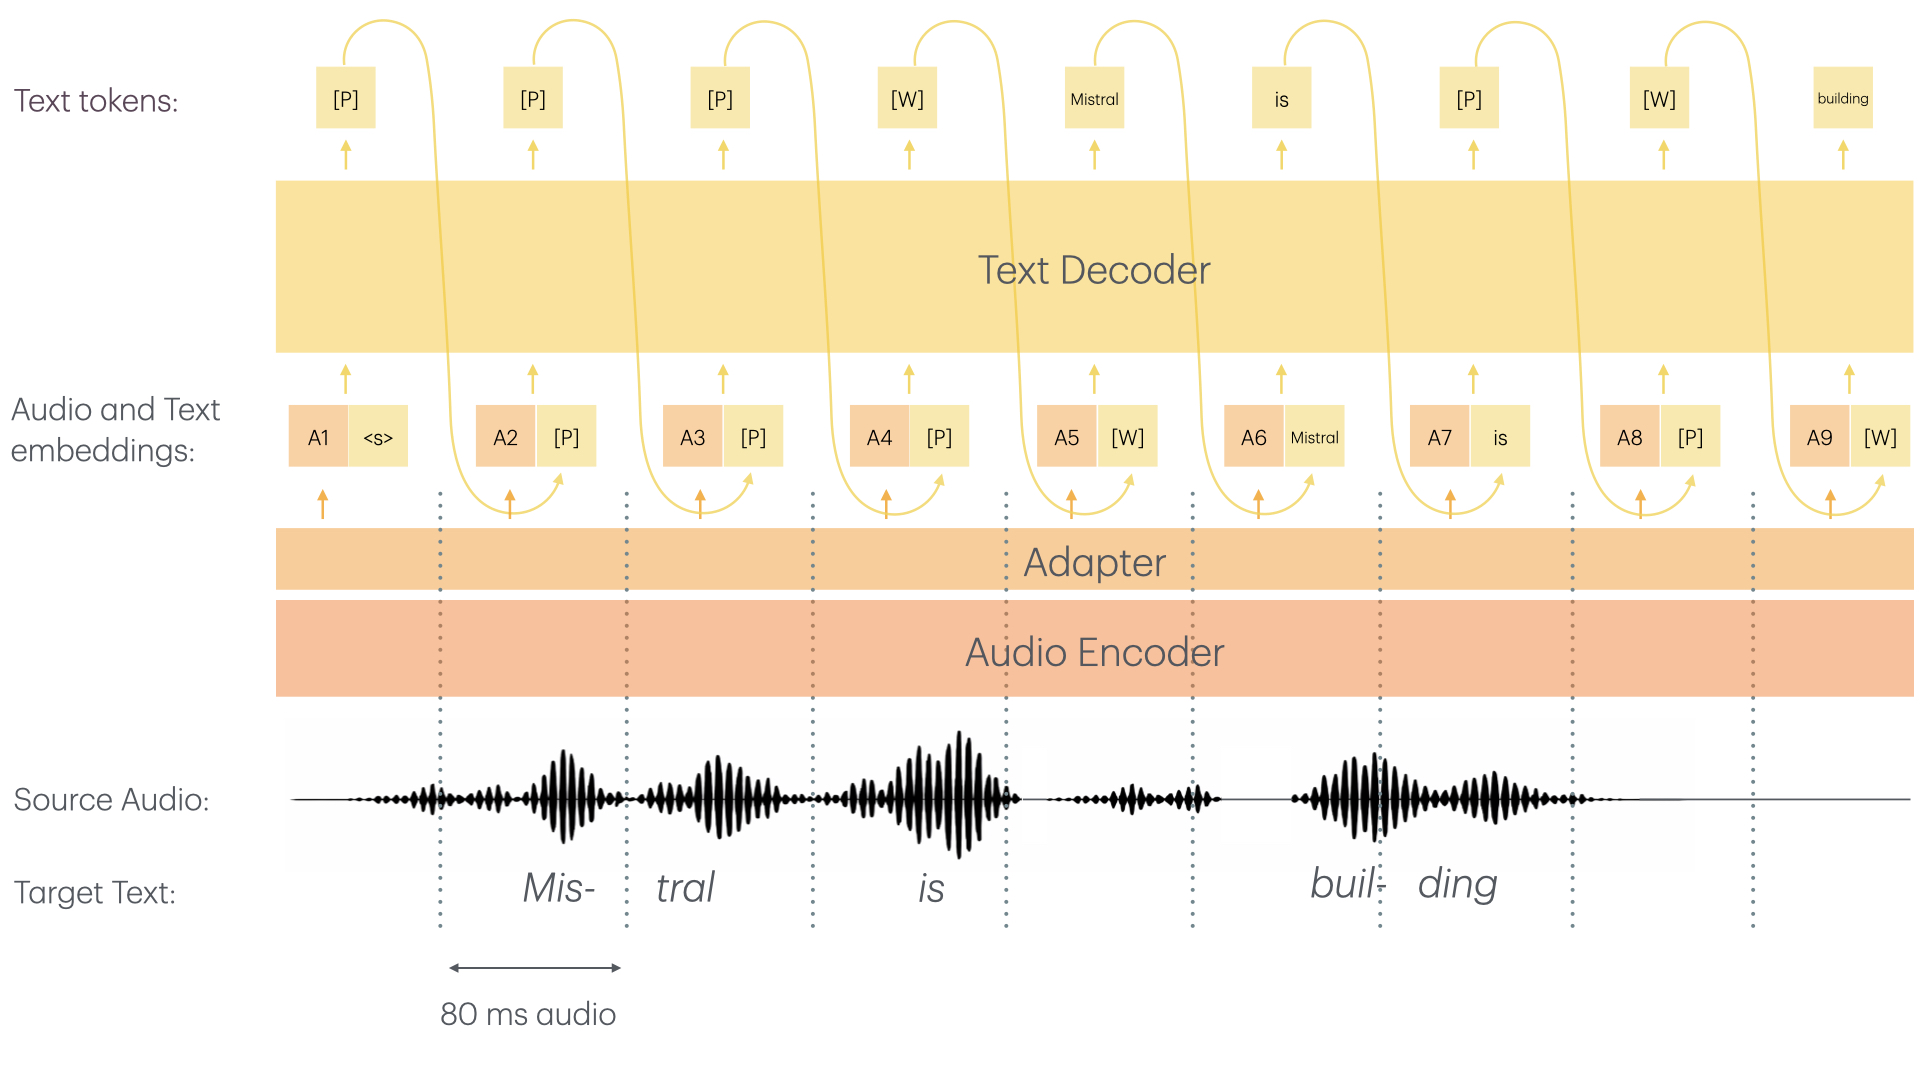
Streaming audio-LLM speech-to-text. A ~970M causal audio encoder (left-pad causal conv stem + 32-layer sliding-window RoPE transformer) feeds a 4-frame-group projector whose audio embeddings are added onto a ~3.4B Ministral decoder (26 layers, GQA 32/8, NEOX RoPE) with delay-token latency conditioning, emitting one text token per 80 ms audio slot (12.5 Hz). Takes a 16 kHz mono WAV and supports both incremental streaming (configurable latency/quality via --stream-chunk-ms and --stream-voxtral-delay) and offline transcription using an accuracy-first 2400 ms delay. Architecturally distinct from the offline Voxtral 2507 family — own arch, streaming frontend, causal encoder, additive audio fusion.
Downloads
| Quantization | Download | Size | WER (LibriSpeech test-clean) |
|---|---|---|---|
| BF16 | Voxtral-Mini-4B-Realtime-2602-BF16.gguf | 8.87 GB | 2.08% |
| F16 | Voxtral-Mini-4B-Realtime-2602-F16.gguf | 8.88 GB | 2.09% |
| Q8_0 | Voxtral-Mini-4B-Realtime-2602-Q8_0.gguf | 4.73 GB | 2.07% |
| Q6_K | Voxtral-Mini-4B-Realtime-2602-Q6_K.gguf | 3.66 GB | 2.08% |
| Q5_K_M | Voxtral-Mini-4B-Realtime-2602-Q5_K_M.gguf | 3.28 GB | 2.08% |
| Q4_K_M | Voxtral-Mini-4B-Realtime-2602-Q4_K_M.gguf | 2.83 GB | 2.08% |
WER on the full LibriSpeech test-clean split (2,620 utterances), batch size 8, timestamps none. Figures without a commit were published before provenance was recorded.
Scored with the Whisper English text normalizer, offline path at delay 6, on an NVIDIA L40S. A delay-30 remeasurement is pending. Same-machine HuggingFace transformers reference (VoxtralRealtimeForConditionalGeneration, BF16, greedy): 2.08%; the BF16 GGUF matches at 2.08%. Every shipped quant stays within bootstrap noise (2.07-2.09%), so the quantization ladder is WER-neutral down to Q4_K_M. The model is multilingual (13 languages, auto-detect); the published WER is English only.
Usage
Build transcribe.cpp from source:
git clone git@github.com:handy-computer/transcribe.cpp.git
cd transcribe.cpp
cmake -B build && cmake --build build
Run on a 16 kHz mono WAV:
build/bin/transcribe-cli \
  -m Voxtral-Mini-4B-Realtime-2602-Q8_0.gguf \
  input.wav
If your audio isn't already 16 kHz mono WAV, convert it first:
ffmpeg -i input.mp3 -ar 16000 -ac 1 output.wav
See the transcribe.cpp model page for performance numbers, numerical validation, and reproduction steps.
License
Inherited from the base model: Apache-2.0. See the upstream model card for full terms.
Original Model Card
The section below is reproduced from mistralai/Voxtral-Mini-4B-Realtime-2602 at commit
2769294for offline reference. The upstream card is the authoritative source.
Voxtral Mini 4B Realtime 2602
Voxtral Mini 4B Realtime 2602 is a multilingual, realtime speech-transcription model and among the first open-source solutions to achieve accuracy comparable to offline systems with a delay of <500ms. It supports 13 languages and outperforms existing open-source baselines across a range of tasks, making it ideal for applications like voice assistants and live subtitling.
Built with a natively streaming architecture and a custom causal audio encoder - it allows configurable transcription delays (240ms to 2.4s), enabling users to balance latency and accuracy based on their needs. At a 480ms delay, it matches the performance of leading offline open-source transcription models, as well as realtime APIs.
As a 4B-parameter model, is optimized for on-device deployment, requiring minimal hardware resources. It runs in realtime with on devices minimal hardware with throughput exceeding 12.5 tokens/second.
This model is released in BF16 under the Apache-2 license, ensuring flexibility for both research and commercial use.
For more details, see our:
Key Features
Voxtral Mini 4B Realtime consists of two main architectural components:
- ≈3.4B Language Model
- ≈970M Audio Encoder
- The audio encoder was trained from scratch with causal attention enabling streaming capability
- Both the audio encoder as well as the LLM backbone use sliding window attention allowing for "infinite" streaming
- For more details, refer to the technical report
The Voxtral Mini 4B Realtime model offers the following capabilities:
- High-Quality Transcription: Transcribe audio to text with confidence.
- Multilingual: Supports dozens of languages, making it perfect for multilingual transcription tasks.
- Real-Time: Fast streaming ASR model, enabling real-time transcription use cases.
- Configurable Transcription Delays: Customize the transcription delay to balance quality and latency, from 80ms to 2.4s.
Use Cases
Real-Time Transcription Purposes:
- Private meeting transcriptions
- Live subtitle creation
- Real-time assistants with speech understanding
- And more
Bringing real-time transcription capabilities to all.
Recommended Settings
We recommend deploying with the following best practices:
- Always set the temperature to 0.0
- A single text-token is worth 80ms. Hence, make sure to set your
--max-model-lenaccordingly. To live-record a 1h meeting, you need to set--max-model-len >= 3600 / 0.8 = 45000. In theory, you should be able to record with no limit; in practice, pre-allocations of RoPE parameters among other things limits--max-model-len. For the best user experience, we recommend to simply instantiate vLLM with the default parameters which will automatically set a maximum model length of 131072 (~ca. 3h). - We strongly recommend using websockets to set up audio streaming sessions. For more info on how to do so, check Usage.
- We recommend using a delay of 480ms as we found it to be the sweet spot of performance and low latency. If, however, you want to adapt the delay, you can change the
"transcription_delay_ms": 480parameter in the tekken.json file to any multiple of 80ms between 80 and 1200, as well as 2400 as a standalone value.
Benchmark Results
We compare Voxtral Mini 4B Realtime to similar models - both offline models and realtime. Voxtral Mini 4B Realtime is competitive to leading offline models and shows significant gains over existing open-source realtime solutions.
Fleurs
| Model | Delay | AVG | Arabic | German | English | Spanish | French | Hindi | Italian | Dutch | Portuguese | Chinese | Japanese | Korean | Russian |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Voxtral Mini Transcribe 2.0 | Offline | 5.90% | 13.54% | 3.54% | 3.32% | 2.63% | 4.32% | 10.33% | 2.17% | 4.78% | 3.56% | 7.30% | 4.14% | 12.29% | 4.75% |
| Voxtral Mini 4B Realtime 2602 | 480 ms | 8.72% | 22.53% | 6.19% | 4.90% | 3.31% | 6.42% | 12.88% | 3.27% | 7.07% | 5.03% | 10.45% | 9.59% | 15.74% | 6.02% |
| 160 ms | 12.60% | 24.33% | 9.50% | 6.46% | 5.34% | 9.75% | 15.28% | 5.59% | 11.39% | 10.01% | 17.67% | 19.17% | 19.81% | 9.53% | |
| 240 ms | 10.80% | 23.95% | 8.15% | 5.91% | 4.59% | 8.00% | 14.26% | 4.41% | 9.23% | 7.51% | 13.84% | 15.17% | 17.56% | 7.87% | |
| 960 ms | 7.70% | 20.32% | 4.87% | 4.34% | 2.98% | 5.68% | 11.82% | 2.46% | 6.76% | 4.57% | 8.99% | 6.80% | 14.90% | 5.56% | |
| 2400 ms | 6.73% | 14.71% | 4.15% | 4.05% | 2.71% | 5.23% | 10.73% | 2.37% | 5.91% | 3.93% | 8.48% | 5.50% | 14.30% | 5.41% |
Long-form English
| Model | Delay | Meanwhile (<10m) | E-21 (<10m) | E-22 (<10m) | TEDLIUM (<20m) |
|---|---|---|---|---|---|
| Voxtral Mini Transcribe 2.0 | Offline | 4.08% | 9.81% | 11.69% | 2.86% |
| Voxtral Mini 4B Realtime 2602 | 480ms | 5.05% | 10.23% | 12.30% | 3.17% |
Short-form English
| Model | Delay | CHiME-4 | GigaSpeech 2k Subset | AMI IHM | SwitchBoard | CHiME-4 SP | GISpeech 2k Subset |
|---|---|---|---|---|---|---|---|
| Voxtral Mini Transcribe 2.0 | Offline | 10.39% | 6.81% | 14.43% | 11.54% | 10.42% | 1.74% |
| Voxtral Mini 4B Realtime 2602 | 480ms | 10.50% | 7.35% | 15.05% | 11.65% | 12.41% | 1.73% |
Usage
The model can also be deployed with the following libraries:
-
vllm (recommended): See here -
transformers: See here -
Community Contributions: See here
vLLM (recommended)
[!Tip] We've worked hand-in-hand with the vLLM team to have production-grade support for Voxtral Mini 4B Realtime 2602 with vLLM. Special thanks goes out to Joshua Deng, Yu Luo, Chen Zhang, Nick Hill, Nicolò Lucchesi, Roger Wang, and Cyrus Leung for the amazing work and help on building a production-ready audio streaming and realtime system in vLLM.
[!Warning] Due to its novel architecture, Voxtral Realtime is currently only support in vLLM. We very much welcome community contributions to add the architecture to Transformers and Llama.cpp.
We've worked hand-in-hand with the vLLM team to have production-grade support for Voxtral Mini 4B Realtime 2602 with vLLM. vLLM's new Realtime API is perfectly suited to run audio streaming sessions with the model.
Installation
Make sure to install vllm from the nightly pypi package. See here for a full installation guide.
uv pip install -U vllm
Doing so should automatically install mistral_common >= 1.9.0.
To check:
python -c "import mistral_common; print(mistral_common.__version__)"
You can also make use of a ready-to-go docker image or on the docker hub.
Make sure to also install all required audio processing libraries:
uv pip install soxr librosa soundfile
Also we recommend using Transformers v5 as v4 can clutter the terminal with unnecessary warnings (see here)
uv pip install --upgrade transformers
Serve
Due to size and the BF16 format of the weights - Voxtral-Mini-4B-Realtime-2602 can run on a single GPU with >= 16GB memory.
The model can be launched in both "eager" mode:
VLLM_DISABLE_COMPILE_CACHE=1 vllm serve mistralai/Voxtral-Mini-4B-Realtime-2602 --compilation_config '{"cudagraph_mode": "PIECEWISE"}'
Additional flags:
- You can set
--max-num-batched-tokensto balance throughput and latency, higher means higher throughput but higher latency. - You can reduce the default
--max-model-lento allocate less memory for the pre-computed RoPE frequencies, if you are certain that you won't have to transcribe for more than X hours. By default the model uses a--max-model-lenof 131072 (> 3h).
Client
After serving vllm, you should see that the model is compatible with vllm's new realtime endpoint:
...
(APIServer pid=3246965) INFO 02-03 17:04:43 [launcher.py:58] Route: /v1/realtime, Endpoint: realtime_endpoint
...
We have added two simple example files that allow you to:

To try out a demo, click here
Transformers
Starting with transformers >= 5.2.0, you can run Voxtral Realtime natively in Transformers!
For more details, refer to the Transformers documentation.
Installation
Install Transformers:
pip install --upgrade transformers
Make sure to have mistral-common installed with audio dependencies:
pip install --upgrade "mistral-common[audio]"
Usage
from transformers import VoxtralRealtimeForConditionalGeneration, AutoProcessor
from mistral_common.tokens.tokenizers.audio import Audio
from huggingface_hub import hf_hub_download

repo_id = "mistralai/Voxtral-Mini-4B-Realtime-2602"

processor = AutoProcessor.from_pretrained(repo_id)
model = VoxtralRealtimeForConditionalGeneration.from_pretrained(repo_id, device_map="auto")

repo_id = "patrickvonplaten/audio_samples"
audio_file = hf_hub_download(repo_id=repo_id, filename="bcn_weather.mp3", repo_type="dataset")

audio = Audio.from_file(audio_file, strict=False)
audio.resample(processor.feature_extractor.sampling_rate)

inputs = processor(audio.audio_array, return_tensors="pt")
inputs = inputs.to(model.device, dtype=model.dtype)

outputs = model.generate(**inputs)
decoded_outputs = processor.batch_decode(outputs, skip_special_tokens=True)

print(decoded_outputs[0])
ExecuTorch (Untested)
[!Warning] Running Voxtral-Realtime on-device with ExecuTorch is not throughly tested and hence there might be some sharp edges. If you encounter any problems, please file a bug report directly on ExecuTorch's GitHub
ExecuTorch enables you to deploy Voxtral-Realtime locally—either on-device or on your laptop.
For a quick, offline demo on your MacBook, check out Voxtral-Mini-4B-Realtime-2602-ExecuTorch.
To deploy Voxtral-Realtime in a custom environment or on any device, refer to the Official Readme.
[!Tip] If you're looking for an implementation that is purely written in C, we recommend to take a look at voxtral.c
Community Contributions (Untested)
Voxtral Realtime integrations in:
- Pure C - thanks Salvatore Sanfilippo
- mlx-audio framework - thanks Shreyas Karnik
- MLX - thanks Awni Hannun
- Rust - thanks TrevorS
License
This model is licensed under the Apache 2.0 License.
You must not use this model in a manner that infringes, misappropriates, or otherwise violates any third party’s rights, including intellectual property rights.