Description
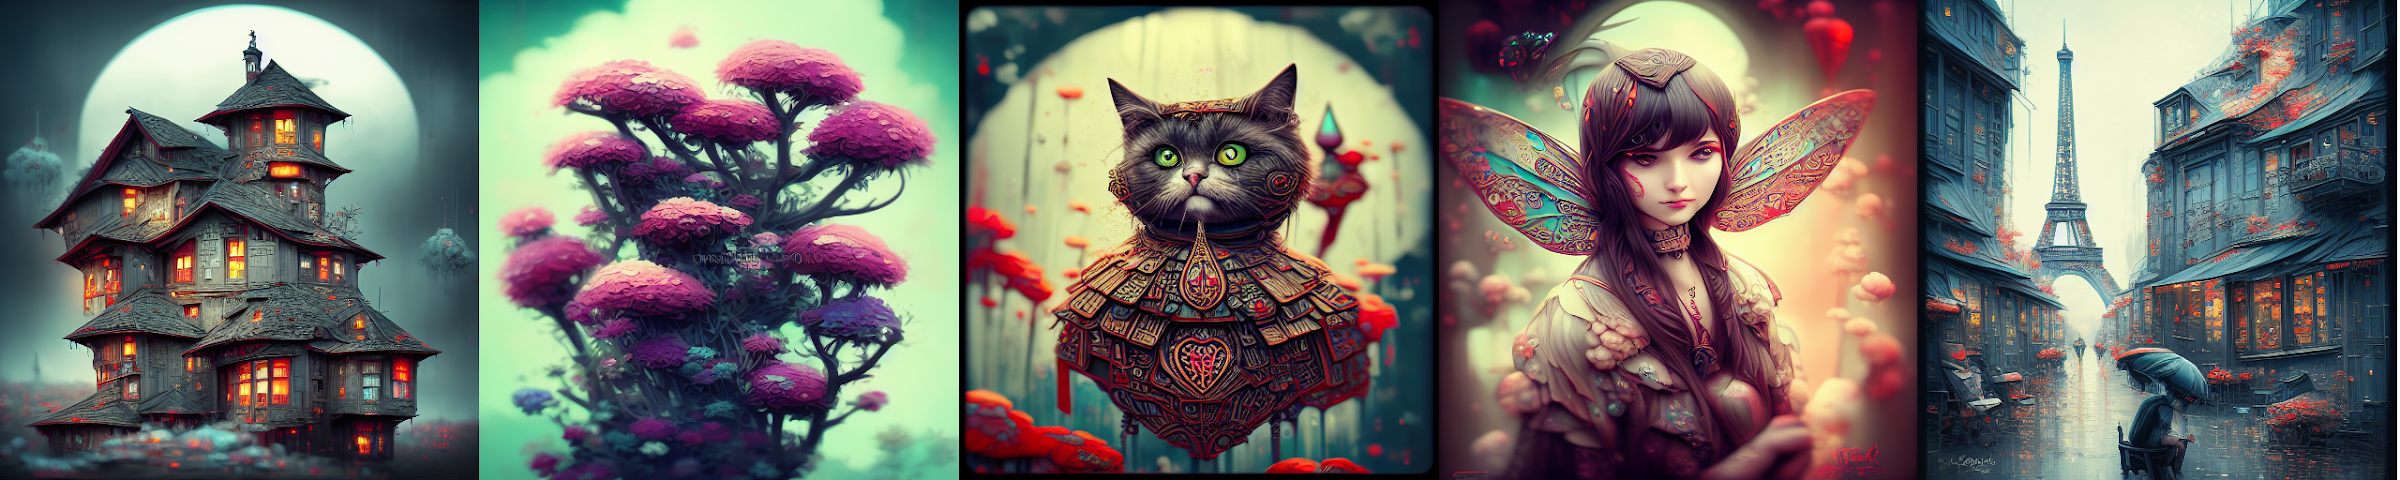
Gigafractal Diffusion is a latent text-to-image diffusion model based on the original CompVis Stable Diffusion v1.5 and then fine-tuned on 40 images origanally made with another diffusion model named 'Disco Diffusion' using Dreambooth. This model has been created to explore the possibilities and limitations of Dreambooth training with training steps increased much more than usual and to overcome biases in the model created by the text incoder's token associations. The purpose of this model is to provide the biomorphic fractalism effect present in Disco Diffusion, but without the bias to 'Disco parties' and especially 'discoballs' for which [the model by snek](was known for).
To use this style in your generations, add gigafractal artstyle to the prompts.
Dreambooth hyperparameters
python main.py --base configs/stable-diffusion/v1-finetune_unfrozen.yaml \
                -t \
                --actual_resume /home/{USERNAME}/kml/stable-diffusion-webui/models/Stable-diffusion/v1-5-pruned.ckpt \
                -n dscdif \
                --gpus 0, \
                --data_root /home/{USERNAME}/kml/datasets/styles/dscdif \
                --reg_data_root /home/{USERNAME}/kml/datasets/styles/dscdif1 \
                --class_word biomorphic \
                --no-test \
                --max_steps 2040
The regularization dataset of 200 AI-generated images had been produced in AUTOMATIC1111's webui with the following prompt which may have had a positive effect on the resulting quality.
a computer generated image of a spiral like object, digital art, polycount, generative art, (fractalism:0.7), lovecraftian, intricate, detailed matte painting, high detail, ornate, cgsociety, psychedelic art, gothic art, artstation hq, colorful, complex, biopunk, 8k, maxmialist Negative prompt: bad quality, text, cropped, worst quality, low quality, normal quality, jpeg artifacts,signature, watermark, username, blurry, artist name, flat, out of focus Steps: 20, Sampler: Euler a, CFG scale: 12.5, Seed: 2042420948, Size: 512x512, Model hash: a9263745
Model Description
The model originally used for fine-tuning is Stable Diffusion V1-5, which is a latent image diffusion model trained on LAION2B-en.
The current model has been fine-tuned with a learning rate of 1.0e-6 for 2040 steps using Dreambooth on Disco Diffusion produced images.
License
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage. The CreativeML OpenRAIL License specifies:
You can't use the model to deliberately produce nor share illegal or harmful outputs or content The authors claims no rights on the outputs you generate, you are free to use them and are accountable for their use which must not go against the provisions set in the license You may re-distribute the weights and use the model commercially and/or as a service. If you do, please be aware you have to include the same use restrictions as the ones in the license and share a copy of the CreativeML OpenRAIL-M to all your users (please read the license entirely and carefully)
Please read the full license here
Downstream Uses
This model can be used for entertainment purposes and as a generative art assistant.
Acknowledgements
Inspired by snek's work on https://huggingface.co/SDAddictsAnon/Snek/blob/main/arrow_disco_artstyle.ckpt.
This project would not have been possible without the incredible work by the CompVis Researchers, Disco Diffusion, Deforum devs and all the artists who made the content for training even if they were an AI.
The dataset for training currently resides here https://drive.google.com/drive/folders/1v-uW2ESlQRFe17tnWZ7_CtjadD9swfIG?usp=share_link. The author is grateful to snek for the provided dataset.
Subjective opinion: the quality of the output images is comparable to that of another text2image generator, Midjourney. You can see some examples of Gigafractal Diffusion produced images at https://drive.google.com/drive/folders/1qmaGZMvFlFsO9e4EzUCnz6ijAUtf1qbP?usp=sharing.