AshhLimaRP-Mistral-7B (Alpaca, v1)
This is a version of LimaRP with 2000 training samples up to about 9k tokens length finetuned on Ashhwriter-Mistral-7B.
LimaRP is a longform-oriented, novel-style roleplaying chat model intended to replicate the experience of 1-on-1 roleplay on Internet forums. Short-form, IRC/Discord-style RP (aka "Markdown format") is not supported. The model does not include instruction tuning, only manually picked and slightly edited RP conversations with persona and scenario data.
Ashhwriter, the base, is a model entirely finetuned on human-written lewd stories.
Available versions
- Float16 HF weights
- LoRA Adapter (adapter_config.json and adapter_model.bin)
- 4bit AWQ
- Q4_K_M GGUF
- Q6_K GGUF
Prompt format
Extended Alpaca format,
with ### Instruction:, ### Input: immediately preceding user inputs and ### Response:
immediately preceding model outputs. While Alpaca wasn't originally intended for multi-turn
responses, in practice this is not a problem; the format follows a pattern already used by
other models.
### Instruction:
Character's Persona: {bot character description}

User's Persona: {user character description}

Scenario: {what happens in the story}

Play the role of Character. You must engage in a roleplaying chat with User below this line. Do not write dialogues and narration for User.

### Input:
User: {utterance}

### Response:
Character: {utterance}

### Input
User: {utterance}

### Response:
Character: {utterance}

(etc.)
You should:
- Replace all text in curly braces (curly braces included) with your own text.
- Replace
UserandCharacterwith appropriate names.
Message length control
Inspired by the previously named "Roleplay" preset in SillyTavern, with this version of LimaRP it is possible to append a length modifier to the response instruction sequence, like this:
### Input
User: {utterance}

### Response: (length = medium)
Character: {utterance}
This has an immediately noticeable effect on bot responses. The lengths using during training are:
micro, tiny, short, medium, long, massive, huge, enormous, humongous, unlimited.
The recommended starting length is medium. Keep in mind that the AI can ramble or impersonate
the user with very long messages.
The length control effect is reproducible, but the messages will not necessarily follow lengths very precisely, rather follow certain ranges on average, as seen in this table with data from tests made with one reply at the beginning of the conversation:

Response length control appears to work well also deep into the conversation. By omitting the modifier, the model will choose the most appropriate response length (although it might not necessarily be what the user desires).
Suggested settings
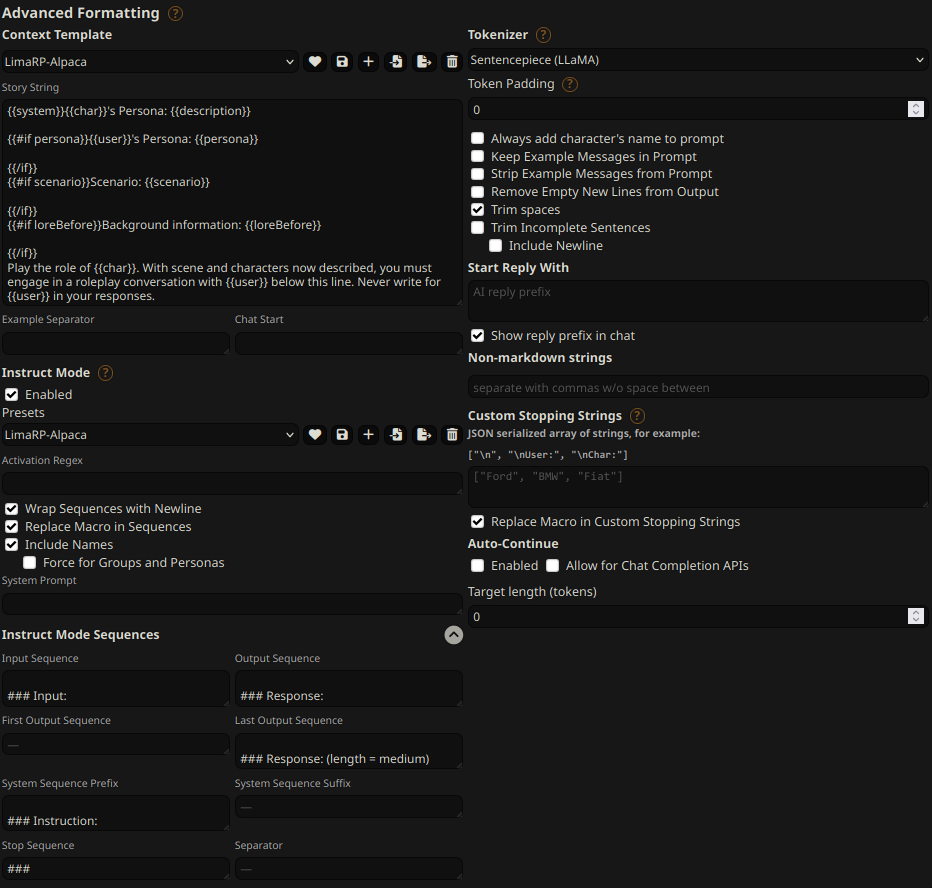
You can follow these instruction format settings in SillyTavern. Replace medium with
your desired response length:
Text generation settings
These settings could be a good general starting point:
- TFS = 0.90
- Temperature = 0.70
- Repetition penalty = ~1.11
- Repetition penalty range = ~2048
- top-k = 0 (disabled)
- top-p = 1 (disabled)
Training procedure
Axolotl was used for training on 2x NVidia A40 GPUs.
The A40 GPUs have been graciously provided by Arc Compute.
Training hyperparameters
A lower learning rate than usual was employed. Due to an unforeseen issue the training was cut short and as a result 3 epochs were trained instead of the planned 4. Using 2 GPUs, the effective global batch size would have been 16.
Training was continued from the most recent LoRA adapter from Ashhwriter, using the same LoRA R and LoRA alpha.
- lora_model_dir: /home/anon/bin/axolotl/OUT_mistral-stories/checkpoint-6000/
- learning_rate: 0.00005
- lr_scheduler: cosine
- noisy_embedding_alpha: 3.5
- num_epochs: 4
- sequence_len: 8750
- lora_r: 256
- lora_alpha: 16
- lora_dropout: 0.05
- lora_target_linear: True
- bf16: True
- fp16: false
- tf32: True
- load_in_8bit: True
- adapter: lora
- micro_batch_size: 2
- optimizer: adamw_bnb_8bit
- warmup_steps: 10
- optimizer: adamw_torch
- flash_attention: true
- sample_packing: true
- pad_to_sequence_len: true
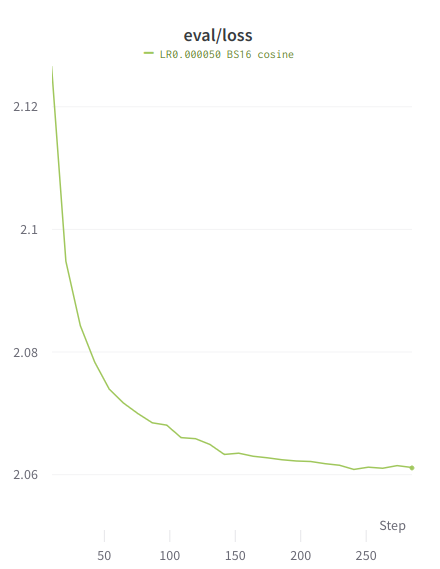
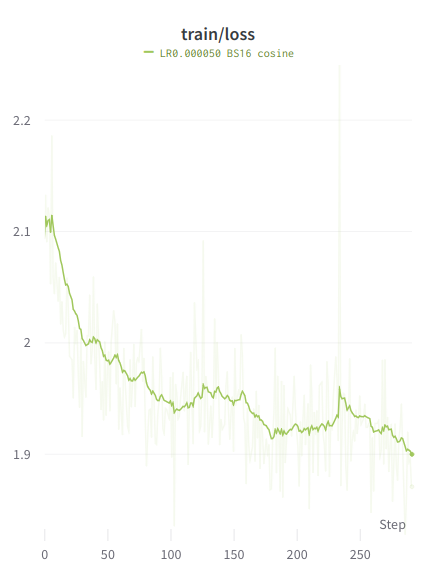
Loss graphs
Values are higher than typical because the training is performed on the entire sample, similar to unsupervised finetuning.
Train loss
Eval loss