Conditional DETR model with ResNet-50 backbone
Conditional DEtection TRansformer (DETR) model trained end-to-end on COCO 2017 object detection (118k annotated images). It was introduced in the paper Conditional DETR for Fast Training Convergence by Meng et al. and first released in this repository.
Model description
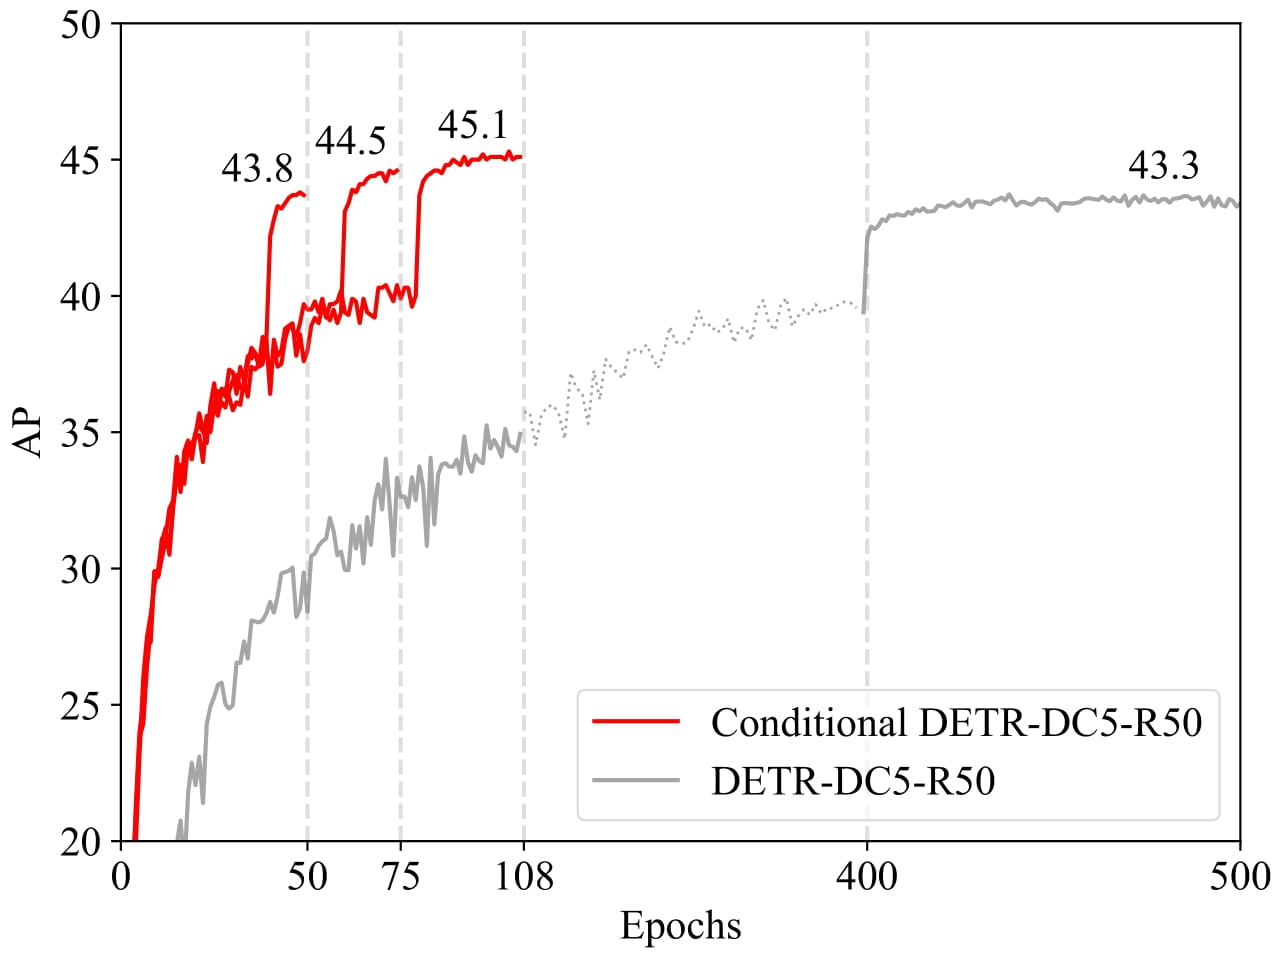
The recently-developed DETR approach applies the transformer encoder and decoder architecture to object detection and achieves promising performance. In this paper, we handle the critical issue, slow training convergence, and present a conditional cross-attention mechanism for fast DETR training. Our approach is motivated by that the cross-attention in DETR relies highly on the content embeddings for localizing the four extremities and predicting the box, which increases the need for high-quality content embeddings and thus the training difficulty. Our approach, named conditional DETR, learns a conditional spatial query from the decoder embedding for decoder multi-head cross-attention. The benefit is that through the conditional spatial query, each cross-attention head is able to attend to a band containing a distinct region, e.g., one object extremity or a region inside the object box. This narrows down the spatial range for localizing the distinct regions for object classification and box regression, thus relaxing the dependence on the content embeddings and easing the training. Empirical results show that conditional DETR converges 6.7× faster for the backbones R50 and R101 and 10× faster for stronger backbones DC5-R50 and DC5-R101.
Intended uses & limitations
You can use the raw model for object detection. See the model hub to look for all available Conditional DETR models.
How to use
Here is how to use this model:
from transformers import AutoImageProcessor, ConditionalDetrForObjectDetection
import torch
from PIL import Image
import requests

url = "http://images.cocodataset.org/val2017/000000039769.jpg"
image = Image.open(requests.get(url, stream=True).raw)

processor = AutoImageProcessor.from_pretrained("microsoft/conditional-detr-resnet-50")
model = ConditionalDetrForObjectDetection.from_pretrained("microsoft/conditional-detr-resnet-50")

inputs = processor(images=image, return_tensors="pt")
outputs = model(**inputs)

# convert outputs (bounding boxes and class logits) to COCO API
# let's only keep detections with score > 0.7
target_sizes = torch.tensor([image.size[::-1]])
results = processor.post_process_object_detection(outputs, target_sizes=target_sizes, threshold=0.7)[0]

for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
    box = [round(i, 2) for i in box.tolist()]
    print(
            f"Detected {model.config.id2label[label.item()]} with confidence "
            f"{round(score.item(), 3)} at location {box}"
    )
This should output:
Detected remote with confidence 0.833 at location [38.31, 72.1, 177.63, 118.45]
Detected cat with confidence 0.831 at location [9.2, 51.38, 321.13, 469.0]
Detected cat with confidence 0.804 at location [340.3, 16.85, 642.93, 370.95]
Currently, both the feature extractor and model support PyTorch.
Training data
The Conditional DETR model was trained on COCO 2017 object detection, a dataset consisting of 118k/5k annotated images for training/validation respectively.
BibTeX entry and citation info
@inproceedings{MengCFZLYS021,
  author    = {Depu Meng and
               Xiaokang Chen and
               Zejia Fan and
               Gang Zeng and
               Houqiang Li and
               Yuhui Yuan and
               Lei Sun and
               Jingdong Wang},
  title     = {Conditional {DETR} for Fast Training Convergence},
  booktitle = {2021 {IEEE/CVF} International Conference on Computer Vision, {ICCV}
               2021, Montreal, QC, Canada, October 10-17, 2021},
}