


WebJudge
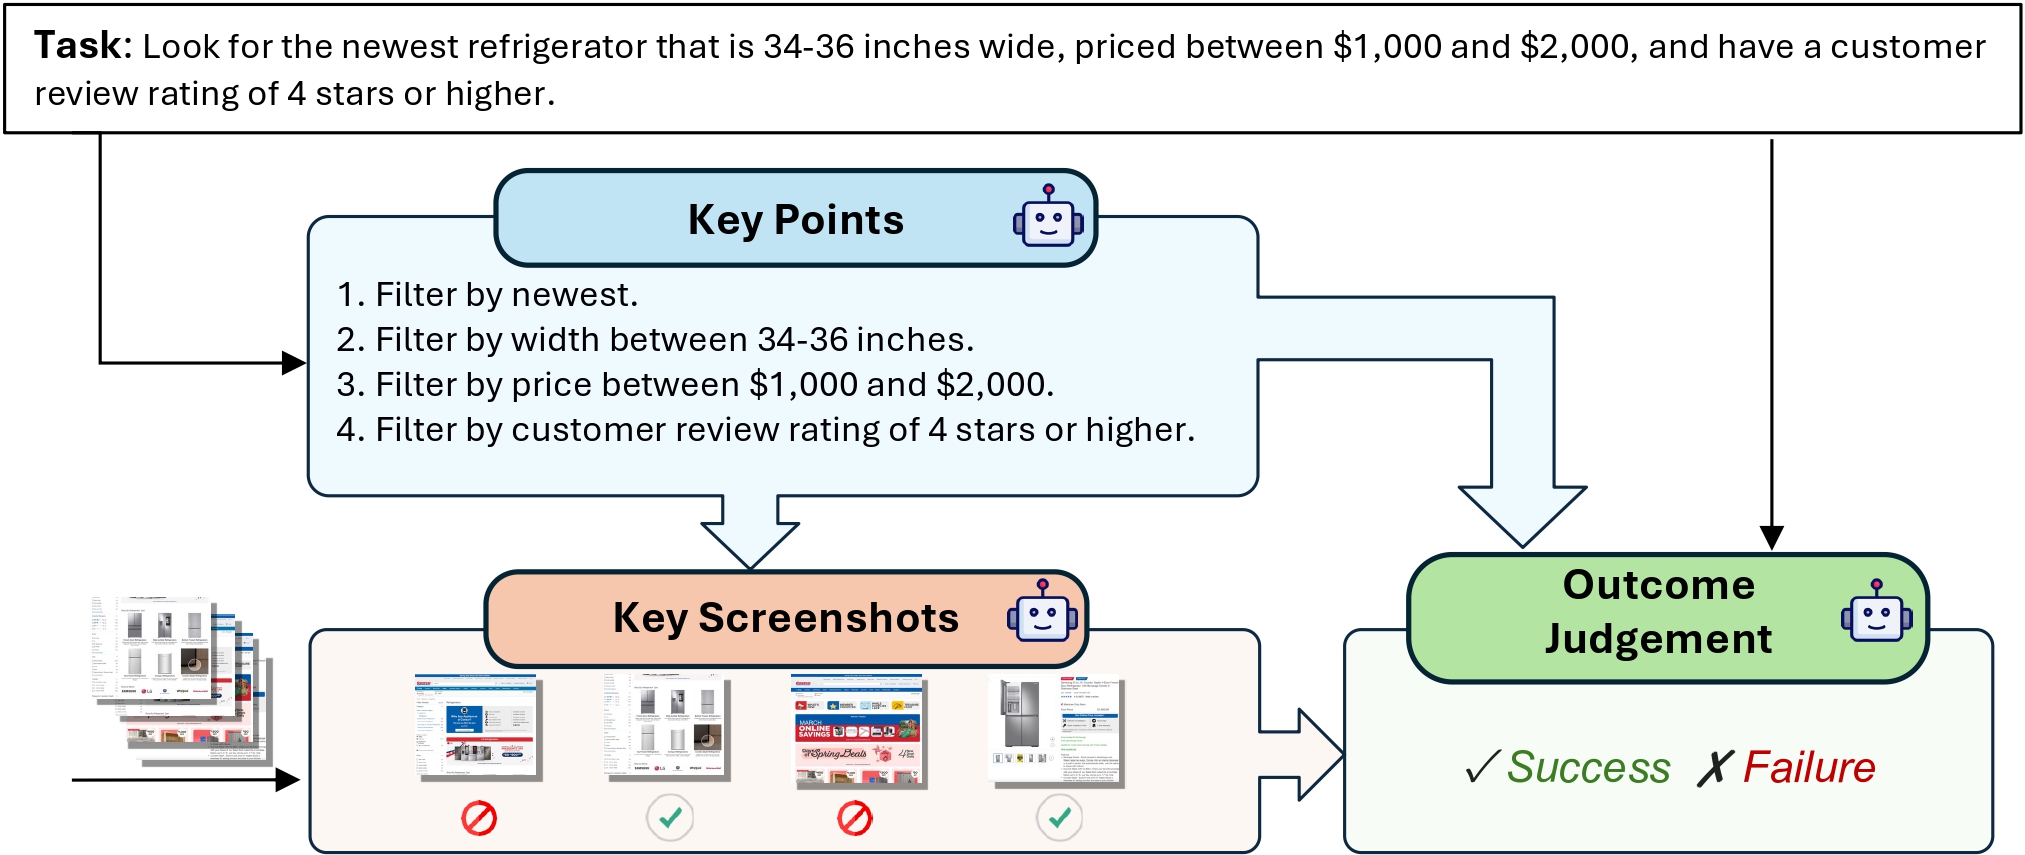
WebJudge preserves critical intermediate screenshots while mitigating the token overload issue, resulting in more accurate and reliable evaluations. Please check our paper for more details.
- Repository
- 📃 Paper
- 🏆 Leaderboard
- 🤗 Data
- Model
Results
Comparison against Existing Evaluation Methods on Online-Mind2Web
Excellent generalization capabilities on AgentRewardBench (5 OOD benchmarks)
| Methods | AB | VWA | WA | Work | Wk++ | Overall |
|---|---|---|---|---|---|---|
| Rule-based* | 25.0 | 85.2 | 79.0 | 100.0 | 83.3 | 83.8 |
| Autonomous Eval* | 83.3 | 61.2 | 67.6 | 96.4 | 59.3 | 67.6 |
| GPT-4o (A11y Tree)* | 77.8 | 63.0 | 70.2 | 94.6 | 63.0 | 69.8 |
| WebJudge (GPT-4o) | 66.7 | 69.8 | 72.6 | 92.3 | 75.0 | 73.7 |
| WebJudge-7B | 80.0 | 66.7 | 77.5 | 100.0 | 70.0 | 75.7 |
| WebJudge (o4-mini) | 100.0 | 74.5 | 81.2 | 100.0 | 90.0 | 82.0 |
WebJudge significantly outperforms existing methods, achieving impressive overall precision of 73.7% 75.7% and 82.0% on WebArena (WA), VisualWebArena (VWA), AssistantBench (AB), WorkArena (Work) and WorkArena++ (Wk++) across 1302 trajectories.
The high precision suggests that WebJudge holds potential as a robust and scalable reward model for downstream applications such as Rejection Sampling Fine-Tuning, Reflection, and Reinforcement Learning.
Inference
vLLM server
vllm serve osunlp/WebJudge-7B --port PORT --api-key API_KEY
or
LLaMA-Factory API
API_PORT=PORT llamafactory-cli api examples/inference/qwen2_vl.yaml
Prompt
Please check our Repository and Paper for more details about prompt.
text = """**Task**: {task}

**Key Points for Task Completion**: {key_points}

The snapshot of the web page is shown in the image."""

messages = [
                {"role": "system", "content": system_msg},
                {
                    "role": "user",
                    "content": [
                        {"type": "text", "text": text},
                        {
                            "type": "image_url",
                            "image_url": {"url": f"data:image/jpeg;base64,{jpg_base64_image}", "detail": "high"},
                        },
                    ],
                }
            ]
completion = client.chat.completions.create(
    model=model_path,
    messages=messages,
    temperature=0
)
Citation Information
Note: Online-Mind2Web is derived from the original Mind2Web dataset. We kindly ask that you cite both the original and this work when using or referencing the data.
@article{xue2025illusionprogressassessingcurrent,
      title={An Illusion of Progress? Assessing the Current State of Web Agents},
      author={Tianci Xue and Weijian Qi and Tianneng Shi and Chan Hee Song and Boyu Gou and Dawn Song and Huan Sun and Yu Su},
      year={2025},
      eprint={2504.01382},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2504.01382},
}

@inproceedings{deng2023mind2web,
 author = {Deng, Xiang and Gu, Yu and Zheng, Boyuan and Chen, Shijie and Stevens, Sam and Wang, Boshi and Sun, Huan and Su, Yu},
 booktitle = {Advances in Neural Information Processing Systems},
 editor = {A. Oh and T. Naumann and A. Globerson and K. Saenko and M. Hardt and S. Levine},
 pages = {28091--28114},
 publisher = {Curran Associates, Inc.},
 title = {Mind2Web: Towards a Generalist Agent for the Web},
 url = {https://proceedings.neurips.cc/paper_files/paper/2023/file/5950bf290a1570ea401bf98882128160-Paper-Datasets_and_Benchmarks.pdf},
 volume = {36},
 year = {2023}
}