Typhoon-S-ThaiLLM-8B-Instruct 🇹🇭 (Research Preview)
Typhoon-S-ThaiLLM-8B-Instruct 🇹🇭 is a "Sovereign", instruction-tuned Thai large language model based on ThaiLLM focusing on openness and reproducibility with the training dataset, training code, and technical report all fully open here.
This work represents an early effort to democratize post-training from base models for sovereign AI. Due to the growing complexity of modern post-training pipelines used by large labs (e.g., DeepSeek, Qwen, Google, Nvidia), building high-quality sovereign instruction-tuned models has become increasingly difficult without leveraging proprietary instruction models. This reliance reduces the effectiveness of sovereign base-model adaptation techniques—such as continual pretraining—because instruction-following capabilities learned during post-training are often lost due to catastrophic forgetting.
This project builds upon the sovereign-tuned base model ThaiLLM and applies post-training methods such as:
- Supervised Fine-Tuning (SFT)
- On-policy distillation (OPD)
All of this is accomplished with only an academic budget—equivalent to two days on a single H100 node.
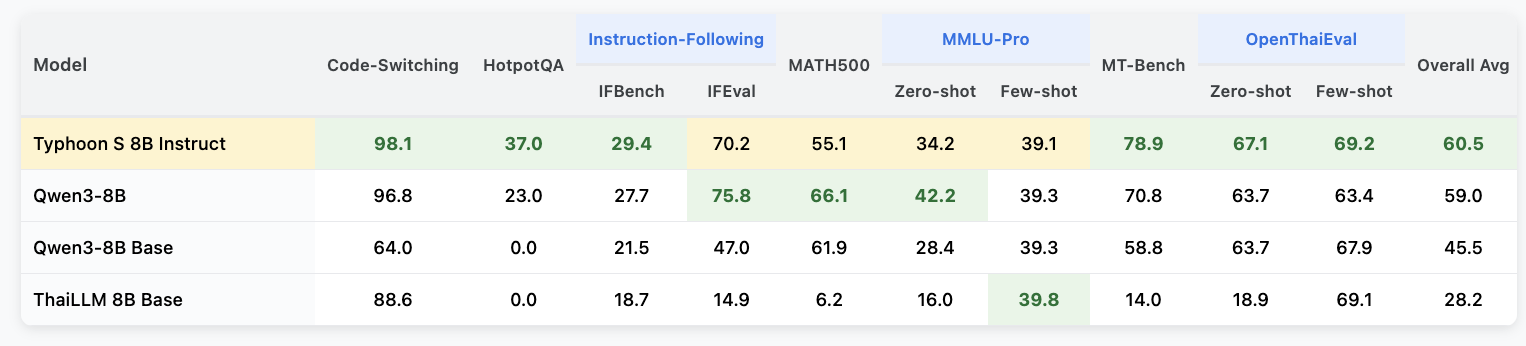
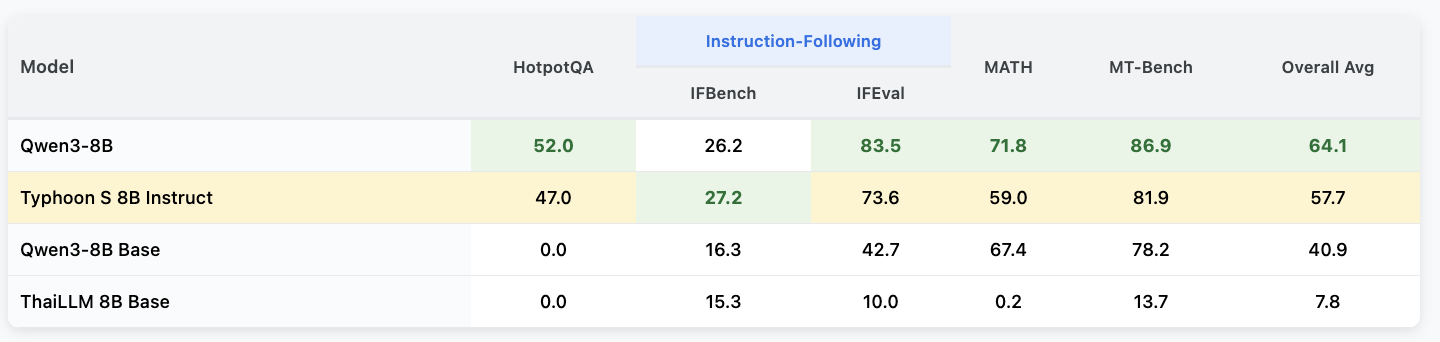
The overarching goal is to demonstrate that it is possible to build a competitive instruction model—on par with leading globally tuned models like Qwen3-8B—while maintaining strong performance advantages in local languages.
For more information, please read the full technical report on arXiv.
Performance
Thai performance
English performance
Model Description
- Model type: A 8B instruct decoder-only model based on Qwen3 architecture and ThaiLLM base model.
- Requirement: transformers 4.57.0 or newer.
- Primary Language(s): Thai 🇹🇭 and English 🇬🇧
- Context Length: 32K
- License: Apache 2.0 License
Usage Example
This code snippet shows how to use the Typhoon model for Thai or English text generation using the transformers library. It includes setting up the model and tokenizer, formatting chat messages in a system-user style, and generating a response.
from transformers import AutoTokenizer, AutoModelForCausalLM
import torch

model_id = "typhoon-ai/typhoon-s-thaillm-8b-instruct-research-preview"

tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)

messages = [
    {"role": "system", "content": "You are a male AI assistant named Typhoon created by SCB 10X to be helpful, harmless, and honest. Typhoon is happy to help with analysis, question answering, math, coding, creative writing, teaching, role-play, general discussion, and all sorts of other tasks. Typhoon responds directly to all human messages without unnecessary affirmations or filler phrases like “Certainly!”, “Of course!”, “Absolutely!”, “Great!”, “Sure!”, etc. Specifically, Typhoon avoids starting responses with the word “Certainly” in any way. Typhoon follows this information in all languages, and always responds to the user in the language they use or request. Typhoon is now being connected with a human. Write in fluid, conversational prose, Show genuine interest in understanding requests, Express appropriate emotions and empathy. Also showing information in term that is easy to understand and visualized."},
    {"role": "user", "content": "ขอสูตรไก่ย่าง"},
]

input_ids = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt",
).to(model.device)

outputs = model.generate(
    input_ids,
    max_new_tokens=512,
    do_sample=True,
    temperature=0.4,
    top_p=0.95,
    repetition_penalty=1.05,
)
response = outputs[0][input_ids.shape[-1]:]
print(tokenizer.decode(response, skip_special_tokens=True))
Deploy as Server
This section shows how to run Typhoon as an OpenAI-compatible API server using vllm.
pip install vllm
vllm serve typhoon-ai/typhoon-s-thaillm-8b-instruct-research-preview --max-model-len 8192 --tool-call-parser hermes --enable-auto-tool-choice --gpu-memory-utilization 0.95
# adjust --max-model-len based on your avaliable memory
Using Tools
You can provide tools to the vLLM-powered OpenAI-compatible API for functionality.
from openai import OpenAI
import json

client = OpenAI(base_url="http://localhost:8000/v1", api_key="dummy")

def get_weather(location: str, unit: str):
    return f"Getting the weather for {location} in {unit}..."

tool_functions = {"get_weather": get_weather}

tools = [{
    "type": "function",
    "function": {
        "name": "get_weather",
        "description": "Get the current weather in a given location",
        "parameters": {
            "type": "object",
            "properties": {
                "location": {"type": "string", "description": "City and state, e.g., 'San Francisco, CA'"},
                "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}
            },
            "required": ["location", "unit"]
        }
    }
}]

response = client.chat.completions.create(
    model=client.models.list().data[0].id,
    messages=[{"role": "user", "content": "What's the weather like in San Francisco?"}],
    tools=tools,
    tool_choice="auto",
    extra_body={
      "repetition_penalty": 1.05
    }
)

tool_call = response.choices[0].message.tool_calls[0].function
print(f"Function called: {tool_call.name}")
print(f"Arguments: {tool_call.arguments}")
print(f"Result: {get_weather(**json.loads(tool_call.arguments))}")
Sampling Parameters
For this model, we encourage you to use a low "temperature" eg.(0.4) and set "repetition_penalty" = 1.05 to improve performance and reduce repetition.
Intended Uses & Limitations
This model is an instructional model. However, it’s still undergoing development. It incorporates some level of guardrails, but it still may produce answers that are inaccurate, biased, or otherwise objectionable in response to user prompts. We recommend that developers assess these risks in the context of their use case.
Follow us
https://twitter.com/opentyphoon
Support
Citation
- If you find Typhoon-S useful for your work, please cite it using:
@misc{pipatanakul2026typhoonsminimalopenposttraining,
      title={Typhoon-S: Minimal Open Post-Training for Sovereign Large Language Models},
      author={Kunat Pipatanakul and Pittawat Taveekitworachai},
      year={2026},
      eprint={2601.18129},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.18129},
}