Typhoon2.1-Gemma3-4B: Thai Large Language Model (Instruct)
Typhoon2.1-Gemma3-4B is a instruct Thai 🇹🇭 large language model with 4 billion parameters, a 128K context length, and function-calling capabilities. It is based on Gemma3 4B.
By using this model, you agree to the OpenTyphoon Terms and Conditions and acknowledge the Privacy Notice: https://opentyphoon.ai/tac · https://opentyphoon.ai/privacy
Remark: This is text only model. We removed vision encoder for this version due to complexity. Stay-tune for version with vision encoder soon.
Performance
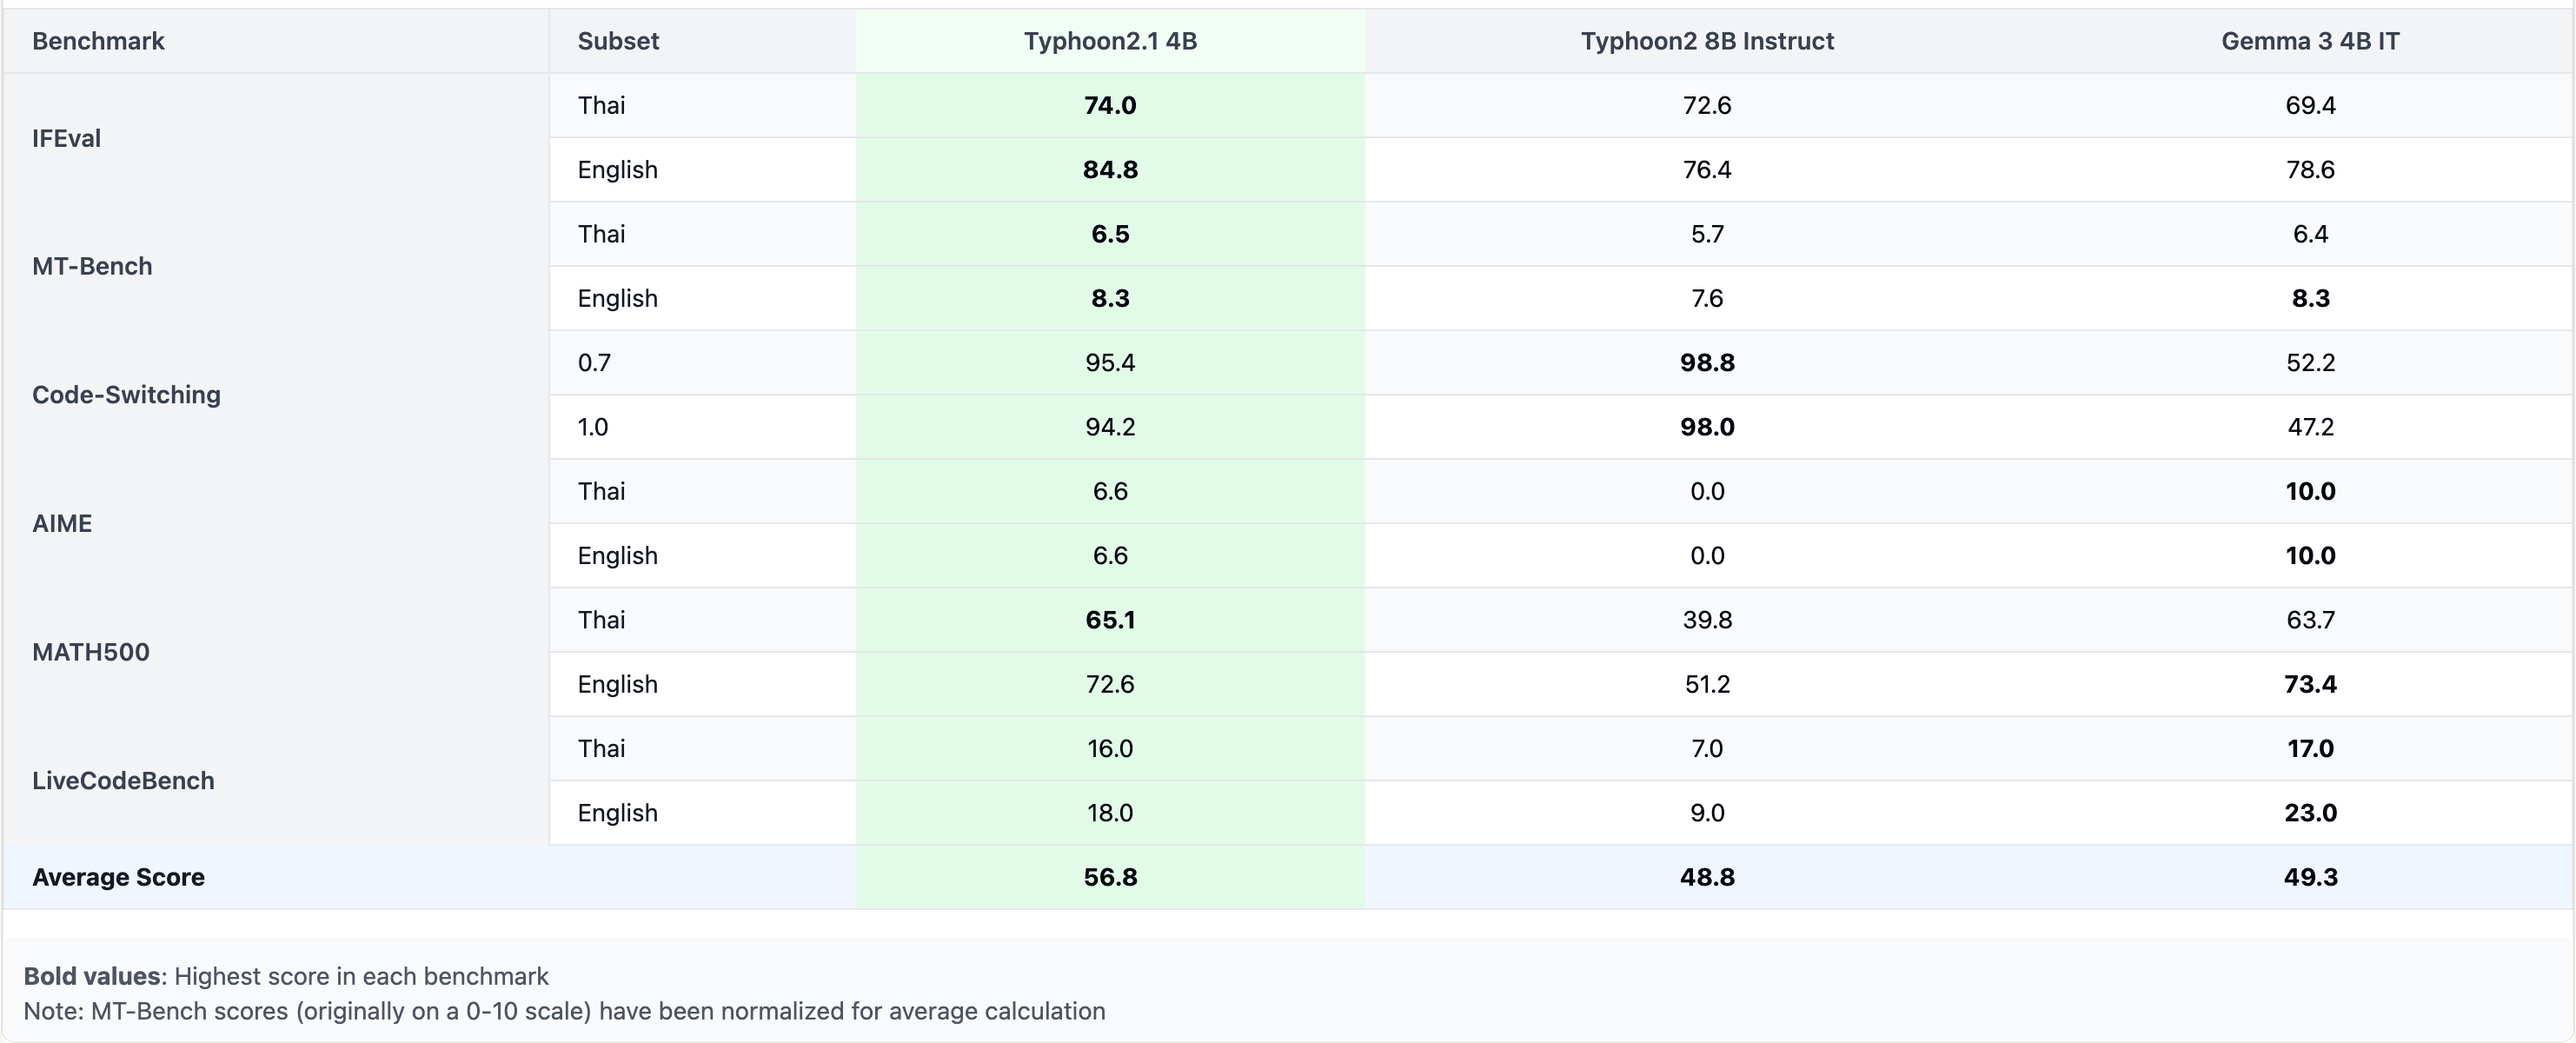
Model Description
- Model type: A 4B instruct decoder-only model based on Gemma3 architecture.
- Requirement: transformers 4.50.0 or newer.
- Primary Language(s): Thai 🇹🇭 and English 🇬🇧
- License: Gemma License
Usage Example
This code snippet shows how to use the Typhoon2.1-Gemma3-4B model for Thai or English text generation using the transformers library. It includes setting up the model and tokenizer, formatting chat messages in a system-user style, and generating a response.
from transformers import AutoTokenizer, AutoModelForCausalLM
import torch

model_id = "scb10x/typhoon2.1-gemma3-4b"

tokenizer = AutoTokenizer.from_pretrained(model_id)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)

messages = [
    {"role": "system", "content": "You are a male AI assistant named Typhoon created by SCB 10X to be helpful, harmless, and honest. Typhoon is happy to help with analysis, question answering, math, coding, creative writing, teaching, role-play, general discussion, and all sorts of other tasks. Typhoon responds directly to all human messages without unnecessary affirmations or filler phrases like “Certainly!”, “Of course!”, “Absolutely!”, “Great!”, “Sure!”, etc. Specifically, Typhoon avoids starting responses with the word “Certainly” in any way. Typhoon follows this information in all languages, and always responds to the user in the language they use or request. Typhoon is now being connected with a human. Write in fluid, conversational prose, Show genuine interest in understanding requests, Express appropriate emotions and empathy. Also showing information in term that is easy to understand and visualized."},
    {"role": "user", "content": "ขอสูตรไก่ย่าง"},
]

input_ids = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt",
    enable_thinking=False # Switches between thinking and non-thinking modes. Default is False.
).to(model.device)

outputs = model.generate(
    input_ids,
    max_new_tokens=512,
    do_sample=True,
    temperature=0.6,
    top_p=0.95,
)
response = outputs[0][input_ids.shape[-1]:]
print(tokenizer.decode(response, skip_special_tokens=True))
Deploy as Server
This section shows how to run Typhoon2.1 as an OpenAI-compatible API server using vllm.
pip install vllm
vllm serve scb10x/typhoon2.1-gemma3-4b --max-model-len 16000 --dtype bfloat16 --tool-call-parser pythonic --enable-auto-tool-choice
# adjust --max-model-len based on your avaliable memory
# you can use --quantization bitsandbytes to reduce the memory use while trade-off inference speed
Using Tools
You can provide tools to the vLLM-powered OpenAI-compatible API for functionality.
from openai import OpenAI
import json

client = OpenAI(base_url="http://localhost:8000/v1", api_key="dummy")

def get_weather(location: str, unit: str):
    return f"Getting the weather for {location} in {unit}..."
tool_functions = {"get_weather": get_weather}

tools = [{
    "type": "function",
    "function": {
        "name": "get_weather",
        "description": "Get the current weather in a given location",
        "parameters": {
            "type": "object",
            "properties": {
                "location": {"type": "string", "description": "City and state, e.g., 'San Francisco, CA'"},
                "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}
            },
            "required": ["location", "unit"]
        }
    }
}]

response = client.chat.completions.create(
    model=client.models.list().data[0].id,
    messages=[{"role": "user", "content": "What's the weather like in San Francisco?"}],
    tools=tools,
    tool_choice="auto"
)

tool_call = response.choices[0].message.tool_calls[0].function
print(f"Function called: {tool_call.name}")
print(f"Arguments: {tool_call.arguments}")
print(f"Result: {get_weather(**json.loads(tool_call.arguments))}")
Switching Between Thinking and Non-Thinking Mode
Typhoon supports two modes: Non-thinking mode (default): Fast response generation without extra reasoning steps. Thinking mode: The model first reasons internally, then provides a clearer and potentially more accurate final answer. You can enable thinking mode by: Setting enable_thinking=True in apply_chat_template. Using a special system prompt that instructs the model to reason inside ... tags.
You can turn on thinking mode by either
- add enable_thinking=True to apply_chat_template
input_ids = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt",
    enable_thinking=True # Switches between thinking and non-thinking modes. Default is False.
).to(model.device)
- manually by supply thinking mode system prompt
You are a helpful assistant. First, think through the reasoning internally, then present the reasoning within <think>...</think>. After thinking, clearly state a response that addresses the user's request and aligns with their preferences, not just providing a direct answer.
- in vllm powered openai compatible client you can add chat_template_kwargs to the post payload
{
  "model": "scb10x/typhoon2.1-gemma3-4b",
  "messages": [
    {"role": "user", "content": "Give me a short introduction to large language models."}
  ],
  "chat_template_kwargs": {"enable_thinking": true}
}
Budget forcing
This section introduces budget forcing, an advanced technique to let the model spend more time and tokens reasoning before producing a final answer—great for improving performance on complex questions.
from vllm import LLM, SamplingParams
from transformers import AutoTokenizer
class BudgetForcingHandler:

    def __init__(self, model_name: str, max_think_token: int, max_ignore=5, temperature=0.6, seed=32):
        self.temperature = temperature
        self.seed = seed
        self.max_think_token = max_think_token
        self.max_ignore = max_ignore
        self.model = LLM(model_name, dtype='bfloat16', enforce_eager=True)
        self.tokenizer = AutoTokenizer.from_pretrained(model_name)
        self.alternative_str = '\nAlternatively'
        self.system = """You are a reasoning assistant. First, think through the reasoning internally, then present the reasoning within <think>...</think>. After thinking, clearly state the final answer."""

    def __call__(self, prompts: List[str]):
        count_prompt = len(prompts)
        prompts = [self.tokenizer.apply_chat_template([{'role': 'system', 'content': self.system}, {'role': 'user', 'content': f'Please solve this math question, and put your final answer within \\boxed{{}}.\n{p}'}], add_generation_prompt=True, tokenize=False) for p in prompts]
        sampling_params = SamplingParams(
            max_tokens=self.max_think_token,
            seed=self.seed,
            stop=["</think>"],
            skip_special_tokens=False,
            temperature=self.temperature,
        )
        o = self.model.generate(
            prompts,
            sampling_params=sampling_params
        )

        outputs = [output.outputs[0].text for output in o]
        token_count = [len(output.outputs[0].token_ids) for output in o]
        for i in range(len(prompts)):
            prompts[i] = prompts[i] + outputs[i]

        for _ in range(self.max_ignore): # Num of times to skip stop token
            inference_loop_prompts = []
            inference_idx = []
            max_inference_token = 0
            print('current token count: ', token_count)
            for i in range(len(prompts)):
                left_budget = self.max_think_token - token_count[i]
                if left_budget > 0:
                    prompts[i] = prompts[i] + self.alternative_str
                    inference_loop_prompts.append(prompts[i])
                    inference_idx.append(i)
                    if left_budget > max_inference_token:
                        max_inference_token = left_budget

            outputs = ['' for _ in range(len(prompts))]
            if max_inference_token == 0 or len(inference_loop_prompts) == 0:
                break
            sampling_params = SamplingParams(
                max_tokens=max_inference_token,
                min_tokens=1,
                seed=self.seed,
                stop=["</think>"],
                skip_special_tokens=False,
                temperature=self.temperature,
            )
            o = self.model.generate(
                inference_loop_prompts,
                sampling_params=sampling_params
            )
            assert len(inference_idx) == len(inference_loop_prompts)
            assert len(inference_idx) == len(o)
            for i, output in zip(inference_idx, o):
                outputs[i] = output.outputs[0].text

            for i, idx in enumerate(inference_idx):
                token_count[idx] = token_count[idx] + len(o[i].outputs[0].token_ids)

            for i in range(len(prompts)):
                prompts[i] = prompts[i] + outputs[i]
        print('generating answer...')
        prompts = [p + '\nTime\'s up. End of thinking process. Will answer immediately.\n</think>' for i, p in enumerate(prompts)]
        sampling_params = SamplingParams(
            max_tokens=2048,
            min_tokens=0,
            seed=self.seed,
            skip_special_tokens=False,
            temperature=self.temperature,
        )
        o = self.model.generate(
            prompts,
            sampling_params=sampling_params,
        )
        for i in range(len(prompts)):
            prompts[i] = prompts[i] + o[i].outputs[0].text
        assert len(prompts) == count_prompt
        return prompts

handler = BudgetForcingHandler("scb10x/typhoon2.1-gemma3-4b", max_think_token=2048)
handler(["How many r in raspberry?"])
Intended Uses & Limitations
This model is an instructional model. However, it’s still undergoing development. It incorporates some level of guardrails, but it still may produce answers that are inaccurate, biased, or otherwise objectionable in response to user prompts. We recommend that developers assess these risks in the context of their use case.
Follow us
https://twitter.com/opentyphoon
Support
Citation
- If you find Typhoon2 useful for your work, please cite it using:
@misc{typhoon2,
      title={Typhoon 2: A Family of Open Text and Multimodal Thai Large Language Models},
      author={Kunat Pipatanakul and Potsawee Manakul and Natapong Nitarach and Warit Sirichotedumrong and Surapon Nonesung and Teetouch Jaknamon and Parinthapat Pengpun and Pittawat Taveekitworachai and Adisai Na-Thalang and Sittipong Sripaisarnmongkol and Krisanapong Jirayoot and Kasima Tharnpipitchai},
      year={2024},
      eprint={2412.13702},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2412.13702},
}