GLM-4-9B-Chat
中文阅读,请看这里.
If you are using the weights from this repository, please update to
transformers>=4.46.0
These weights are not compatible with older versions of the transformers library.
Model Introduction
GLM-4-9B is the open-source version of the latest generation of pre-trained models in the GLM-4 series launched by Zhipu AI. In the evaluation of data sets in semantics, mathematics, reasoning, code, and knowledge, GLM-4-9B and its human preference-aligned version GLM-4-9B-Chat have shown superior performance beyond Llama-3-8B. In addition to multi-round conversations, GLM-4-9B-Chat also has advanced features such as web browsing, code execution, custom tool calls (Function Call), and long context reasoning (supporting up to 128K context). This generation of models has added multi-language support, supporting 26 languages including Japanese, Korean, and German. We have also launched the GLM-4-9B-Chat-1M model that supports 1M context length (about 2 million Chinese characters) and the multimodal model GLM-4V-9B based on GLM-4-9B. GLM-4V-9B possesses dialogue capabilities in both Chinese and English at a high resolution of 1120*1120. In various multimodal evaluations, including comprehensive abilities in Chinese and English, perception & reasoning, text recognition, and chart understanding, GLM-4V-9B demonstrates superior performance compared to GPT-4-turbo-2024-04-09, Gemini 1.0 Pro, Qwen-VL-Max, and Claude 3 Opus.
Benchmark
We evaluated the GLM-4-9B-Chat model on some classic tasks and obtained the following results:
| Model | AlignBench-v2 | MT-Bench | IFEval | MMLU | C-Eval | GSM8K | MATH | HumanEval | NCB |
|---|---|---|---|---|---|---|---|---|---|
| Llama-3-8B-Instruct | 5.12 | 8.00 | 68.58 | 68.4 | 51.3 | 79.6 | 30.0 | 62.2 | 24.7 |
| ChatGLM3-6B | 3.97 | 5.50 | 28.1 | 66.4 | 69.0 | 72.3 | 25.7 | 58.5 | 11.3 |
| GLM-4-9B-Chat | 6.61 | 8.35 | 69.0 | 72.4 | 75.6 | 79.6 | 50.6 | 71.8 | 32.2 |
Long Context
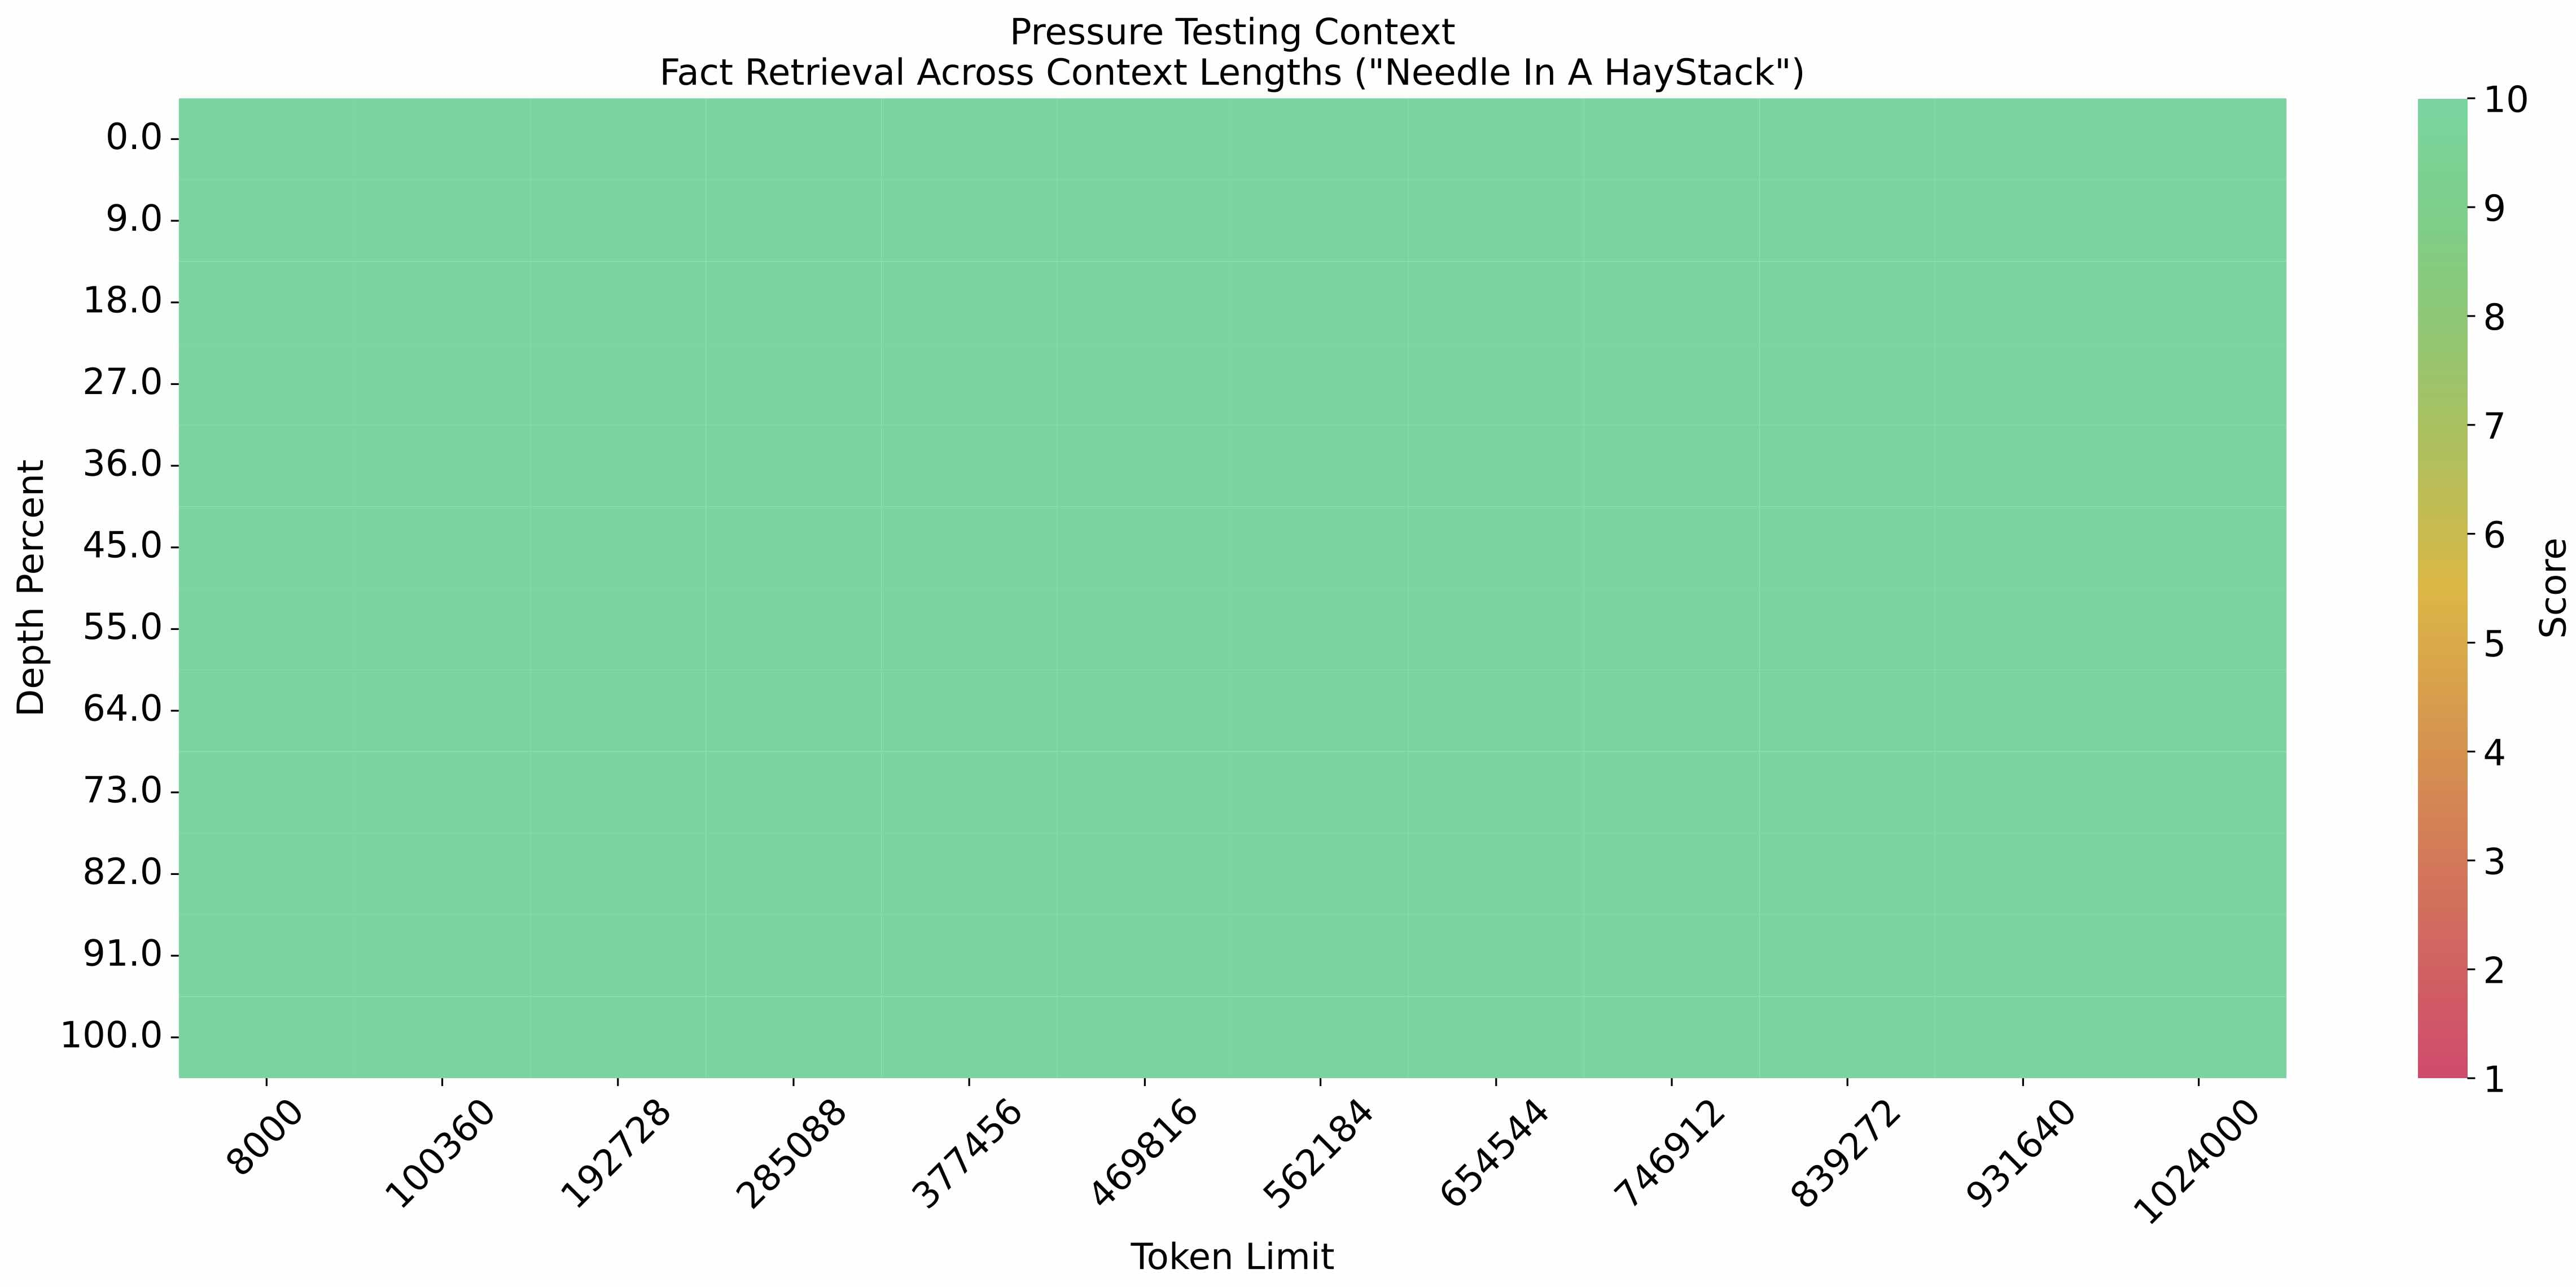
The eval_needle experiment was conducted with a context length of 1M, and the results are as follows:
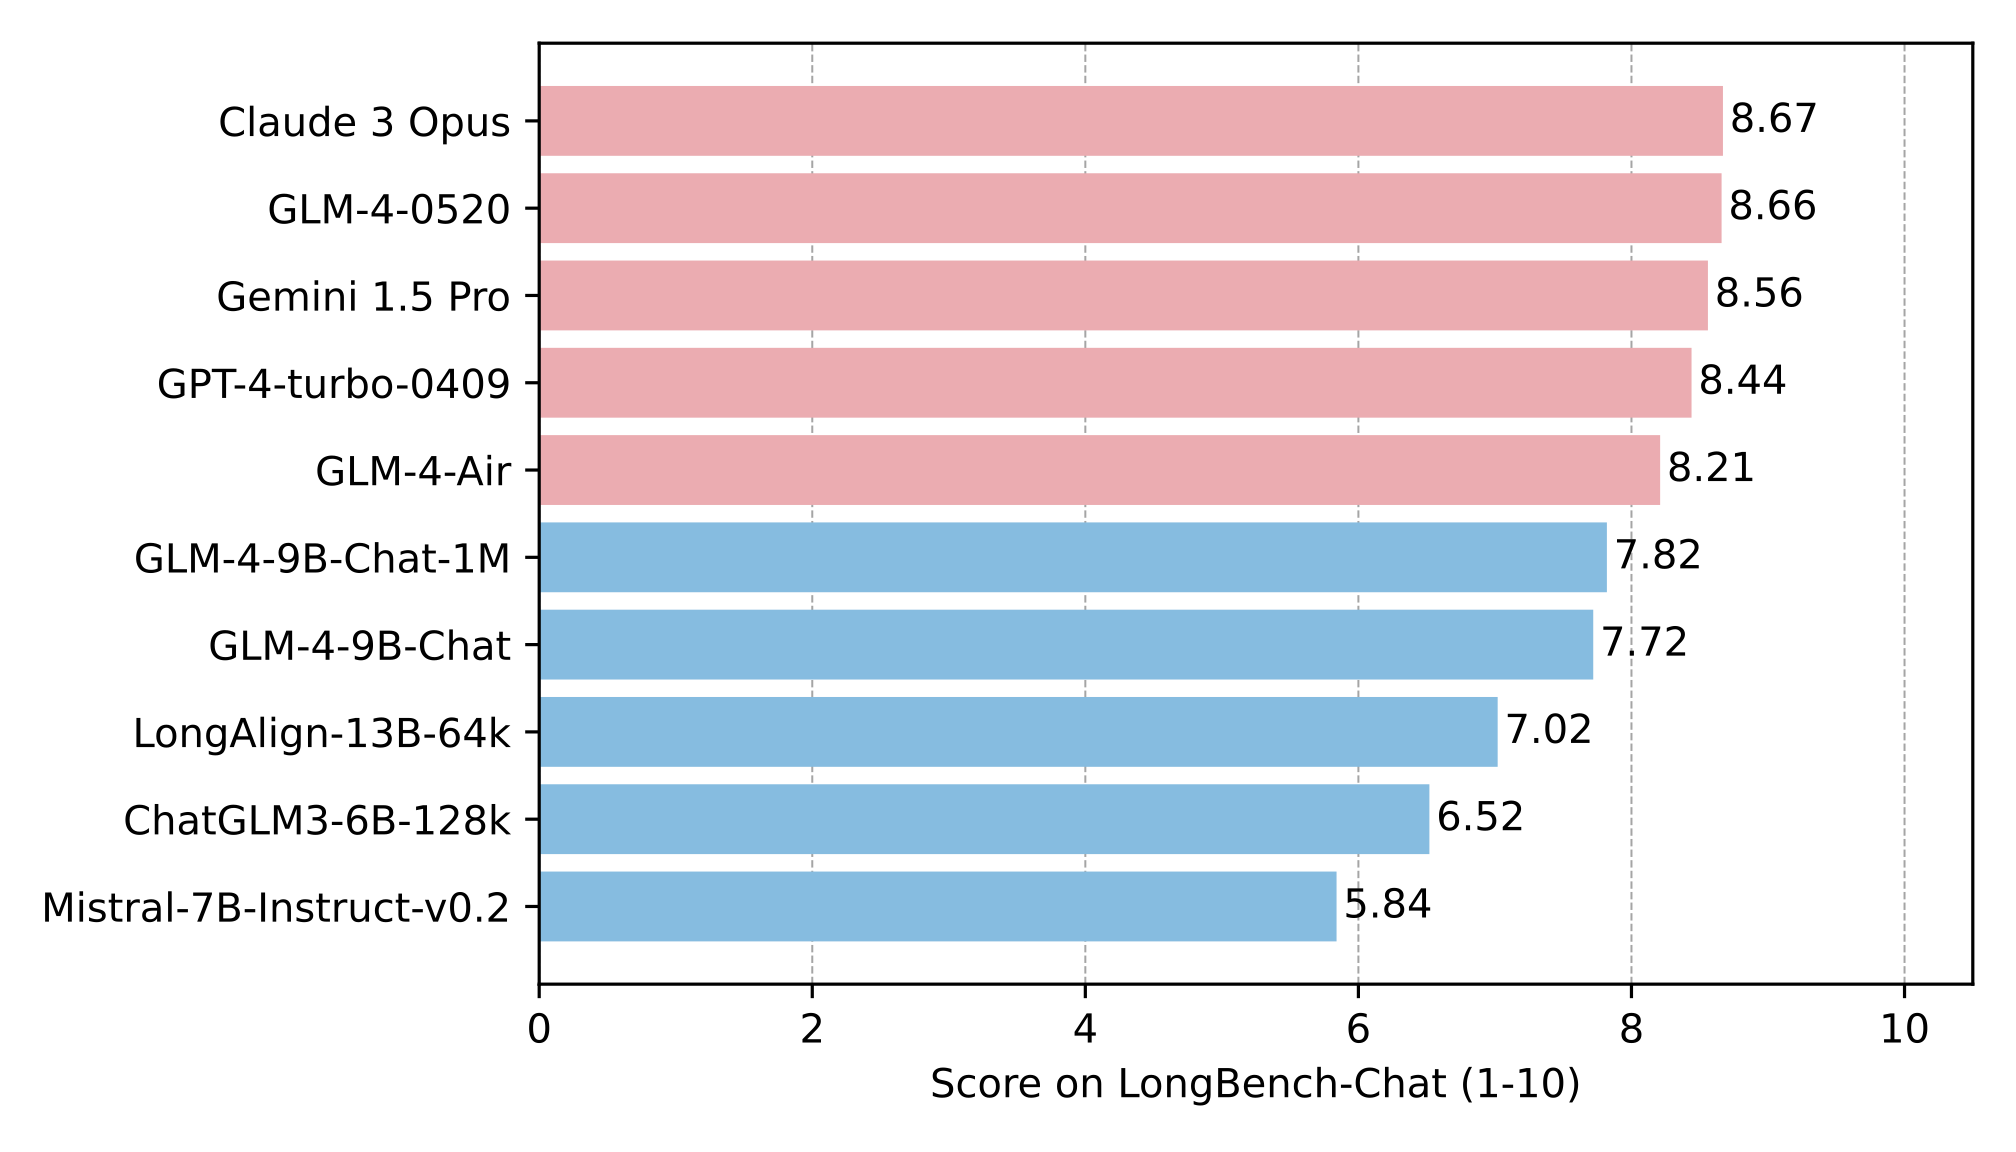
The long text capability was further evaluated on LongBench, and the results are as follows:
Multi Language
The tests for GLM-4-9B-Chat and Llama-3-8B-Instruct are conducted on six multilingual datasets. The test results and the corresponding languages selected for each dataset are shown in the table below:
| Dataset | Llama-3-8B-Instruct | GLM-4-9B-Chat | Languages |
|---|---|---|---|
| M-MMLU | 49.6 | 56.6 | all |
| FLORES | 25.0 | 28.8 | ru, es, de, fr, it, pt, pl, ja, nl, ar, tr, cs, vi, fa, hu, el, ro, sv, uk, fi, ko, da, bg, no |
| MGSM | 54.0 | 65.3 | zh, en, bn, de, es, fr, ja, ru, sw, te, th |
| XWinograd | 61.7 | 73.1 | zh, en, fr, jp, ru, pt |
| XStoryCloze | 84.7 | 90.7 | zh, en, ar, es, eu, hi, id, my, ru, sw, te |
| XCOPA | 73.3 | 80.1 | zh, et, ht, id, it, qu, sw, ta, th, tr, vi |
Function Call
Tested on Berkeley Function Calling Leaderboard.
| Model | Overall Acc. | AST Summary | Exec Summary | Relevance |
|---|---|---|---|---|
| Llama-3-8B-Instruct | 58.88 | 59.25 | 70.01 | 45.83 |
| gpt-4-turbo-2024-04-09 | 81.24 | 82.14 | 78.61 | 88.75 |
| ChatGLM3-6B | 57.88 | 62.18 | 69.78 | 5.42 |
| GLM-4-9B-Chat | 81.00 | 80.26 | 84.40 | 87.92 |
This repository is the model repository of GLM-4-9B-Chat, supporting 128K context length.
Quick Start
For more inference code and requirements, please visit our github page.
Please strictly follow the dependencies to install, otherwise it will not run properly
Transformers Lib(4.46.0 and later version) for inference:
from transformers import AutoModelForCausalLM, AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained('THUDM/glm-4-9b-chat-hf')
model = AutoModelForCausalLM.from_pretrained('THUDM/glm-4-9b-chat-hf', device_map="auto")

message = [
    {
        "role": "system",
        "content": "Answer the following question."
    },
    {
        "role": "user",
        "content": "How many legs does a cat have?"
    }
]

inputs = tokenizer.apply_chat_template(
    message,
    return_tensors='pt',
    add_generation_prompt=True,
    return_dict=True,
).to(model.device)

input_len = inputs['input_ids'].shape[1]
generate_kwargs = {
    "input_ids": inputs['input_ids'],
    "attention_mask": inputs['attention_mask'],
    "max_new_tokens": 128,
    "do_sample": False,
}
out = model.generate(**generate_kwargs)
print(tokenizer.decode(out[0][input_len:], skip_special_tokens=True))
vLLM Lib(0.6.4 and later version) for inference:
from transformers import AutoTokenizer
from vllm import LLM, SamplingParams

# GLM-4-9B-Chat-1M
# max_model_len, tp_size = 1048576, 4
# If you encounter OOM phenomenon, it is recommended to reduce max_model_len or increase tp_size
max_model_len, tp_size = 131072, 1
model_name = "THUDM/glm-4-9b-chat-hf"
prompt = [{"role": "user", "content": "what is your name?"}]

tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
llm = LLM(
    model=model_name,
    tensor_parallel_size=tp_size,
    max_model_len=max_model_len,
    trust_remote_code=True,
    enforce_eager=True,
    # GLM-4-9B-Chat-1M-HF If you encounter OOM phenomenon, it is recommended to enable the following parameters
    # enable_chunked_prefill=True,
    # max_num_batched_tokens=8192
)
stop_token_ids = [151329, 151336, 151338]
sampling_params = SamplingParams(temperature=0.95, max_tokens=1024, stop_token_ids=stop_token_ids)

inputs = tokenizer.apply_chat_template(prompt, tokenize=False, add_generation_prompt=True)
outputs = llm.generate(prompts=inputs, sampling_params=sampling_params)

print(outputs[0].outputs[0].text)
LICENSE
The weights of the GLM-4 model are available under the terms of LICENSE.
Citations
If you find our work useful, please consider citing the following paper.
@misc{glm2024chatglm,
      title={ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools},
      author={Team GLM and Aohan Zeng and Bin Xu and Bowen Wang and Chenhui Zhang and Da Yin and Diego Rojas and Guanyu Feng and Hanlin Zhao and Hanyu Lai and Hao Yu and Hongning Wang and Jiadai Sun and Jiajie Zhang and Jiale Cheng and Jiayi Gui and Jie Tang and Jing Zhang and Juanzi Li and Lei Zhao and Lindong Wu and Lucen Zhong and Mingdao Liu and Minlie Huang and Peng Zhang and Qinkai Zheng and Rui Lu and Shuaiqi Duan and Shudan Zhang and Shulin Cao and Shuxun Yang and Weng Lam Tam and Wenyi Zhao and Xiao Liu and Xiao Xia and Xiaohan Zhang and Xiaotao Gu and Xin Lv and Xinghan Liu and Xinyi Liu and Xinyue Yang and Xixuan Song and Xunkai Zhang and Yifan An and Yifan Xu and Yilin Niu and Yuantao Yang and Yueyan Li and Yushi Bai and Yuxiao Dong and Zehan Qi and Zhaoyu Wang and Zhen Yang and Zhengxiao Du and Zhenyu Hou and Zihan Wang},
      year={2024},
      eprint={2406.12793},
      archivePrefix={arXiv},
      primaryClass={id='cs.CL' full_name='Computation and Language' is_active=True alt_name='cmp-lg' in_archive='cs' is_general=False description='Covers natural language processing. Roughly includes material in ACM Subject Class I.2.7. Note that work on artificial languages (programming languages, logics, formal systems) that does not explicitly address natural-language issues broadly construed (natural-language processing, computational linguistics, speech, text retrieval, etc.) is not appropriate for this area.'}
}