spop style
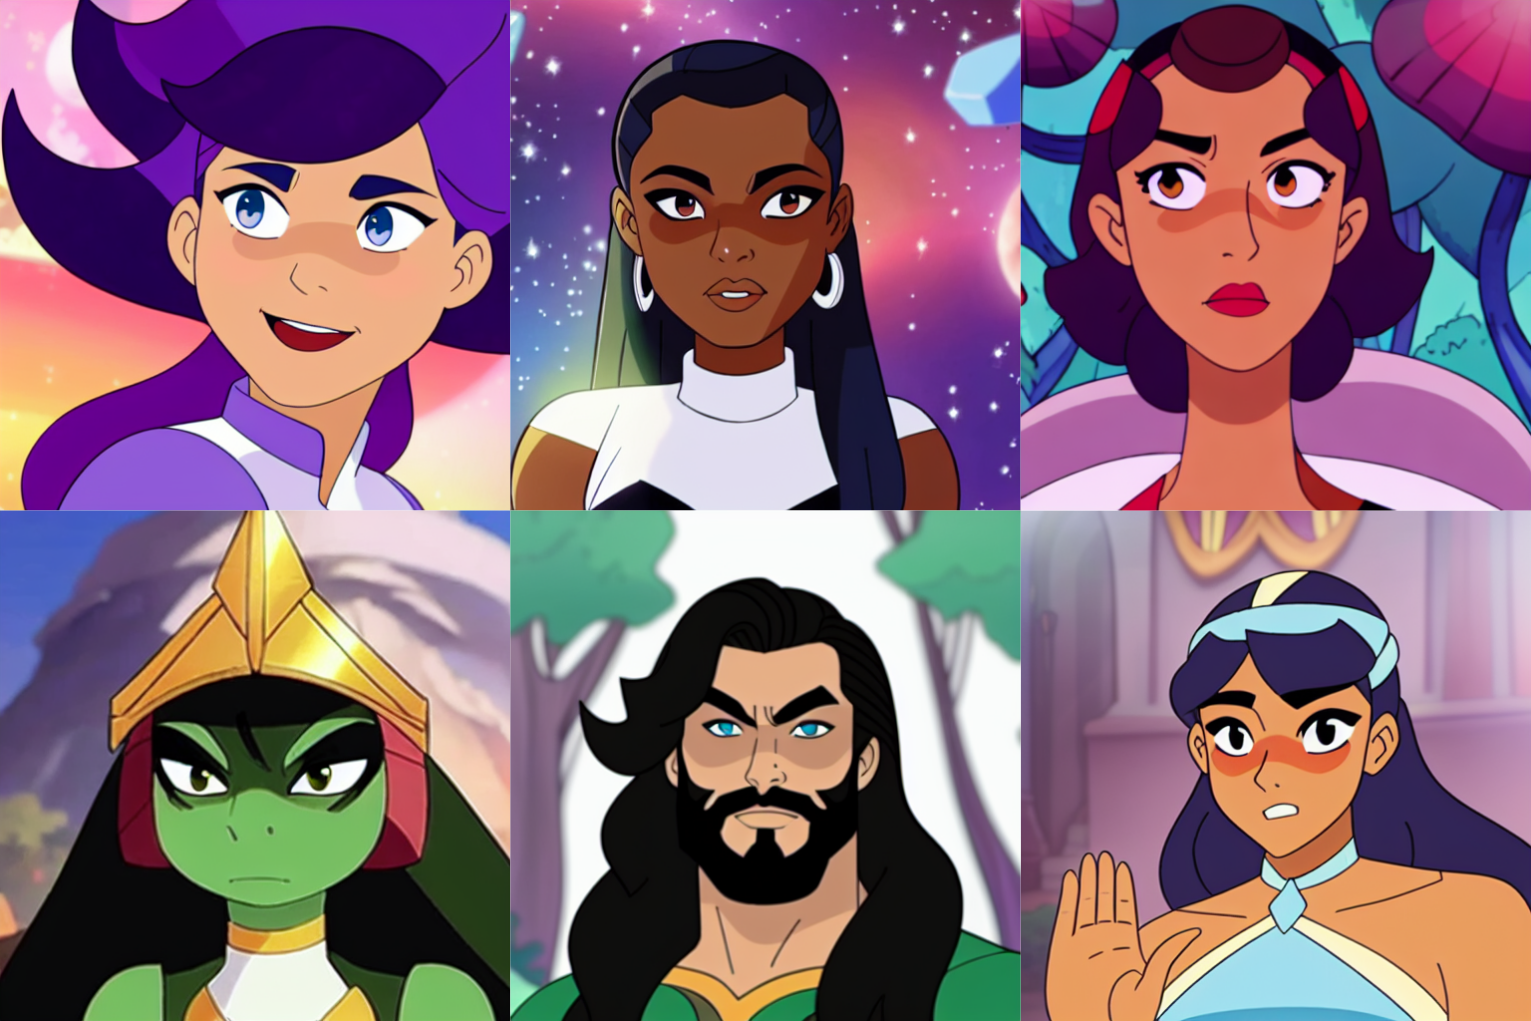
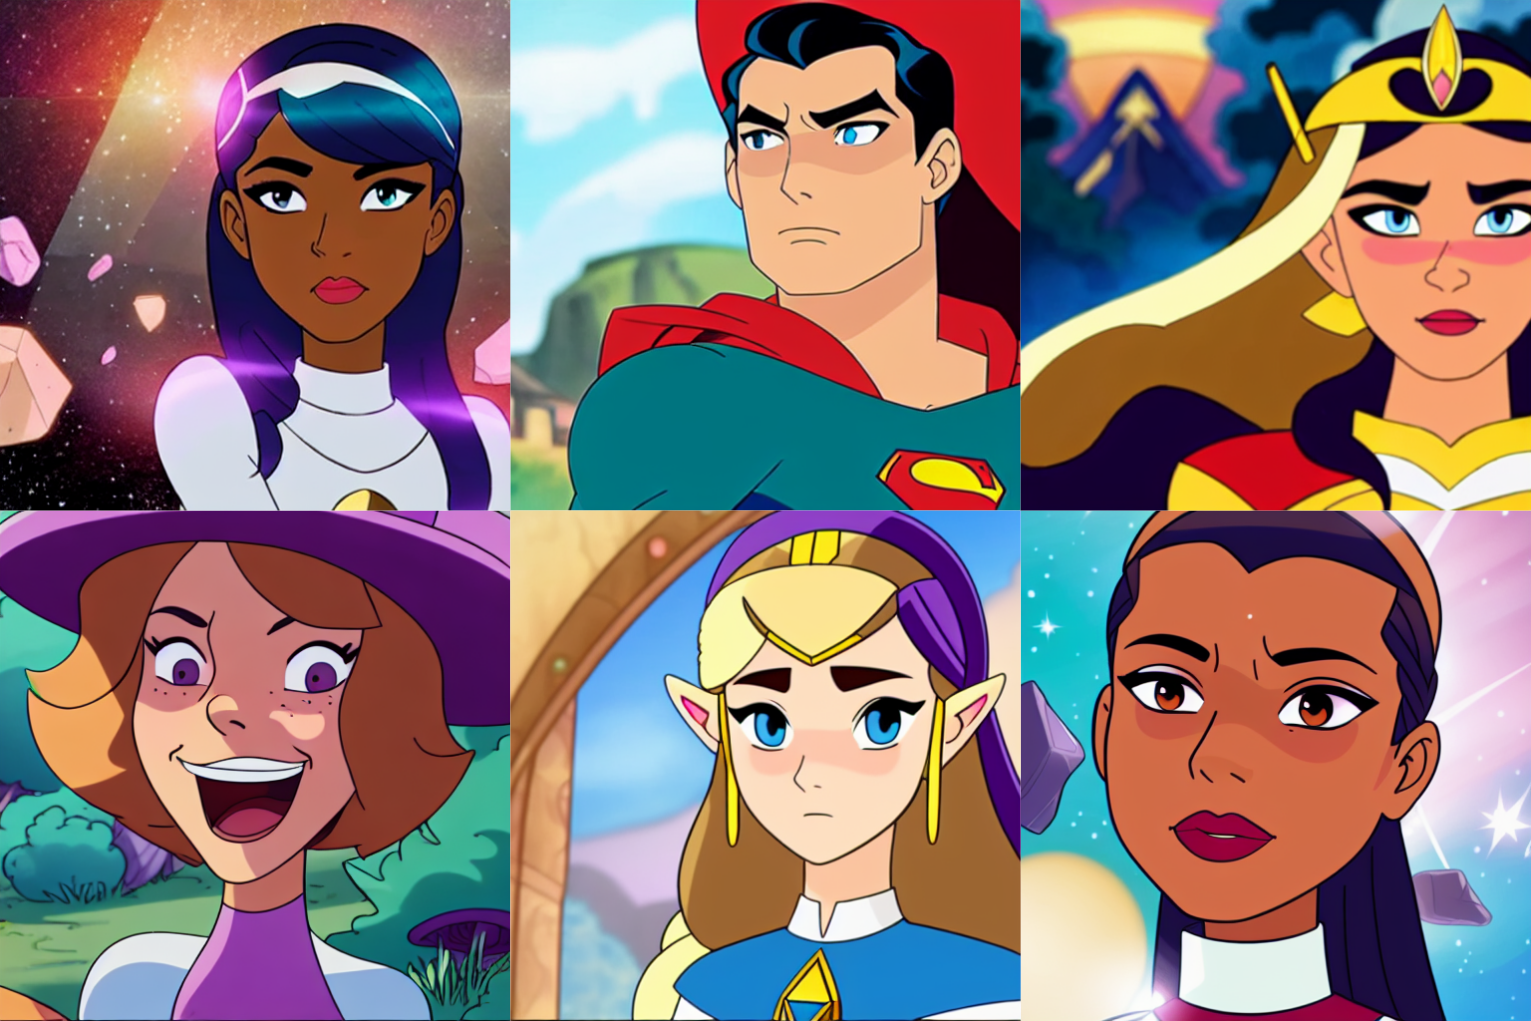
This model features four different concepts: humans, outer space, forests, and landscapes in the specific style of SPOP: She-Ra and the Princesses of Power, the Dreamworks version.
This is a fine-tuned Stable Diffusion model, based on SD 1.5.
The goal of this model is to capture the style - not the individual characters featured in the series.
💖 Disclaimer: This is my favorite show. I won't go into that here but a lot of love went into this model.
Model Usage
This model was trained on multiple concepts. Use the tokens below:
| Token | Description |
|---|---|
👤 dwspop style | Uses concepts trained on people |
🌌 dwspop space | Uses concepts trained on outer space |
🌲 dwspop forest | Uses concepts trained on forests |
🌄 dwspop landscape | Uses concepts trained on landscapes |
👤 dwspop style examples
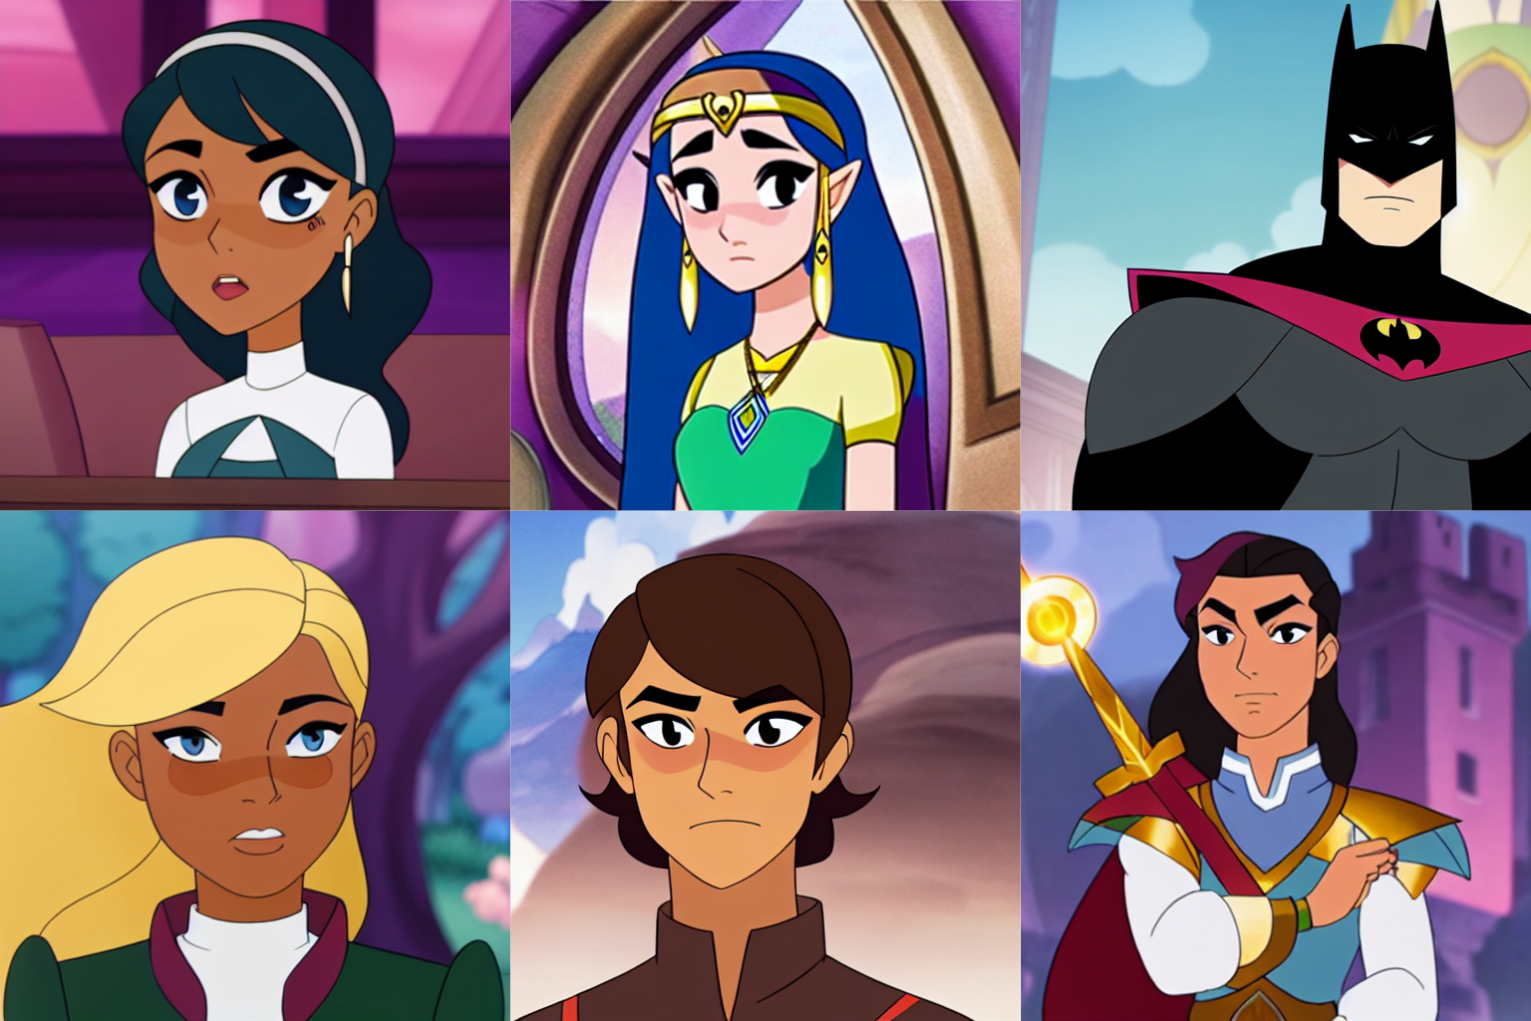
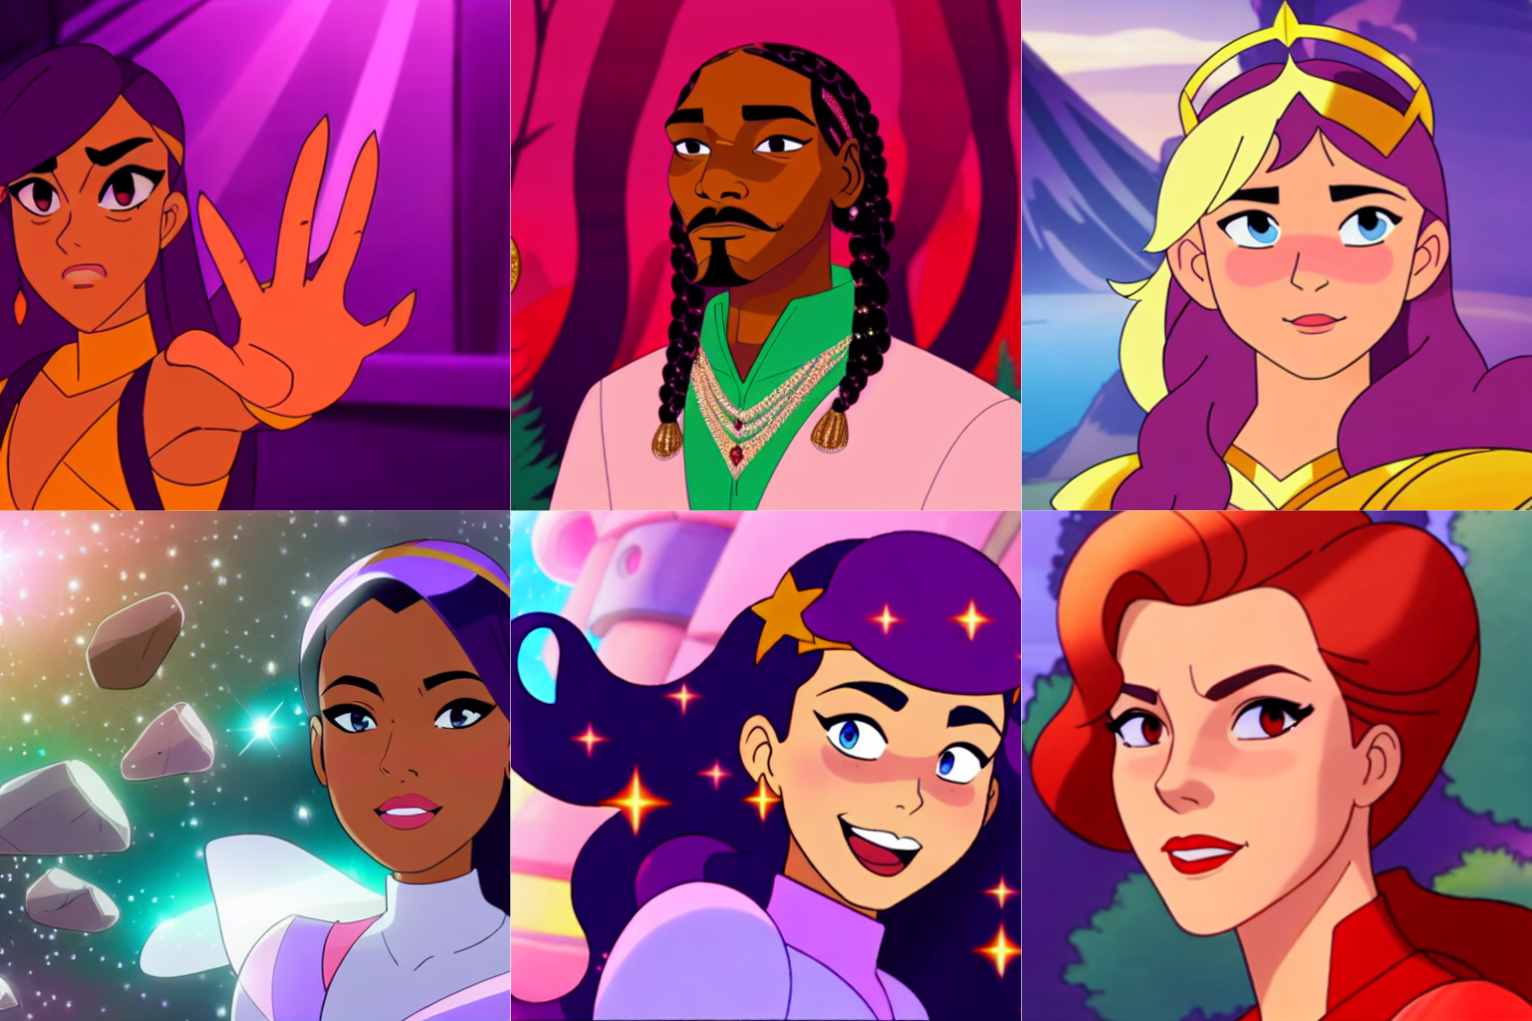
This token is capable of handling multiple genders and uses person which can be then used for woman, man,
or cat-like woman, or even lizard, dog, snoop dog... it's awesome:
-
a photo of a person in a forest, dwspop style -
a photo of a woman floating in space, dwspop style -
a photo of a man inside of a palace standing near a window, dwspop style
⛔ Negative prompt: ((out of focus body)), ((out of focus face)), ((((ugly)))), (((duplicate))), ((morbid)), ((mutilated)), [out of frame], extra fingers, mutated hands, ((poorly drawn hands)), ((poorly drawn face)), (((mutation))), (((deformed))), ((ugly)), blurry, ((bad anatomy)), (((bad proportions))), ((extra limbs)), cloned face, (((disfigured))), out of frame, ugly, extra limbs, (bad anatomy), gross proportions, (malformed limbs), ((missing arms)), ((missing legs)), (((extra arms))), (((extra legs))), mutated hands, (fused fingers), (too many fingers), (((long neck)))
🌌 dwspop space examples
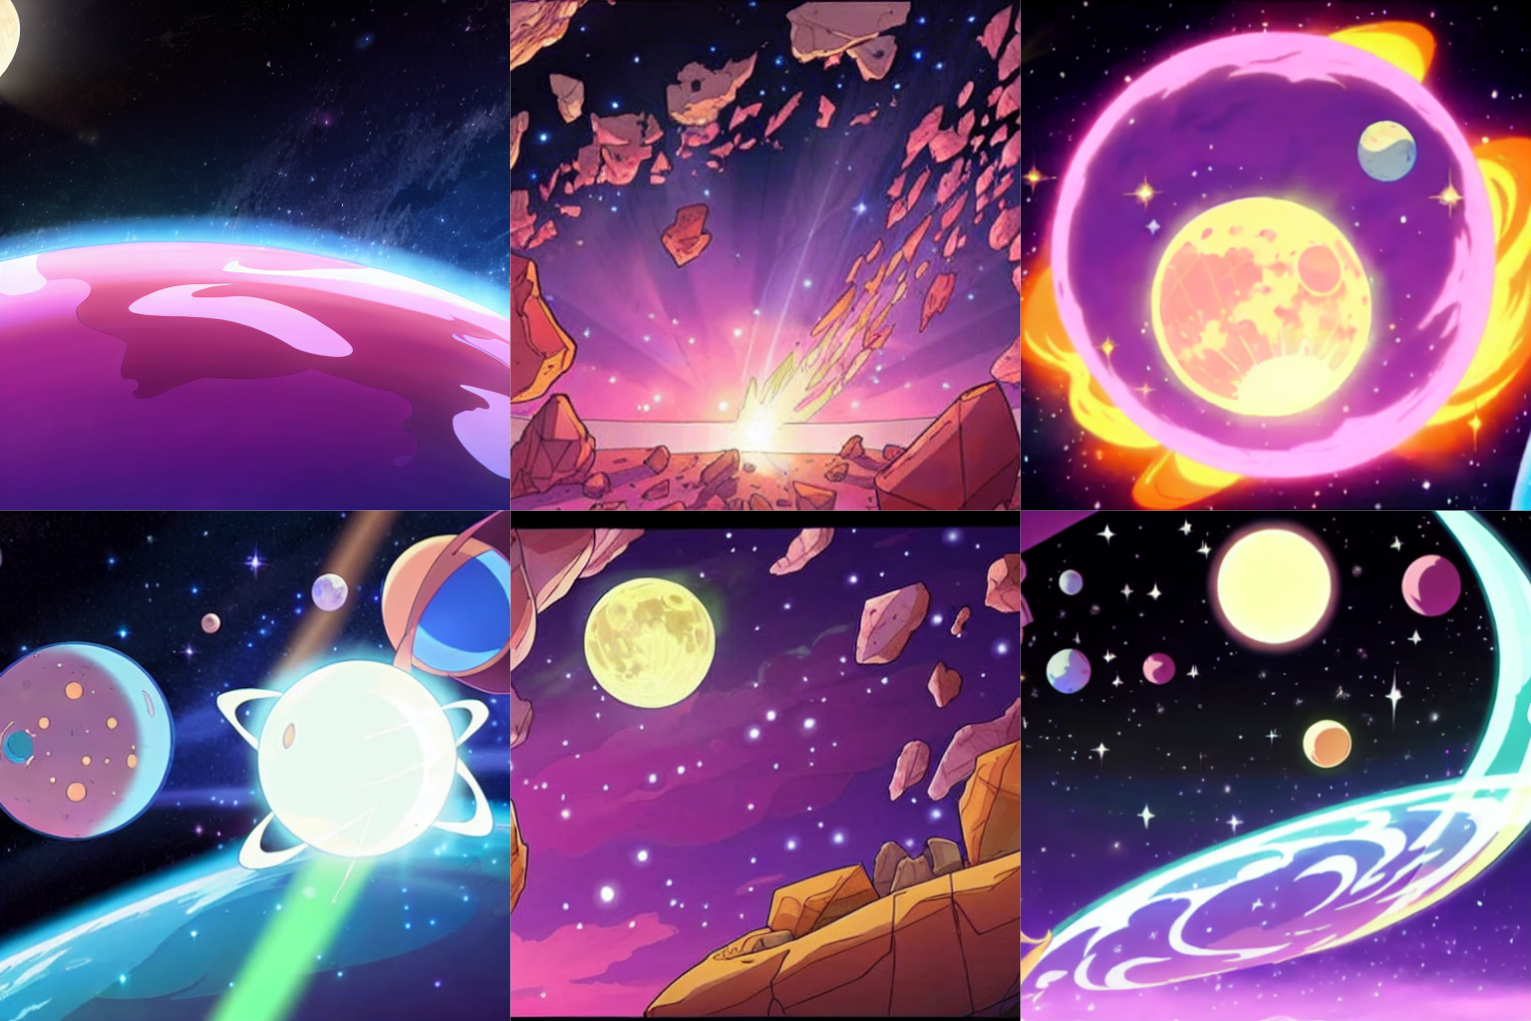
The space token is versatile when prompting, especially when generating galaxies and solar systems. This token is capable of handling different camera angles by desribing in your prompts as a scene.
-
a scene of outer space with asteroids and rocks floating in space getting melted by a bright light, dwspop space -
a scene of an outer space solar system with planets, stars and galaxies in the background, dwspop space -
a scene of a planet in space with stars in the background, dwspop space
⛔ Negative prompt: ((out of focus face)), (((duplicate))), [out of frame], blurry, out of frame, ugly, blur, motion blur
🌲 dwspop forest forest examples
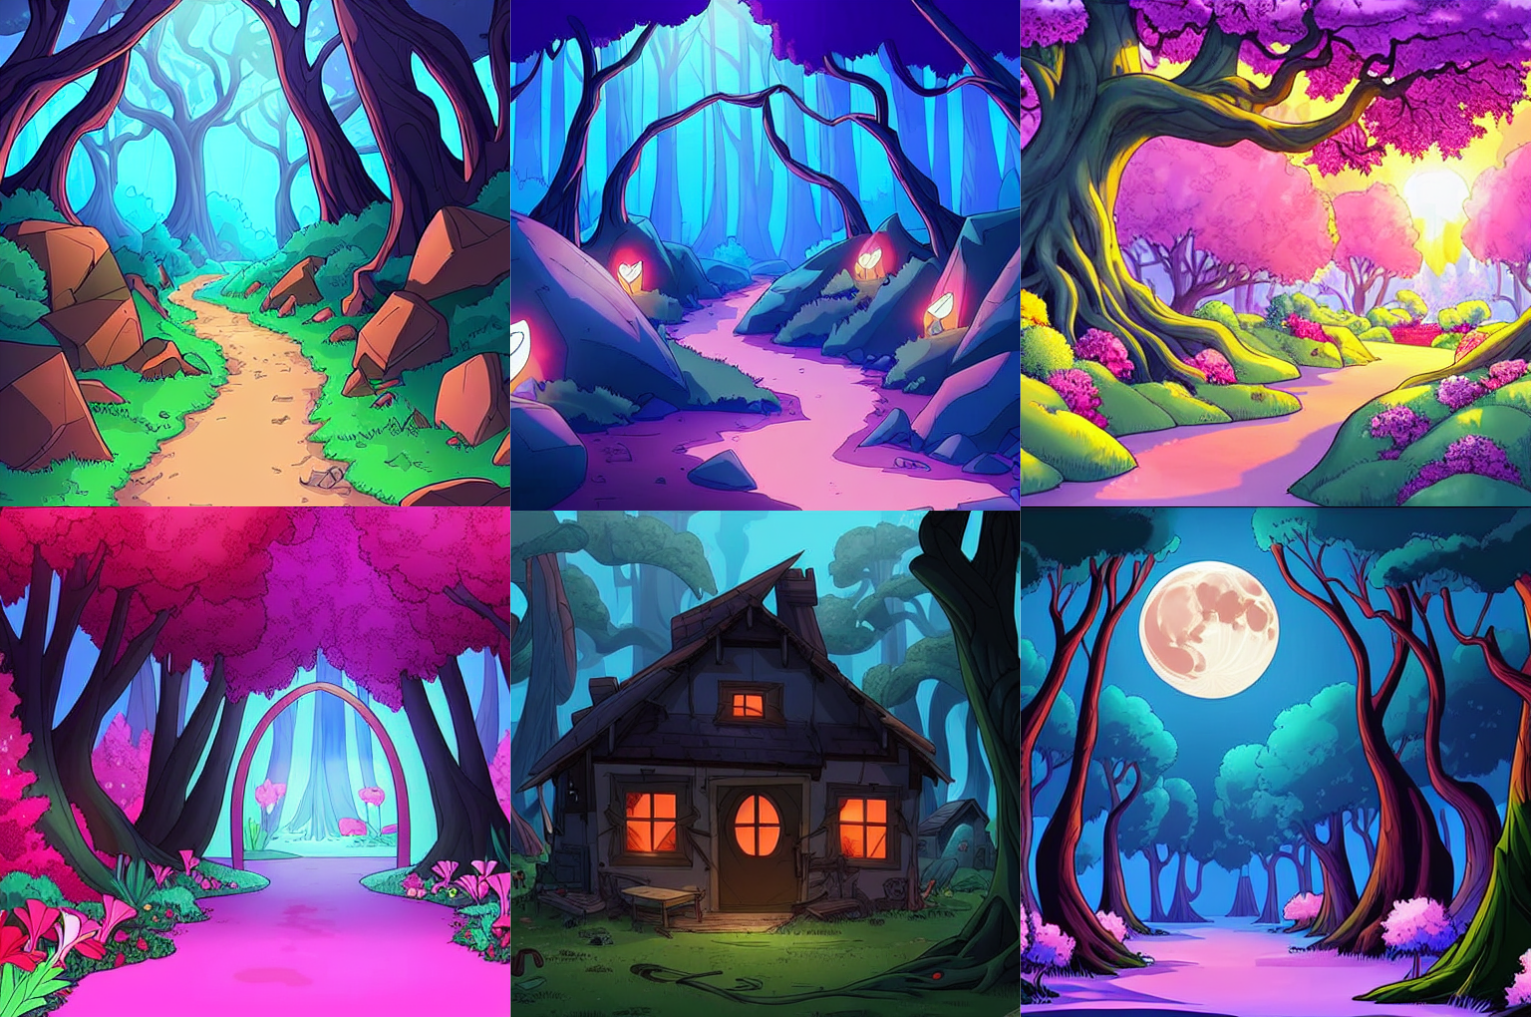
The forest token is able to generate random forest scenes due to the regularization images that were used. When prompting, additional enviromental objects are supported, such as crystals, rocks, flowers, cottage. Finally, mix in time of day: sunrise, dawn, sunset, evening.
-
a beautiful photo of a path in a forest with glowing lights and rocks and trees on either side of the path, dwspop forest -
a forest during night time with a full moon in the sky, dynamic lighting, bright lights, dwspop forest -
a scene of an entrance to a huge forest with pink flowers, dynamic lighting, bright lights, dwspop forest
⛔ Negative prompt: ((out of focus face)), (((duplicate))), [out of frame], blurry, out of frame, ugly, blur, motion blur
🌄 dwspop landscape examples:
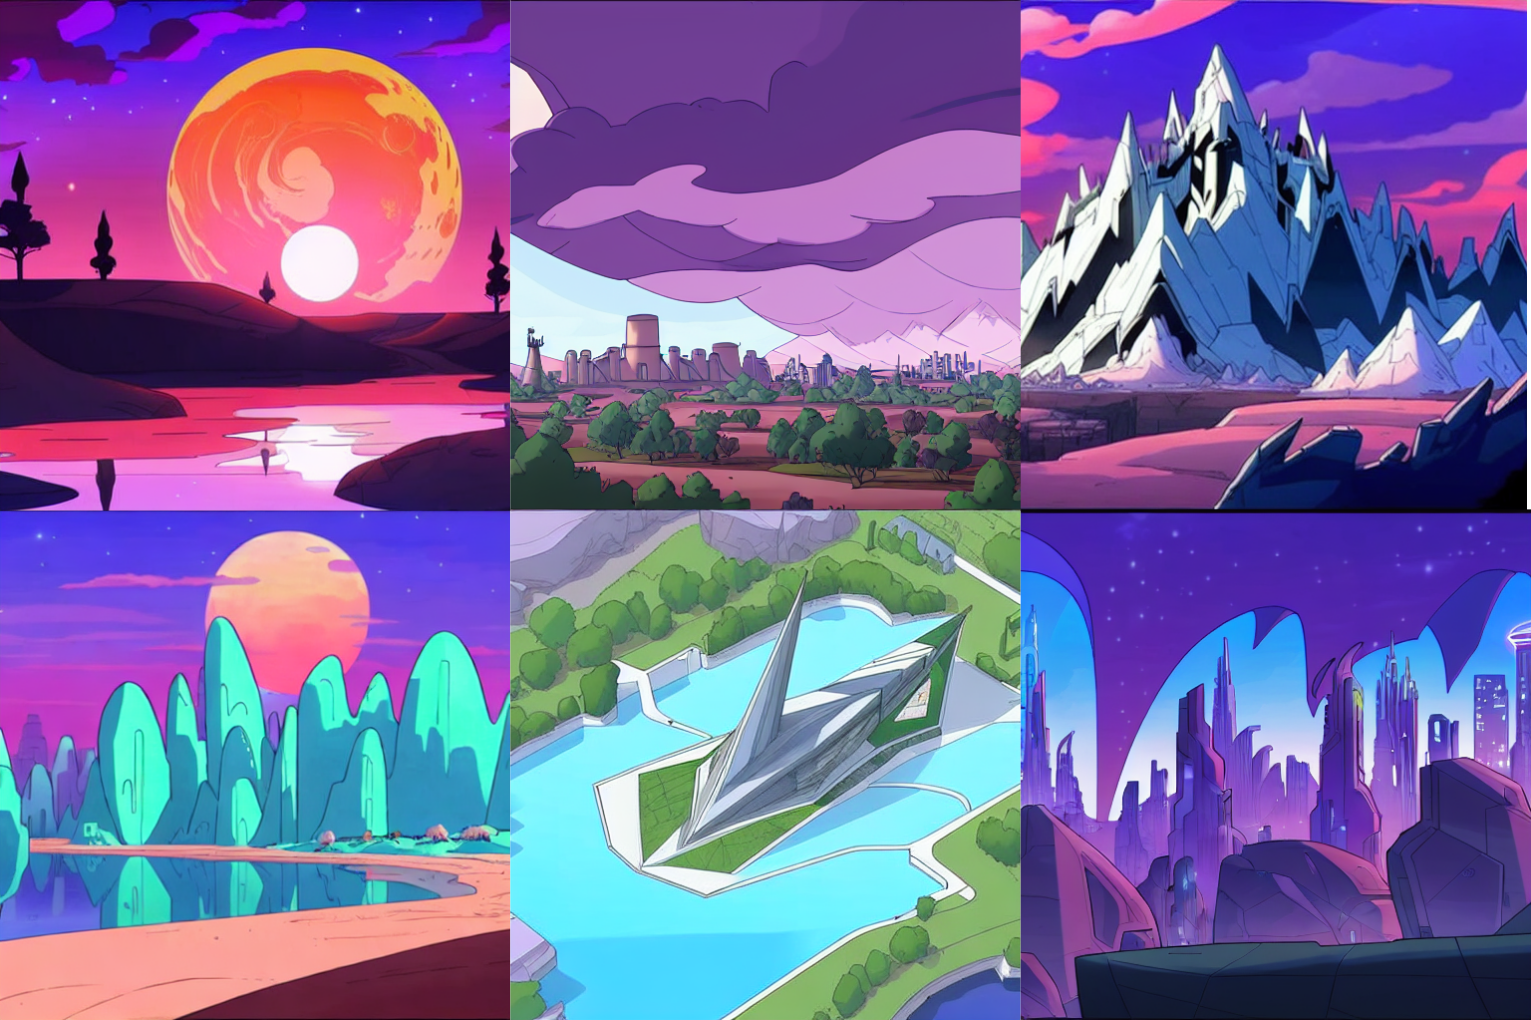
The landscape token is primarly for landscapes but also supports a small percentage of architecture. Blending your prompts to have both an establishing shot of a landscape with architecture woven in and out is where this token shines.
-
a scene of a weapon shop that has many different swords hanging on the wall and arrows and staffs inside of barrels, a small shop with a tent in the background, dwspop landscape -
a scene of a village with a waterfall, wooden stairs leading to the top of trees, dynamic lighting, dwspop landscape -
a beautiful scene of a palace with wide doors and a fountain and flowers near a window, sunset, dynamic lighting, dwspop landscape
⛔ Negative prompt: ((out of focus face)), (((duplicate))), [out of frame], blurry, out of frame, ugly, blur, motion blur
🧨 Diffusers
This model can be used just like any other Stable Diffusion model. For more information, see Stable Diffusion.
Export the model:
from diffusers import StableDiffusionPipeline
import torch

model_id = "zuleo/spop"
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
pipe = pipe.to("cuda")

prompt = "Perfectly-centered close up portrait-photograph of a person, marketplace in the background, sunrise, dwspop style"
image = pipe(prompt).images[0]

image.save("./spop_person.png")
📅 text2img Range Grids
It's always great to get a visual of what's going on with sampler, CFG scale, and other settings. See the examples below and tune them to your liking.
Sampler
Using different samplers can produce different results. My favorites are using DPM++ 2S a Karras, DPM++ SDE Karras, DPM adaptive for cartoon scenes.
🔥 DPM Adaptive: DPM Adaptive does not use steps. This sampler is fixed depending on the CFG scale and additional configurations.
View the XY grids below for details:
-
Space: https://huggingface.co/zuleo/spop/resolve/main/images/dwspop_space_grid.png
-
Forest: https://huggingface.co/zuleo/spop/resolve/main/images/dwspop_forest_grid.png
-
Landscape: https://huggingface.co/zuleo/spop/resolve/main/images/dwspop_landscape_grid.png

Sampling Steps for person
Values between 25 - 38 is a good range for most samplers but not all. See the Sampling Steps grid with each sampler below:
CFG Scale
Values between 7 - 11 is a good range. See the CFG Scale grid:
📅 img2img Grids
This model works with img2img with a balanced configuration between CFG scale, denoising, and adding more detail with sampling steps.
Denoising & Steps
Steps: 39 - 46, Denoising: 0.49 - 0.6:

Samplers & Denoising
Samplers: all, Denoising: 0.6 - 0.7:

Samplers & CFG Scale
Samplers: all, CFG Scale: 7.0 - 11.0:
🌐 Regularization images
If you would like to use the regularization images from this training, see the datasets below:
-
space: https://huggingface.co/datasets/3ee/regularization-space -
forest: https://huggingface.co/datasets/3ee/regularization-forest -
landscape: https://huggingface.co/datasets/3ee/regularization-landscape
☕ If you enjoy this model, buy me a coffee