Model card
We introduce Sana, a text-to-image framework that can efficiently generate images up to 4096 × 4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU.
Source code is available at https://github.com/NVlabs/Sana.
Note
- Weakness in Complex Scene Creation: Due to limitation of data, our model has limited capabilities in generating complex scenes, text, and human hands.
- Enhancing Capabilities: The model’s performance can be improved by increasing the complexity and length of prompts. Below are some examples of prompts and samples.
2K samples
| Images | 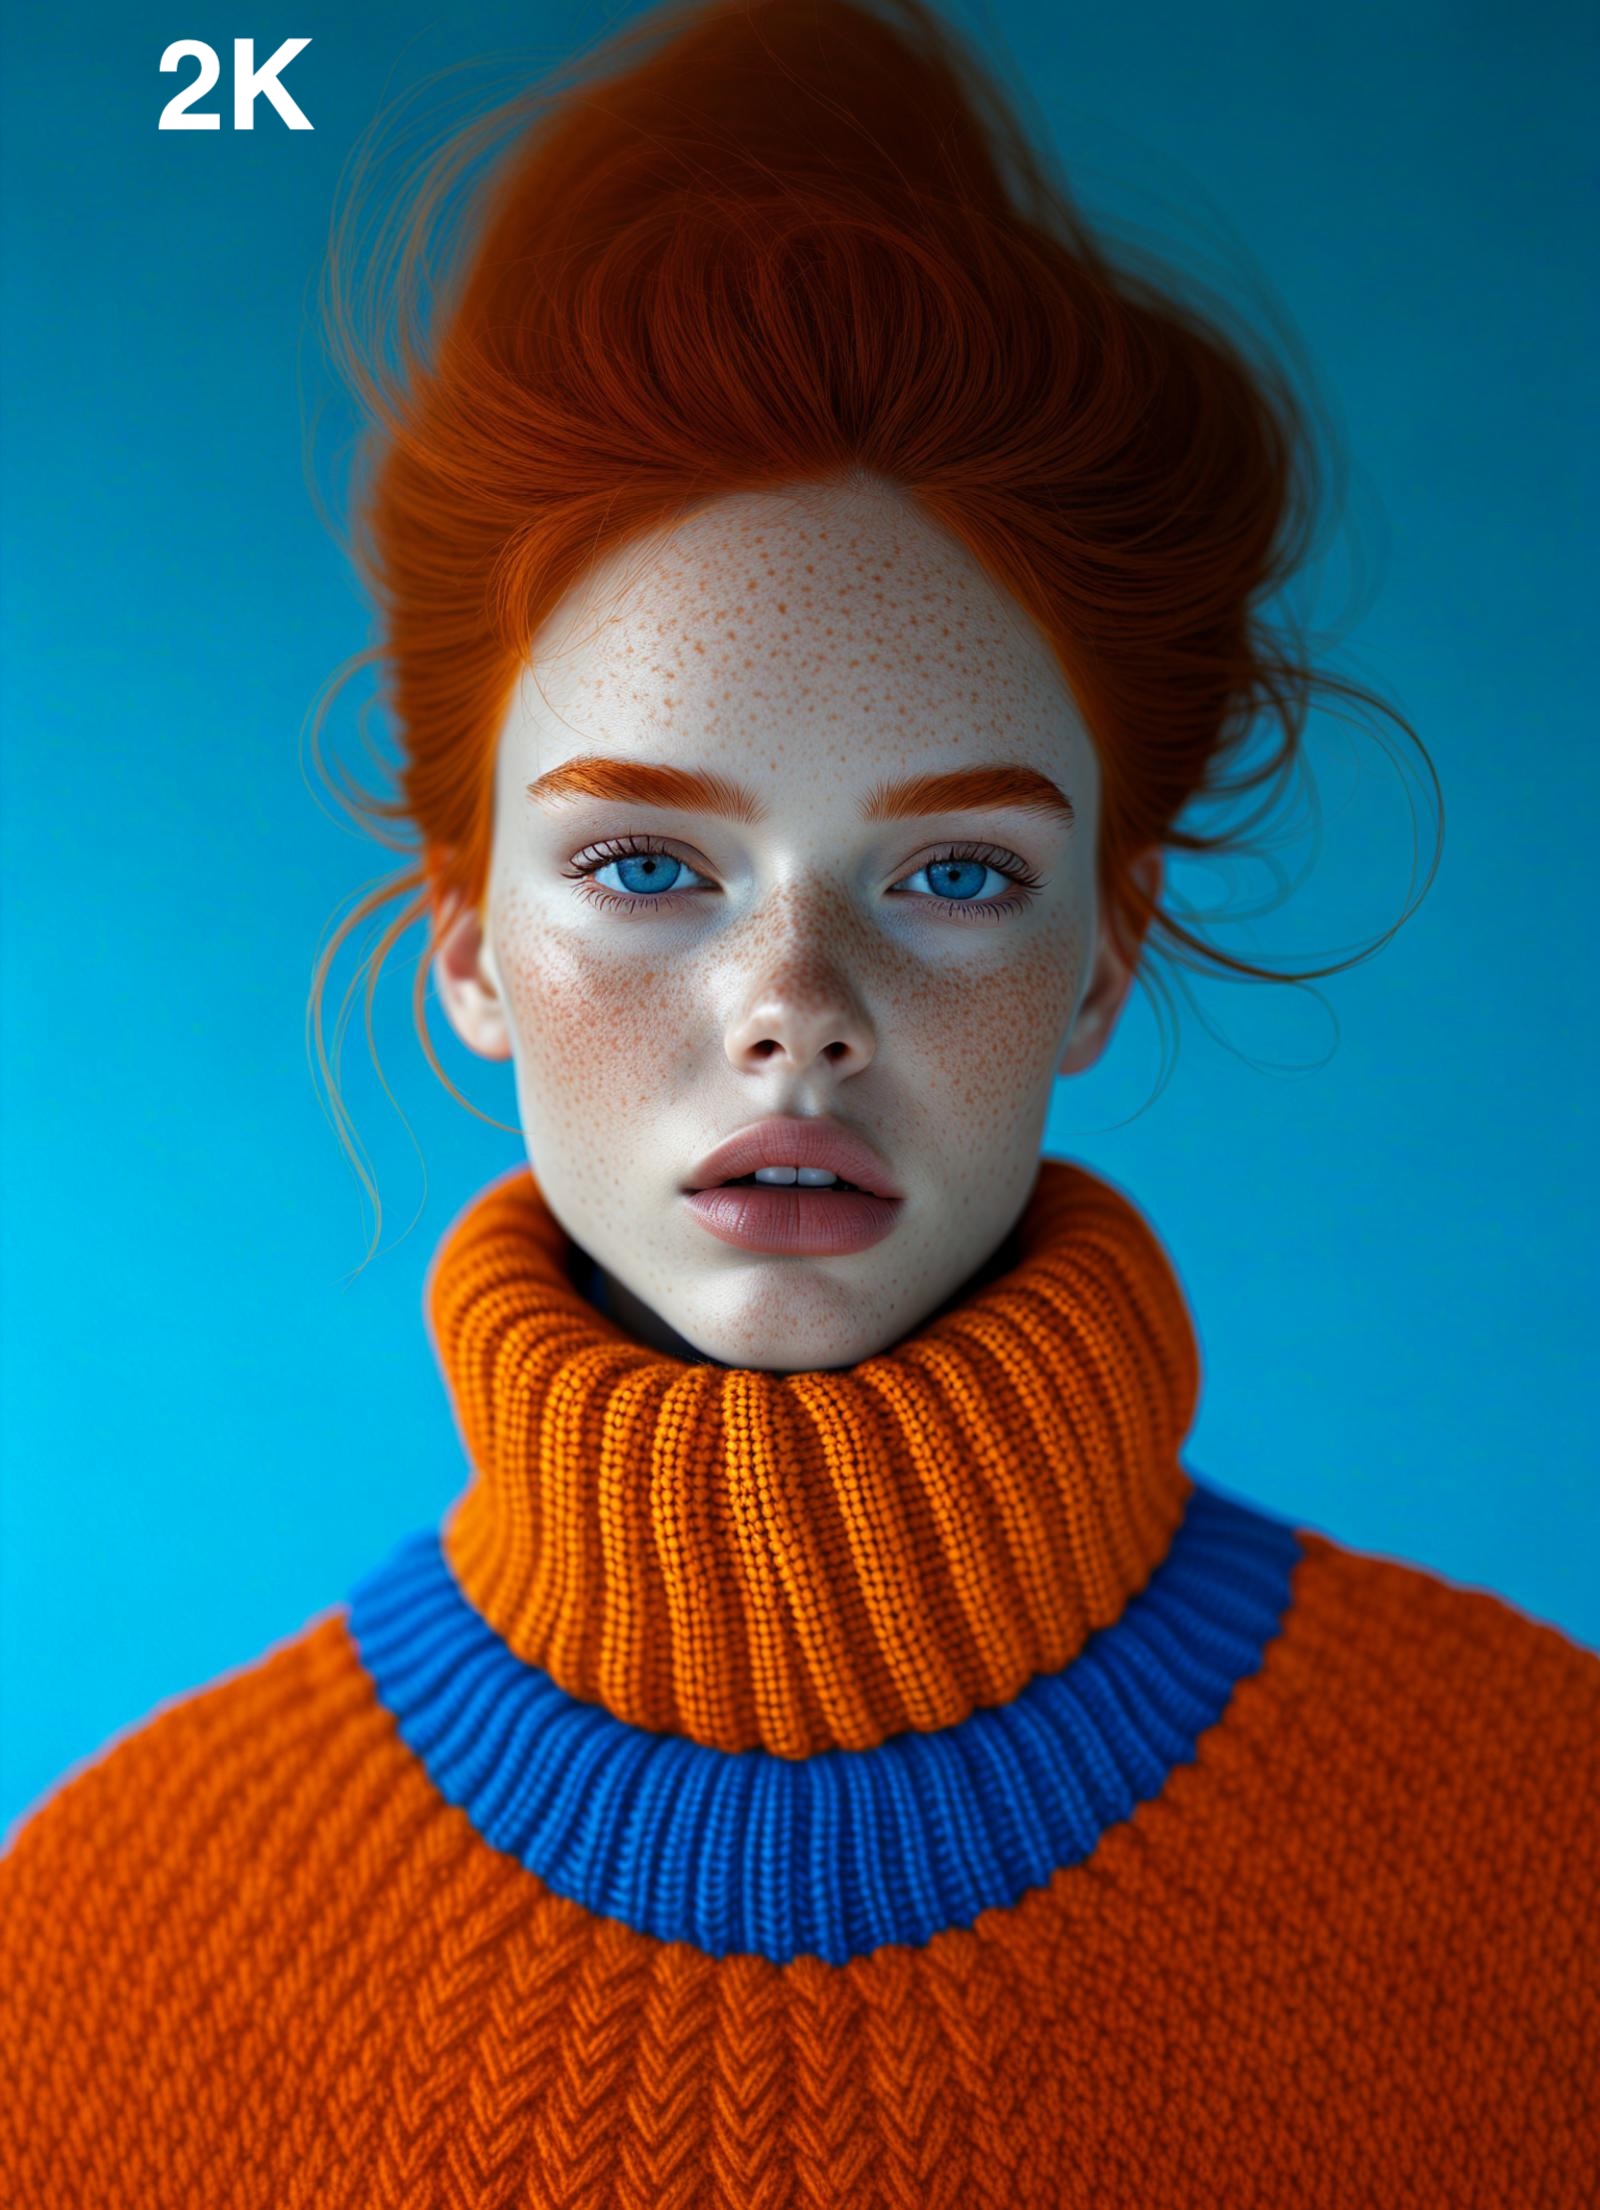 | 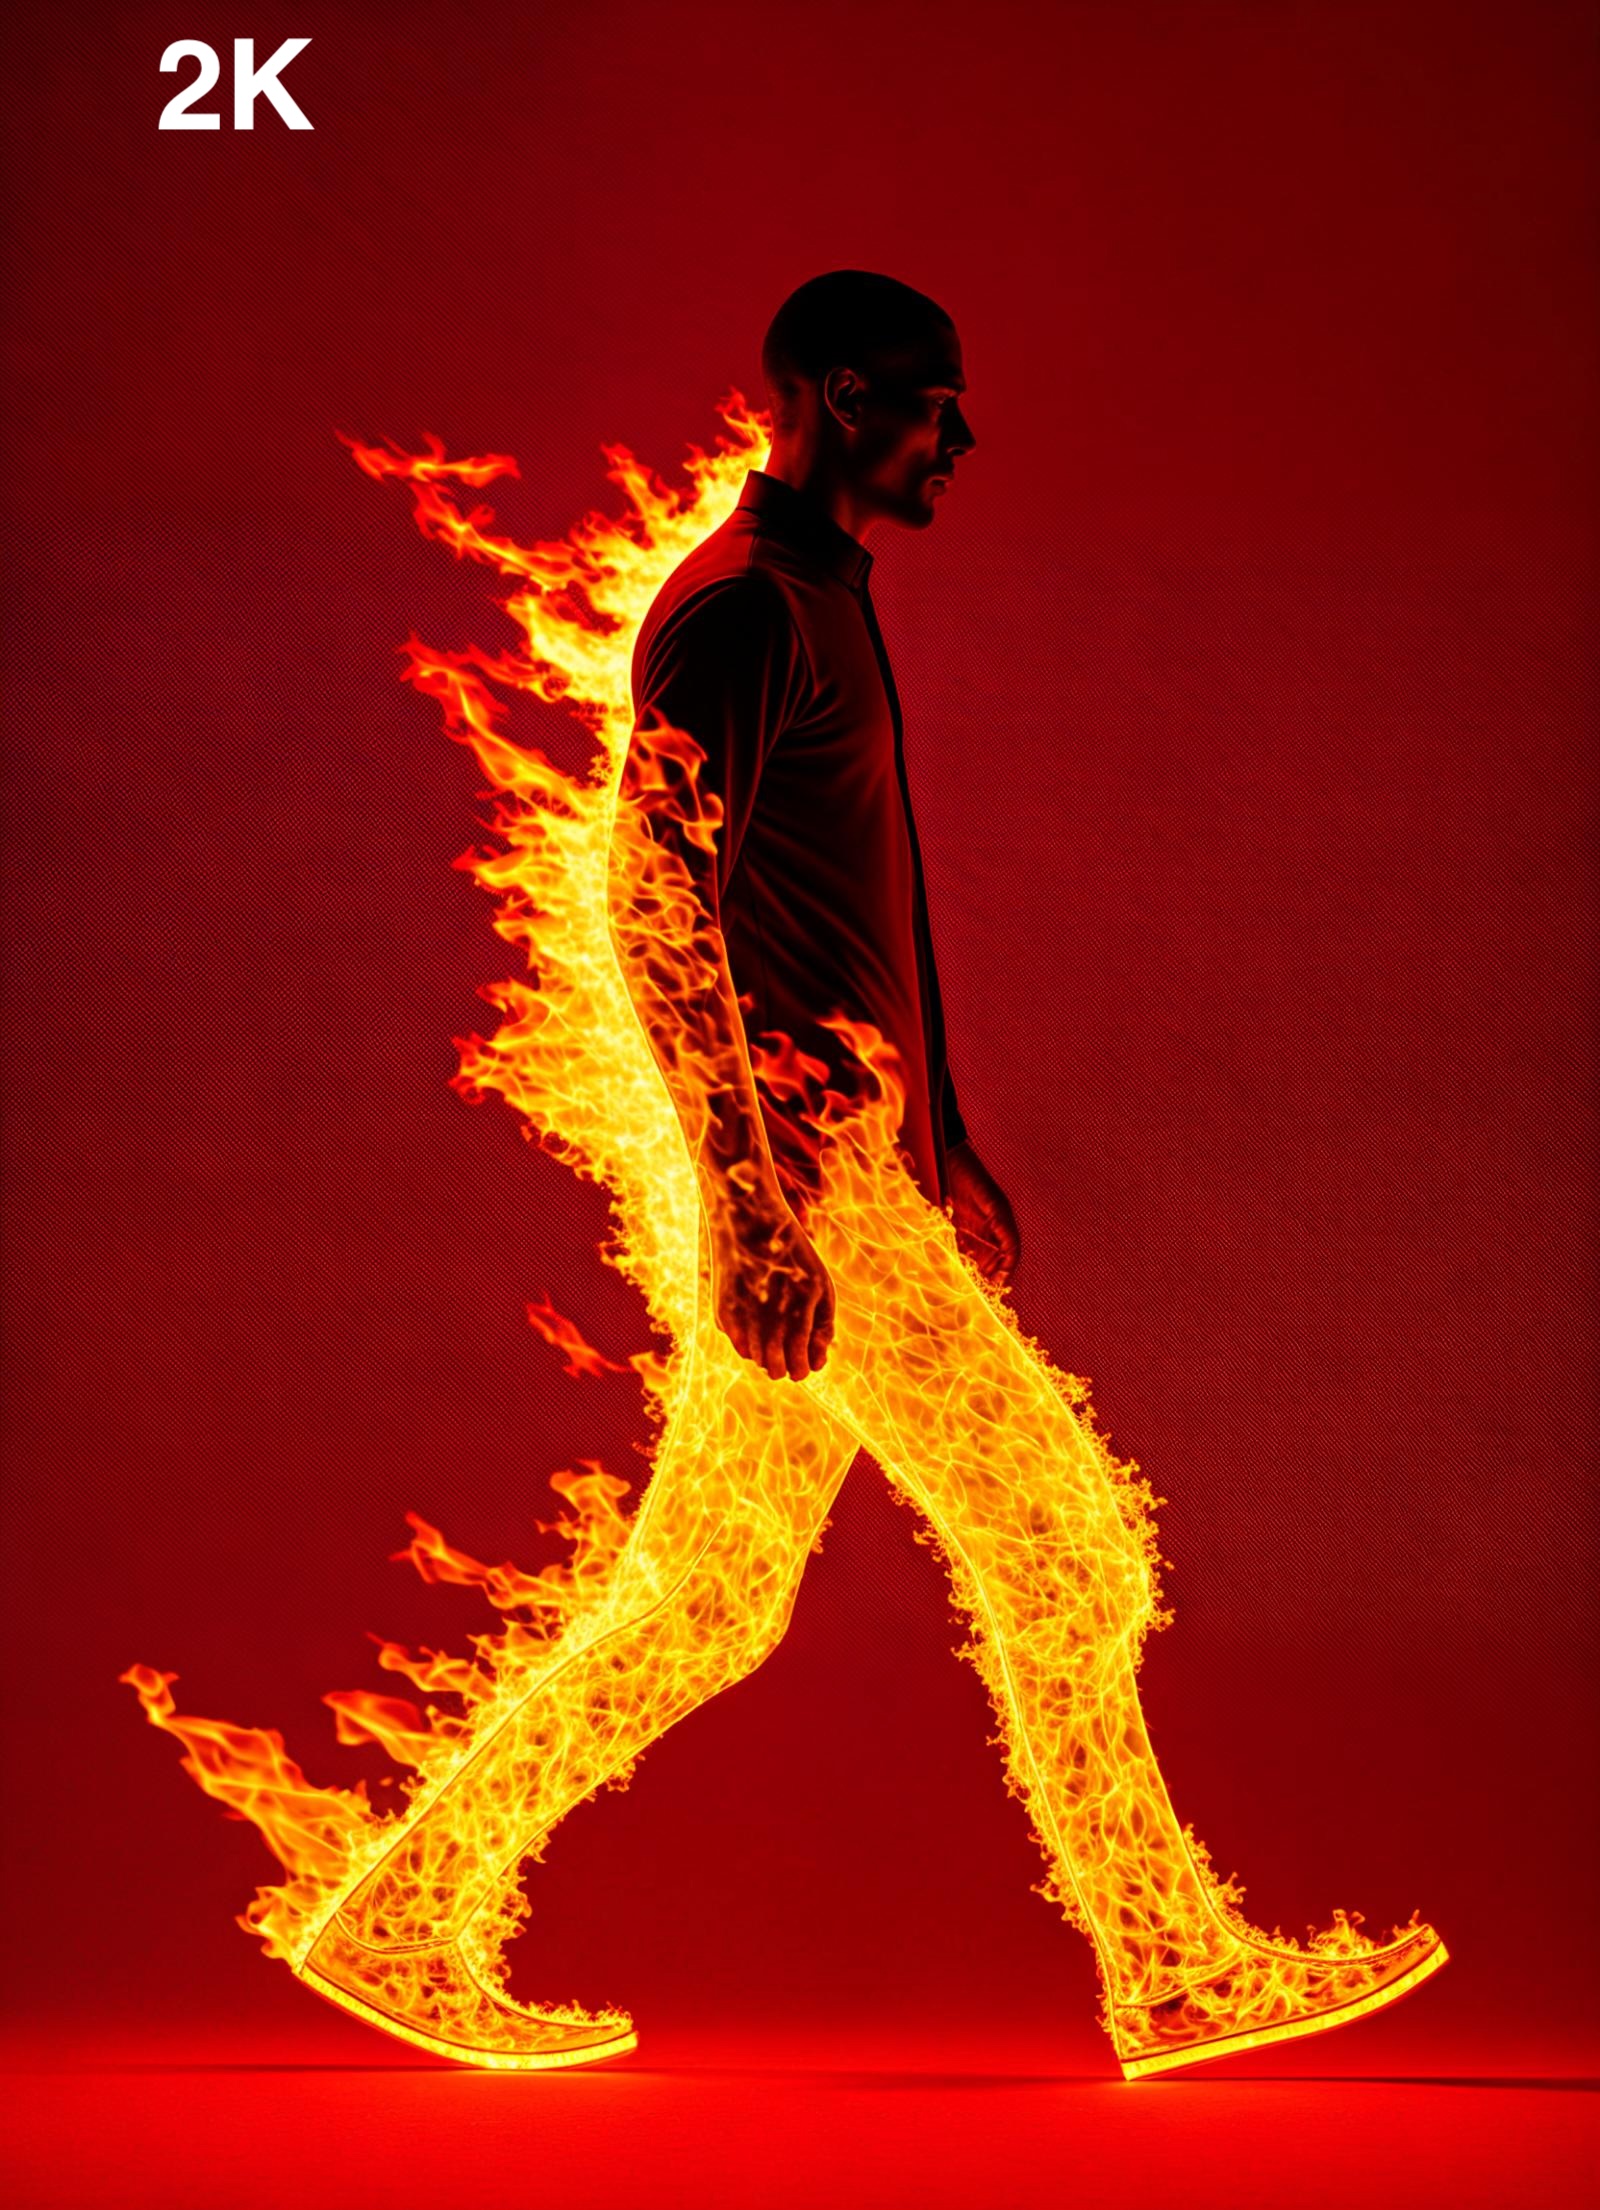 | 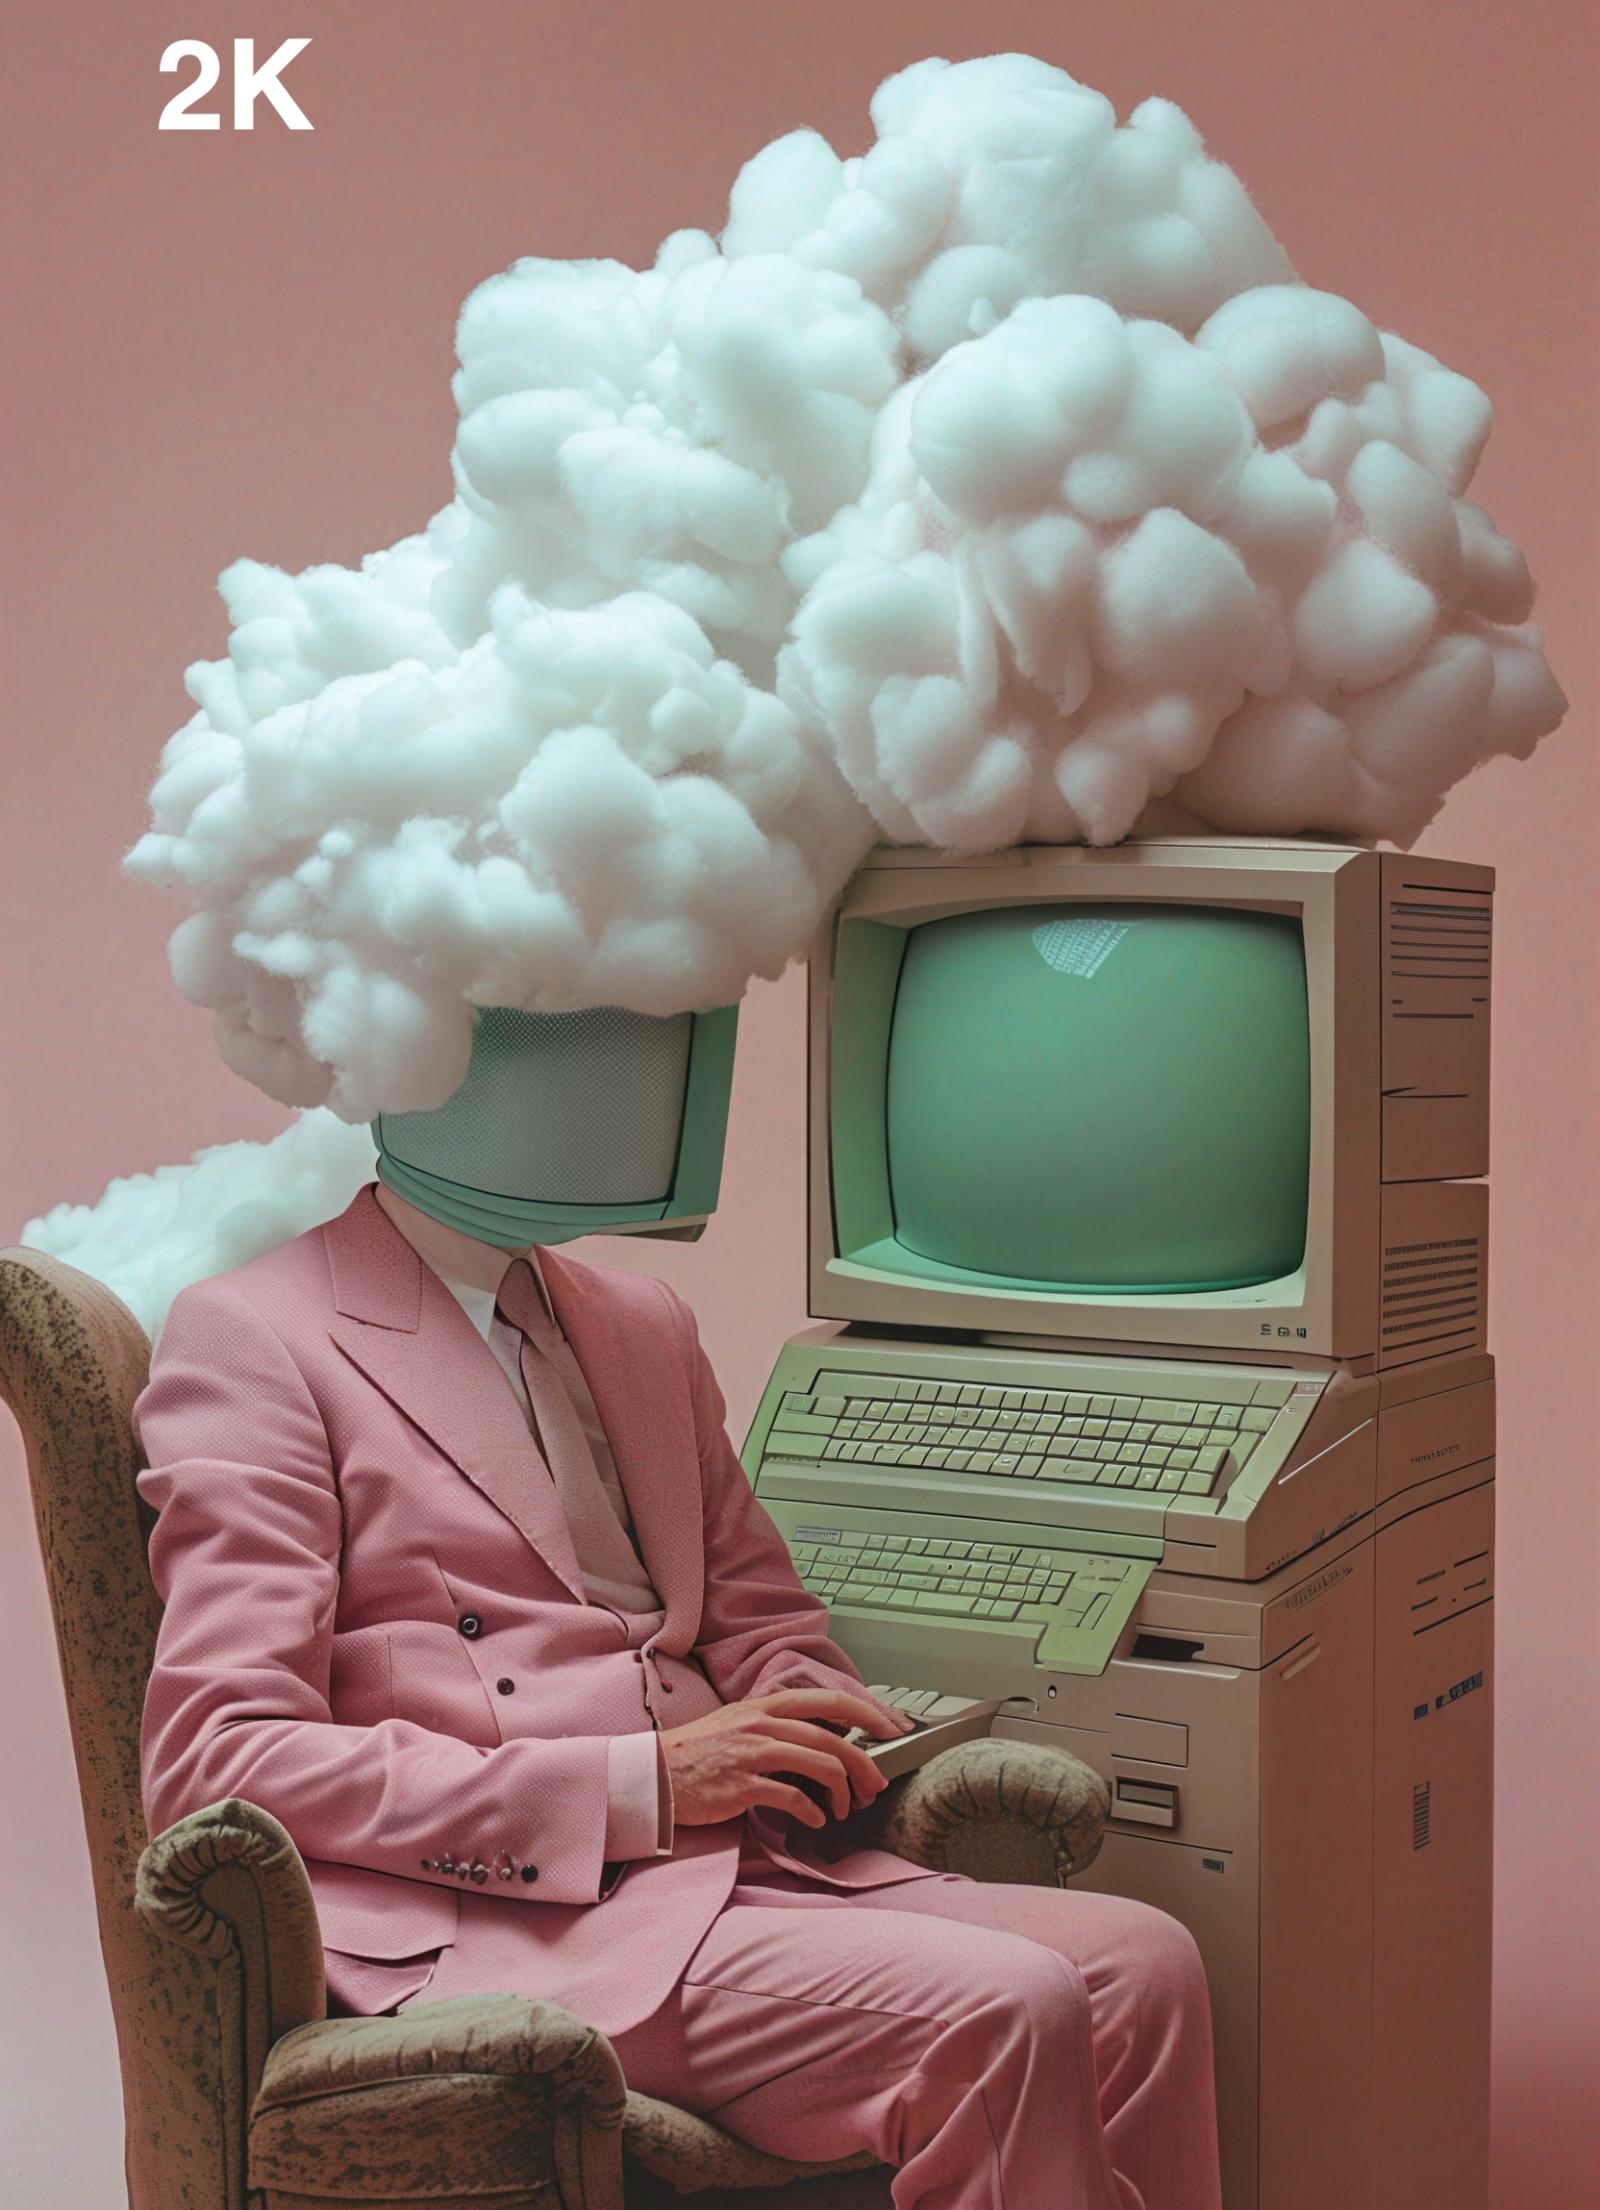 | 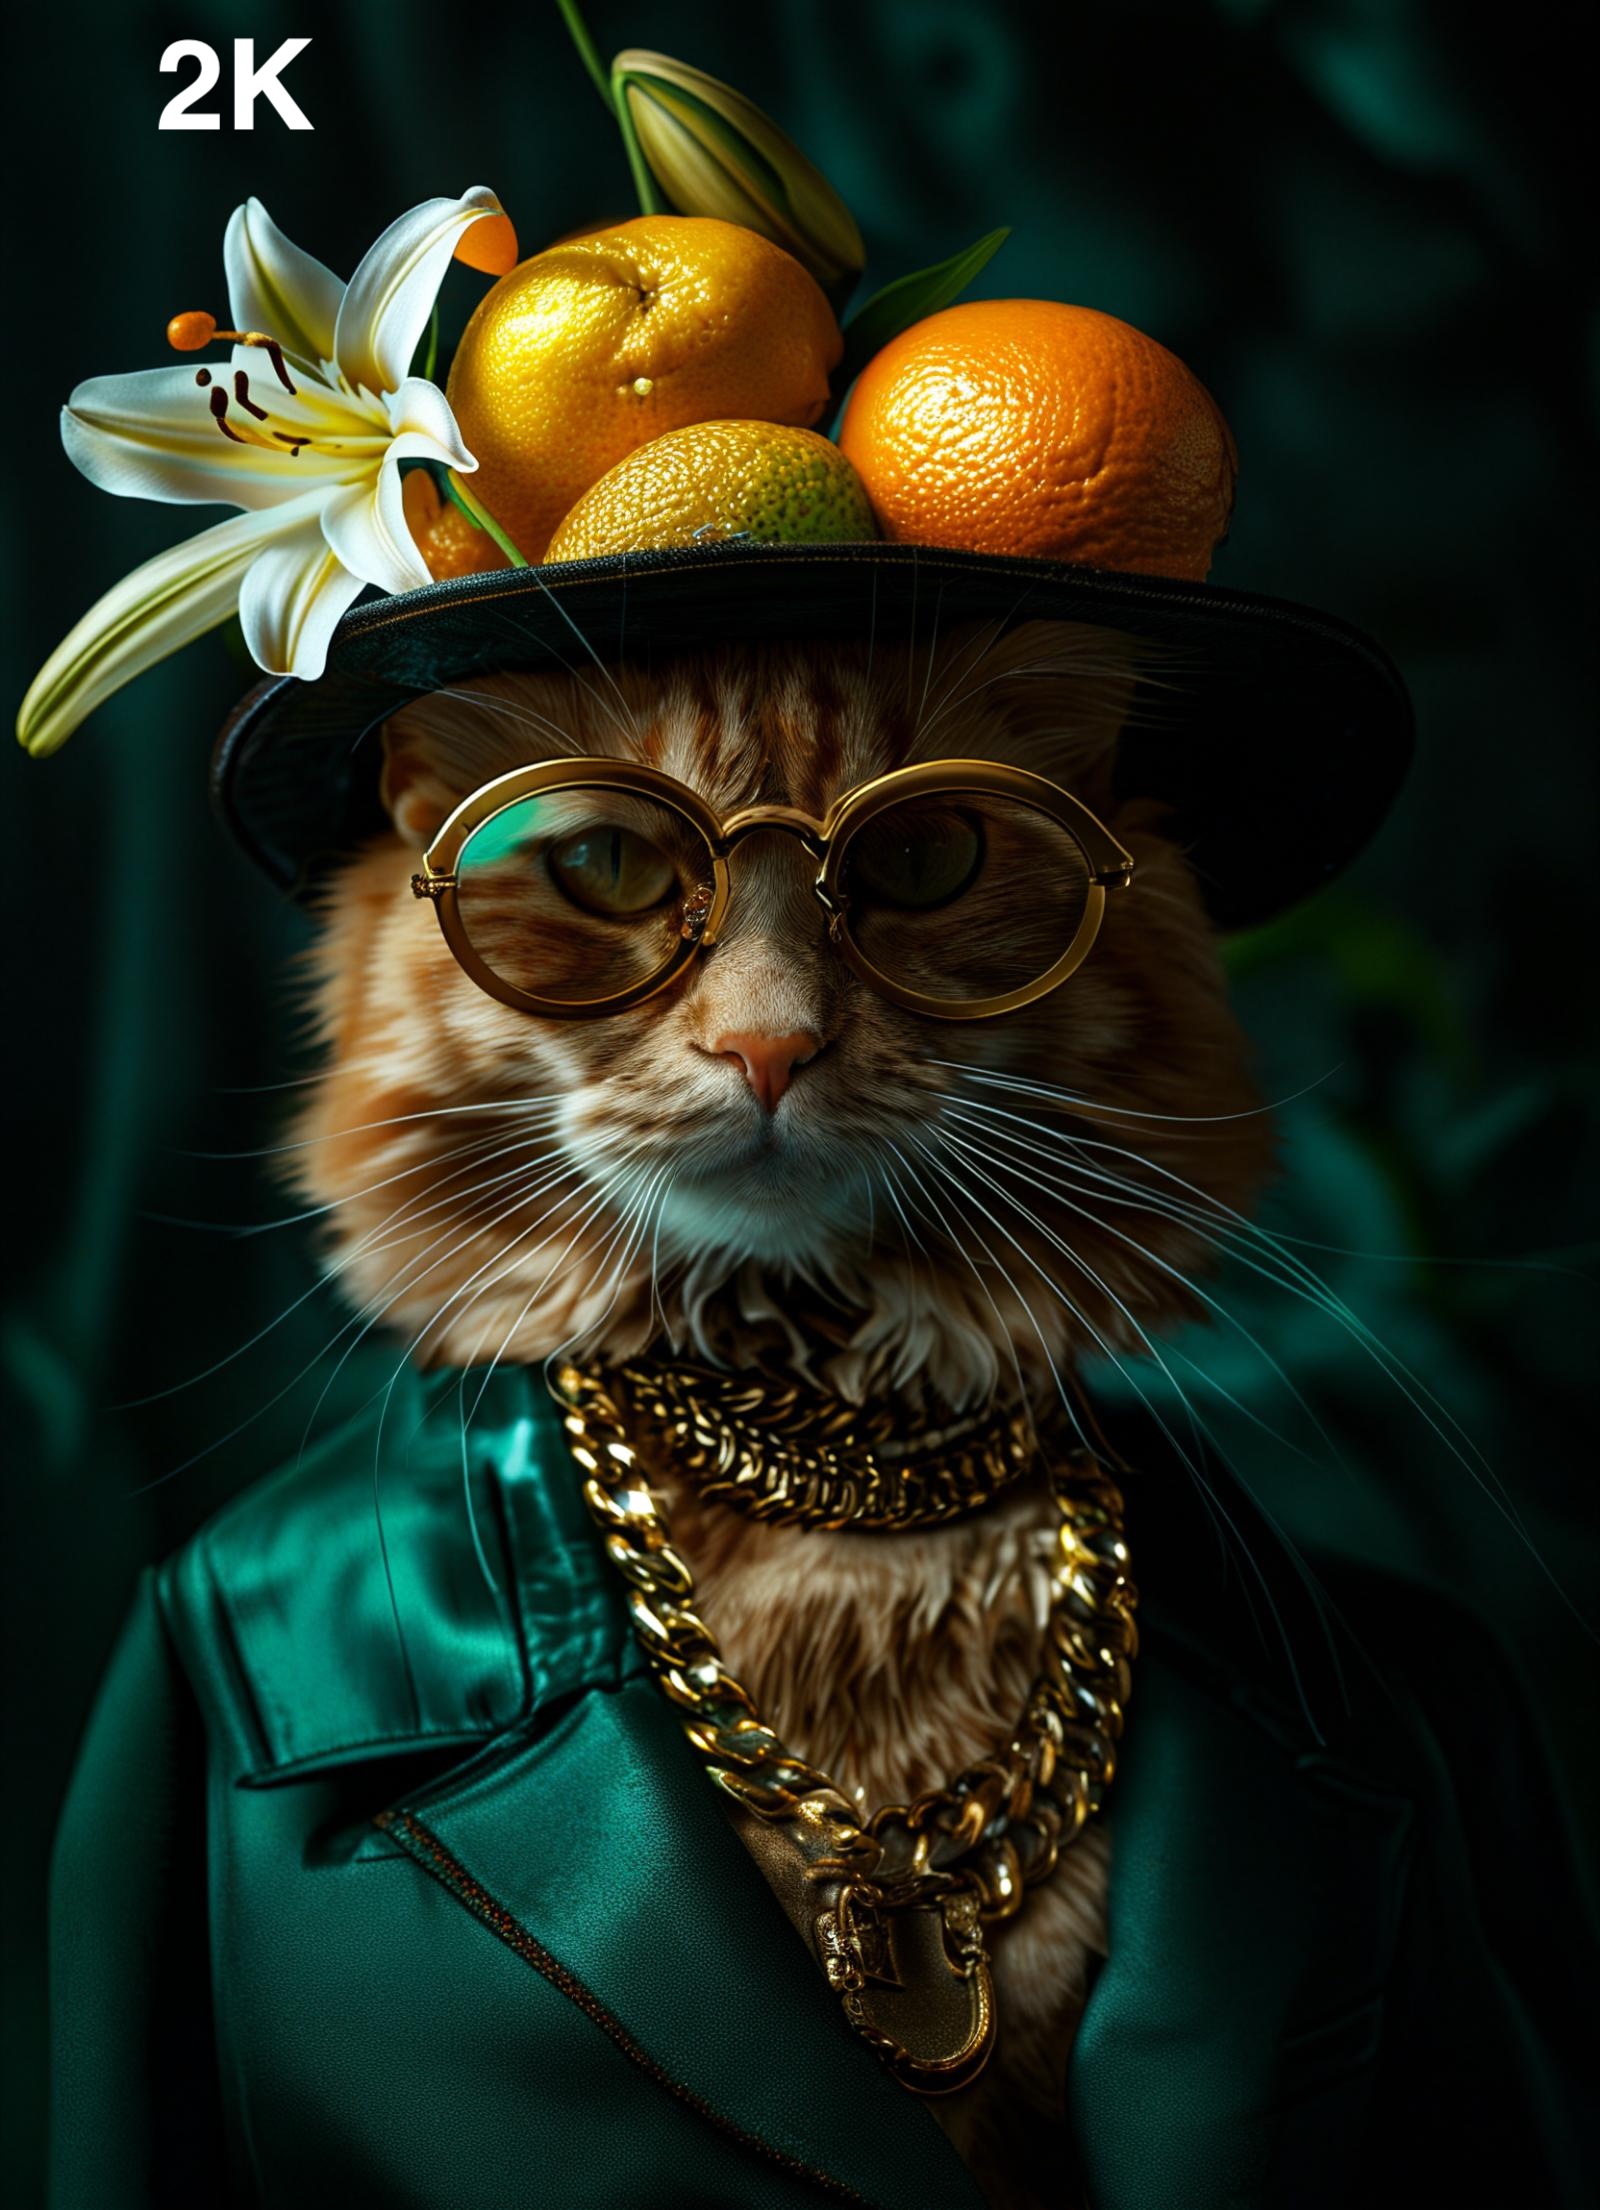 |
|---|---|---|---|---|
| prompt | A model wearing an orange and blue sweater with a knitted pattern, detailed face, ginger hair color, blue background, shot in the style of Tim Walker | A studio shot of a figure composed of vivid , realistic flames walking in side profile, no face, with flames trailing naturally behind, against an intense red background, Captured by Helmut Newton, with a Hasselblad H6D and an 80mm f/2.8 lens at f/5.6, 1/125s, ISO 400. The flames are intense and detailed, with a natural, realistic texture that emphasizes the movement. HD quality, natural look | A surreal photograph of a man with his head covered in large , fluffy cotton clouds, sitting in an armchair facing the camera and using an old computer from the early 20th century. The computer has a green screen monitor. He is wearing a pink suit, and the overall scene has a soft, pastel color palette with a retro futuristic, 1970s vibe | highend portrait of a cool ginger cat , high fashion Style with crazy glasses and stylish clothes and luxury necklace of jeweleries, hat consisting of lilies, oranges and lemons, color: dark green and gold, background: dark and luxury, hyper detailled, stil: raw, cinematic light, canon, expressive and original, canon, 50 mm lens, editorial, look: expensive, mood: motivated and good vibes |
| Images | 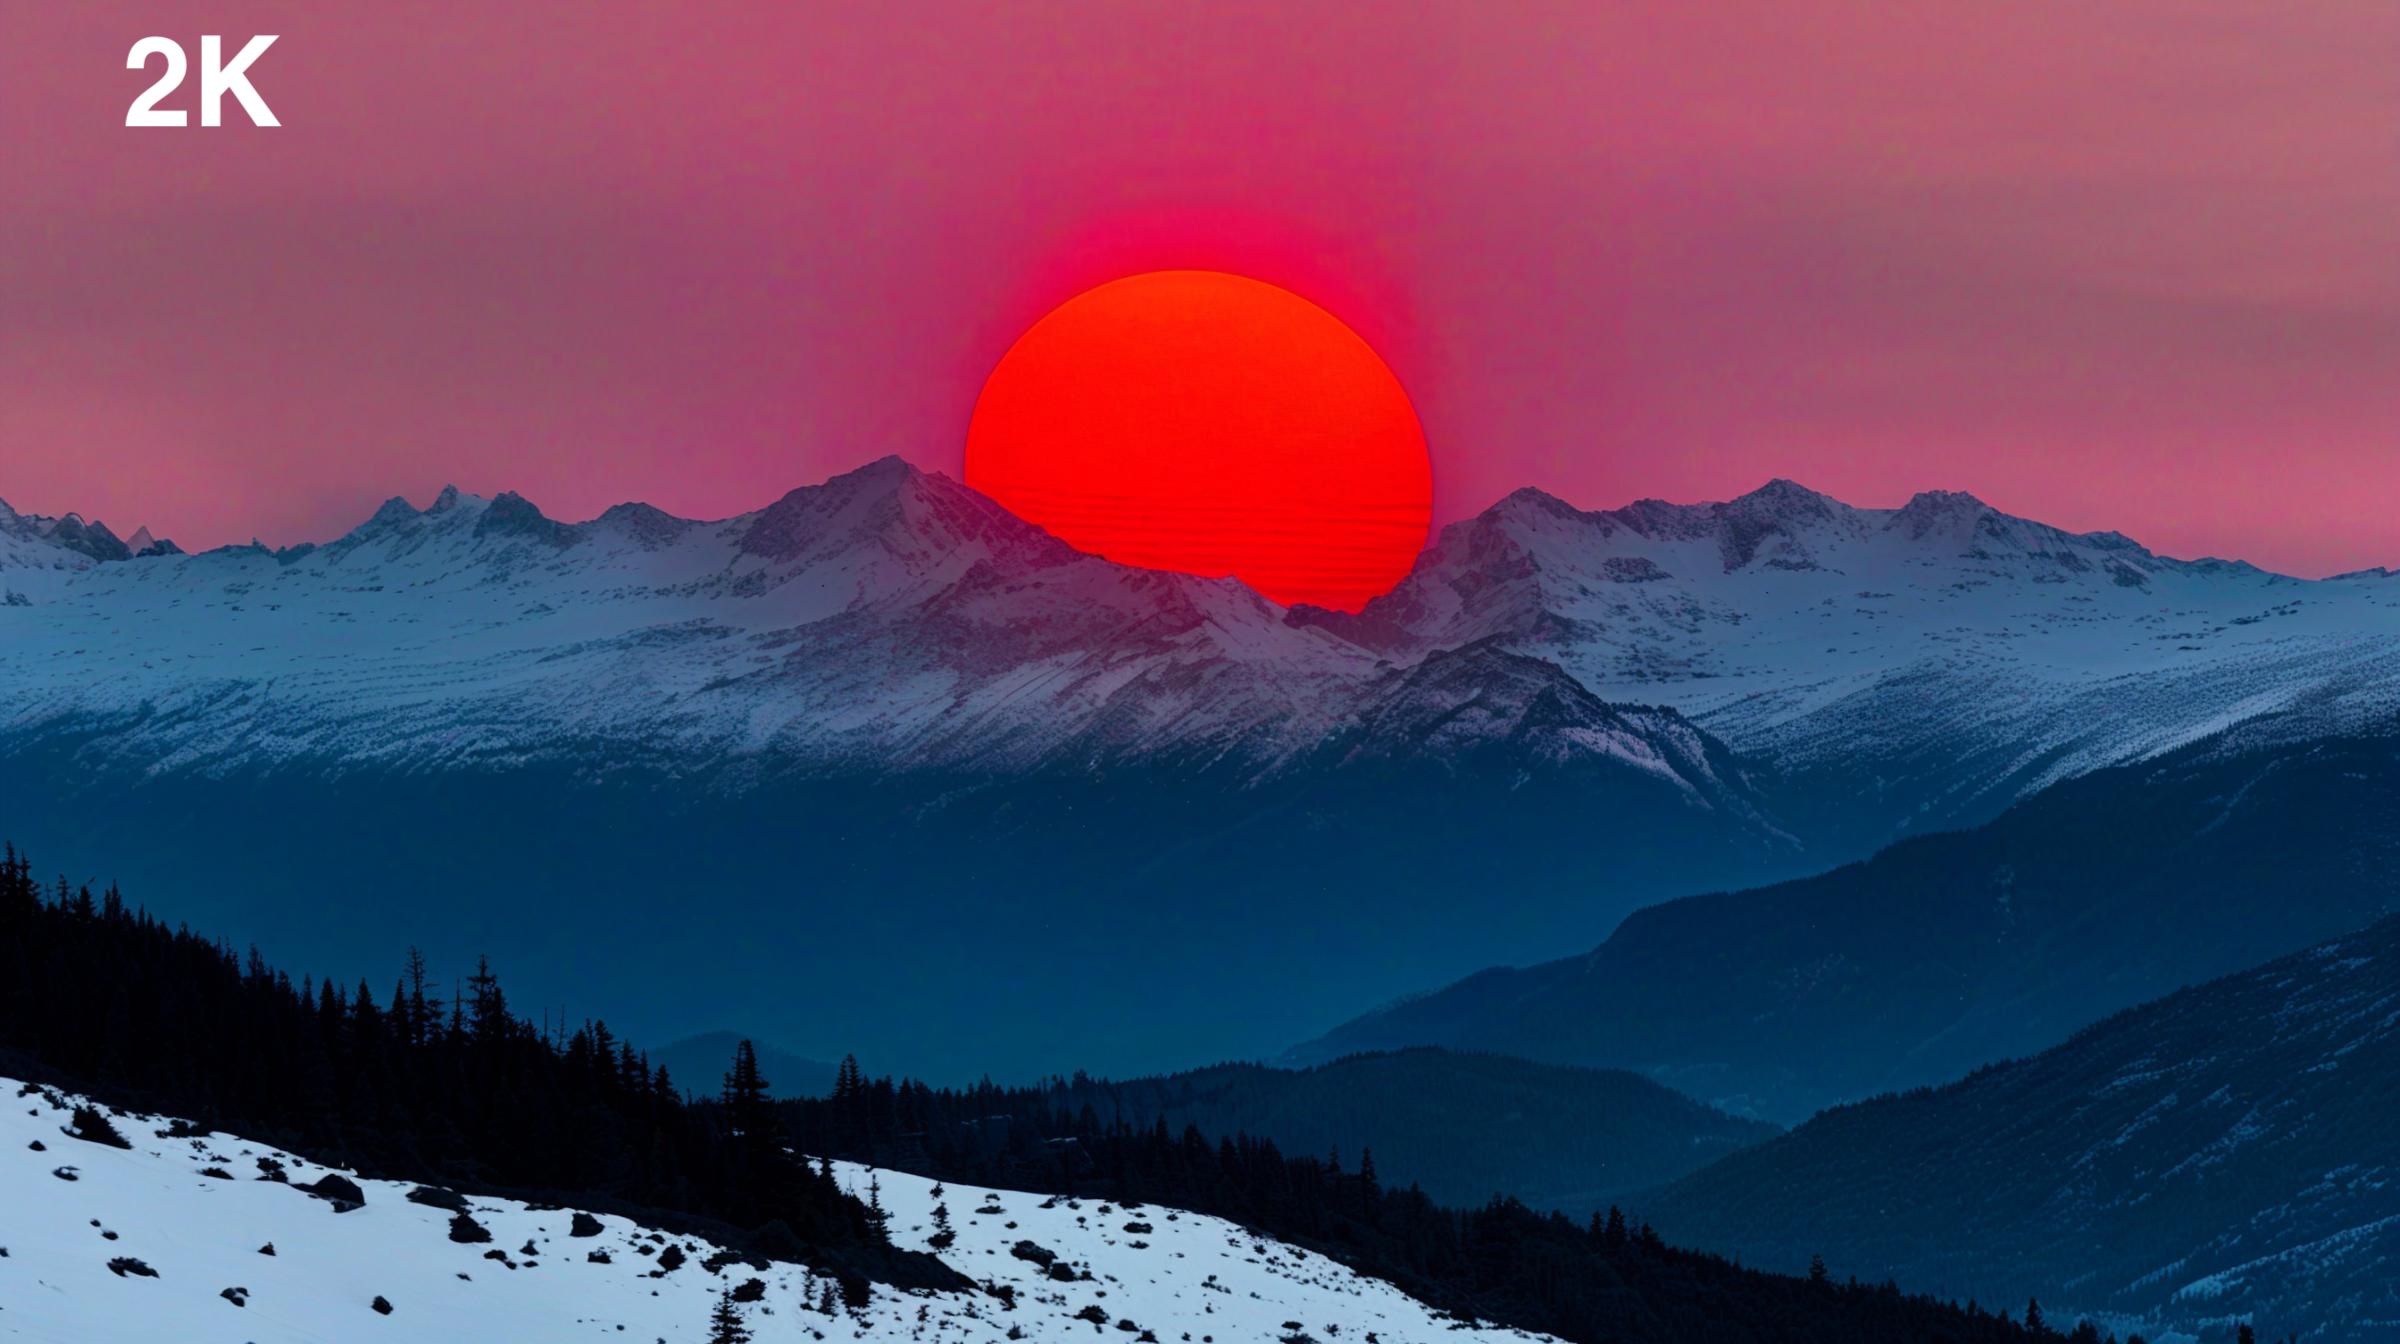 | 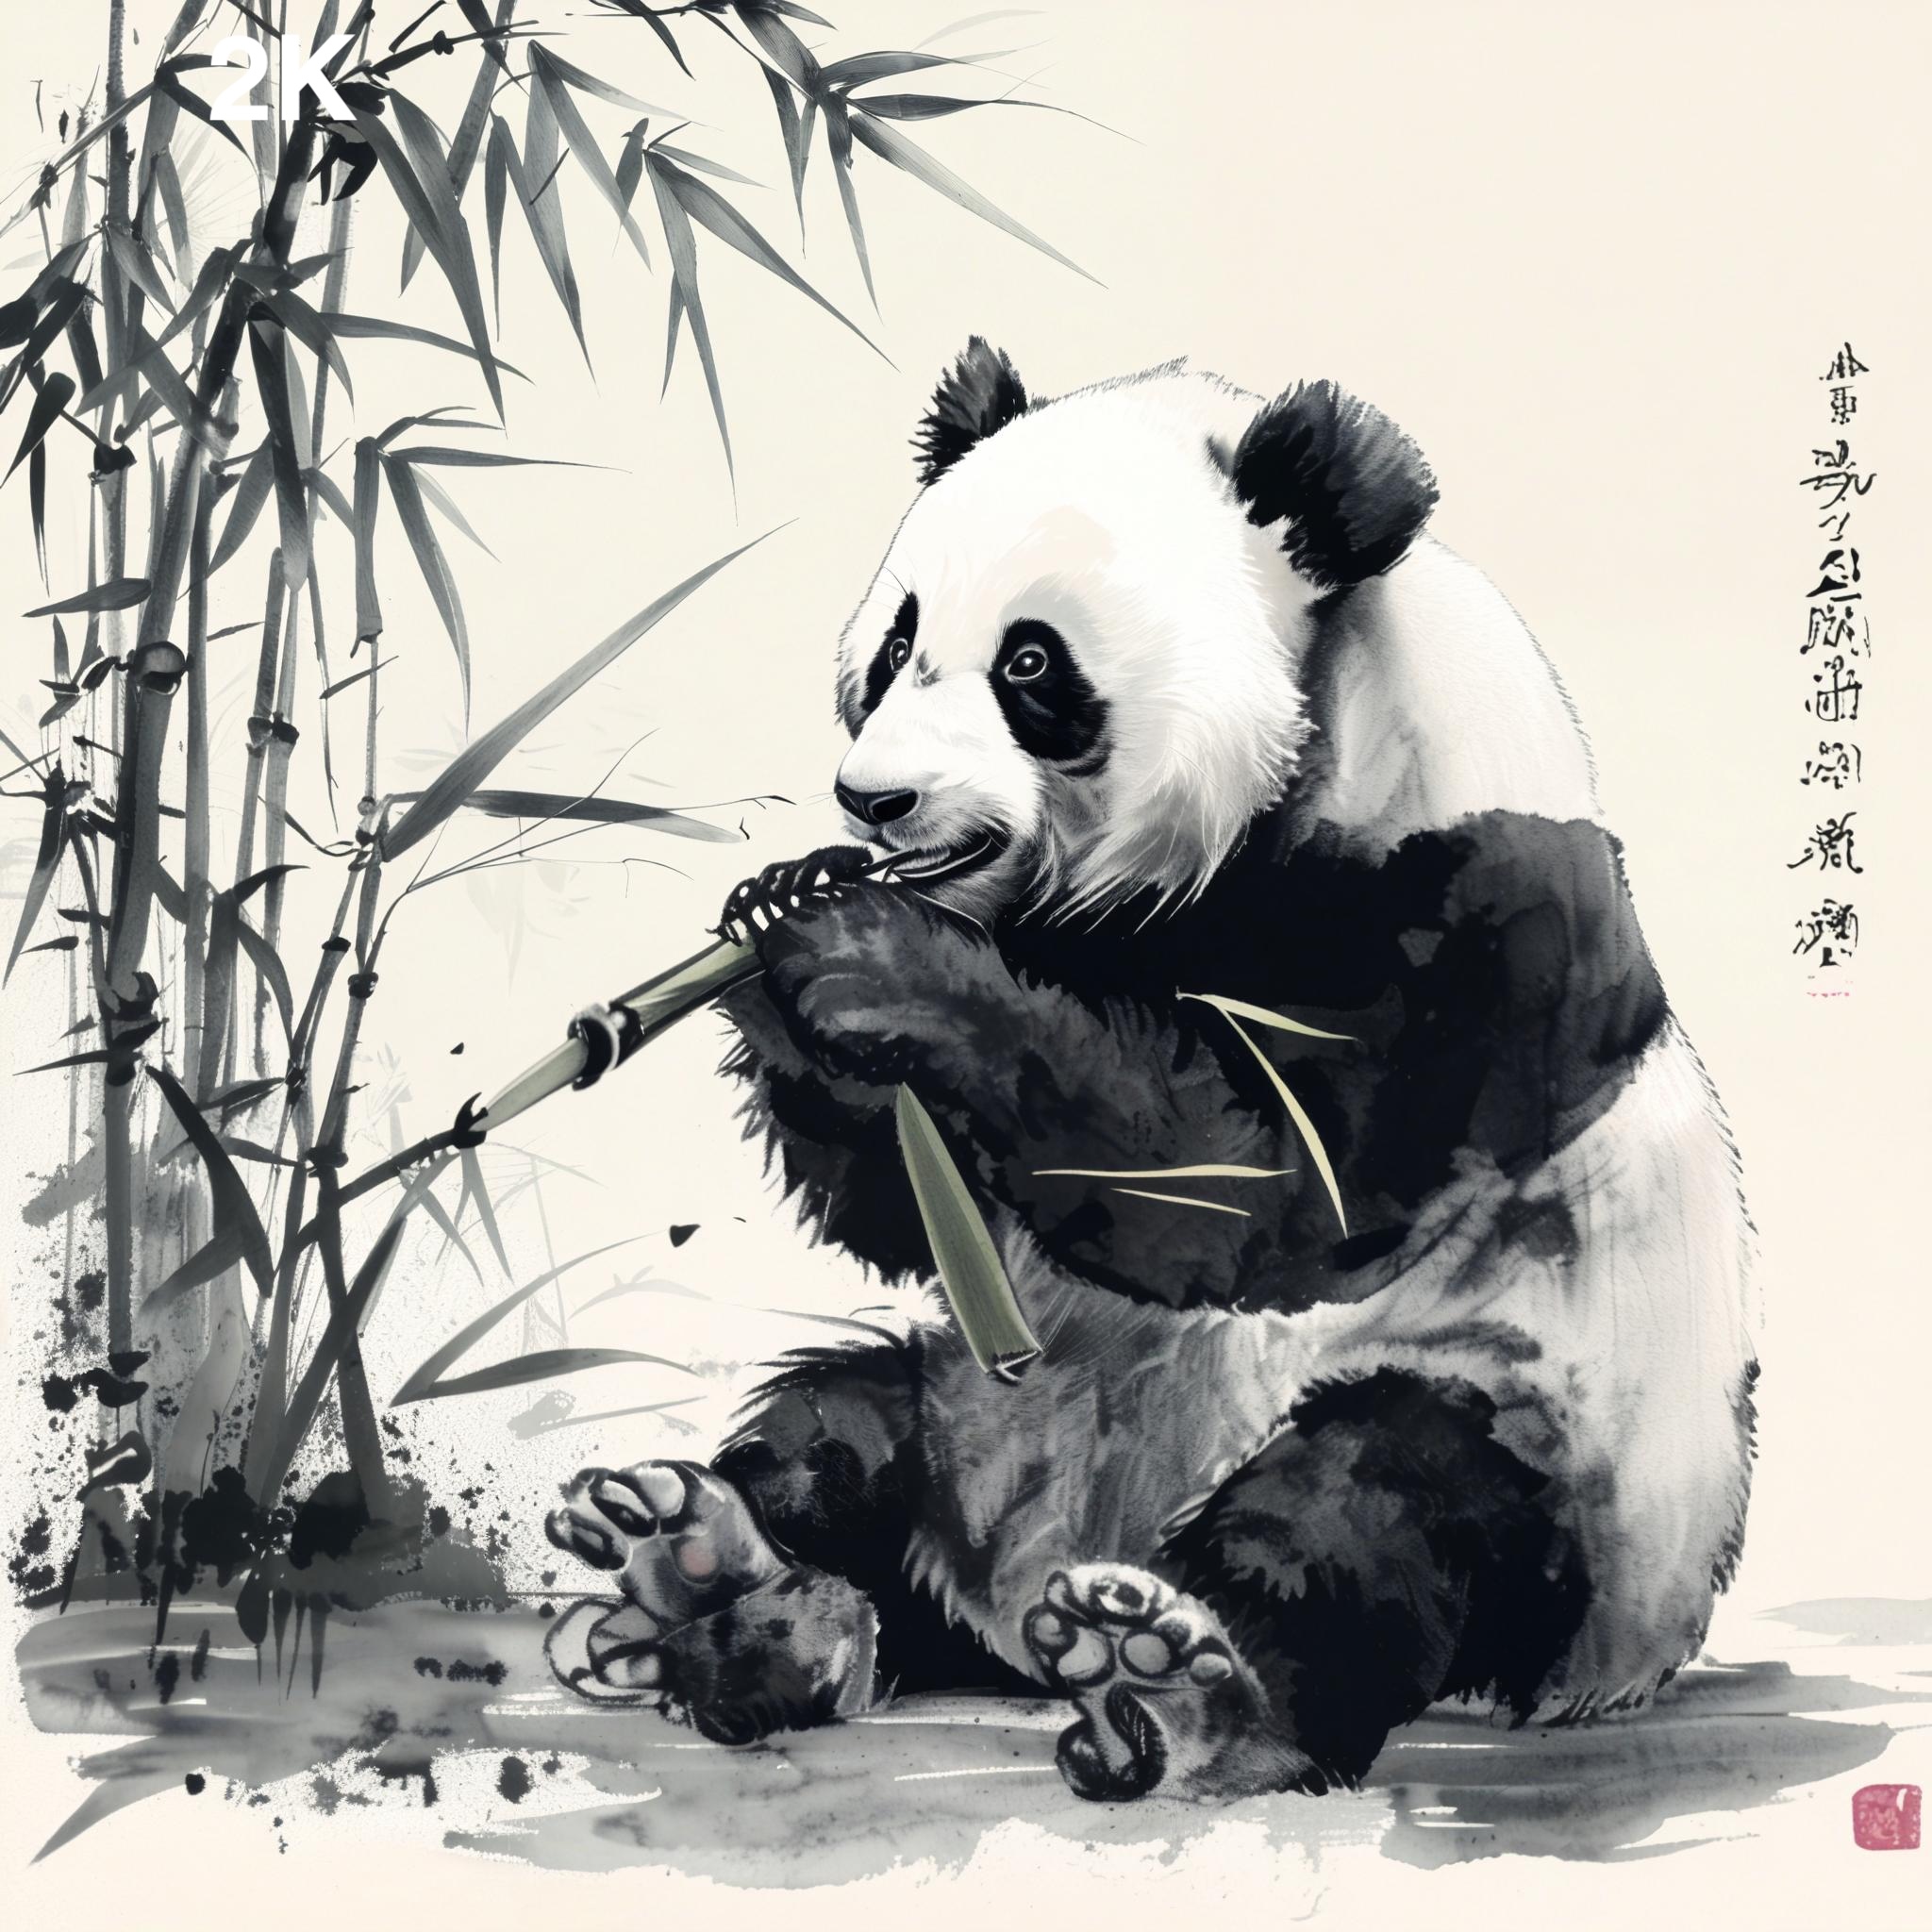 | 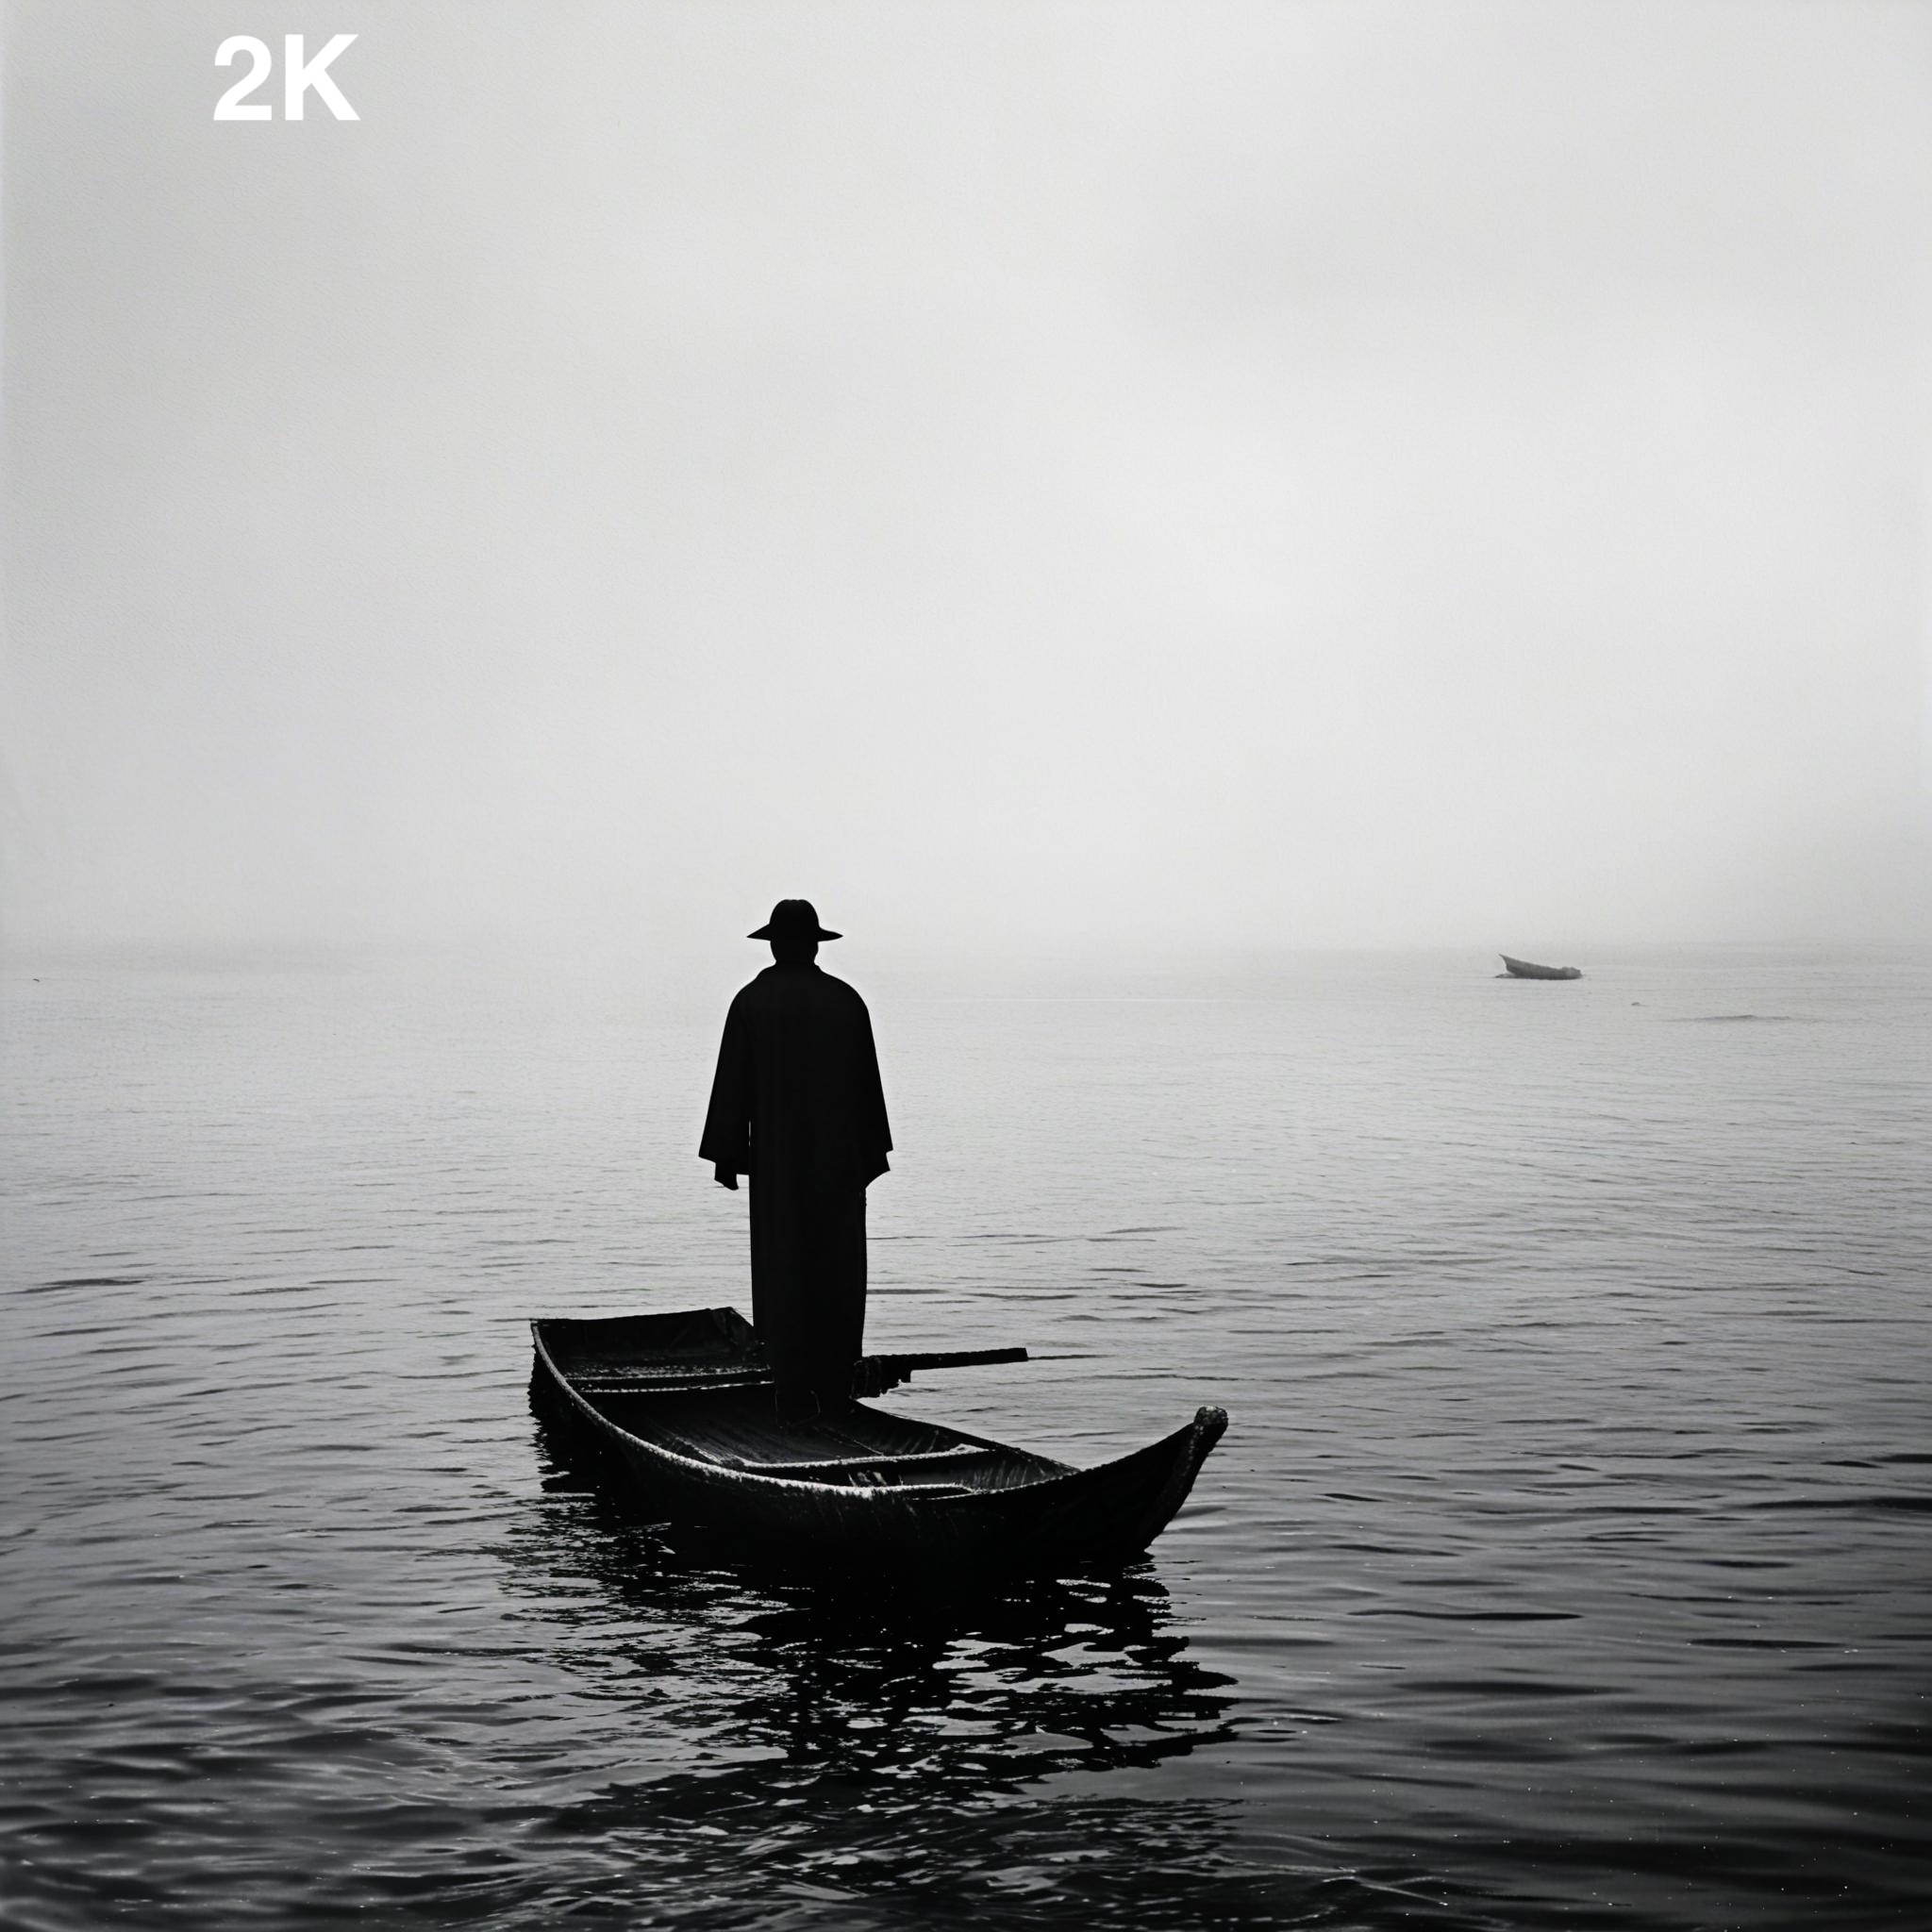 |
|---|---|---|---|
| prompt | 雪山之巅红日东升 | 一只可爱的 🐼 在吃 🎋, 水墨画风格 | 孤舟蓑笠翁 |
| Images | 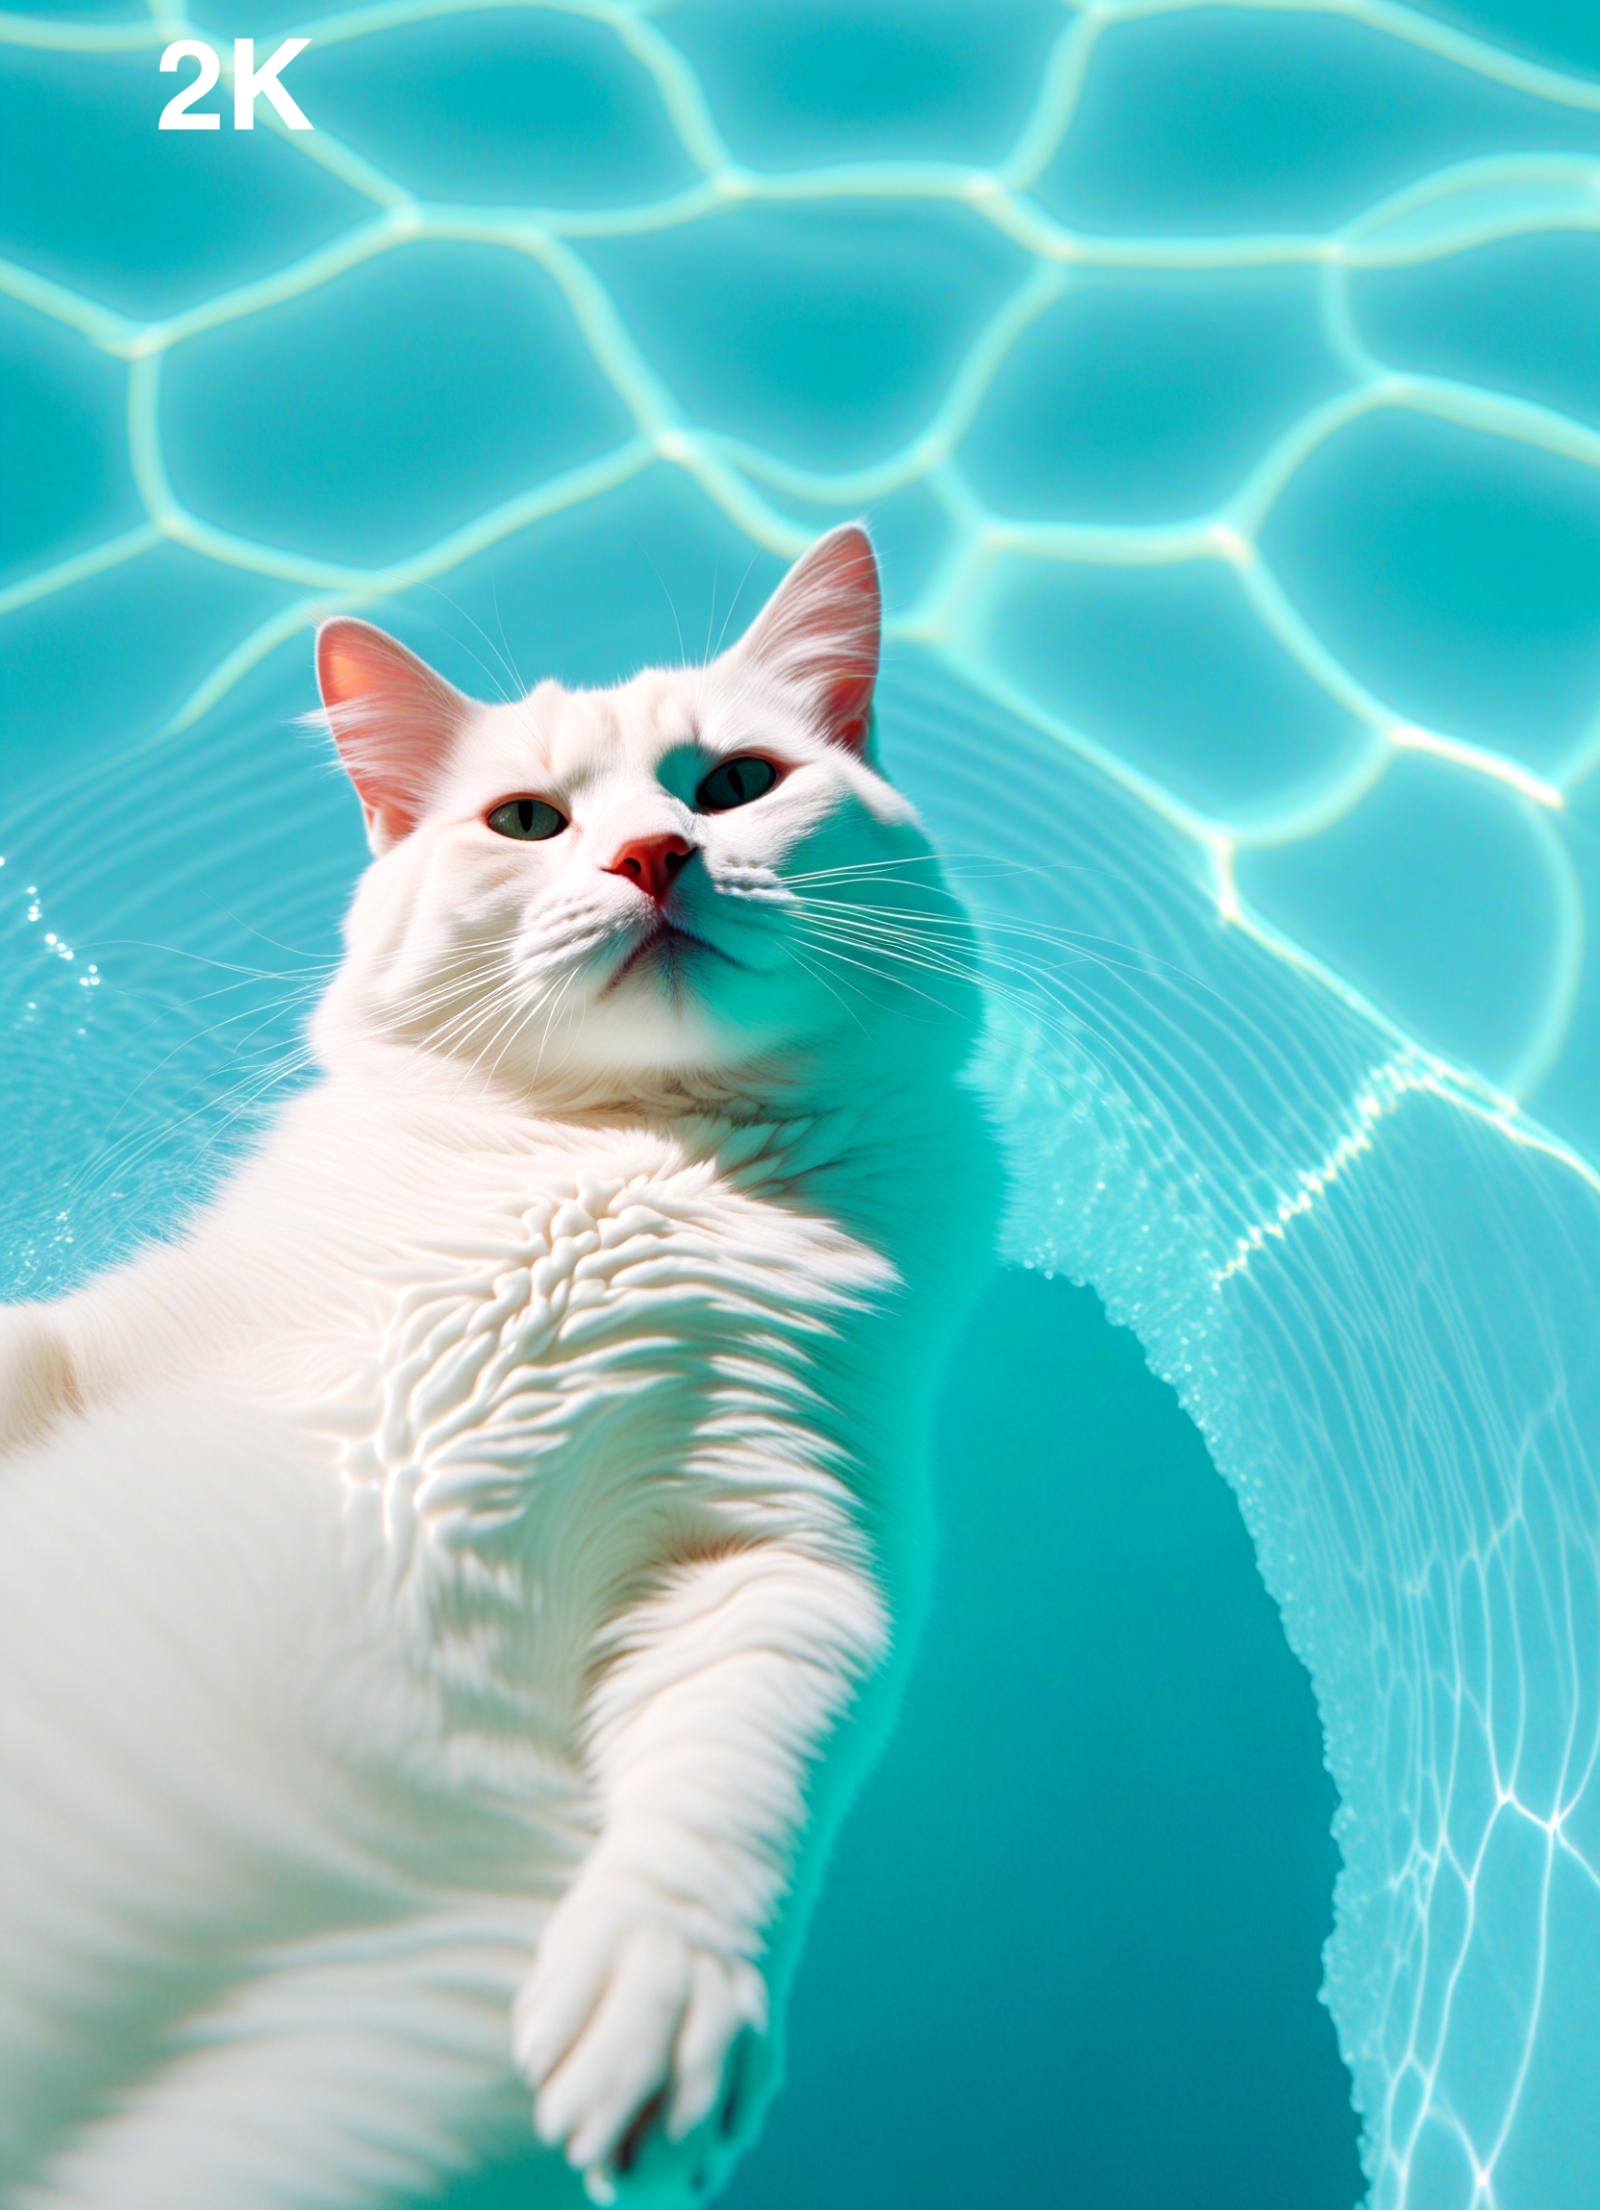 | 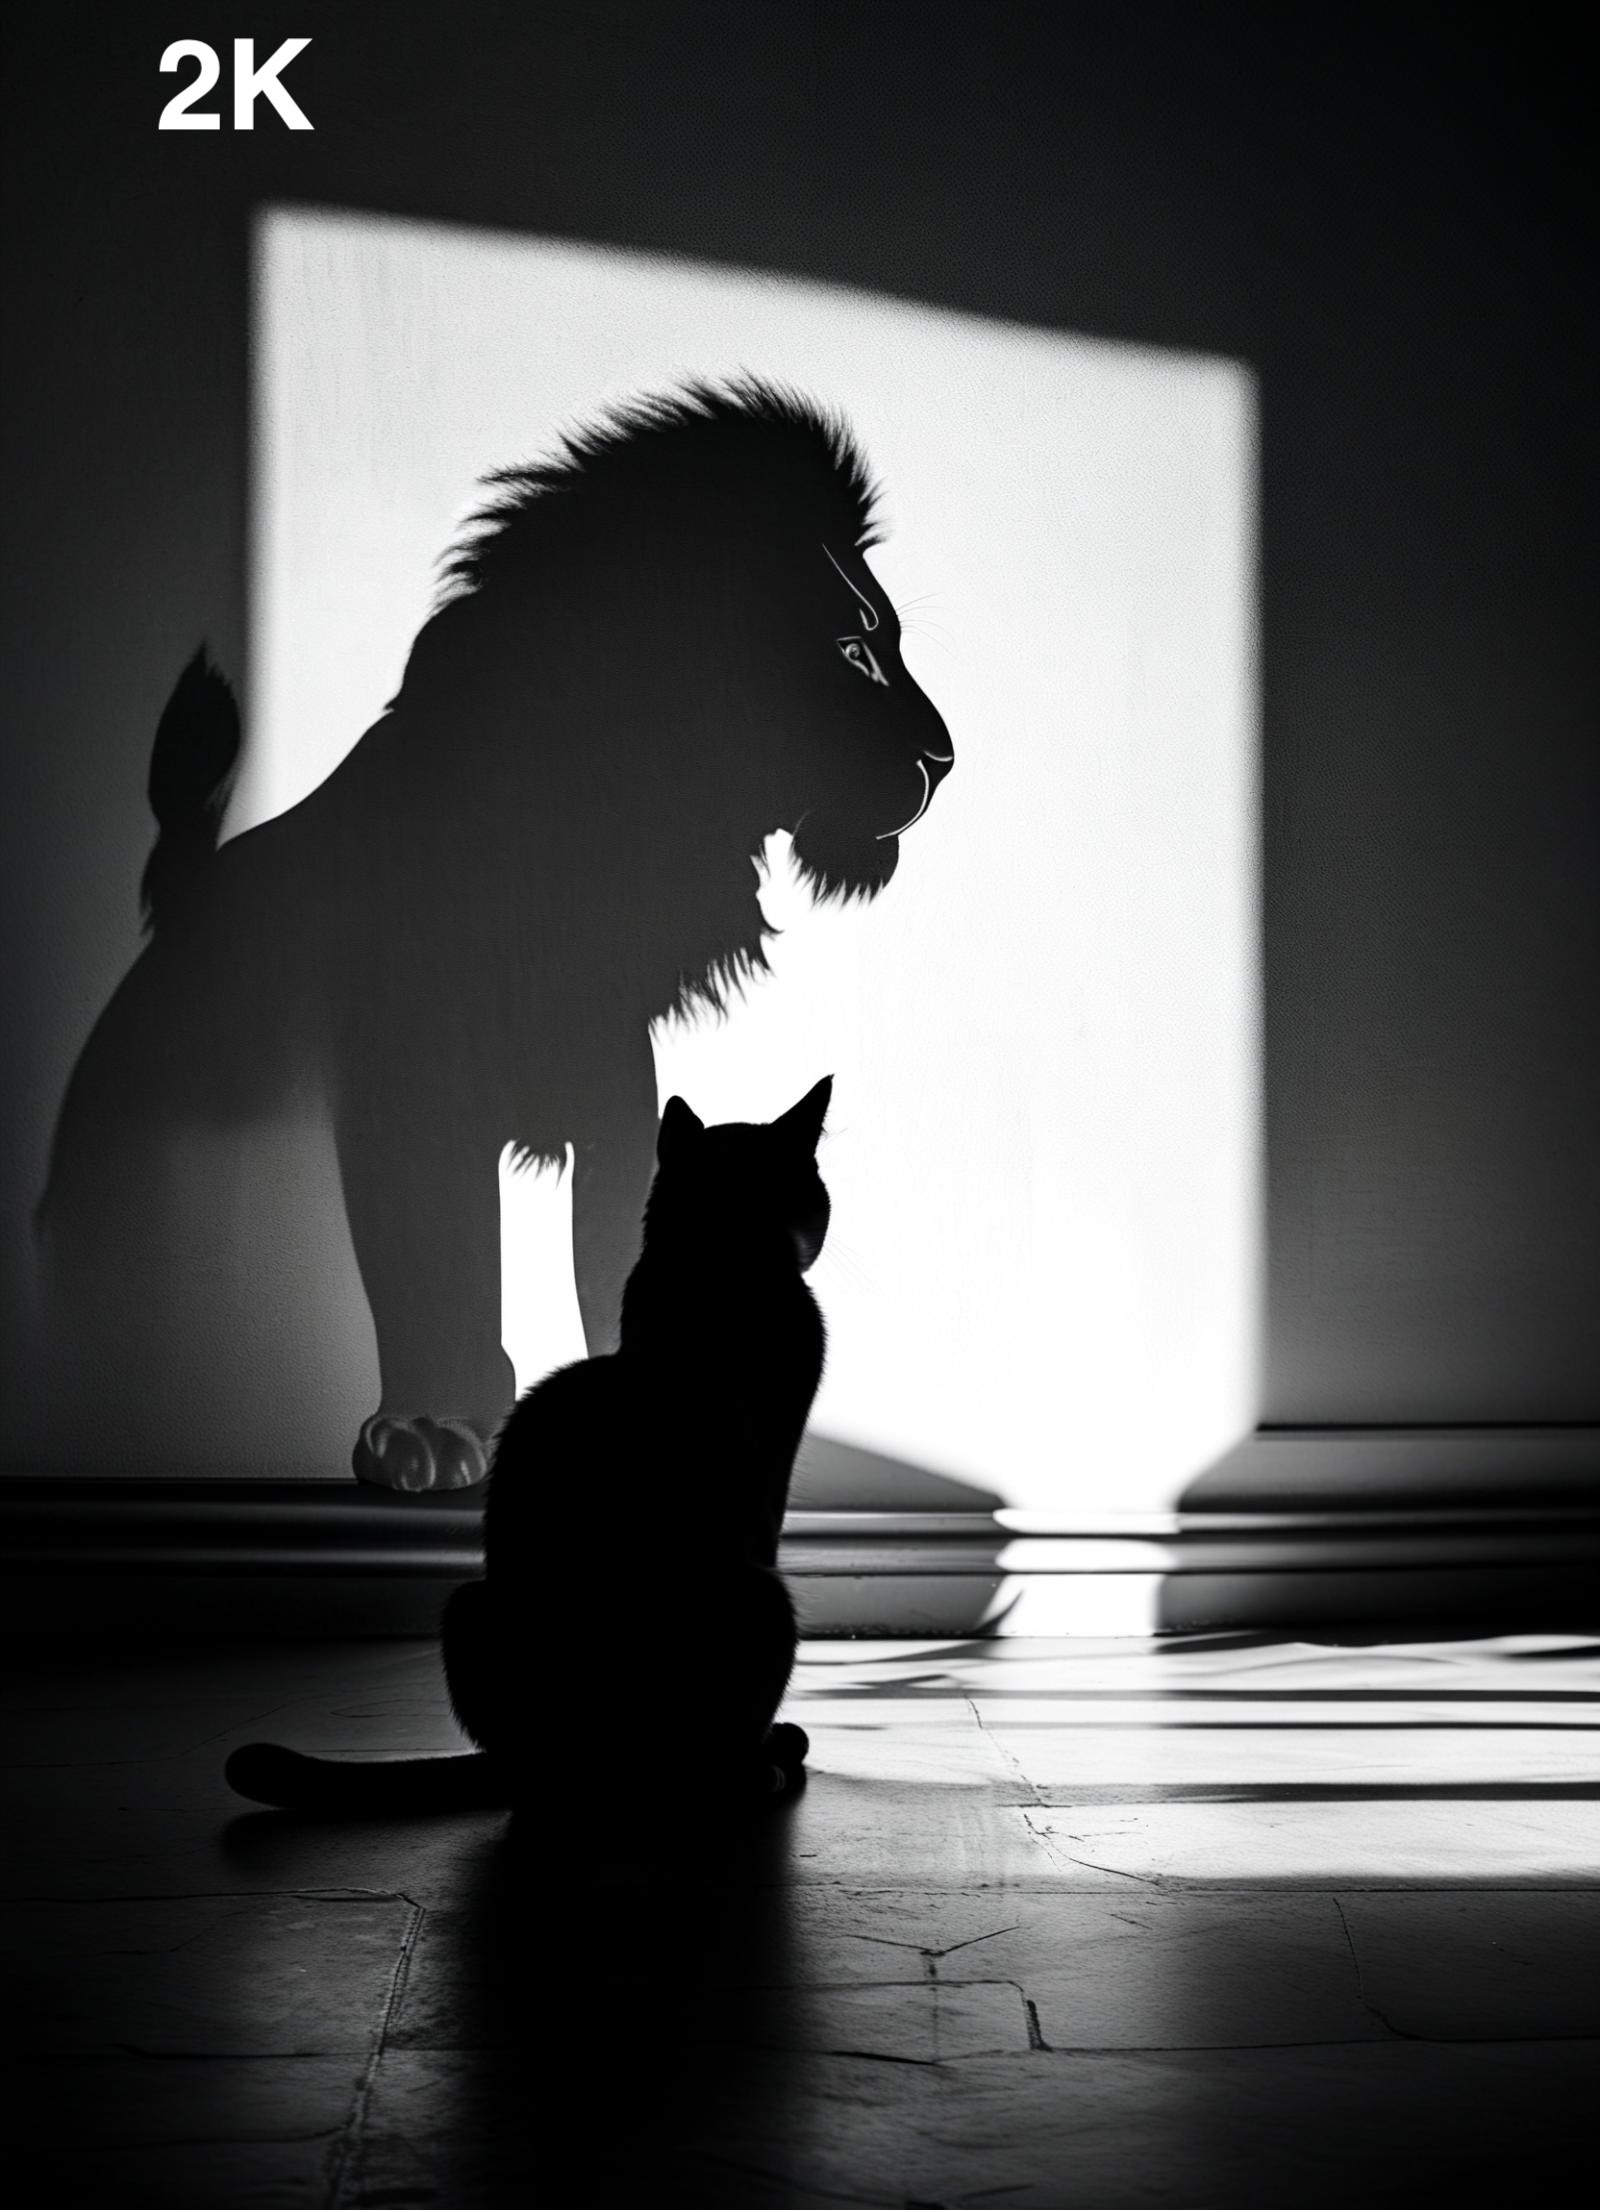 | 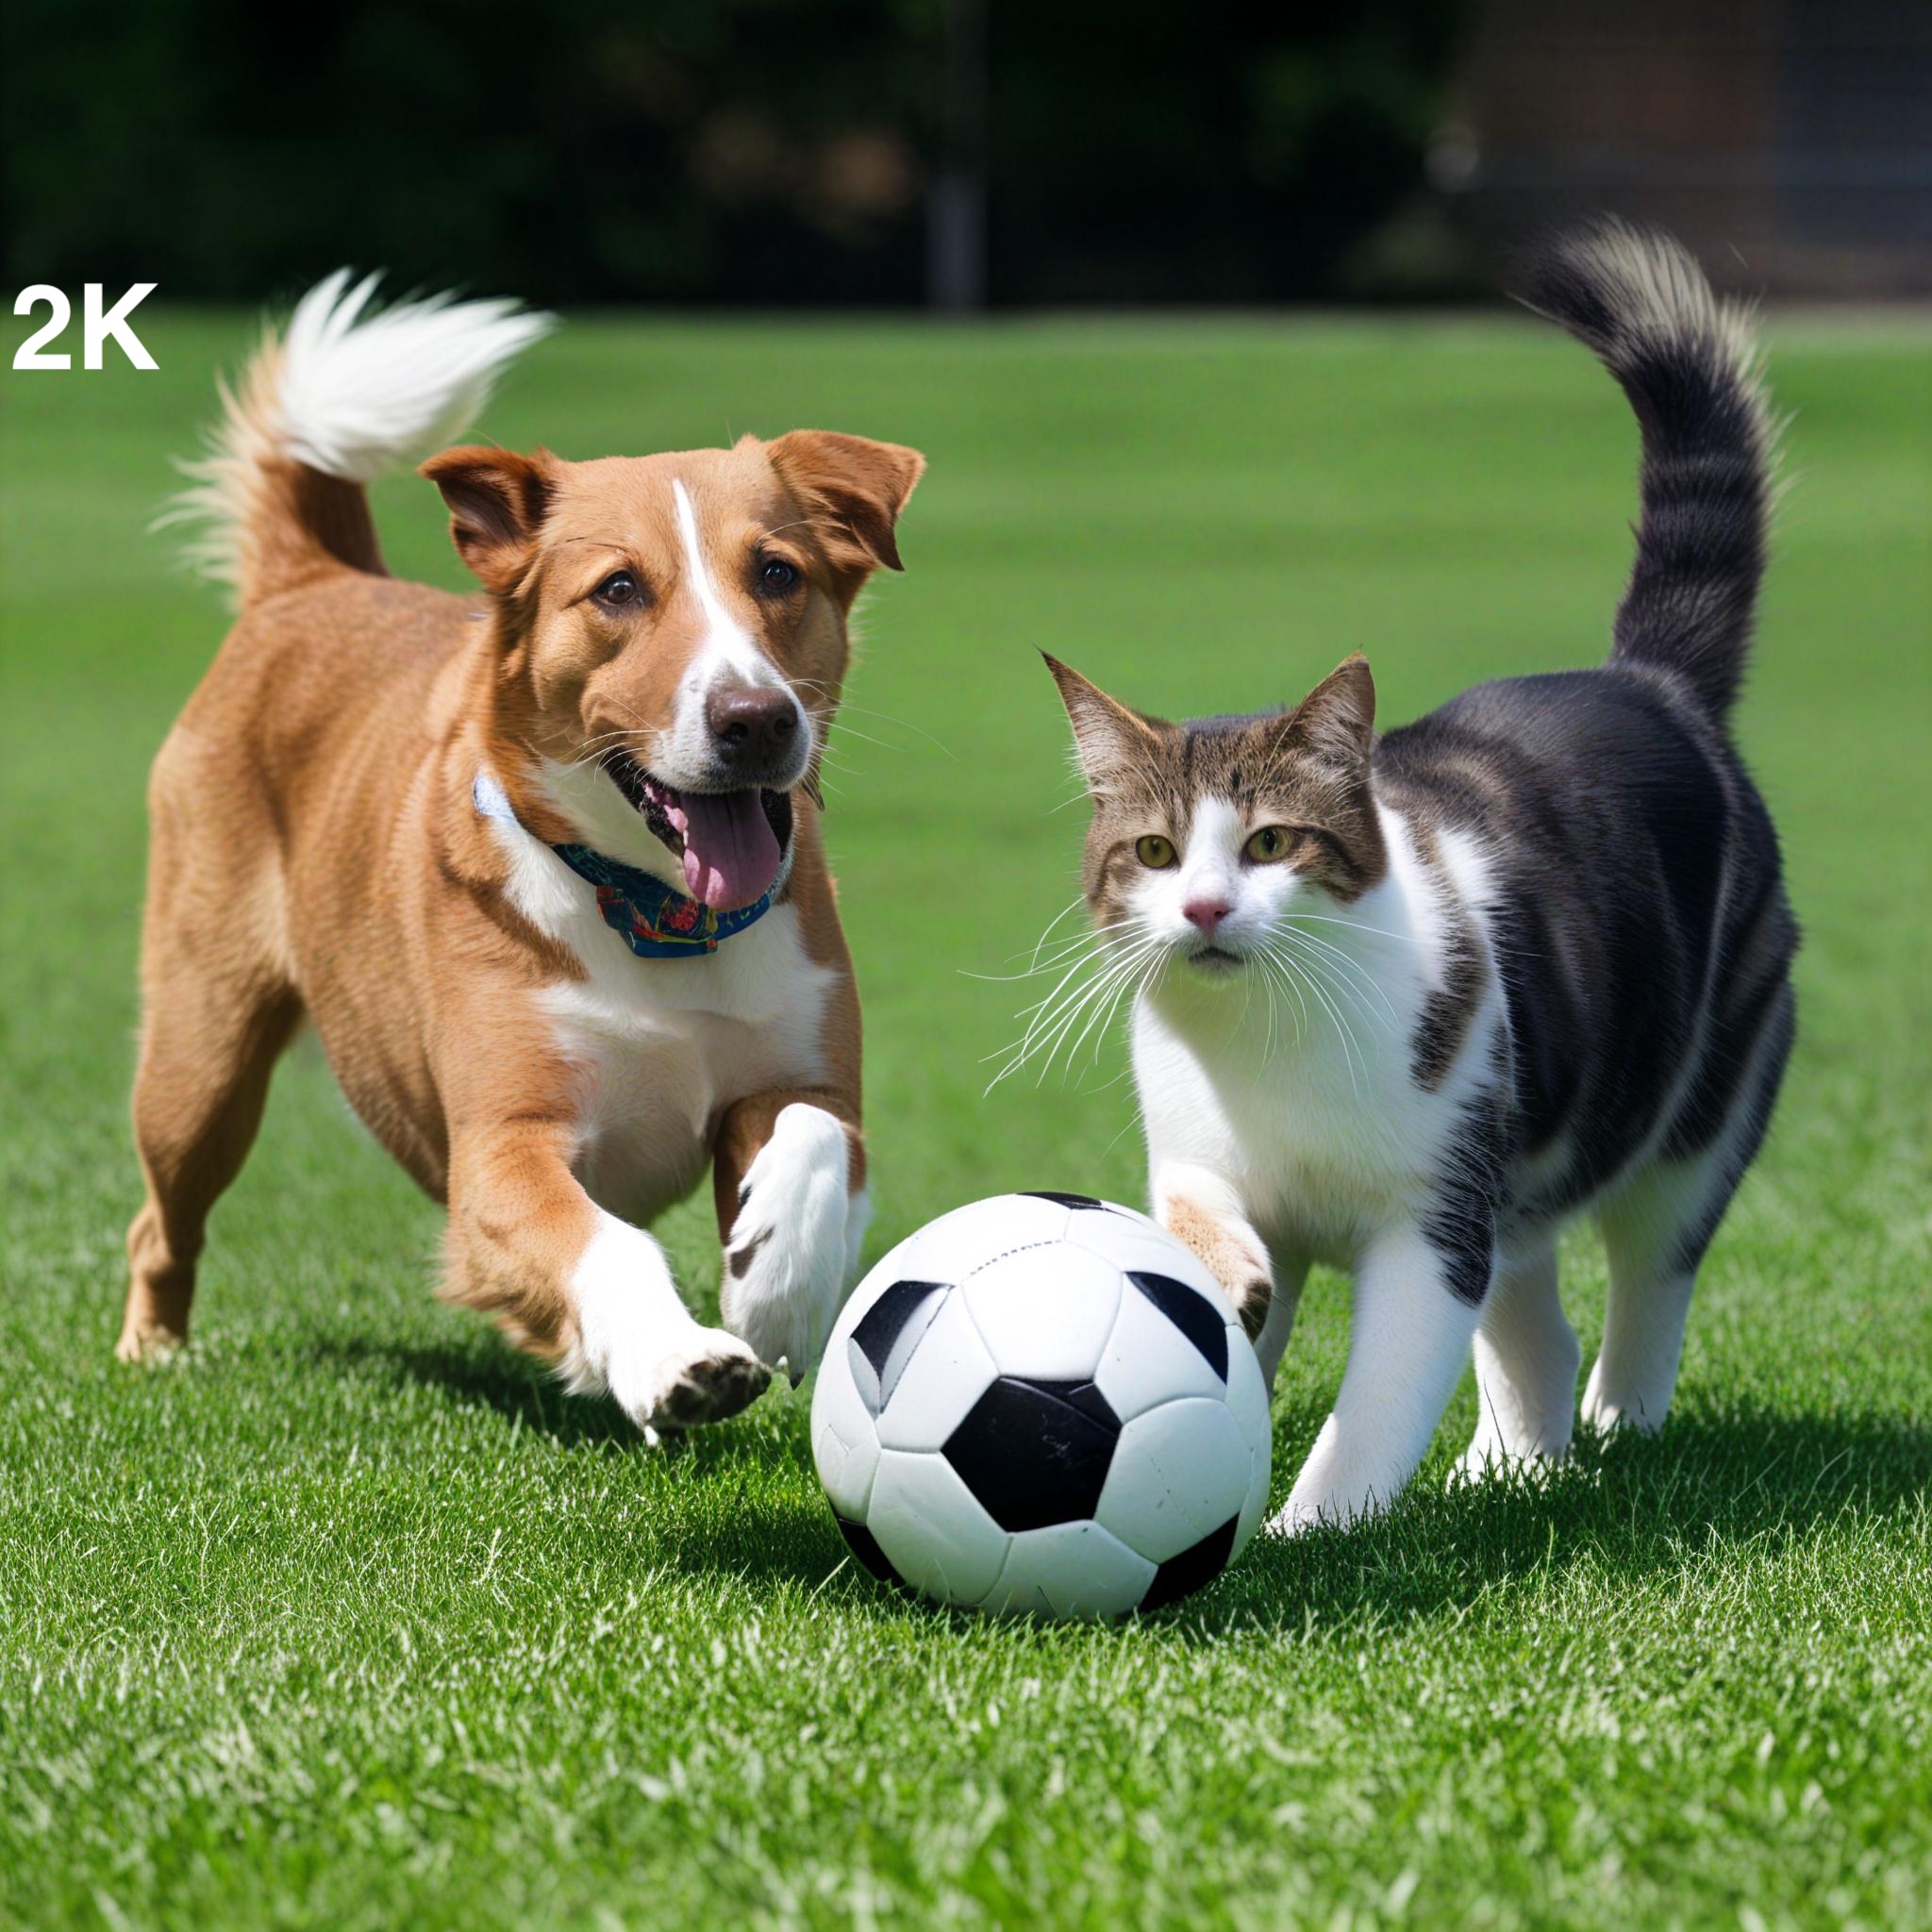 |
|---|---|---|---|
| prompt | a cat floating in a body of water in the pool, Lean back clear and transparent water, light white, and turquoise, y2k aesthetic, soft and dreamy colors, brightly colored, popular Instagram, highlevel of detail, realistic photo feeling | A black cat sits on the ground, facing away from us and casting its shadow in front of it. The silhouette of a majestic lion is projected onto the wall by the light source behind the scene. Black and white photography, soft lighting, high contrast, sharp focus, symmetrical composition, simple background, portrait lens, static posture. | 🐶 和 🐱 玩 ⚽ |
Model Description
- Developed by: NVIDIA, Sana
- Model type: Linear-Diffusion-Transformer-based text-to-image generative model
- Model size: 1648M parameters
- Model resolution: This model is developed to generate 2Kpx based images with multi-scale heigh and width.
- License: Apache License 2.0. Additional Information: Gemma Terms of Use | Google AI for Developers for Gemma-2-2B-IT, Gemma Prohibited Use Policy | Google AI for Developers.
- Model Description: This is a model that can be used to generate and modify images based on text prompts. It is a Linear Diffusion Transformer that uses one fixed, pretrained text encoders (Gemma2-2B-IT) and one 32x spatial-compressed latent feature encoder (DC-AE).
- Special: This model is fine-tuned from the base model Efficient-Large-Model/Sana_1600M_1024px_BF16 and it supports Emoji, Chinese and English and all mixed prompts.
- Resources for more information: Check out our GitHub Repository and the Sana report on arXiv.
Model Sources
For research purposes, we recommend our generative-models Github repository (https://github.com/NVlabs/Sana),
which is more suitable for both training and inference and for which most advanced diffusion sampler like Flow-DPM-Solver is integrated.
MIT Han-Lab provides free Sana inference.
- Repository: https://github.com/NVlabs/Sana
🧨 Diffusers
1. How to use SanaPipeline with 🧨diffusers
[!IMPORTANT] Make sure to specify
pipe.transformerto defaulttorch_dtypeandvariantaccording to Model Card.Set
pipe.text_encoderto BF16 andpipe.vaeto FP32 or BF16. For more info, docs are here.
# run `pip install git+https://github.com/huggingface/diffusers` before use Sana in diffusers
import torch
from diffusers import SanaPipeline

pipe = SanaPipeline.from_pretrained(
    "Efficient-Large-Model/Sana_1600M_2Kpx_BF16_diffusers",
    variant="bf16",
    torch_dtype=torch.bfloat16,
)
pipe.to("cuda")

pipe.vae.to(torch.bfloat16)
pipe.text_encoder.to(torch.bfloat16)

prompt = 'A cute 🐼 eating 🎋, ink drawing style'
image = pipe(
    prompt=prompt,
    height=2048,
    width=2048,
    guidance_scale=5.0,
    num_inference_steps=20,
    generator=torch.Generator(device="cuda").manual_seed(42),
)[0]

image[0].save("sana.png")
2. How to use SanaPAGPipeline with 🧨diffusers
# run `pip install git+https://github.com/huggingface/diffusers` before use Sana in diffusers
import torch
from diffusers import SanaPAGPipeline

pipe = SanaPAGPipeline.from_pretrained(
  "Efficient-Large-Model/Sana_1600M_2Kpx_BF16_diffusers",
  variant="bf16",
  torch_dtype=torch.bfloat16,
  pag_applied_layers="transformer_blocks.8",
)
pipe.to("cuda")

pipe.text_encoder.to(torch.bfloat16)
pipe.vae.to(torch.bfloat16)

prompt = 'A cute 🐼 eating 🎋, ink drawing style'
image = pipe(
    prompt=prompt,
    height=2048,
    width=2048,
    guidance_scale=5.0,
    pag_scale=2.0,
    num_inference_steps=20,
    generator=torch.Generator(device="cuda").manual_seed(42),
)[0]
image[0].save('sana.png')
Uses
Direct Use
The model is intended for research purposes only. Possible research areas and tasks include
-
Generation of artworks and use in design and other artistic processes.
-
Applications in educational or creative tools.
-
Research on generative models.
-
Safe deployment of models which have the potential to generate harmful content.
-
Probing and understanding the limitations and biases of generative models.
Excluded uses are described below.
Out-of-Scope Use
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
Limitations and Bias
Limitations
- The model does not achieve perfect photorealism
- The model cannot render complex legible text
- fingers, .etc in general may not be generated properly.
- The autoencoding part of the model is lossy.
Bias
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.