Autonomous agents for software development are already contributing to a wide range of software development tasks. But up to this point, strong coding agents have relied on proprietary models, which means that even if you use an open-source agent like OpenHands, you are still reliant on API calls to an external service.
Today, we are excited to introduce OpenHands LM, a new open coding model that:
- Is open and available on Hugging Face, so you can download it and run it locally
- Is a reasonable size, 32B, so it can be run locally on hardware such as a single 3090 GPU
- Achieves strong performance on software engineering tasks, including 37.2% resolve rate on SWE-Bench Verified
Read below for more details and our future plans!
What is OpenHands LM?
OpenHands LM is built on the foundation of Qwen Coder 2.5 Instruct 32B, leveraging its powerful base capabilities for coding tasks. What sets OpenHands LM apart is our specialized fine-tuning process:
- We used training data generated by OpenHands itself on a diverse set of open-source repositories
- Specifically, we use an RL-based framework outlined in SWE-Gym, where we set up a training environment, generate training data using an existing agent, and then fine-tune the model on examples that were resolved successfully
- It features a 128K token context window, ideal for handling large codebases and long-horizon software engineering tasks
Performance: Punching Above Its Weight
We evaluated OpenHands LM using our latest iterative evaluation protocol on the SWE-Bench Verified benchmark.
The results are impressive:
- 37.2% verified resolve rate on SWE-Bench Verified
- Performance comparable to models with 20x more parameters, including Deepseek V3 0324 (38.8%) with 671B parameters
Here's how OpenHands LM compares to other leading open-source models:
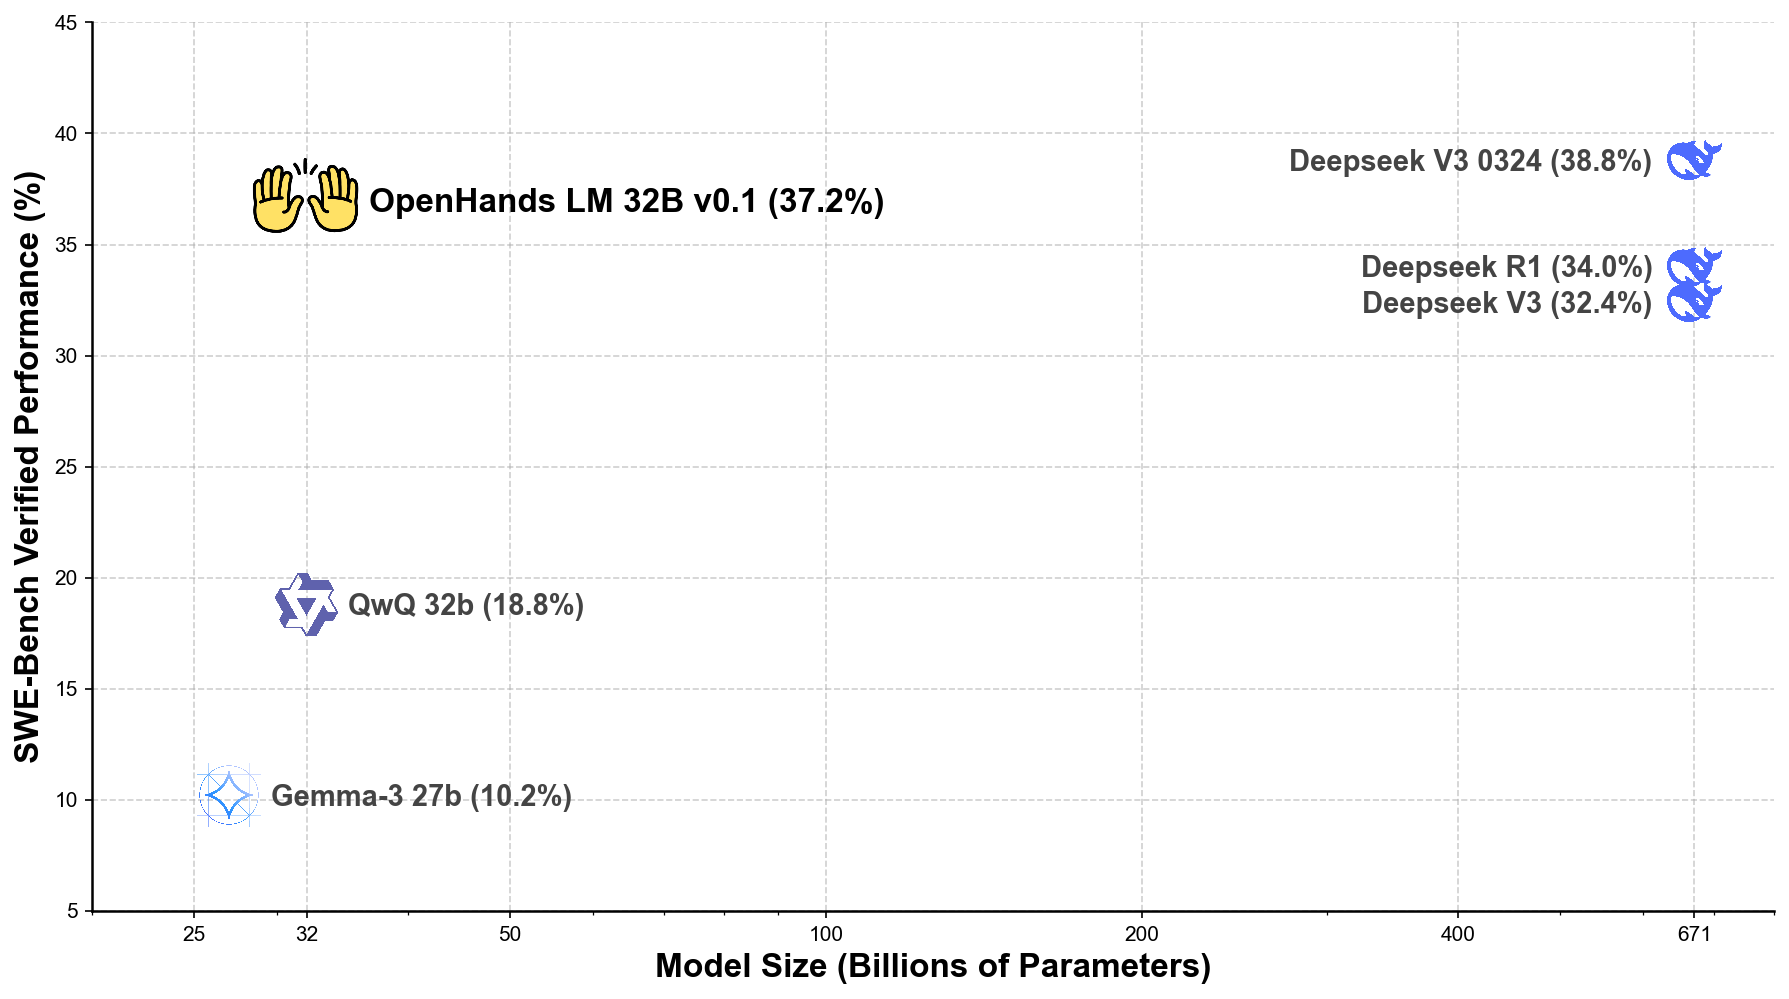
As the plot demonstrates, our 32B parameter model achieves efficiency that approaches much larger models. While the largest models (671B parameters) achieve slightly higher scores, our 32B parameter model performs remarkably well, opening up possibilities for local deployment that are not possible with larger models.
Getting Started: How to Use OpenHands LM Today
You can start using OpenHands LM immediately through these channels:
-
Download the model from Hugging Face The model is available on Hugging Face and can be downloaded directly from there.
-
Create an OpenAI-compatible endpoint with a model serving framework For optimal performance, it is recommended to serve this model with a GPU using SGLang or vLLM.
-
Point your OpenHands agent to the new model Download OpenHands and follow the instructions for using an OpenAI-compatible endpoint.
The Road Ahead: Our Development Plans
This initial release marks just the beginning of our journey. We will continue enhancing OpenHands LM based on community feedback and ongoing research initiatives.
In particular, it should be noted that the model is still a research preview, and (1) may be best suited for tasks regarding solving github issues and perform less well on more varied software engineering tasks, (2) may sometimes generate repetitive steps, and (3) is somewhat sensitive to quantization, and may not function at full performance at lower quantization levels. Our next releases will focus on addressing these limitations.
We're also developing more compact versions of the model (including a 7B parameter variant) to support users with limited computational resources. These smaller models will preserve OpenHands LM's core strengths while dramatically reducing hardware requirements.
We encourage you to experiment with OpenHands LM, share your experiences, and participate in its evolution. Together, we can create better tools for tomorrow's software development landscape.
Try OpenHands Cloud
While OpenHands LM is a powerful model you can run locally, we also offer a fully managed cloud solution that makes it even easier to leverage AI for your software development needs.
OpenHands Cloud provides:
- Seamless GitHub integration with issue and PR support
- Multiple interaction methods including text, voice, and mobile
- Parallel agent capabilities for working on multiple tasks simultaneously
- All the power of OpenHands without managing infrastructure
OpenHands Cloud is built on the same technology as our open-source solution but adds convenient features for teams and individuals who want a ready-to-use platform. Visit app.all-hands.dev to get started today!
Join Our Community
We invite you to be part of the OpenHands LM journey:
- Explore our GitHub repository
- Connect with us on Slack
- Follow our documentation to get started
By contributing your experiences and feedback, you'll help shape the future of this open-source initiative. Together, we can create better tools for tomorrow's software development landscape.
We can't wait to see what you'll create with OpenHands LM!