This is an FP8 / INT8 quantized version of Qwen-Image.
- Optimized for efficient inference with reduced memory footprint. Same-seed LPIPS vs the bf16 model (lower is better): 0.057 INT8; FP8 needs activation_value_lb handling - use INT8 for stability.
Samples
Prompt: "cute sloth typing on a computer"
Introduction
We are thrilled to release Qwen-Image, an image generation foundation model in the Qwen series that achieves significant advances in complex text rendering and precise image editing. Experiments show strong general capabilities in both image generation and editing, with exceptional performance in text rendering, especially for Chinese.

News
- 2025.08.04: We released the Technical Report of Qwen-Image!
- 2025.08.04: We released Qwen-Image weights! Check at huggingface and Modelscope!
- 2025.08.04: We released Qwen-Image! Check our blog for more details!
Quick Start
Install the latest version of diffusers
pip install git+https://github.com/huggingface/diffusers
The following contains a code snippet illustrating how to use the model to generate images based on text prompts:
from diffusers import DiffusionPipeline
import torch

model_name = "Qwen/Qwen-Image"

# Load the pipeline
if torch.cuda.is_available():
    torch_dtype = torch.bfloat16
    device = "cuda"
else:
    torch_dtype = torch.float32
    device = "cpu"

pipe = DiffusionPipeline.from_pretrained(model_name, torch_dtype=torch_dtype)
pipe = pipe.to(device)

positive_magic = {
    "en": ", Ultra HD, 4K, cinematic composition.", # for english prompt
    "zh": ", 超清,4K,电影级构图." # for chinese prompt
}

# Generate image
prompt = '''A coffee shop entrance features a chalkboard sign reading "Qwen Coffee 😊 $2 per cup," with a neon light beside it displaying "通义千问". Next to it hangs a poster showing a beautiful Chinese woman, and beneath the poster is written "π≈3.1415926-53589793-23846264-33832795-02384197". Ultra HD, 4K, cinematic composition'''

negative_prompt = " " # using an empty string if you do not have specific concept to remove


# Generate with different aspect ratios
aspect_ratios = {
    "1:1": (1328, 1328),
    "16:9": (1664, 928),
    "9:16": (928, 1664),
    "4:3": (1472, 1140),
    "3:4": (1140, 1472),
    "3:2": (1584, 1056),
    "2:3": (1056, 1584),
}

width, height = aspect_ratios["16:9"]

image = pipe(
    prompt=prompt + positive_magic["en"],
    negative_prompt=negative_prompt,
    width=width,
    height=height,
    num_inference_steps=50,
    true_cfg_scale=4.0,
    generator=torch.Generator(device="cuda").manual_seed(42)
).images[0]

image.save("example.png")
Show Cases
One of its standout capabilities is high-fidelity text rendering across diverse images. Whether it’s alphabetic languages like English or logographic scripts like Chinese, Qwen-Image preserves typographic details, layout coherence, and contextual harmony with stunning accuracy. Text isn’t just overlaid—it’s seamlessly integrated into the visual fabric.
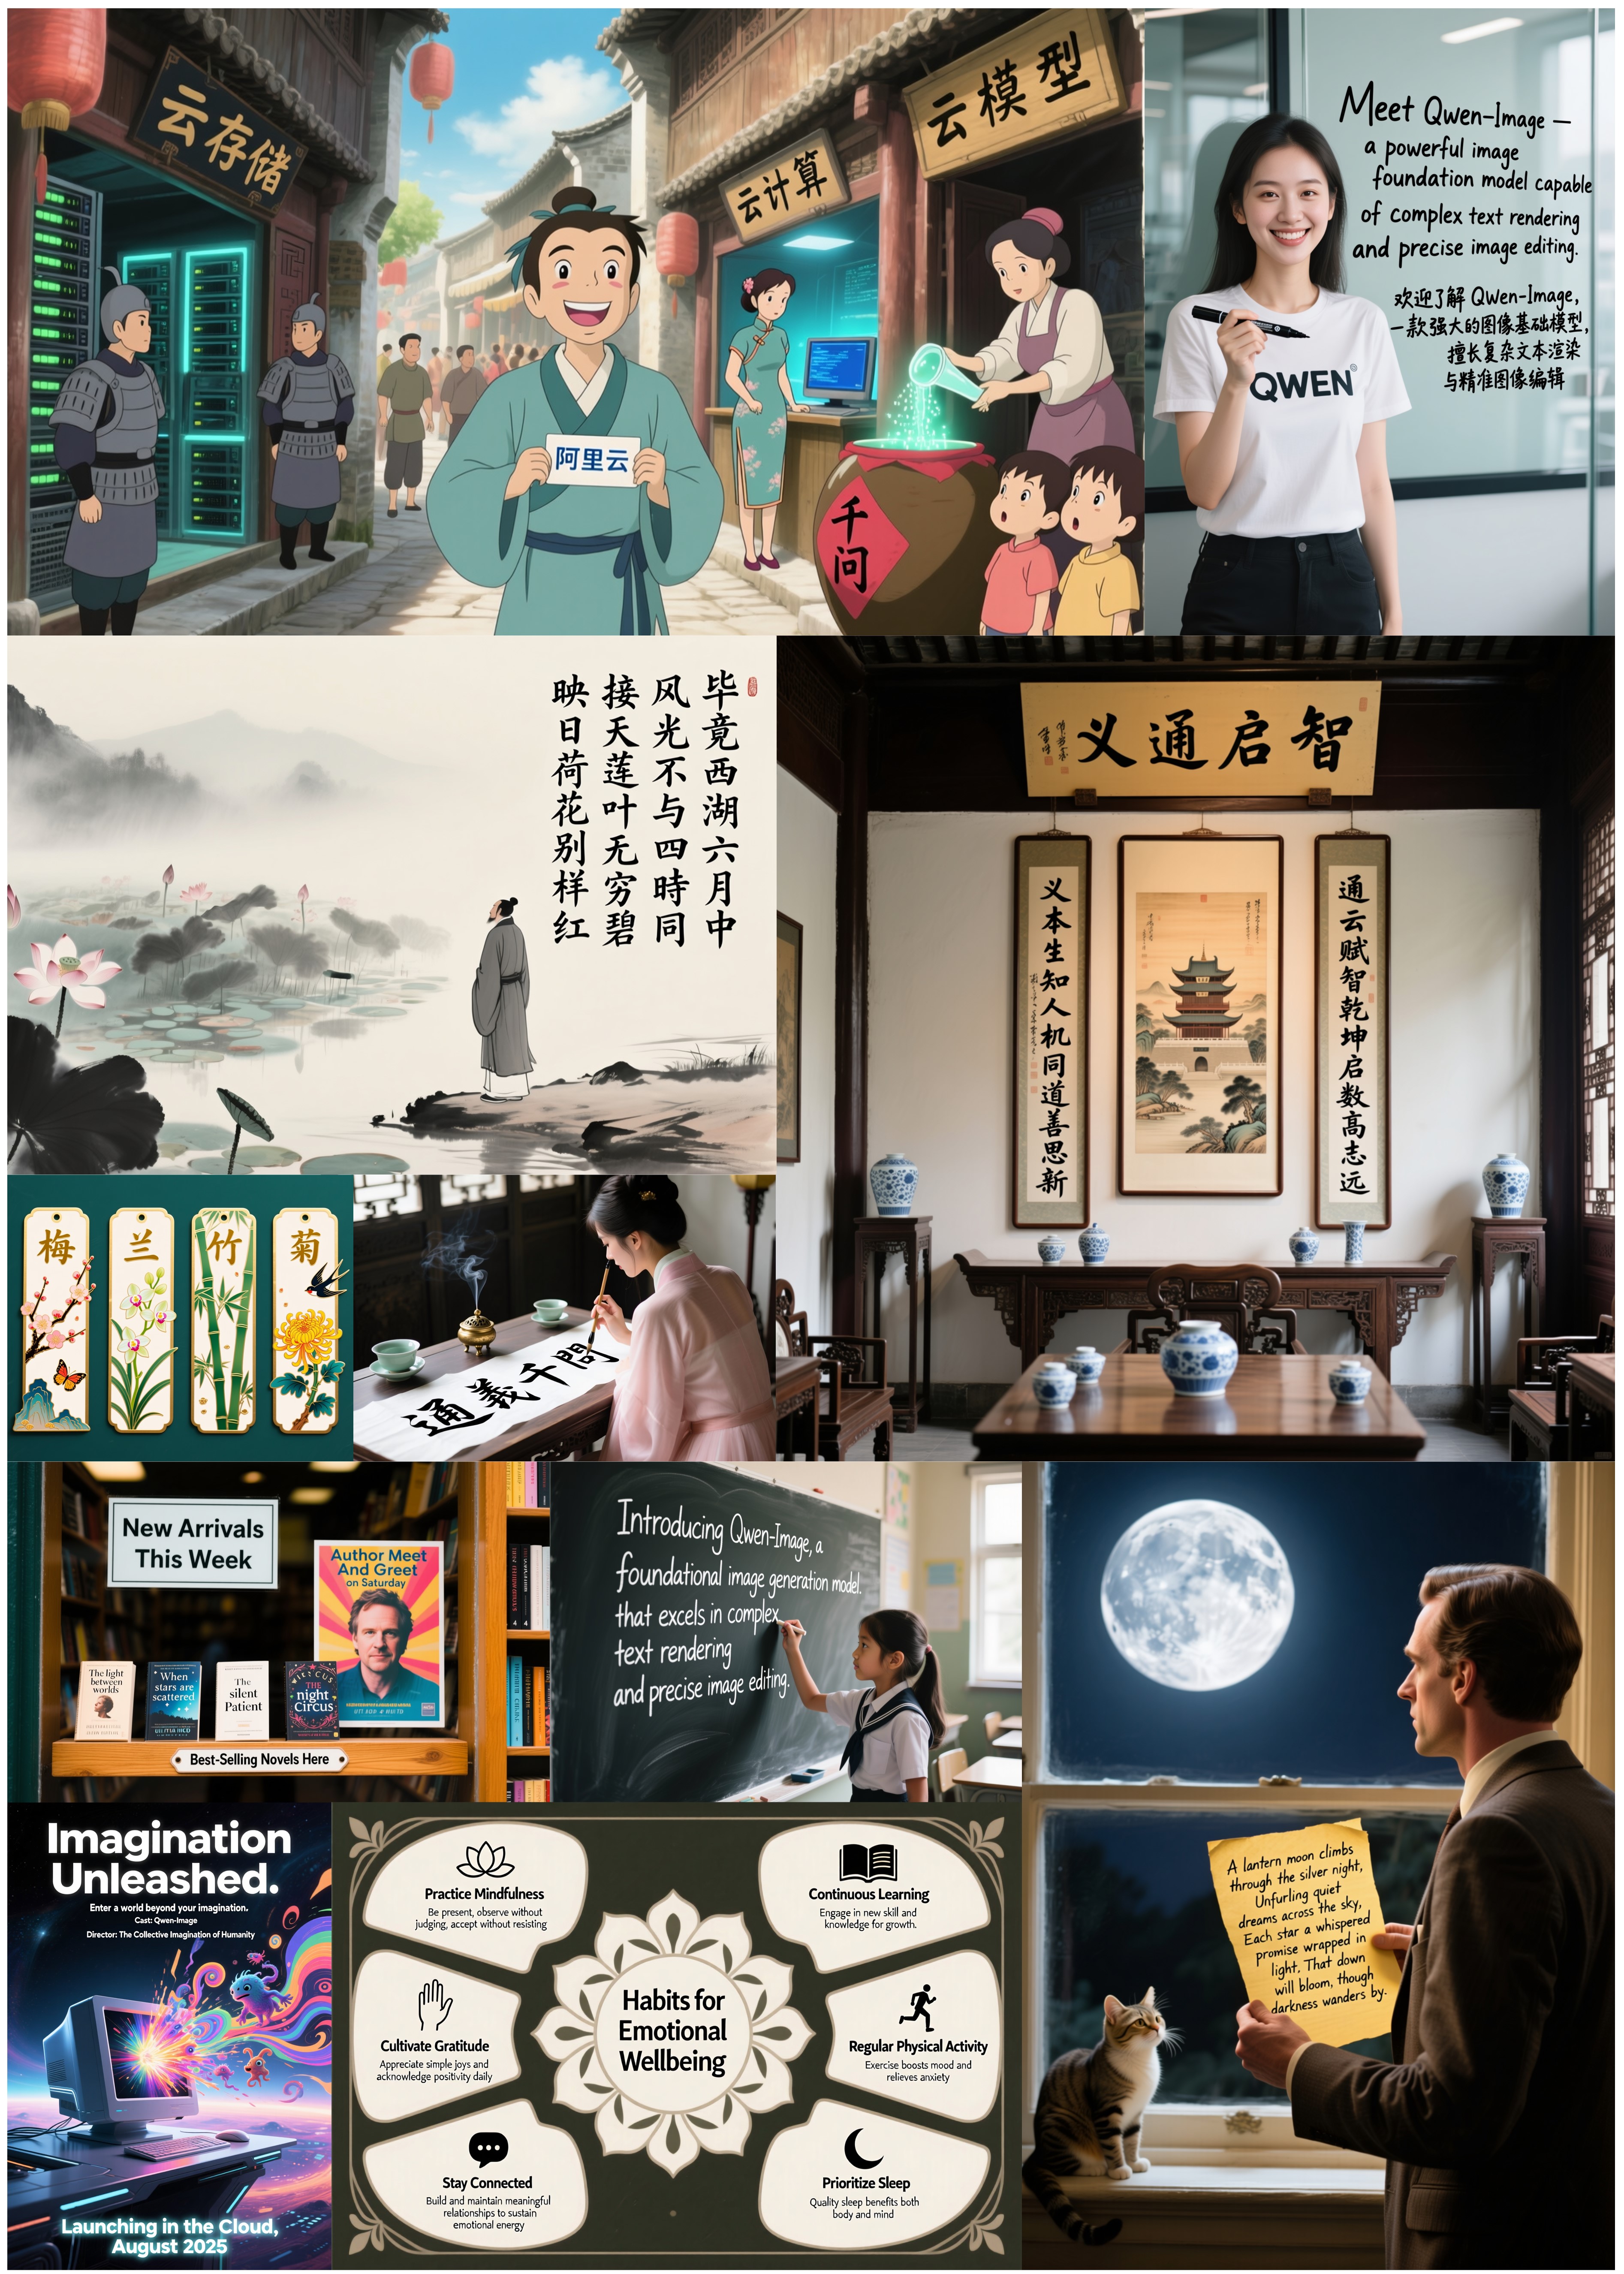
Beyond text, Qwen-Image excels at general image generation with support for a wide range of artistic styles. From photorealistic scenes to impressionist paintings, from anime aesthetics to minimalist design, the model adapts fluidly to creative prompts, making it a versatile tool for artists, designers, and storytellers.

When it comes to image editing, Qwen-Image goes far beyond simple adjustments. It enables advanced operations such as style transfer, object insertion or removal, detail enhancement, text editing within images, and even human pose manipulation—all with intuitive input and coherent output. This level of control brings professional-grade editing within reach of everyday users.

But Qwen-Image doesn’t just create or edit—it understands. It supports a suite of image understanding tasks, including object detection, semantic segmentation, depth and edge (Canny) estimation, novel view synthesis, and super-resolution. These capabilities, while technically distinct, can all be seen as specialized forms of intelligent image editing, powered by deep visual comprehension.

Together, these features make Qwen-Image not just a tool for generating pretty pictures, but a comprehensive foundation model for intelligent visual creation and manipulation—where language, layout, and imagery converge.
License Agreement
Qwen-Image is licensed under Apache 2.0.
Citation
We kindly encourage citation of our work if you find it useful.
@misc{wu2025qwenimagetechnicalreport,
      title={Qwen-Image Technical Report},
      author={Chenfei Wu and Jiahao Li and Jingren Zhou and Junyang Lin and Kaiyuan Gao and Kun Yan and Sheng-ming Yin and Shuai Bai and Xiao Xu and Yilei Chen and Yuxiang Chen and Zecheng Tang and Zekai Zhang and Zhengyi Wang and An Yang and Bowen Yu and Chen Cheng and Dayiheng Liu and Deqing Li and Hang Zhang and Hao Meng and Hu Wei and Jingyuan Ni and Kai Chen and Kuan Cao and Liang Peng and Lin Qu and Minggang Wu and Peng Wang and Shuting Yu and Tingkun Wen and Wensen Feng and Xiaoxiao Xu and Yi Wang and Yichang Zhang and Yongqiang Zhu and Yujia Wu and Yuxuan Cai and Zenan Liu},
      year={2025},
      eprint={2508.02324},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2508.02324},
}
Quantized transformer checkpoints (this repo)
This repo adds pre-quantized diffusion transformer checkpoints for Qwen/Qwen-Image, built with torchao dynamic activation quantization from the dense bf16 transformer. The official model card above is unchanged from the source repo.
Files:
- Qwen-Image-INT8.pt (27.3 GB)
- Qwen-Image-FP8.pt (20.5 GB)
Details:
- int8: Int8DynamicActivationInt8WeightConfig (per-token activation, per-channel weight, torch._int_mm).
- fp8: Float8DynamicActivationFloat8WeightConfig with PerRow granularity (e4m3, torch._scaled_mm). The loader must floor the dynamic activation scale (activation_value_lb=1e-12 on torchao 0.13+) so all-zero activation token rows cannot produce a zero scale.
- Loading a checkpoint is bit-identical to quantizing the dense bf16 transformer on the fly; the checkpoint skips the dense load and quantize step.
- Validated against same-seed dense bf16 renders (SSIM, LPIPS-vgg, CLIP delta, non-finite and black-frame checks) on torch 2.12.1 and torchao 0.17.
Note: fp8 is accuracy-denied for this family in the Studio deny list (activation outliers); the shipped scheme is int8. The fp8 file is staged for the pending activation_value_lb re-gate.
Samples
Prompt: "cute sloth typing on a computer" (1024x1024, family default steps/guidance, seeds 0-2).
int8
fp8
Pre-cast fp8 text encoder (this repo)
Qwen-Image-text_encoder-FP8.pt (8.8 GB) is the pipeline's text encoder (Qwen2_5_VLForConditionalGeneration, the text_encoder
subfolder of Qwen/Qwen-Image) with the layerwise fp8 storage cast Unsloth Studio applies at load
time, saved pre-cast:
- Loading it is bit-identical to downloading the dense encoder and casting on load (verified tensor for tensor: 729 tensors, 605 cast to fp8 storage).
- Cuts the text-encoder download from 16.6 GB to 8.8 GB.
- Plain-tensor state dict: loads with torch.load(weights_only=True). Metadata records scheme fp8, component text_encoder, base Qwen/Qwen-Image.